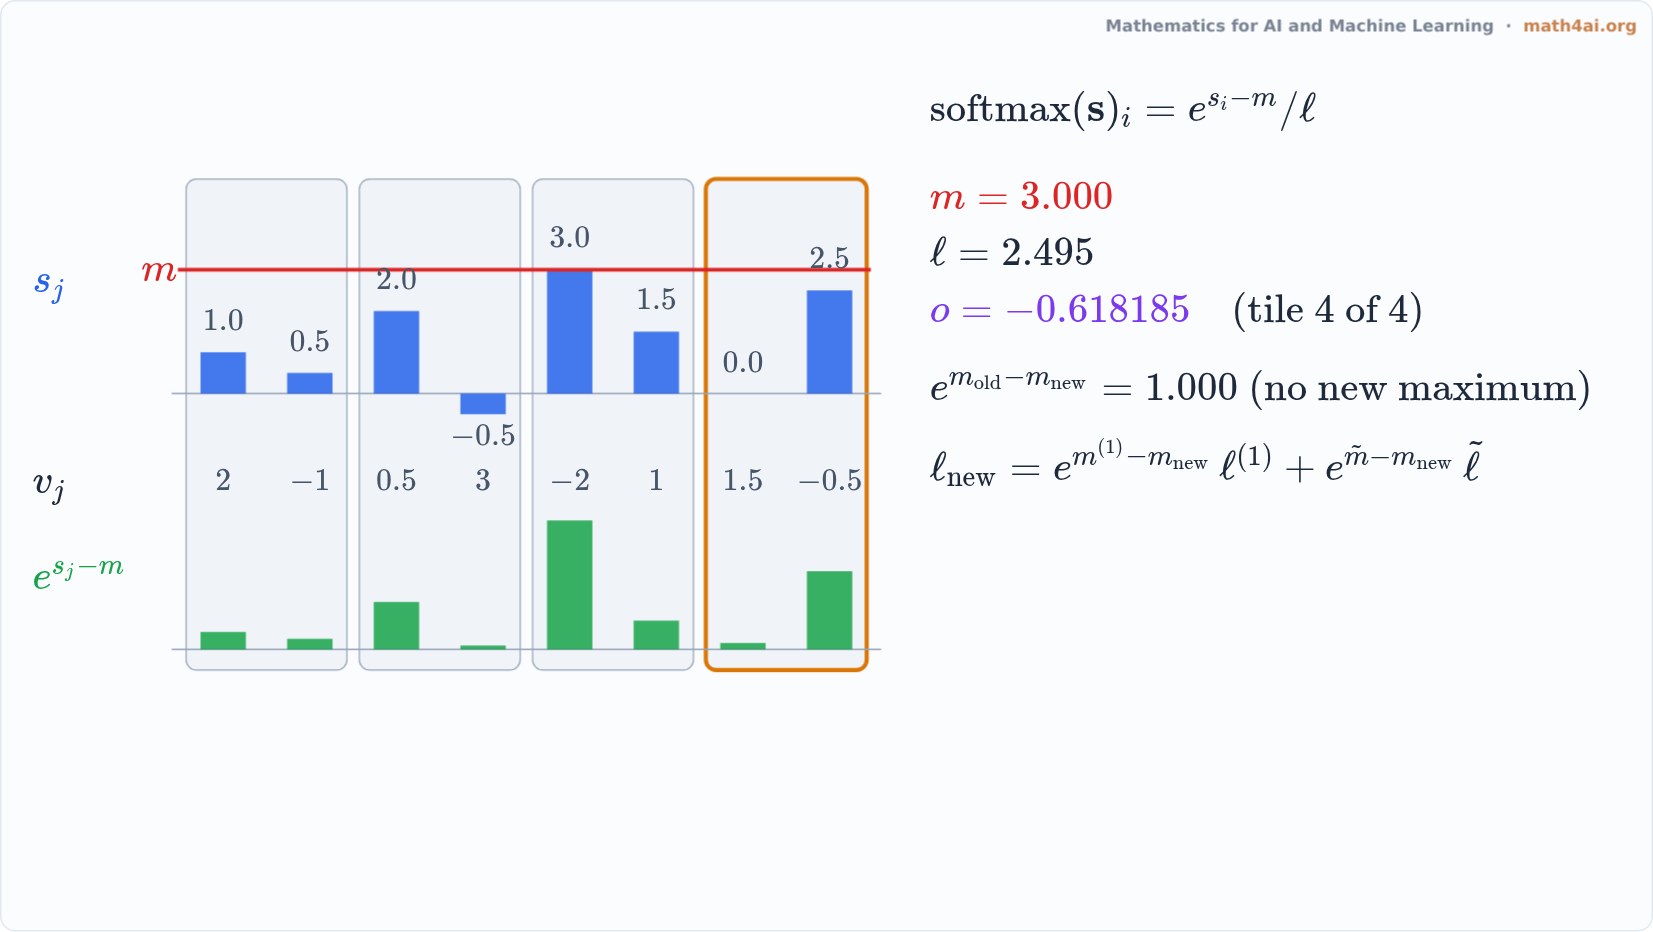
Online Softmax, One Tile at a Time
An interactive live film: FlashAttention reads a row of attention scores tile by tile, keeping a running maximum, sum and output that are rescaled by e^(m_old - m_new) whenever a larger score appears; drag the scores or change the tile size and the result still equals the full softmax exactly.
Narration
Here is one row of attention scores s, the eight blue bars, with a value v under each one. The safe softmax needs the maximum and the sum over the whole row.
FlashAttention reads the row in tiles, two scores at a time, in the orange box. It keeps only three running numbers: the maximum m, drawn as the red line, the sum l, and the output o.
The rest of the narration is in the book's Companion.
More from Chapter 10
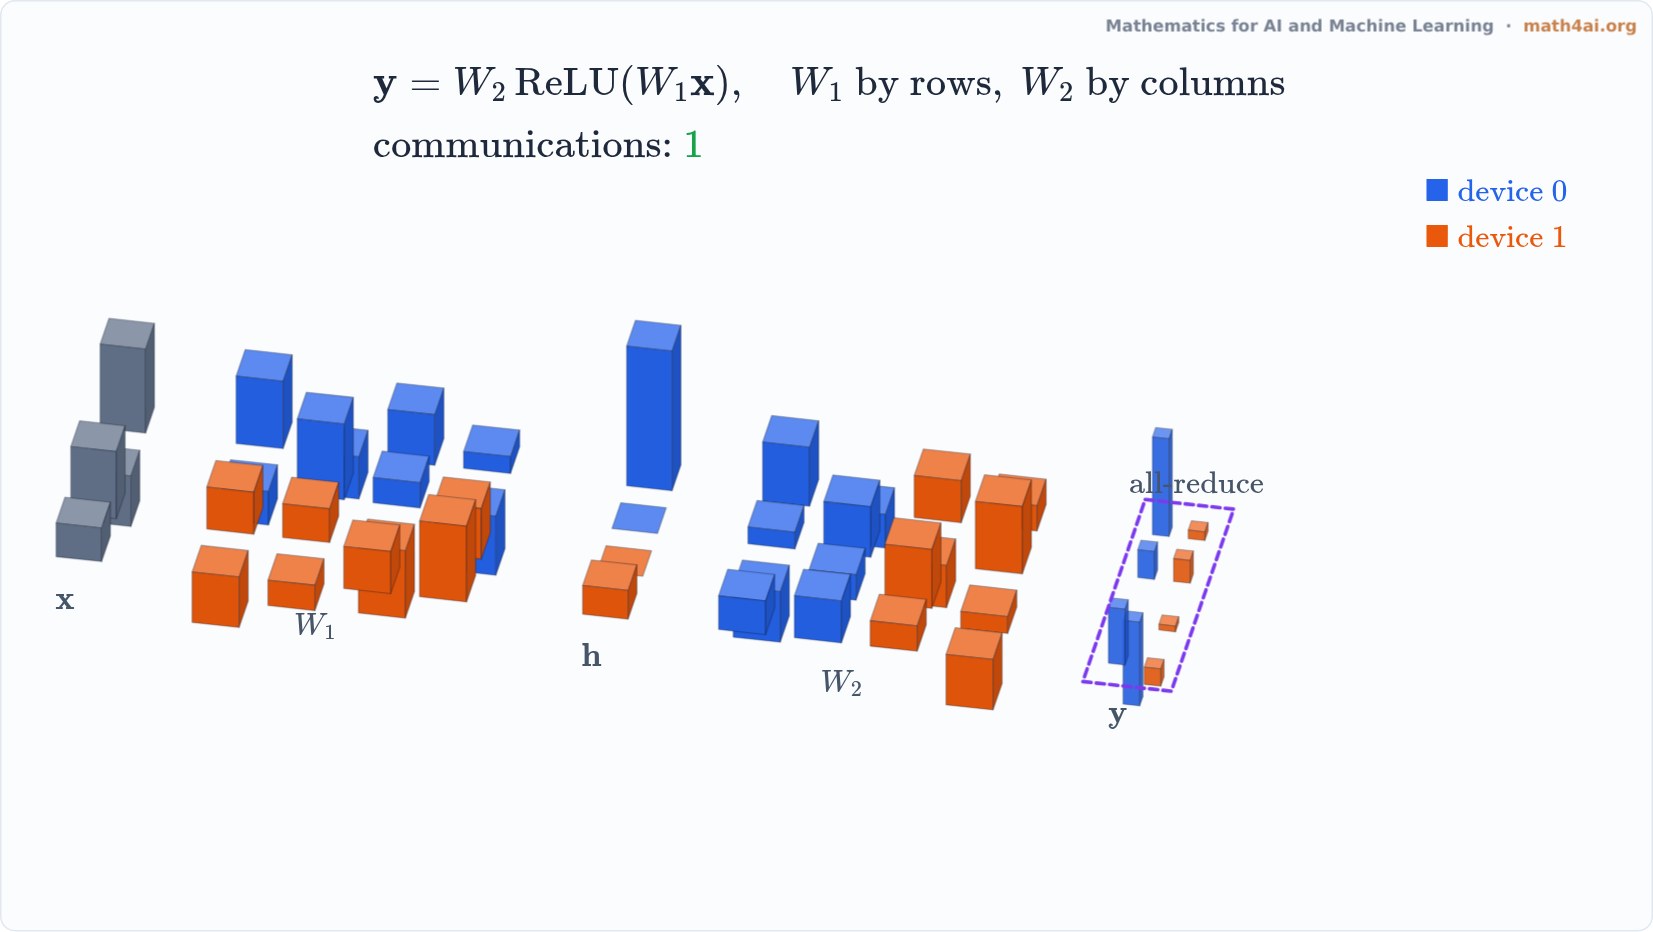 Interactive2:11Tensor Parallelism: Block Products Across DevicesChapter 10
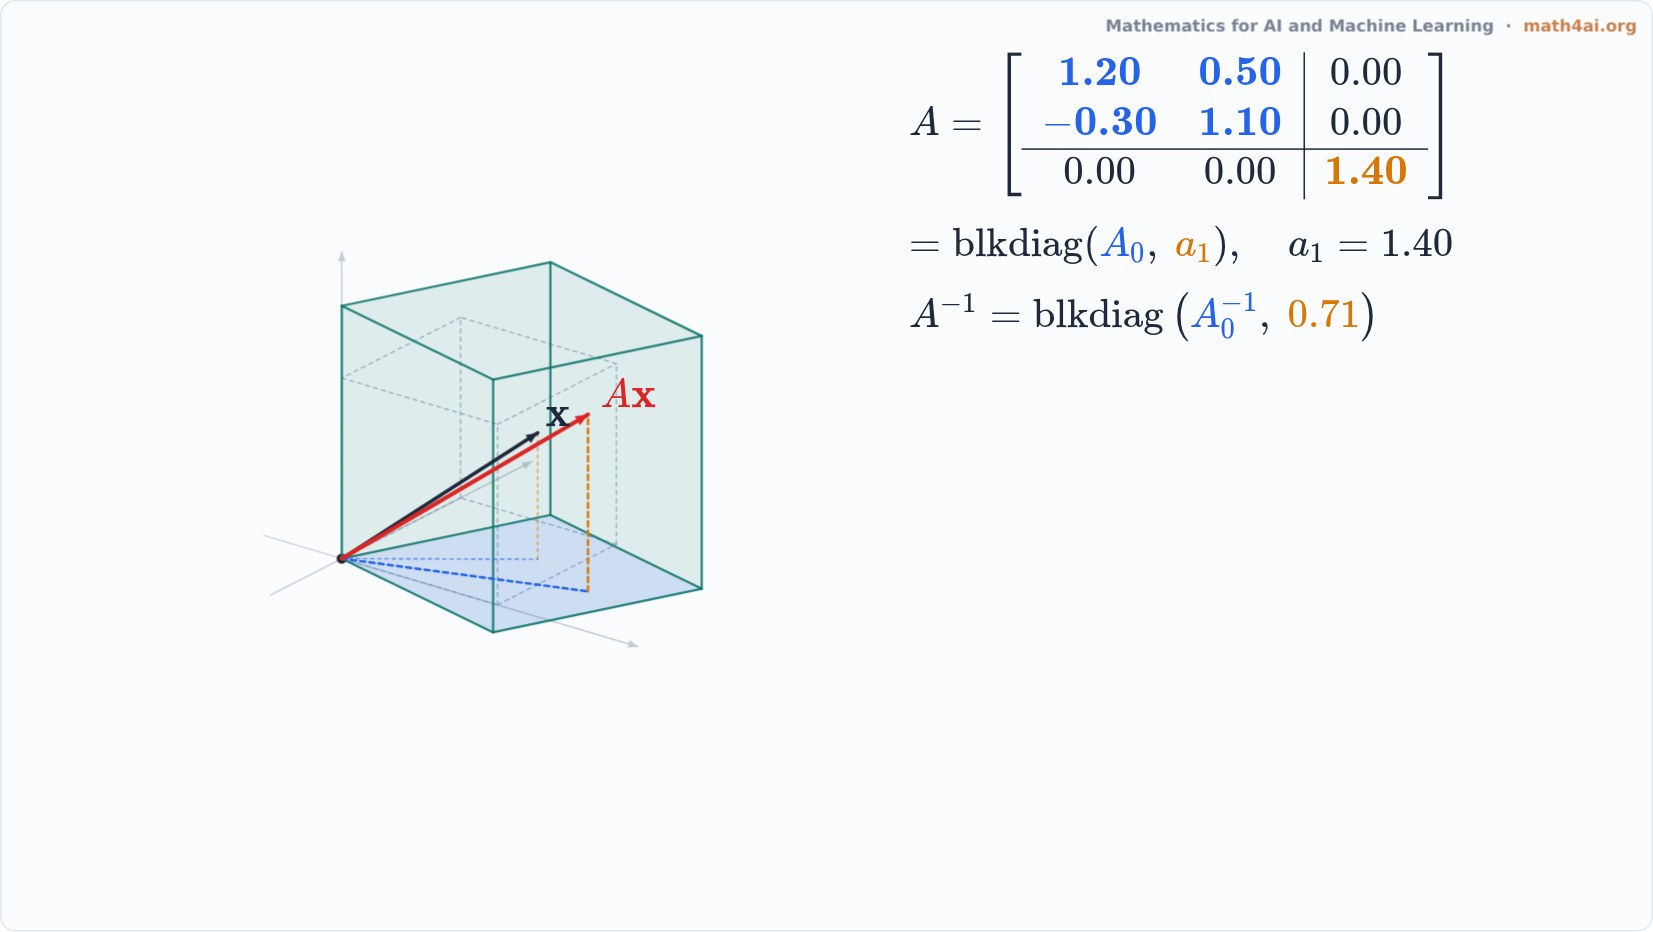 Preview1:24Block Diagonal Matrices: Separate WorldsChapter 10
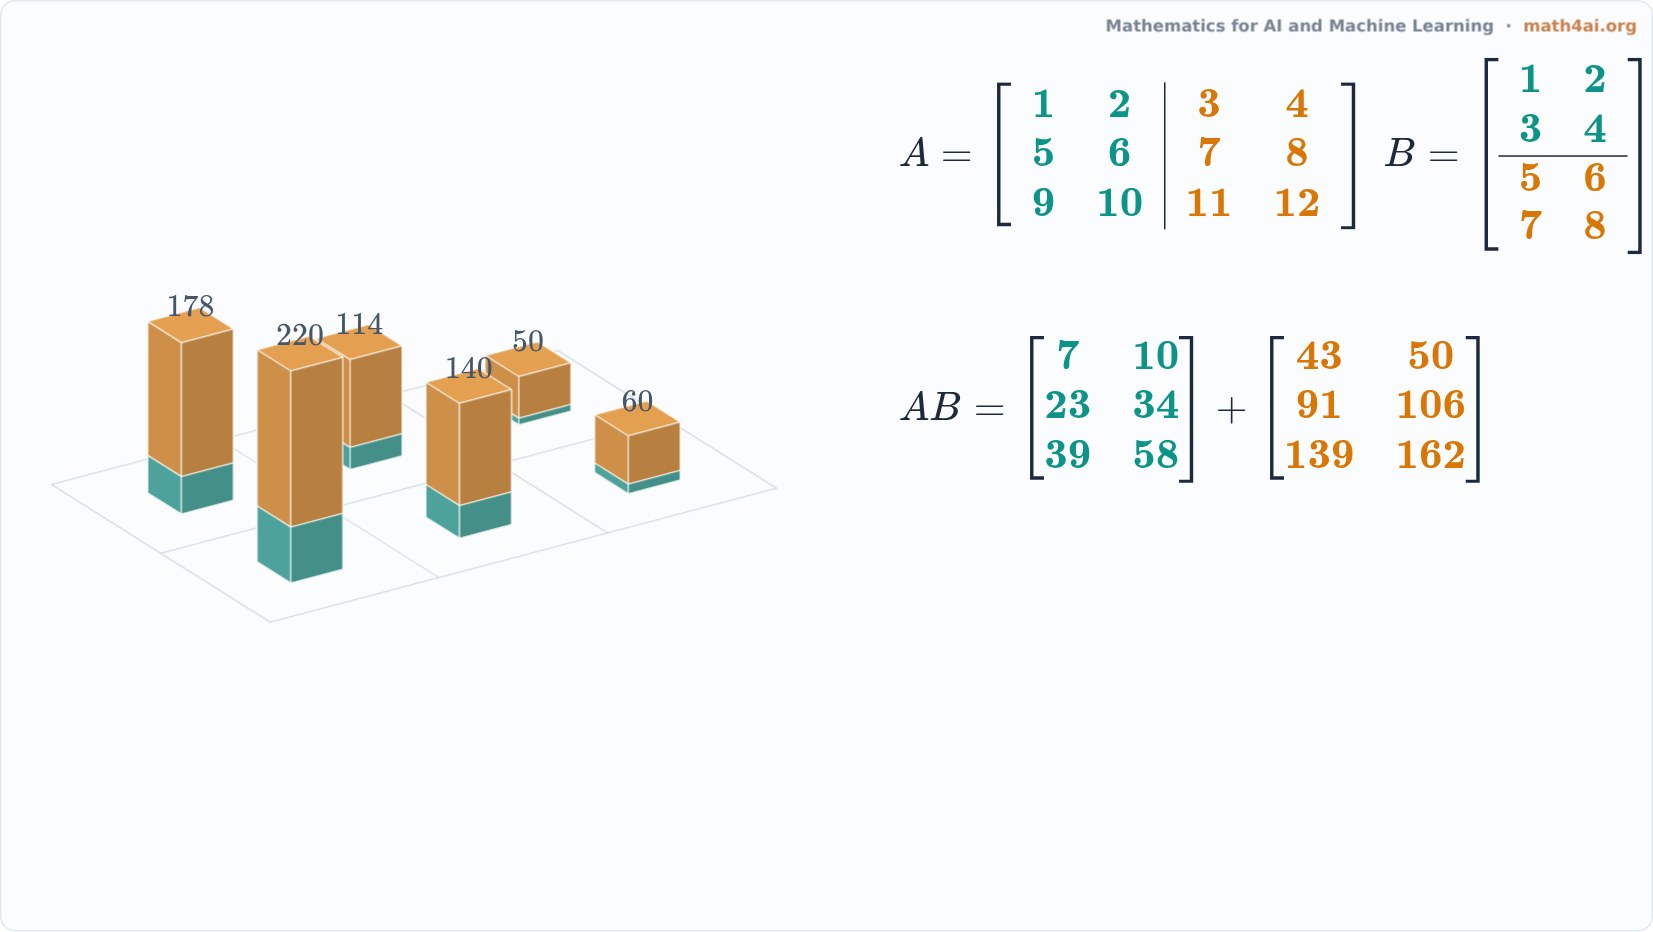 Preview1:28Block Multiplication: Blocks Multiply Like NumbersChapter 10
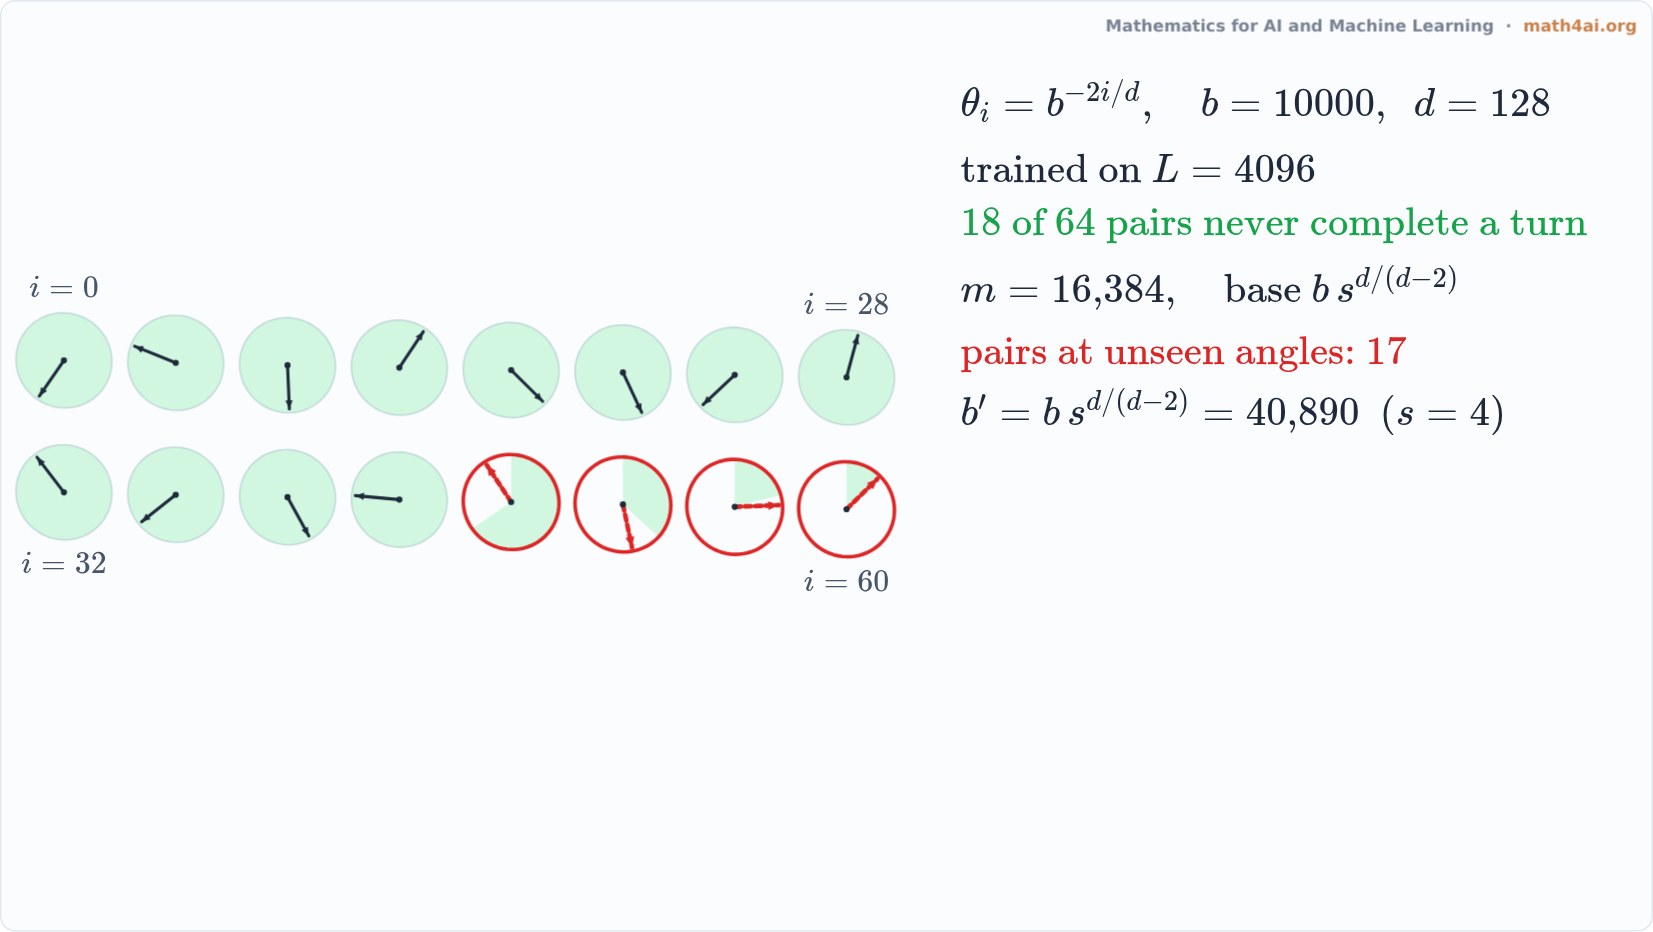 Preview1:39Longer Contexts with Rotary PositionsChapter 10
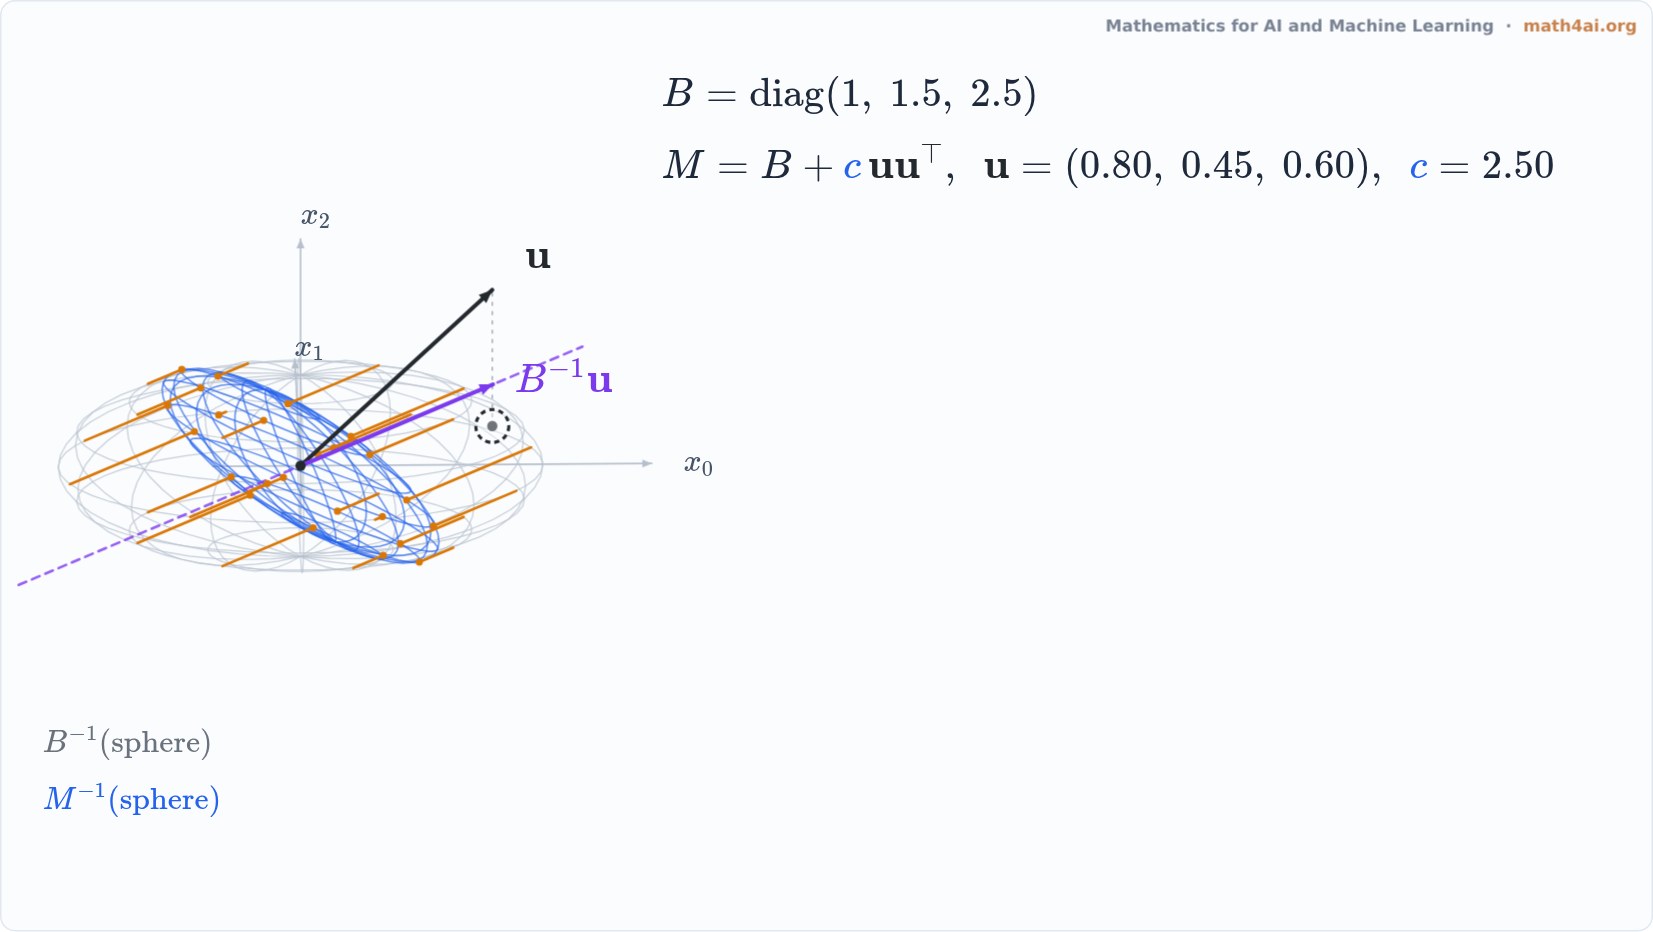 Preview2:20Woodbury Identity: a Rank-One Update of the InverseChapter 10
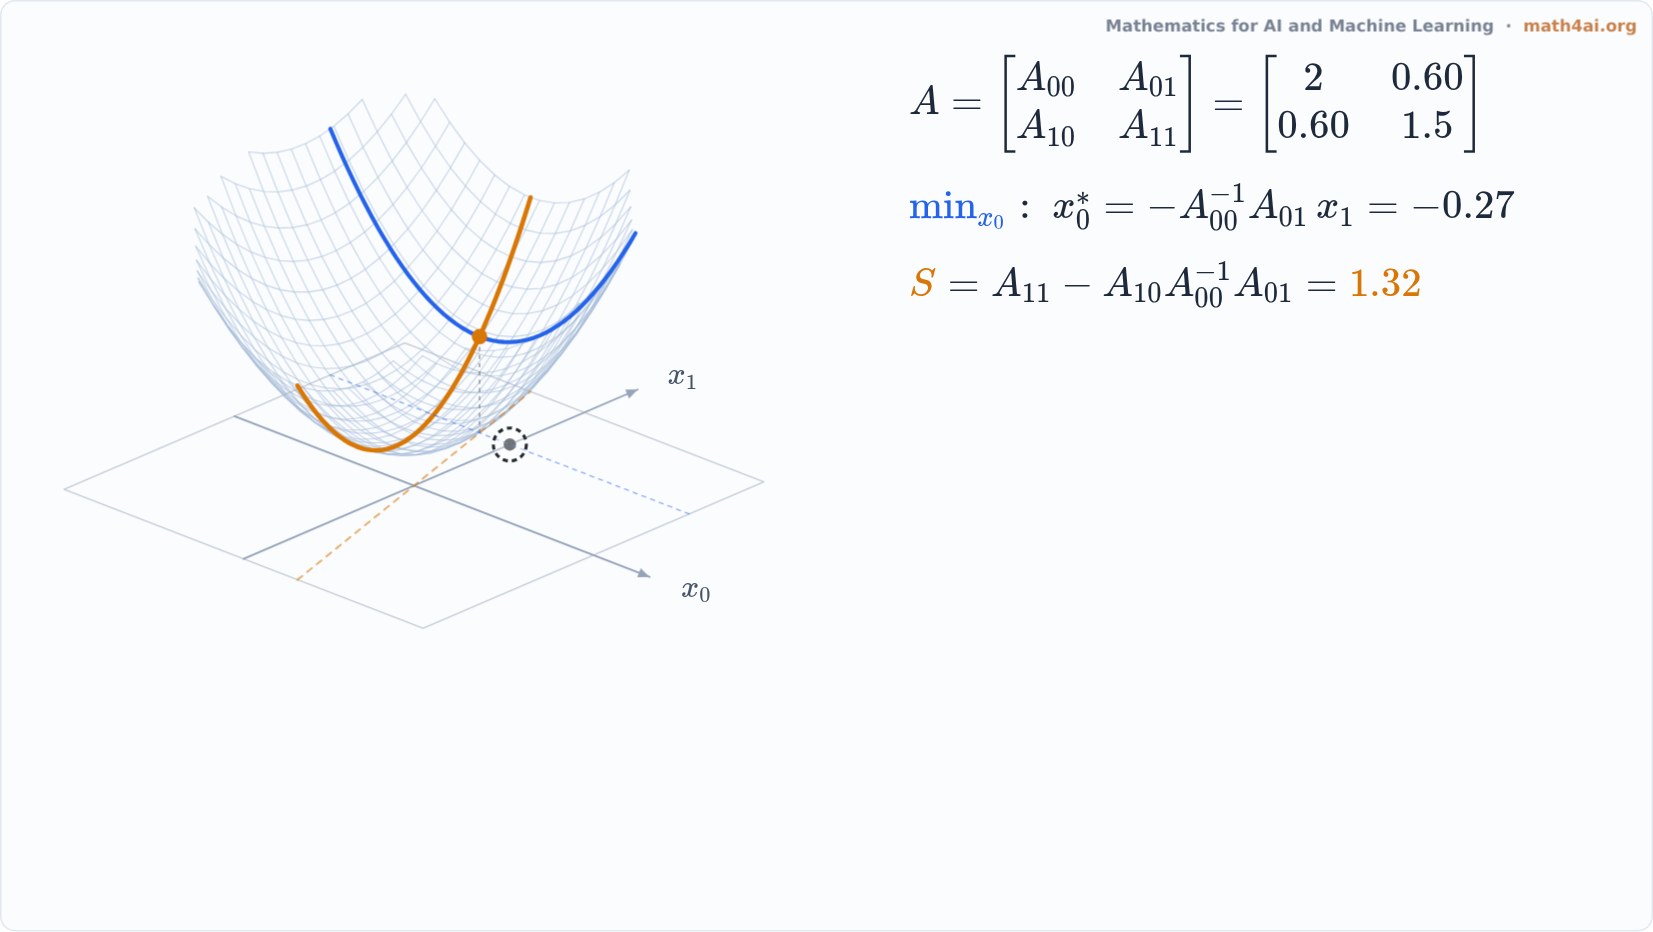 Preview1:40Schur Complement: What Is Left After Minimizing Out a BlockChapter 10
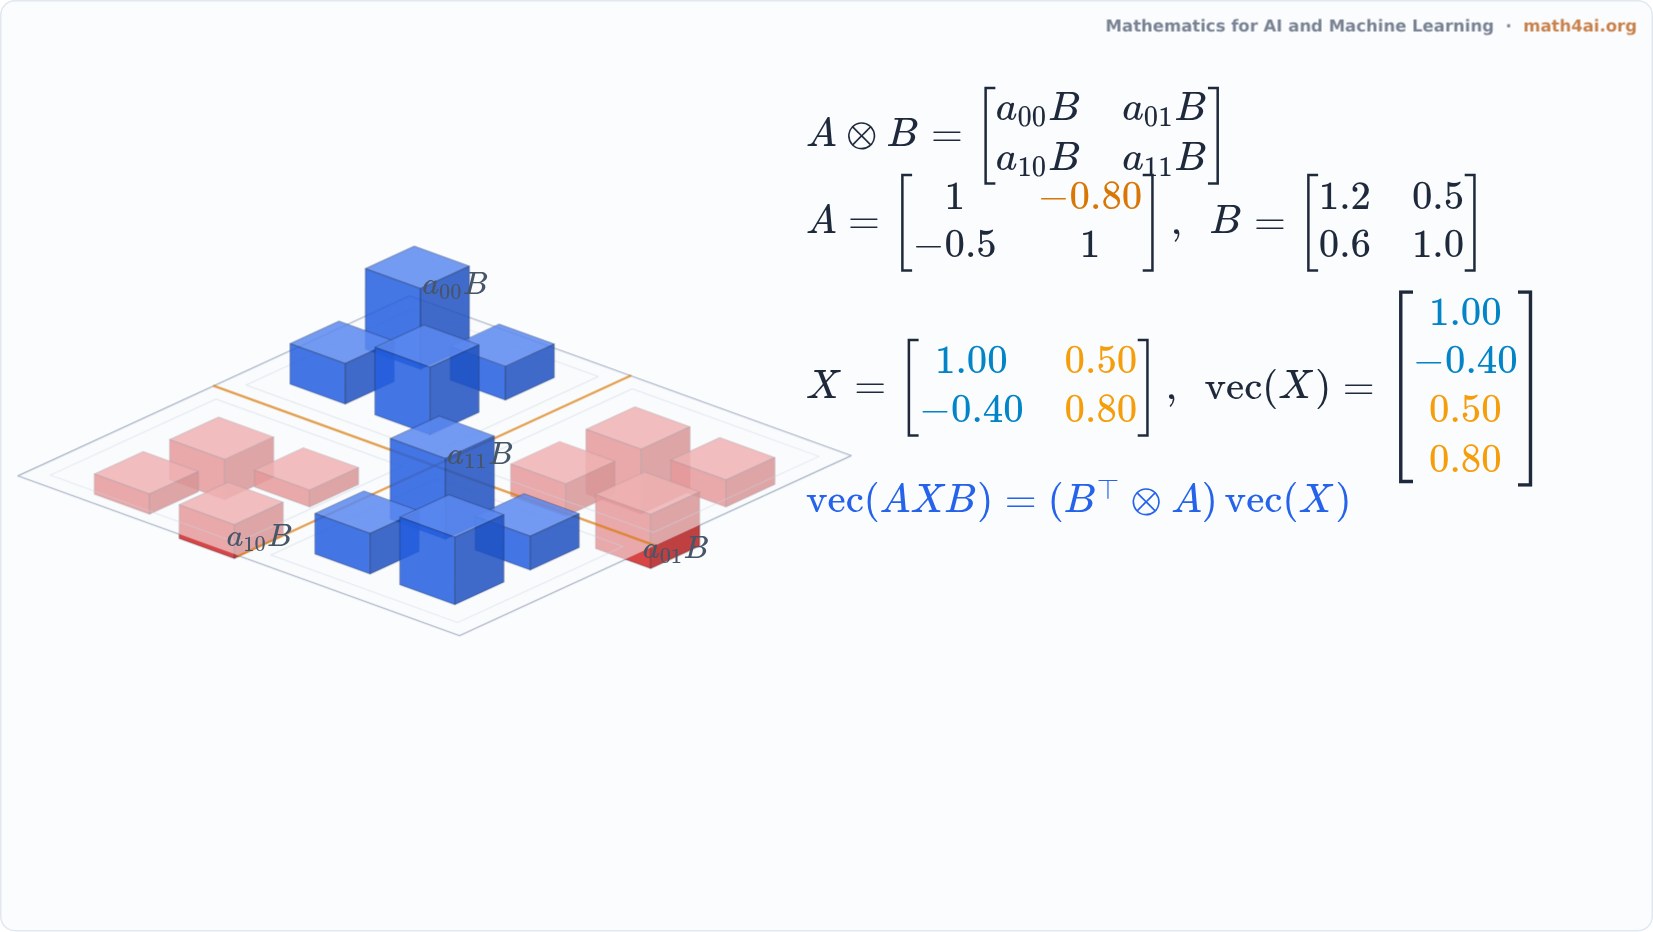 Preview1:32Kronecker Product and the Vectorization IdentityChapter 10
 Preview1:40Block Cholesky: Two Steps to a CircleChapter 10
 Preview1:56Mixture of Experts: Routing Tokens to a Few BlocksChapter 10