165 live films. 21 are free to play here, one from every chapter; the others are in the book's Companion.
Chapter 1 Vector Space and Inner Product
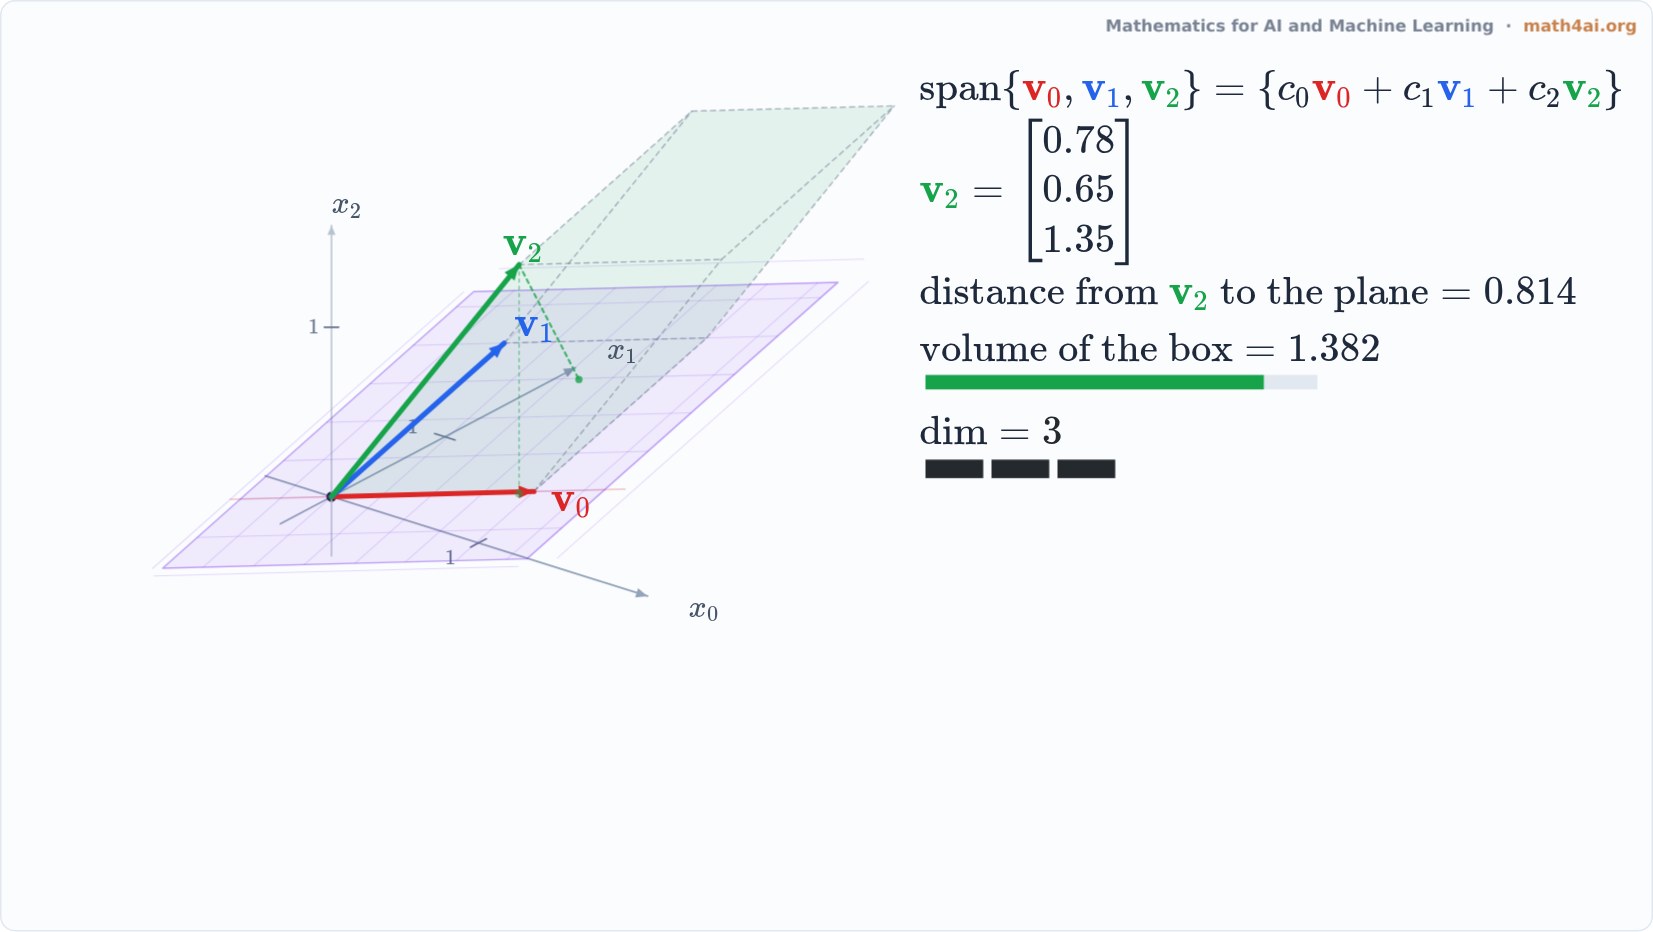 Interactive1:30Span and Independence: When the Dimension JumpsChapter 1
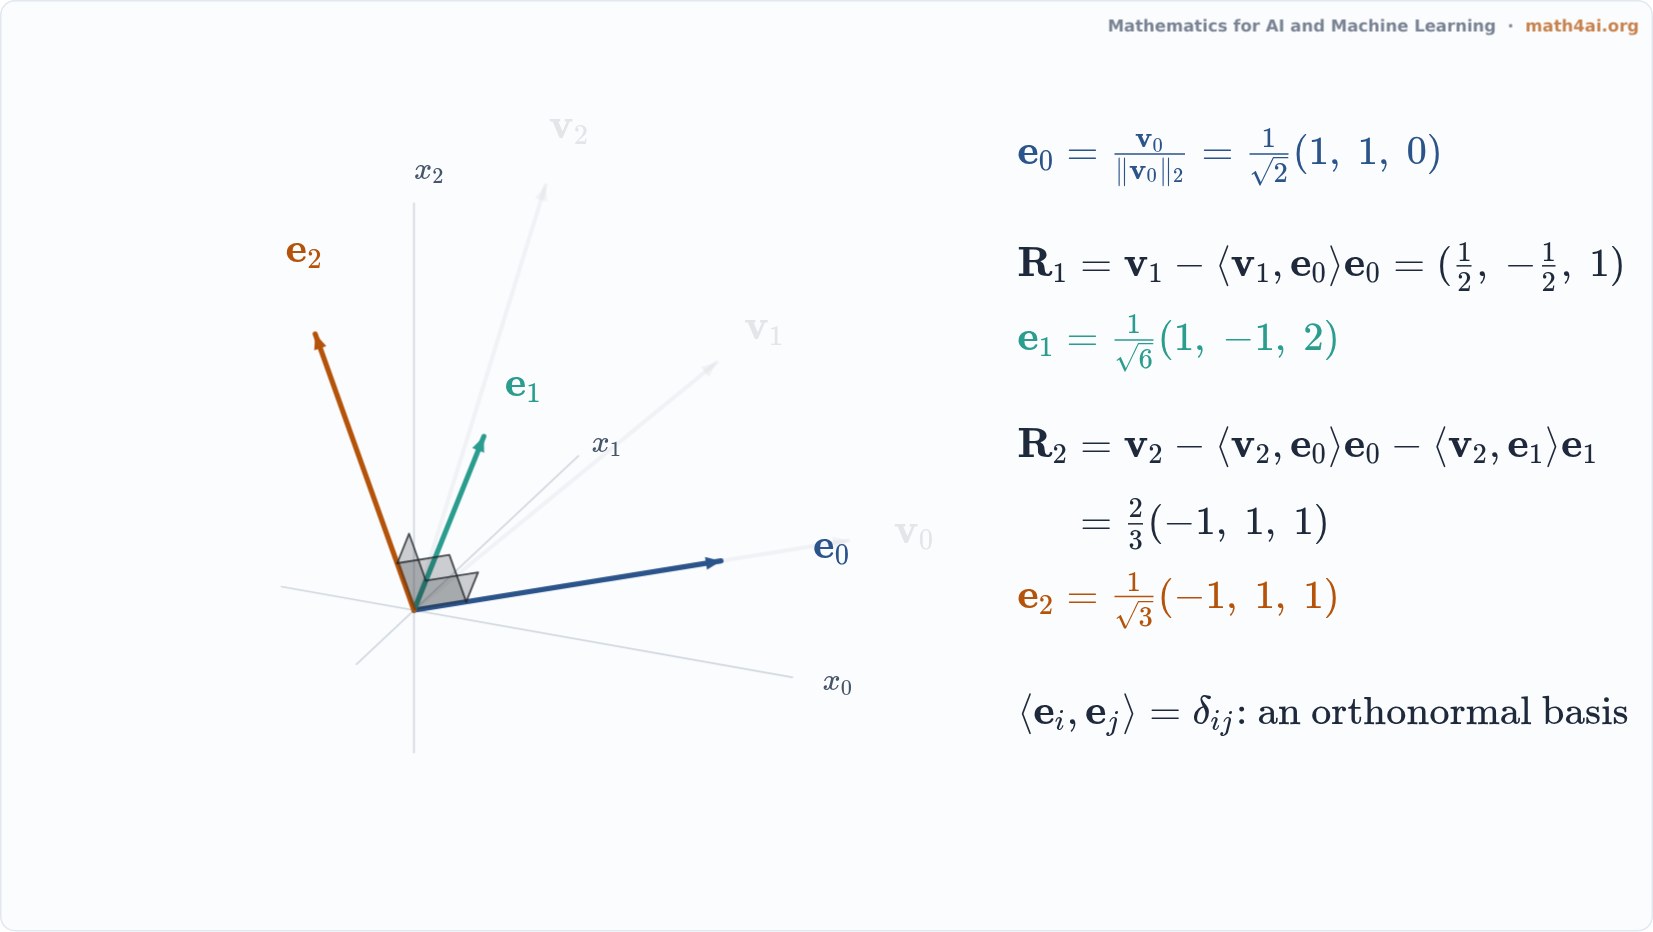 Preview1:31Gram–Schmidt, One Vector at a TimeChapter 1
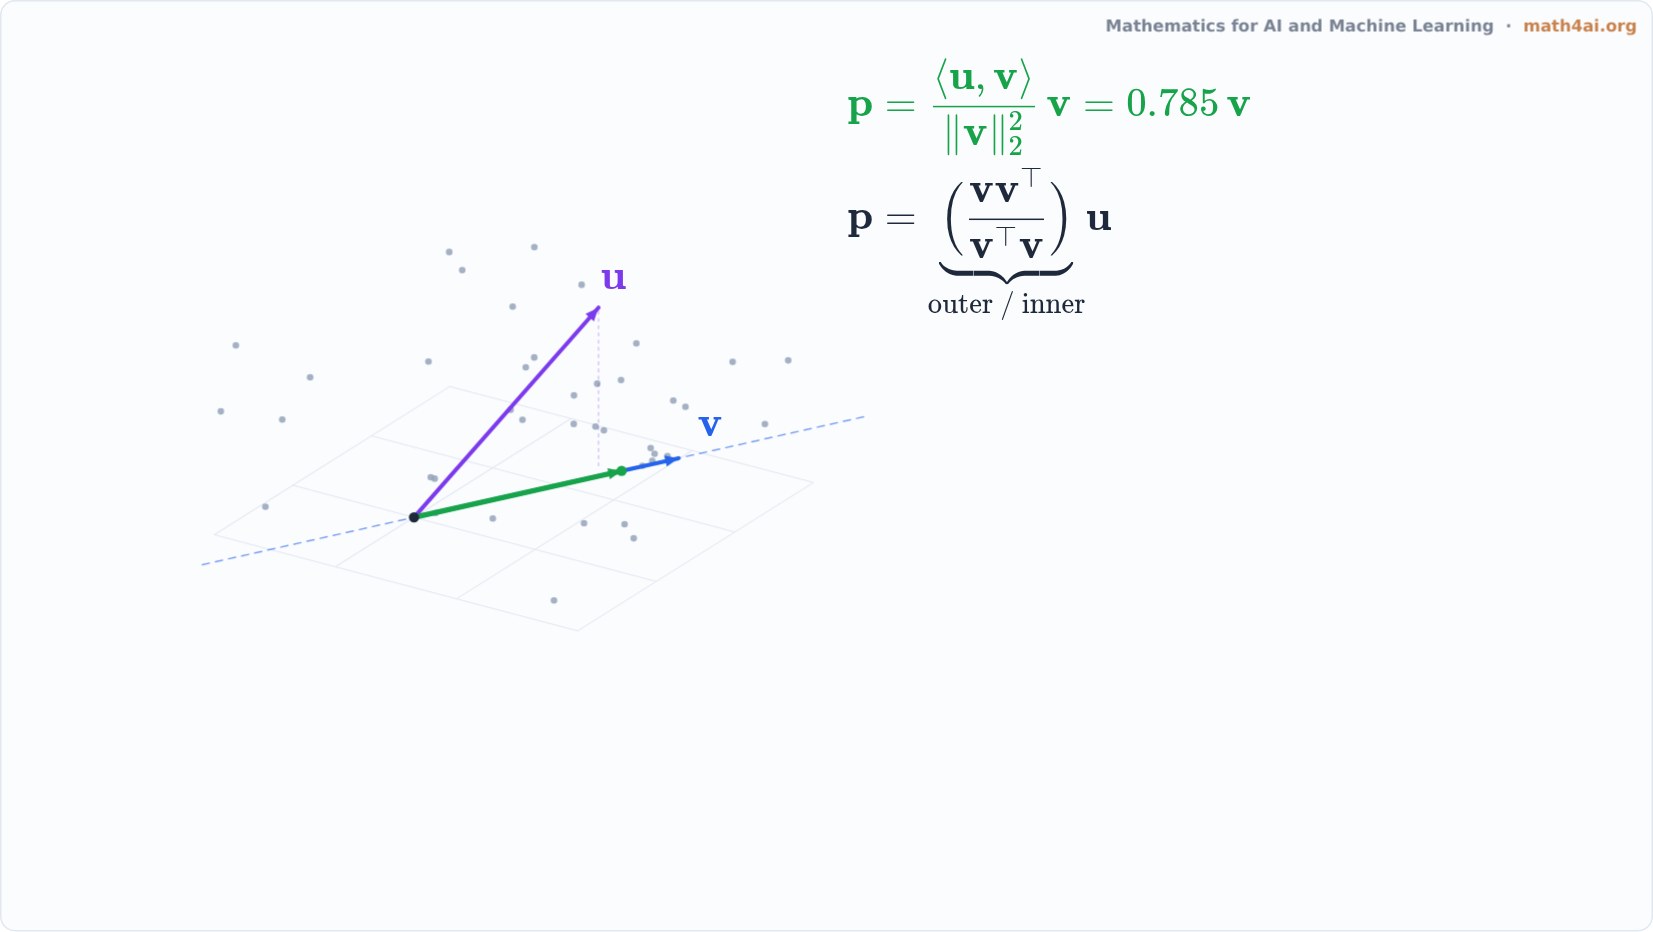 Preview1:42Projection onto a Line: the Closest PointChapter 1
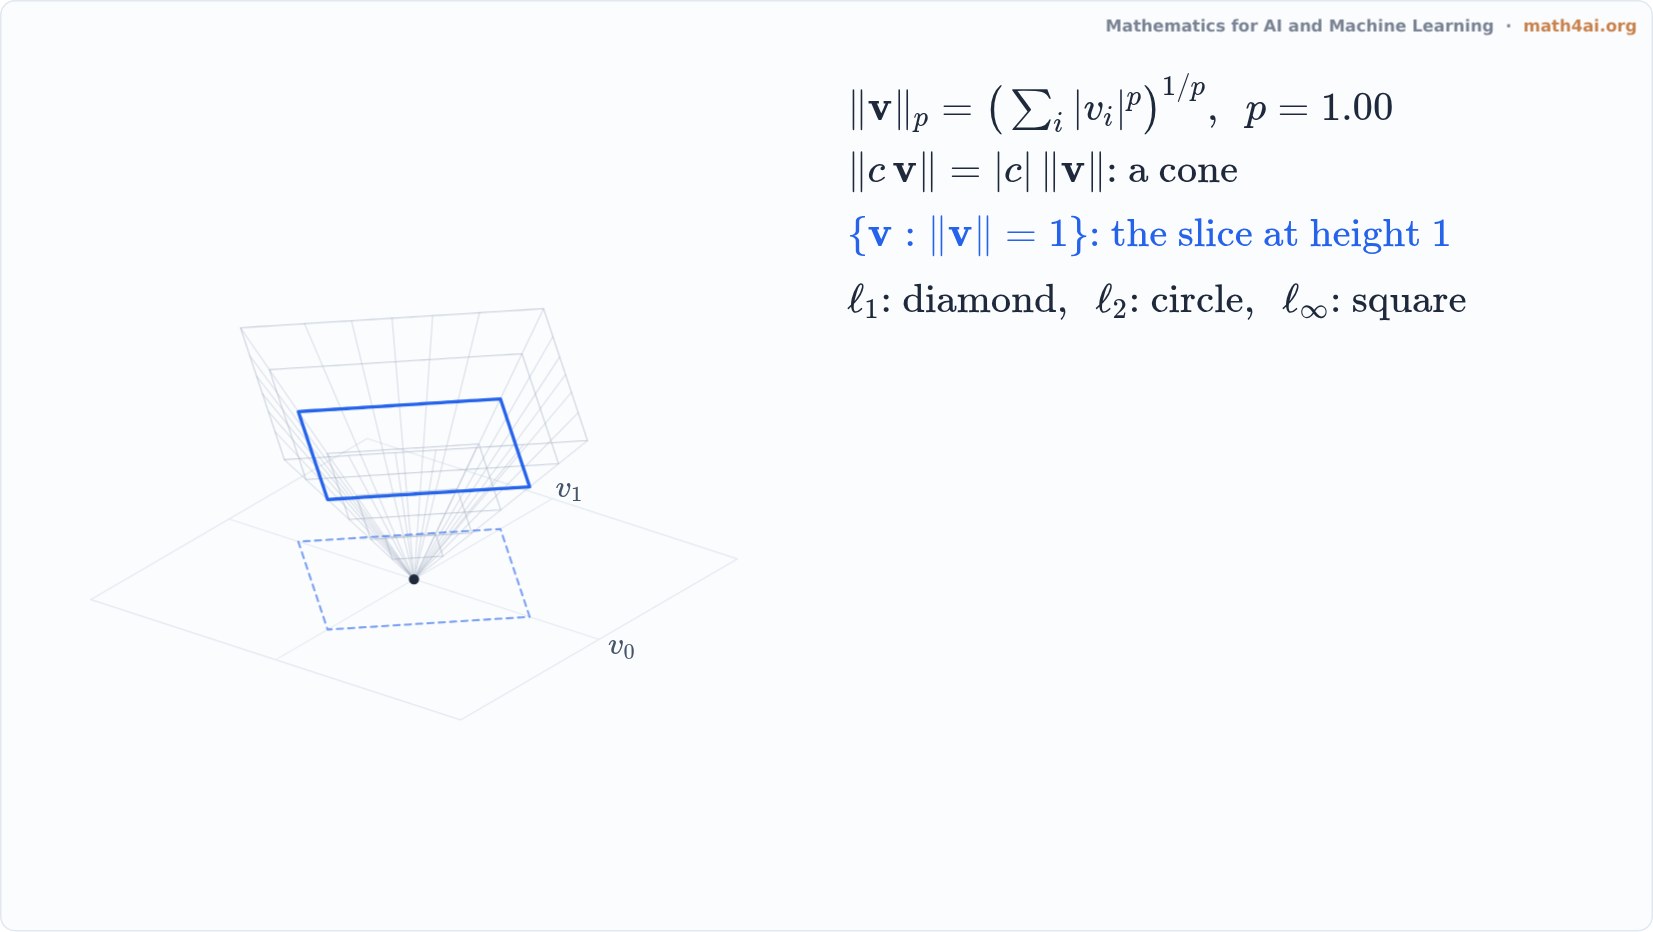 Preview1:42Norms as Cones: the Unit Ball Is a SliceChapter 1
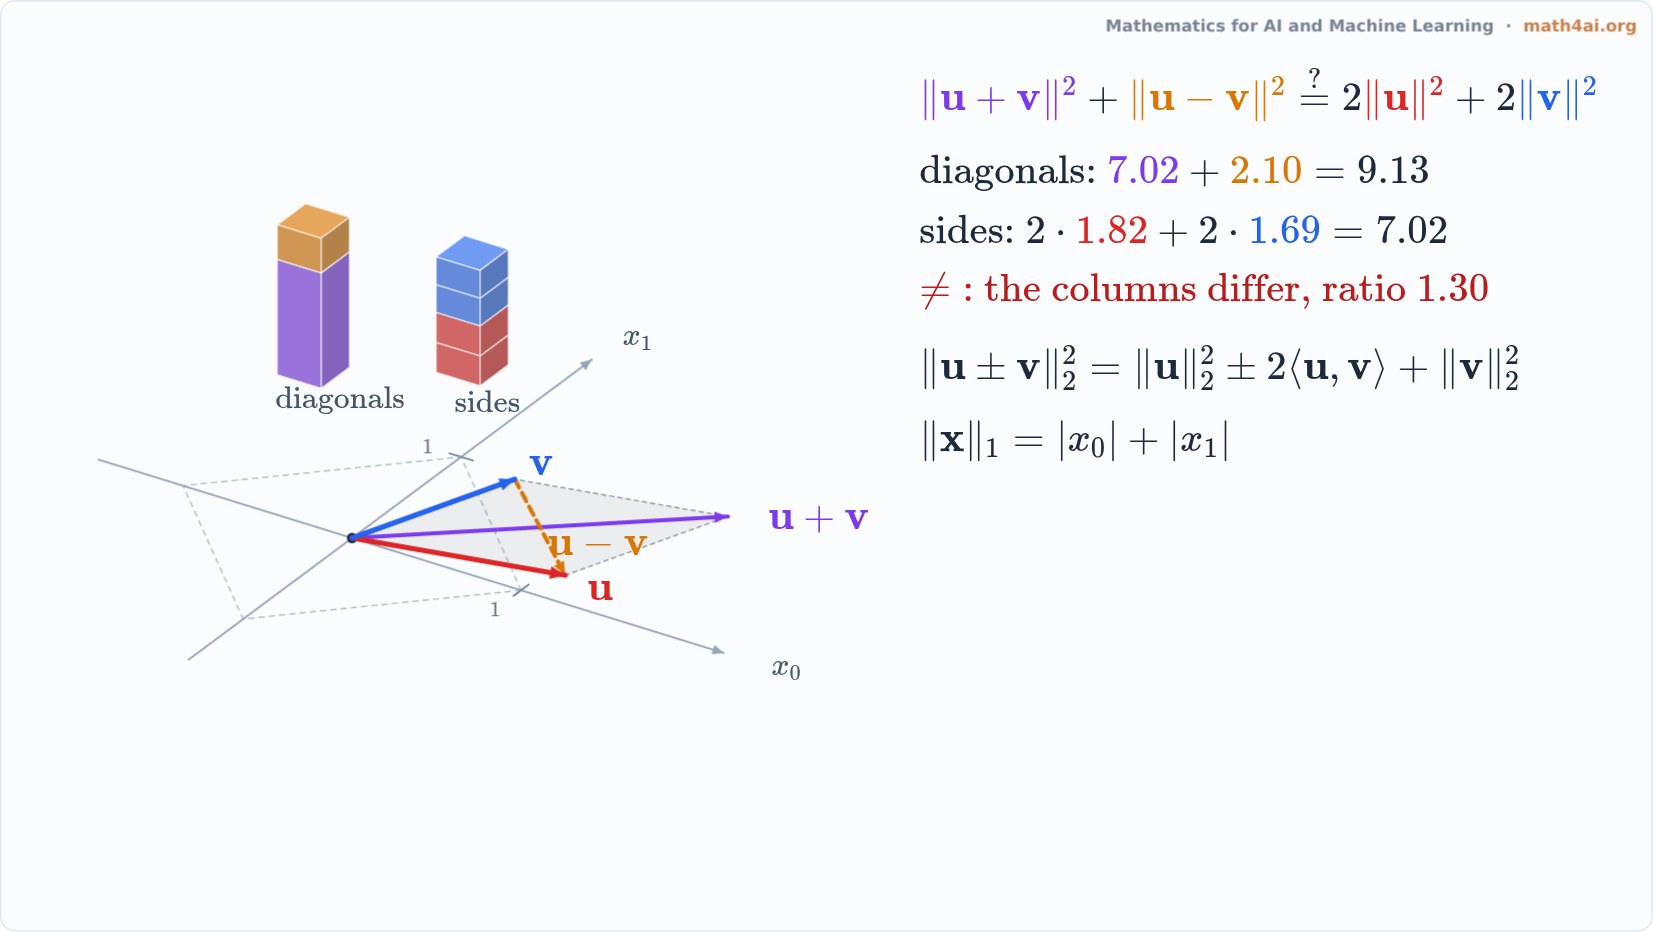 Preview1:36The Parallelogram Law: Which Norms Come from an Inner ProductChapter 1
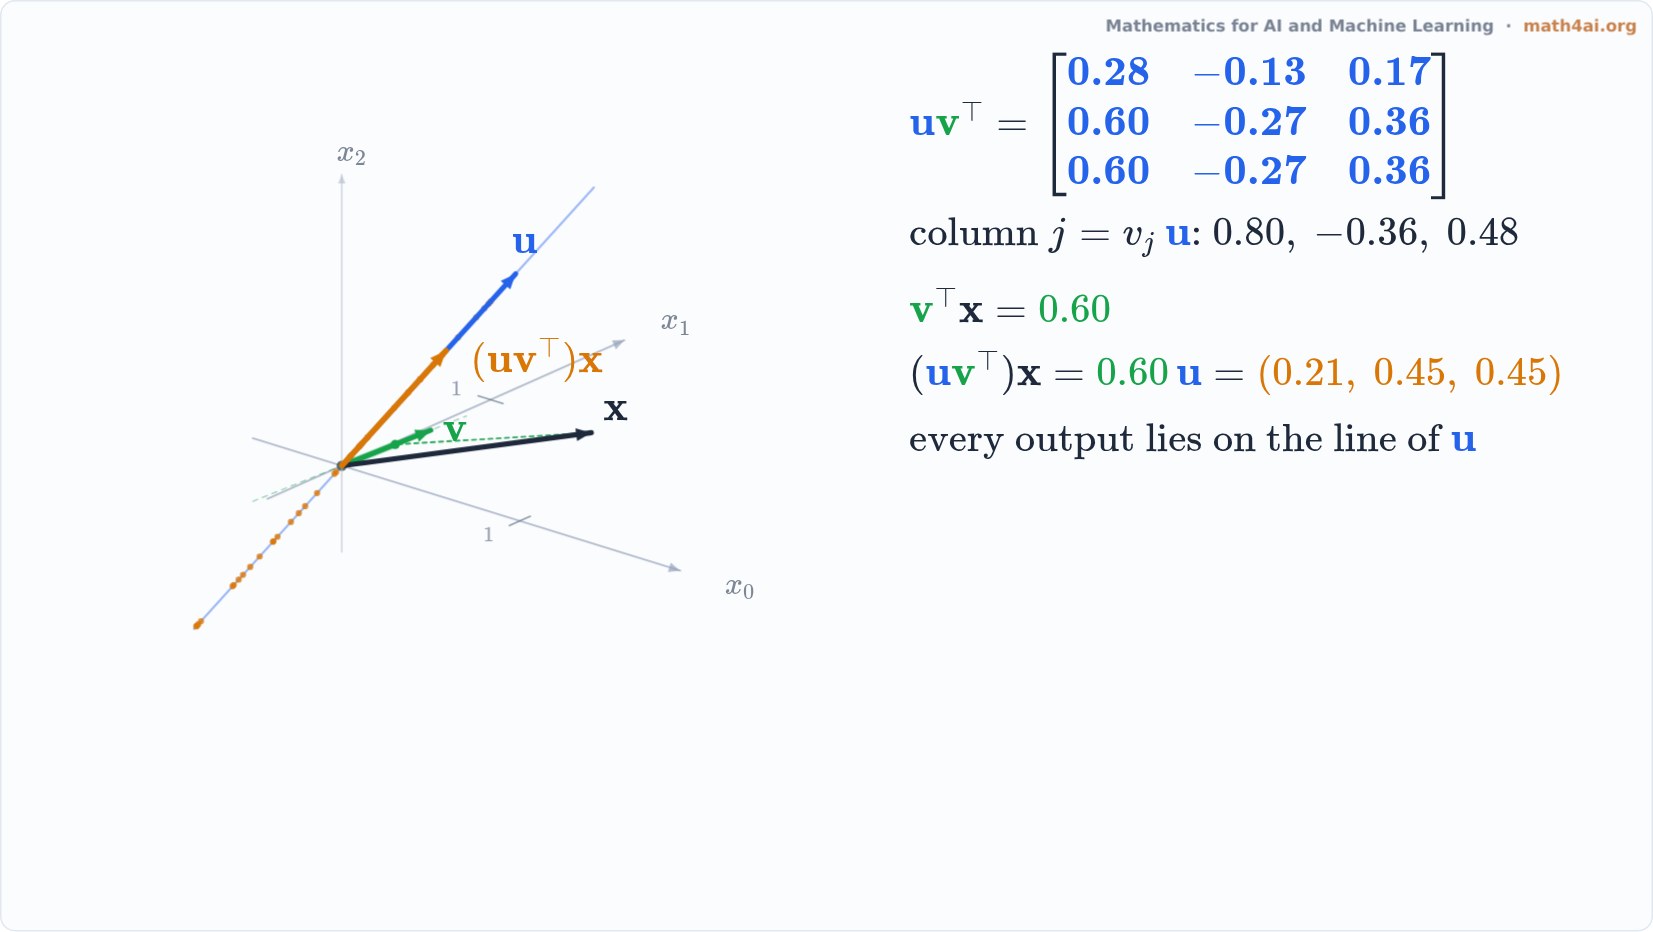 Preview1:31The Outer Product: All of Space onto One LineChapter 1
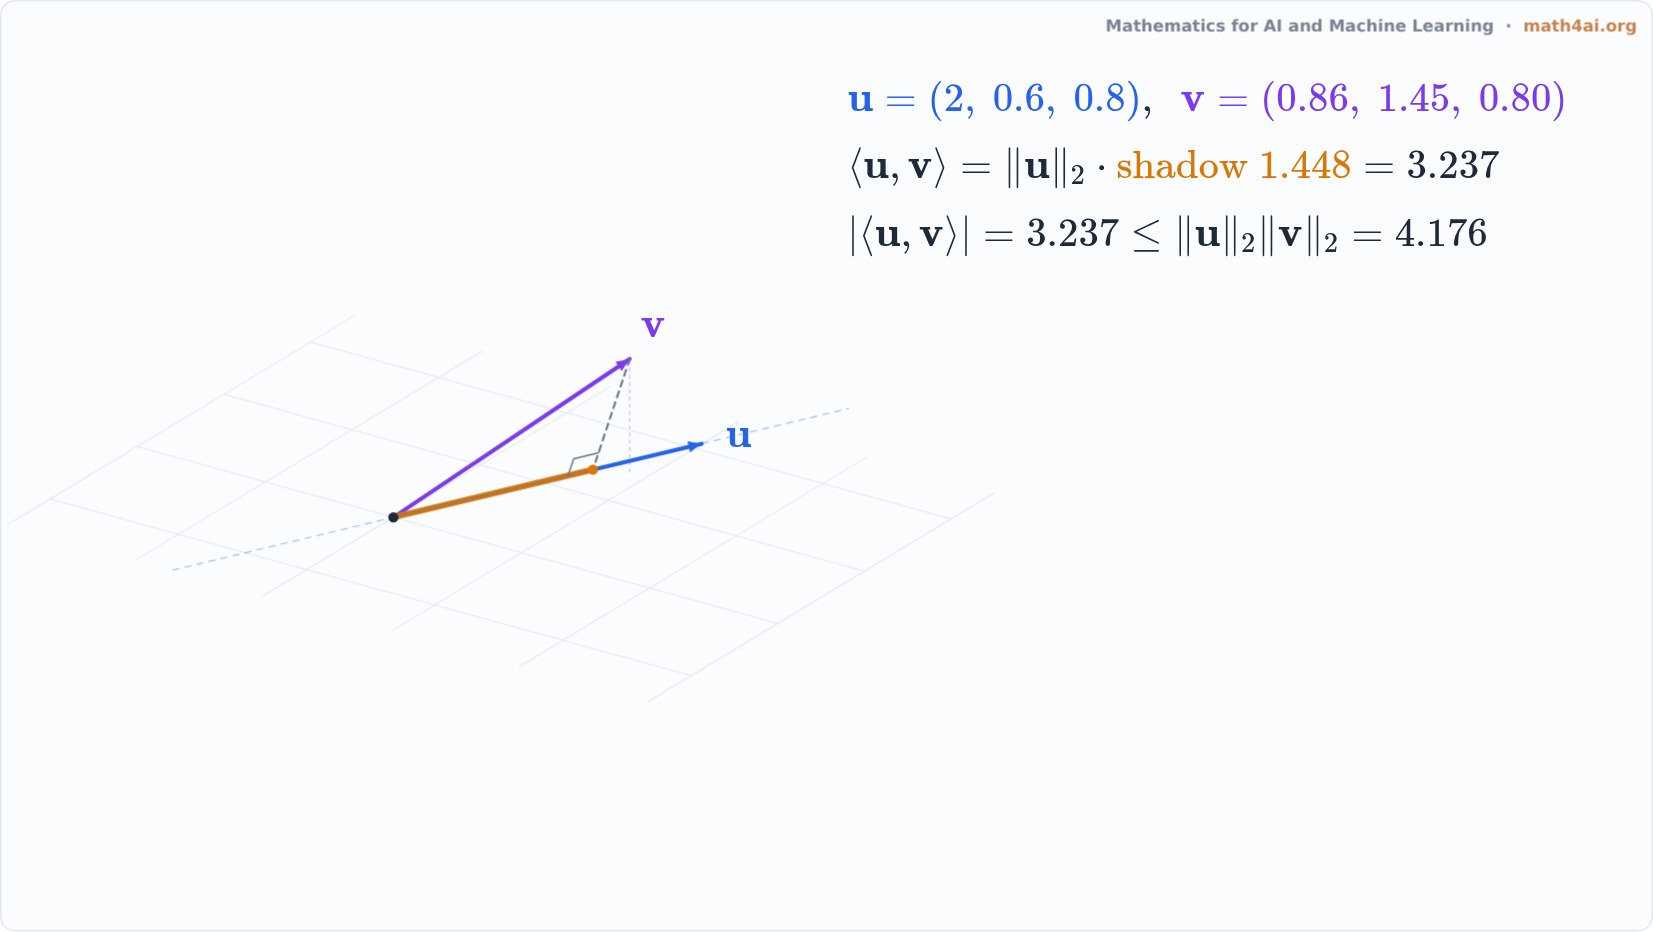 Preview1:29Cauchy-Schwarz: a Shadow Is Never Longer than the StickChapter 1
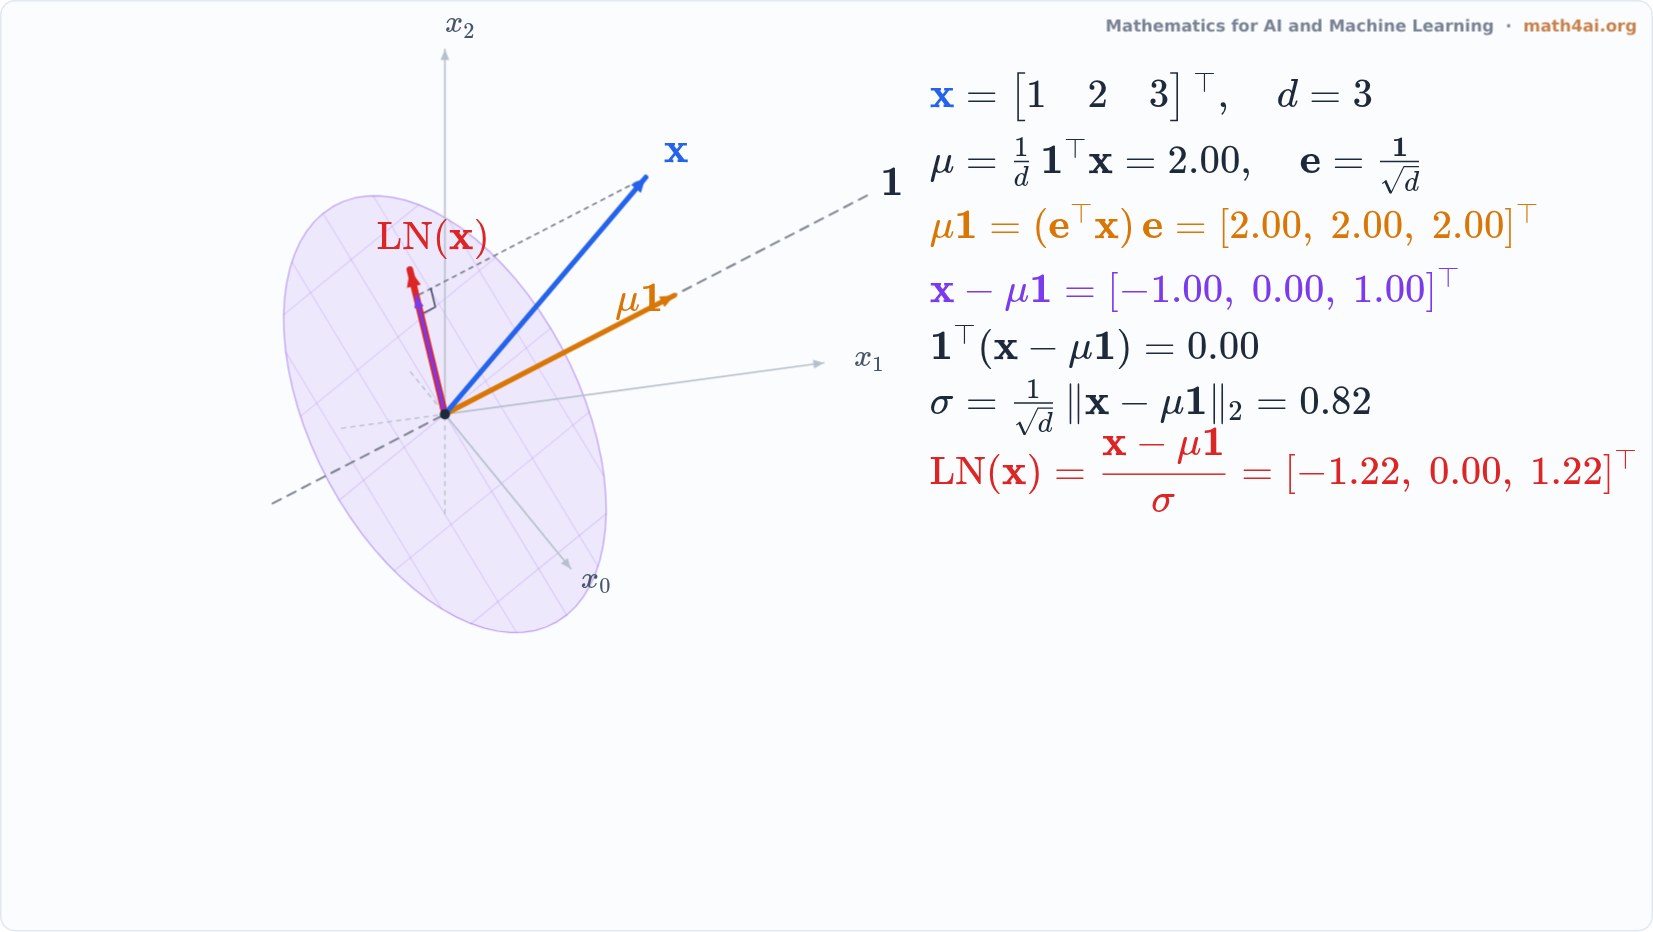 Preview1:43Layer Normalization: Project, Then RescaleChapter 1
Chapter 2 Matrix
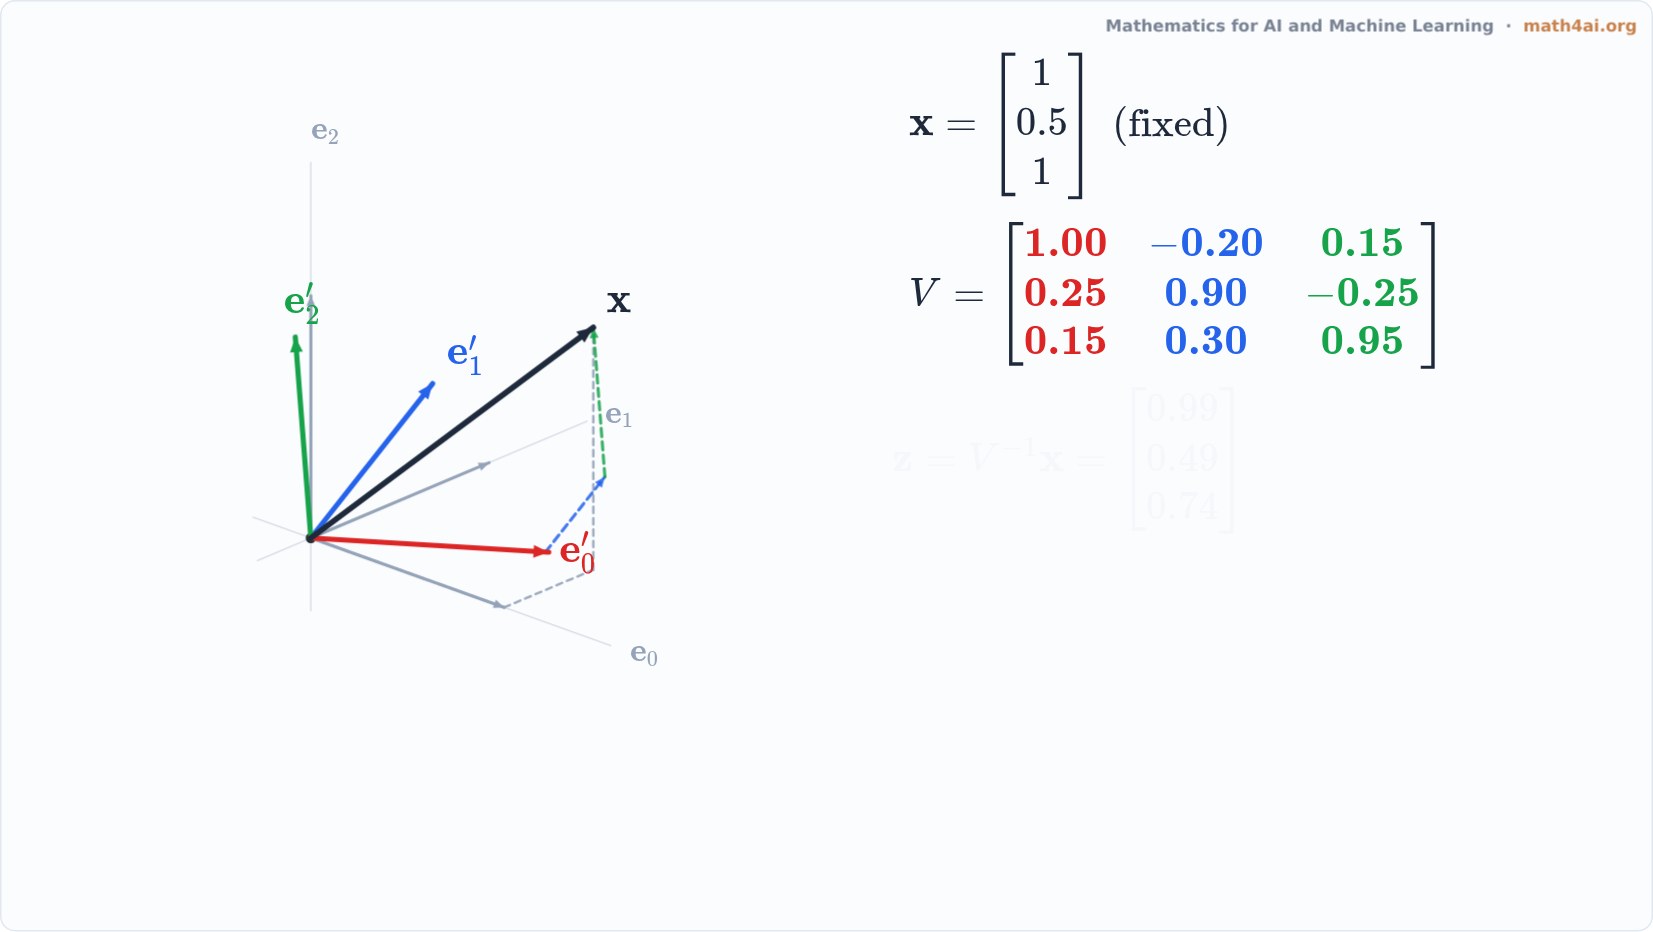 Interactive1:40Change of Basis: One Vector, Two Sets of CoordinatesChapter 2
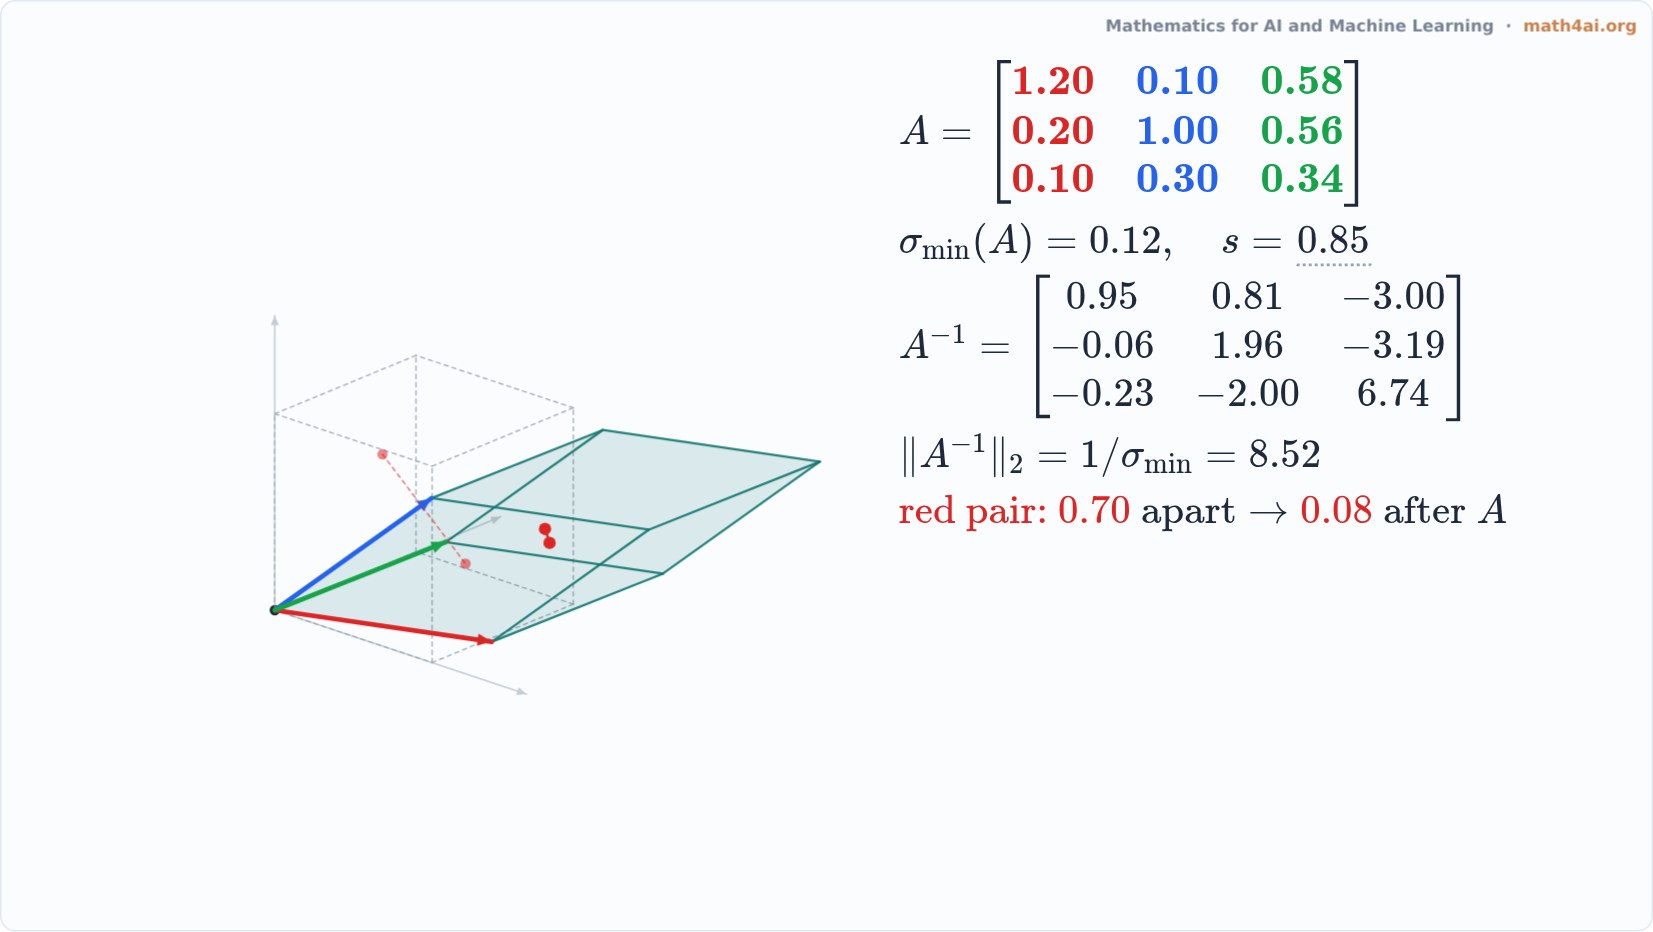 Preview1:29The Matrix Inverse: Squashed Means GoneChapter 2
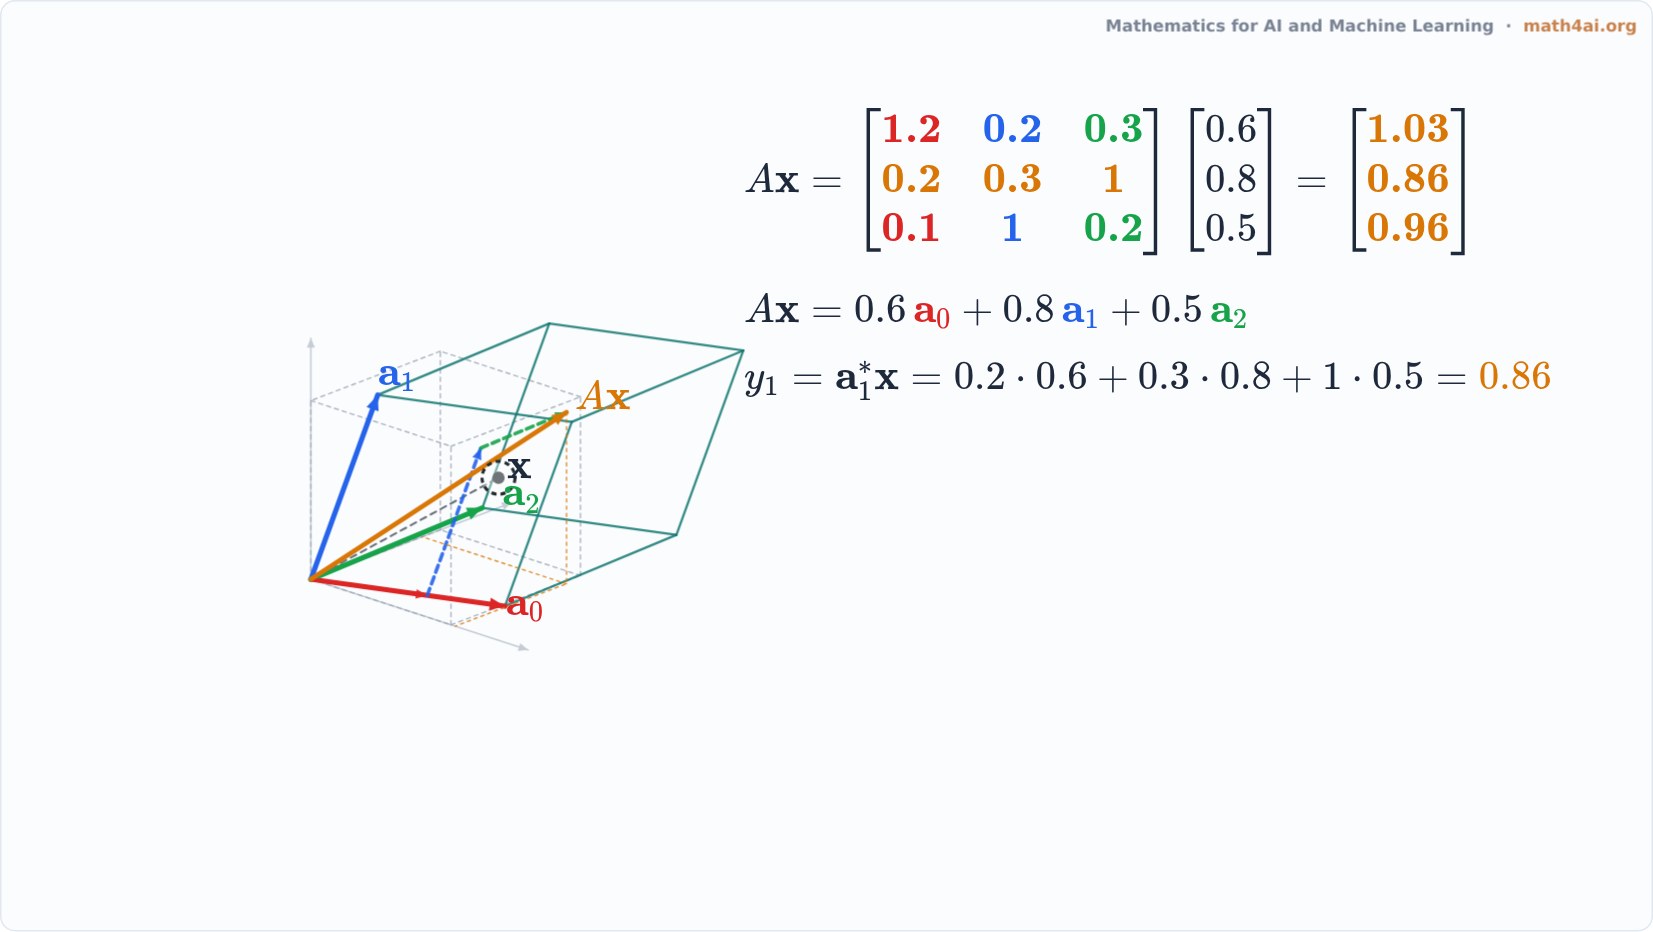 Preview1:53A Matrix Moves the CubeChapter 2
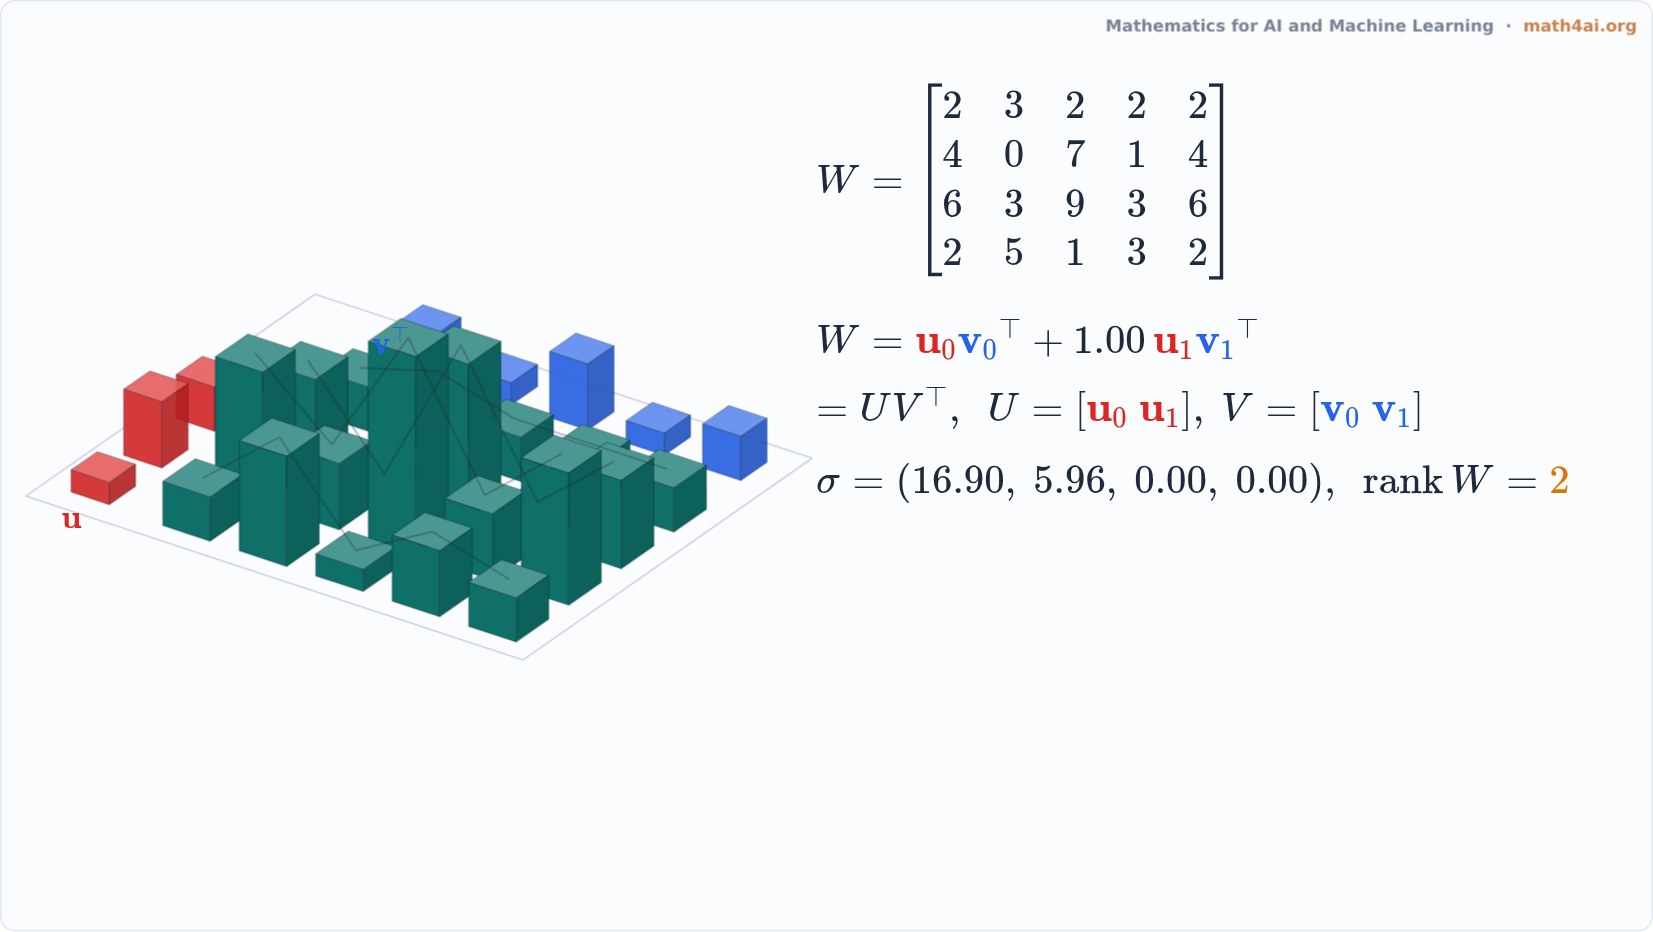 Preview1:49Rank One as a LandscapeChapter 2
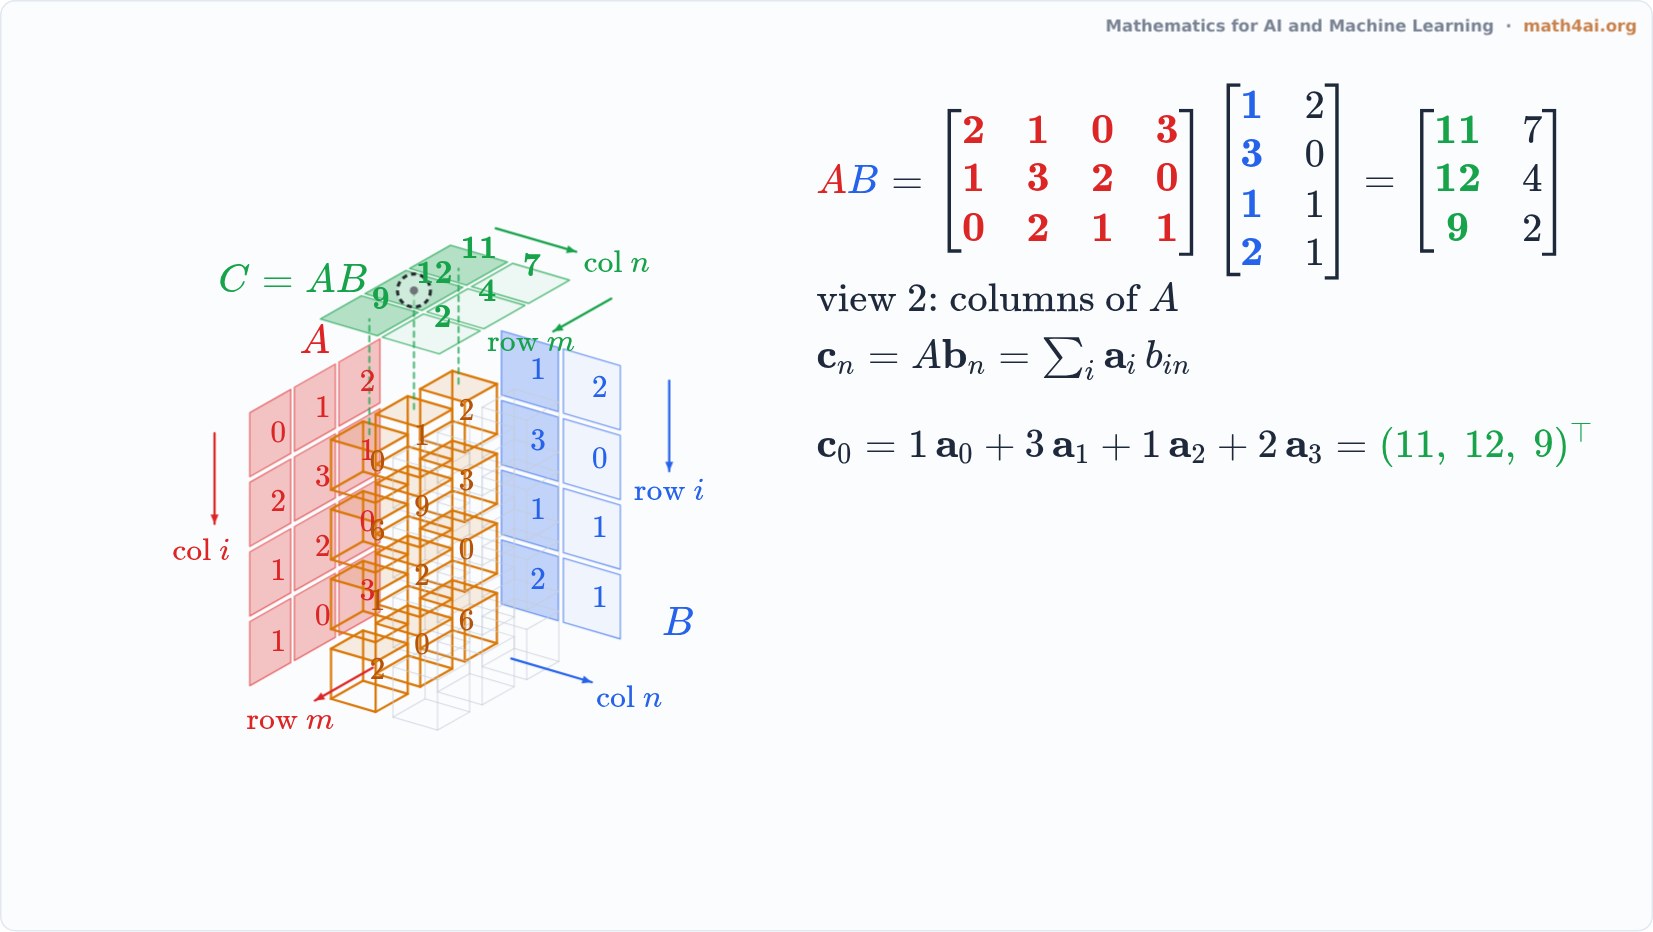 Preview2:29Four Views of Matrix MultiplicationChapter 2
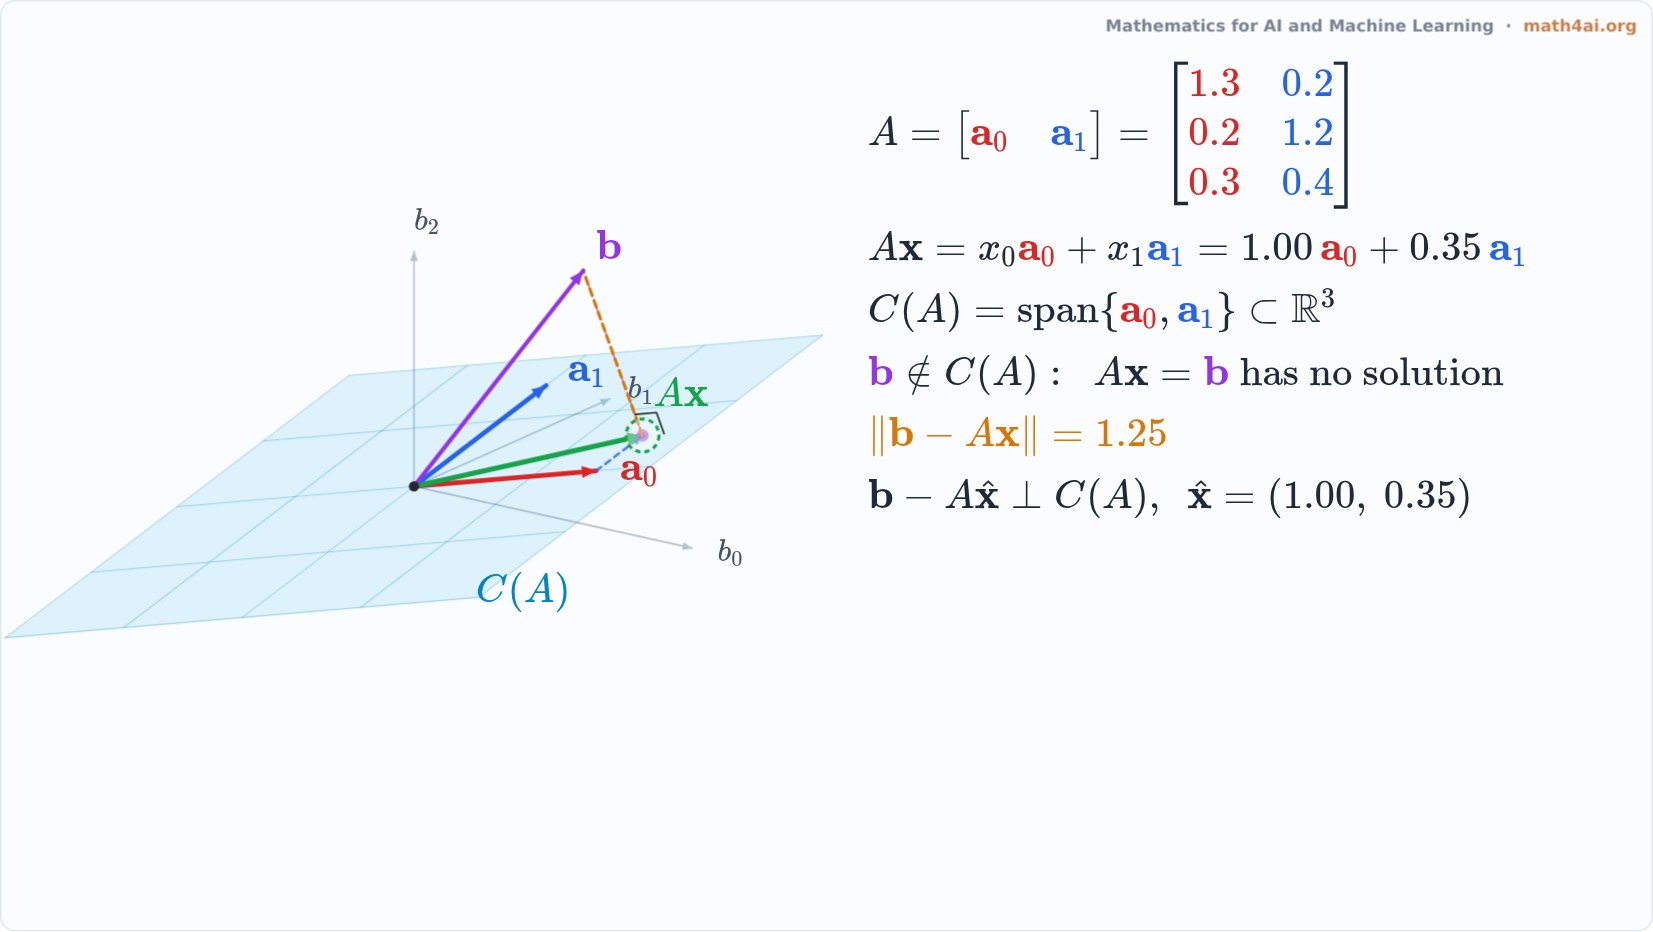 Preview1:44Column Space: Every Output Ax Lies on One PlaneChapter 2
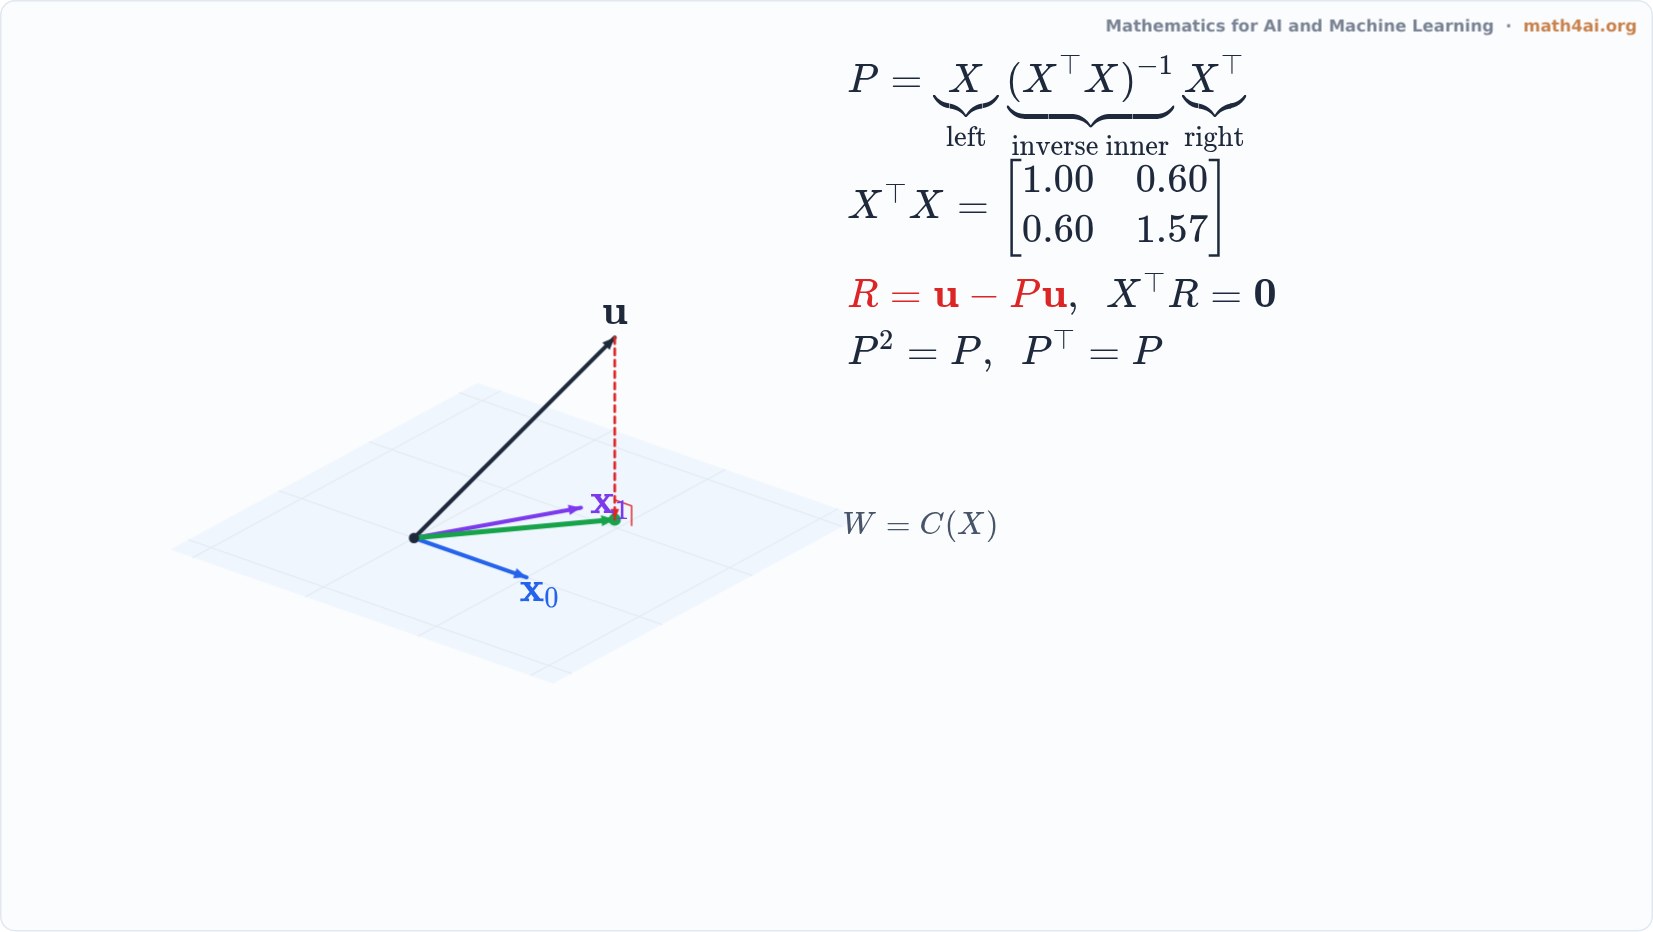 Preview1:37The Projection Matrix: Outer times Inverse InnerChapter 2
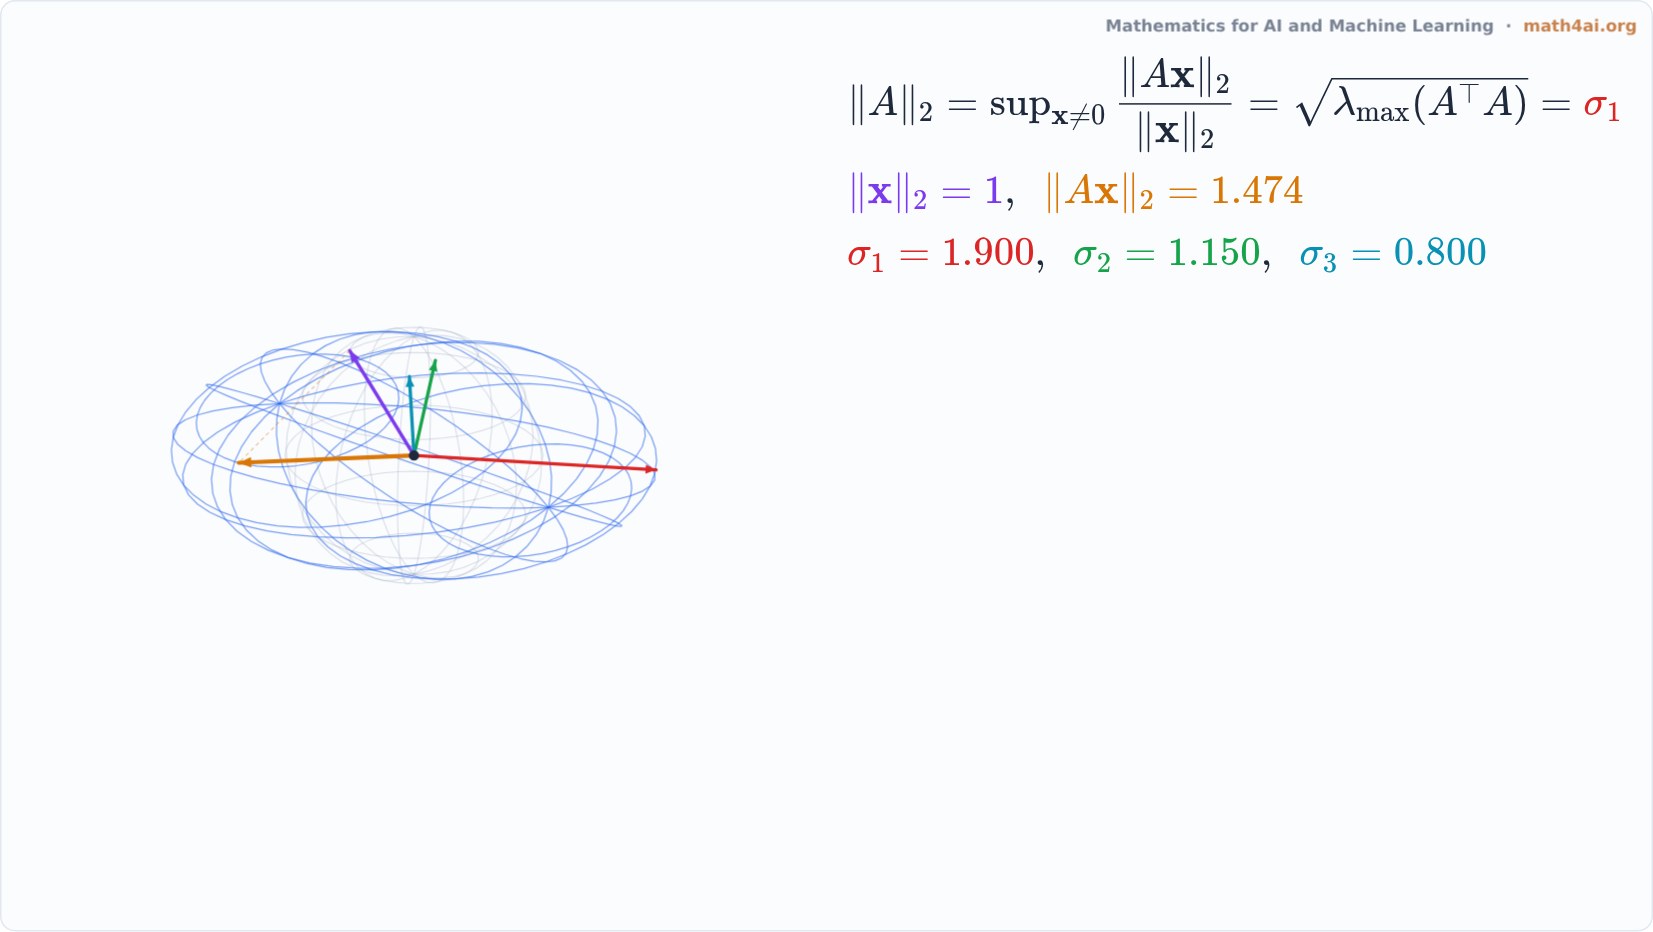 Preview1:36Matrix Norm and Condition Number: the Largest StretchChapter 2
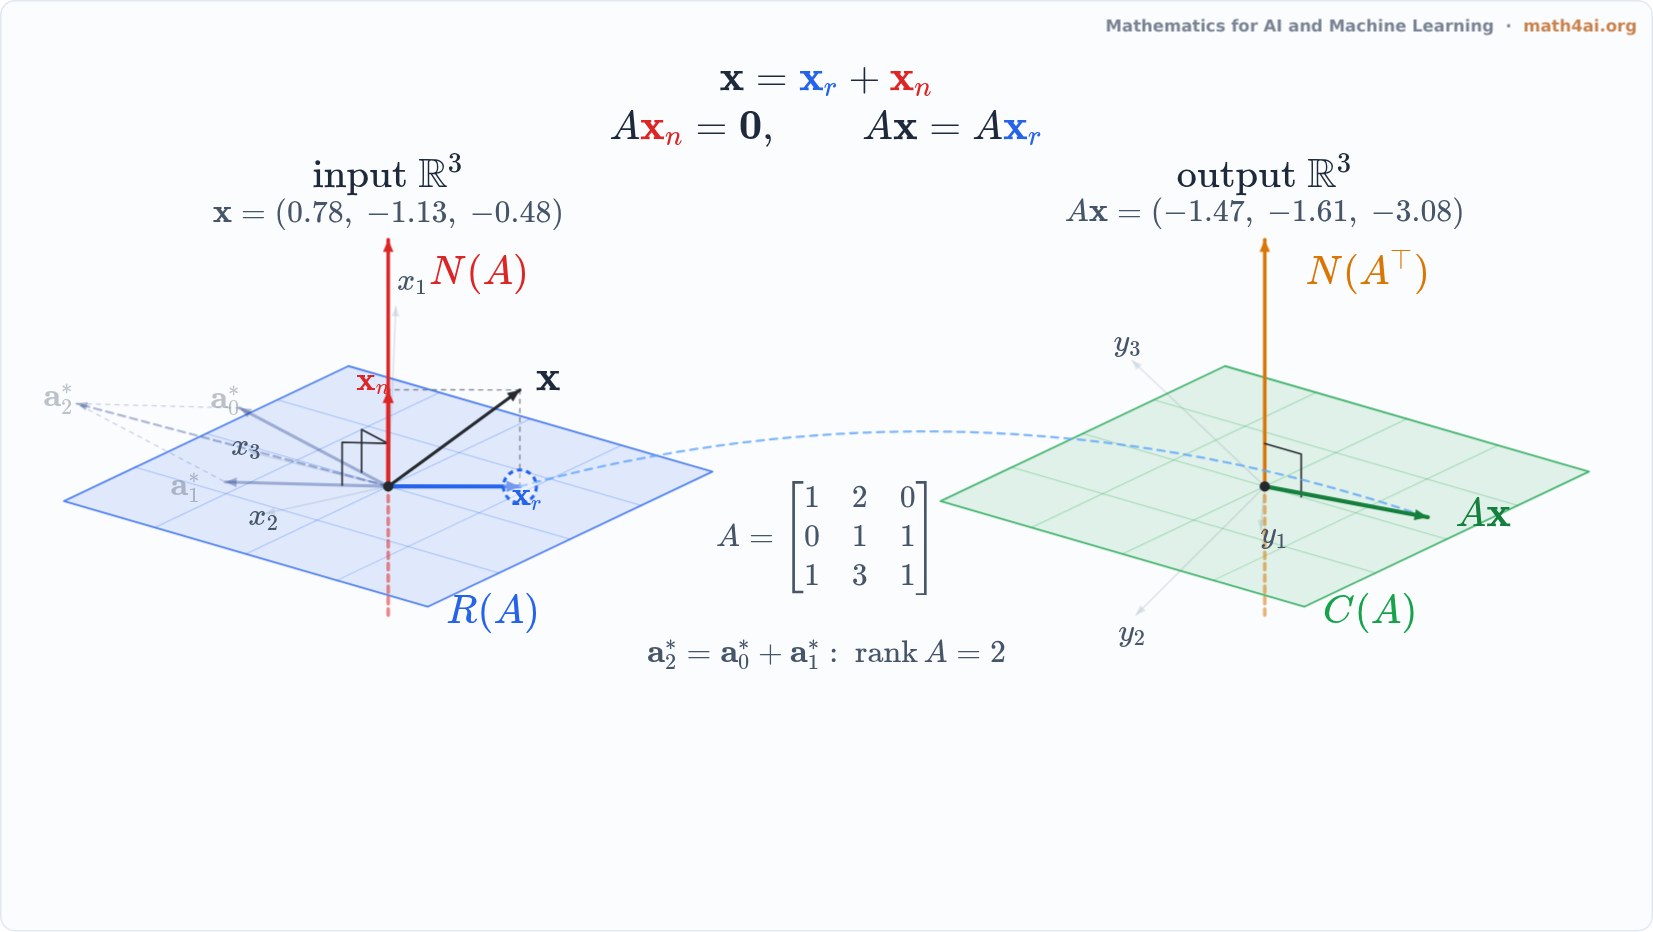
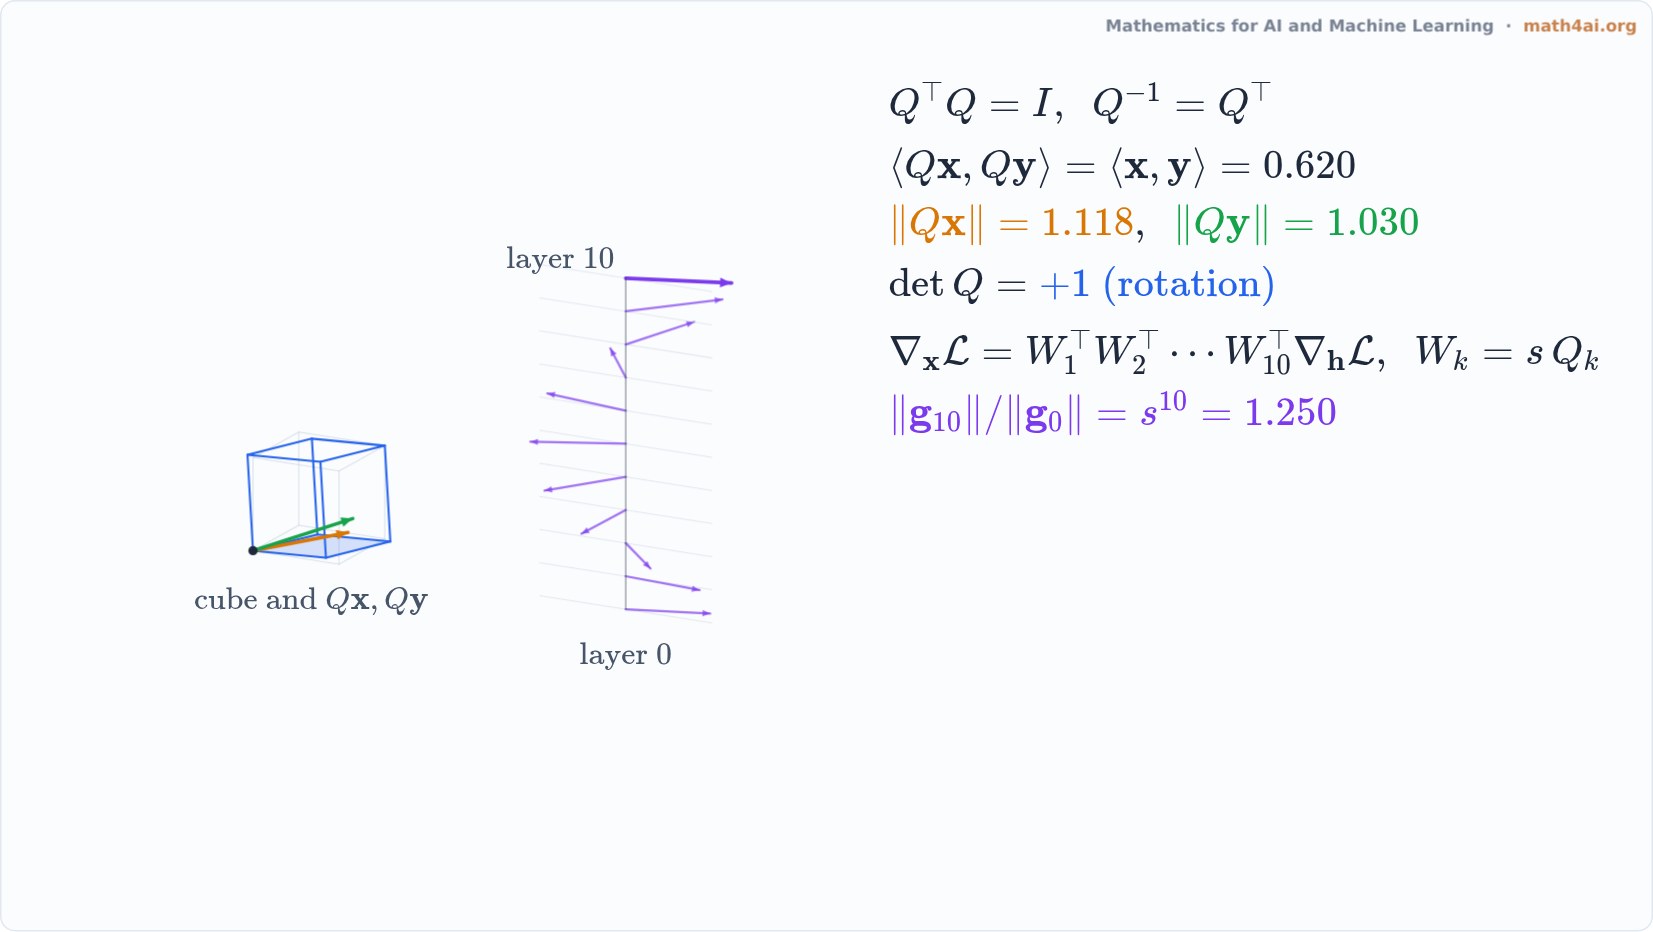
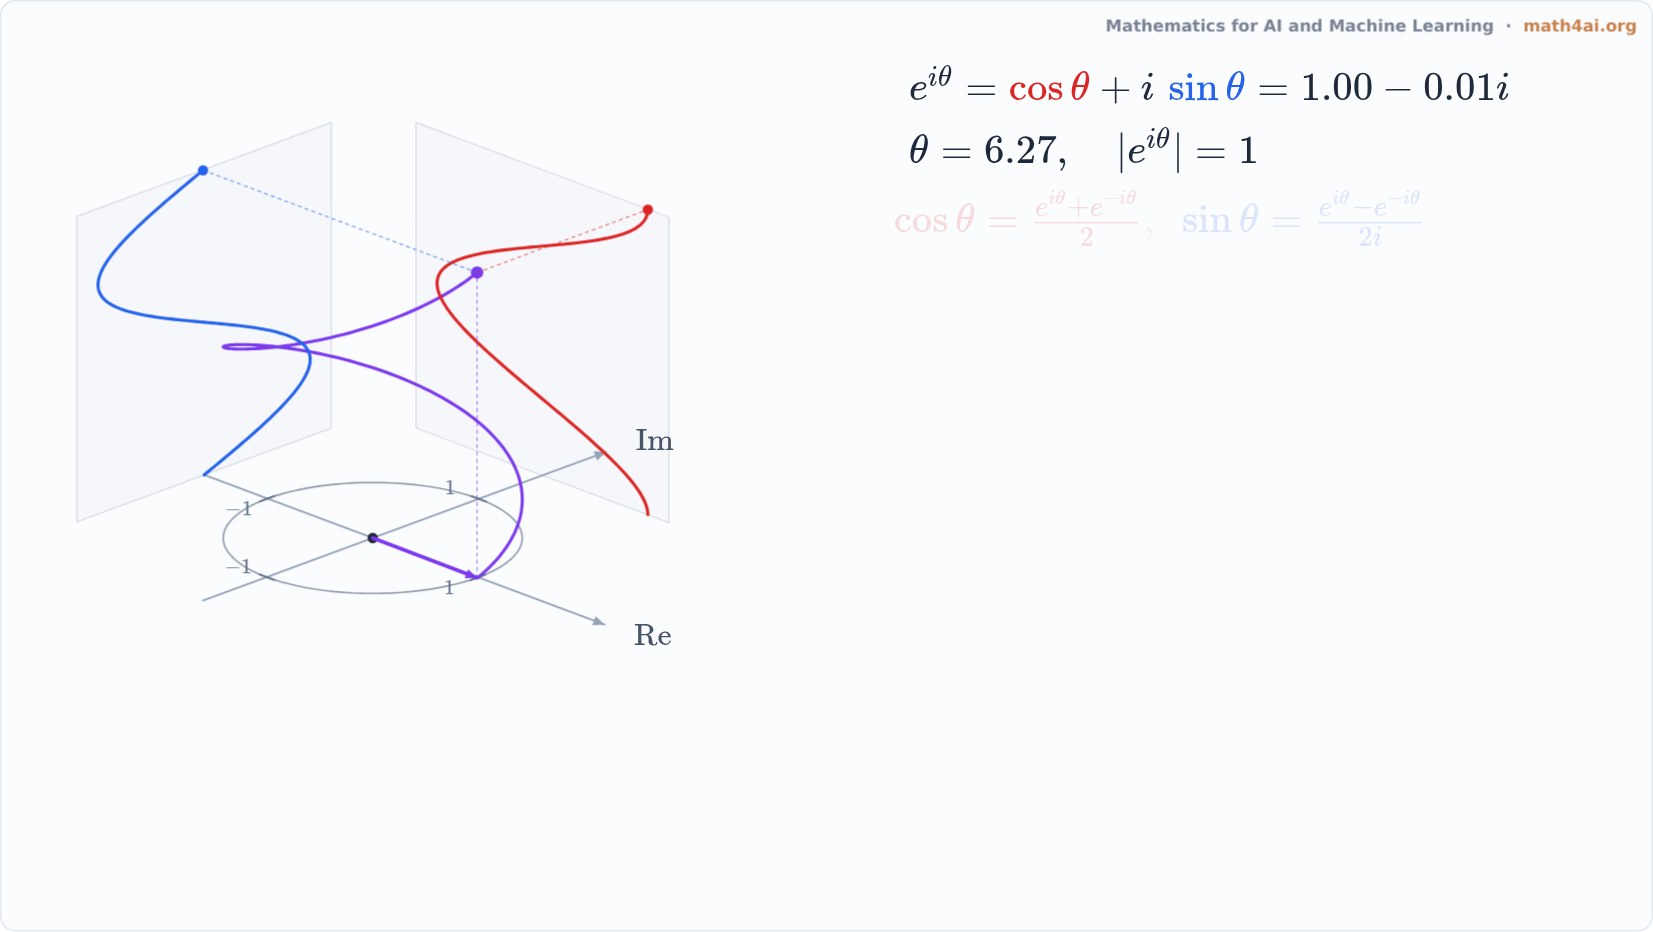
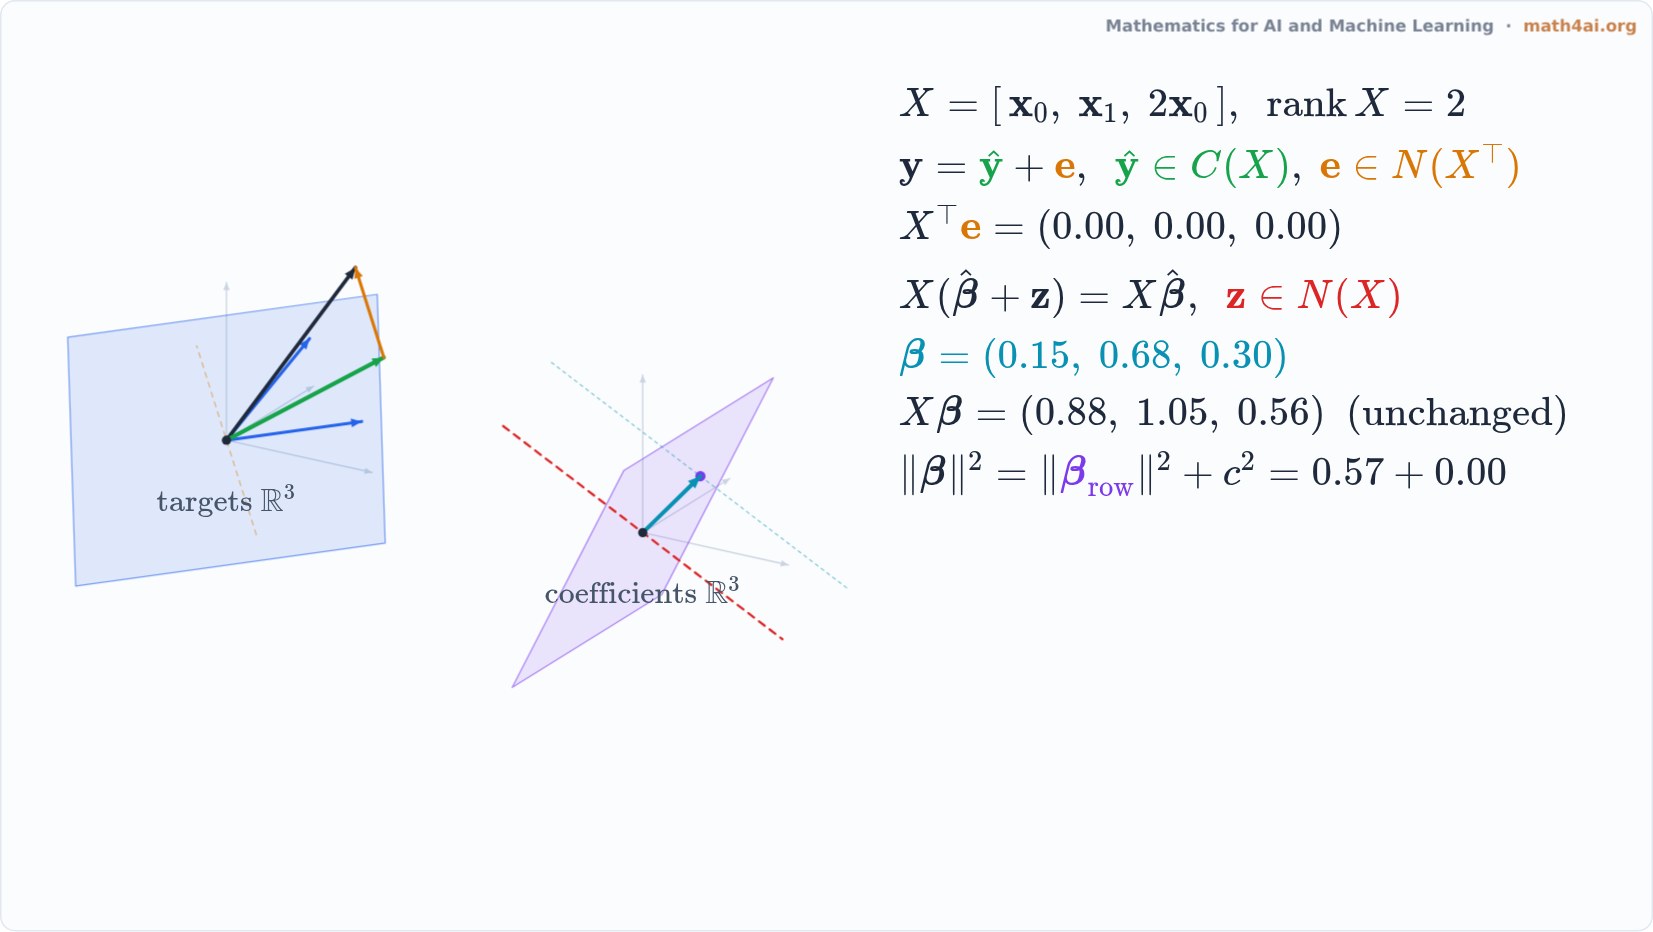
Chapter 3 Subspaces and Orthogonality
Chapter 4 QR Decomposition and Numerical Rank
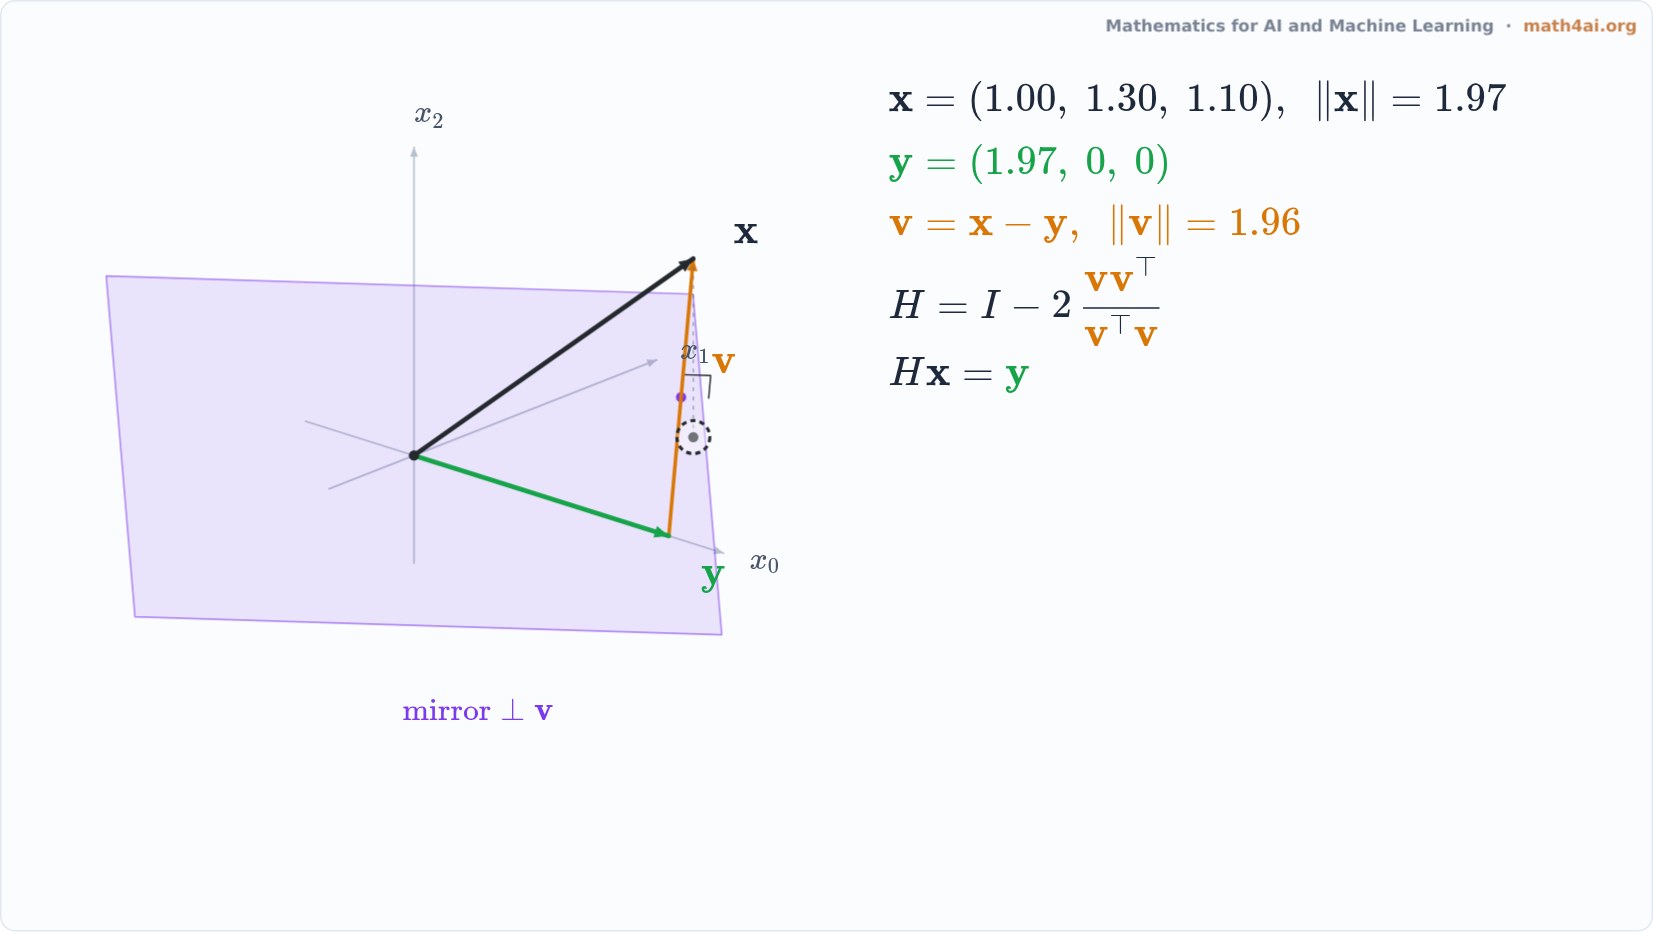 Interactive1:51Householder Reflection: A Mirror That Clears a ColumnChapter 4
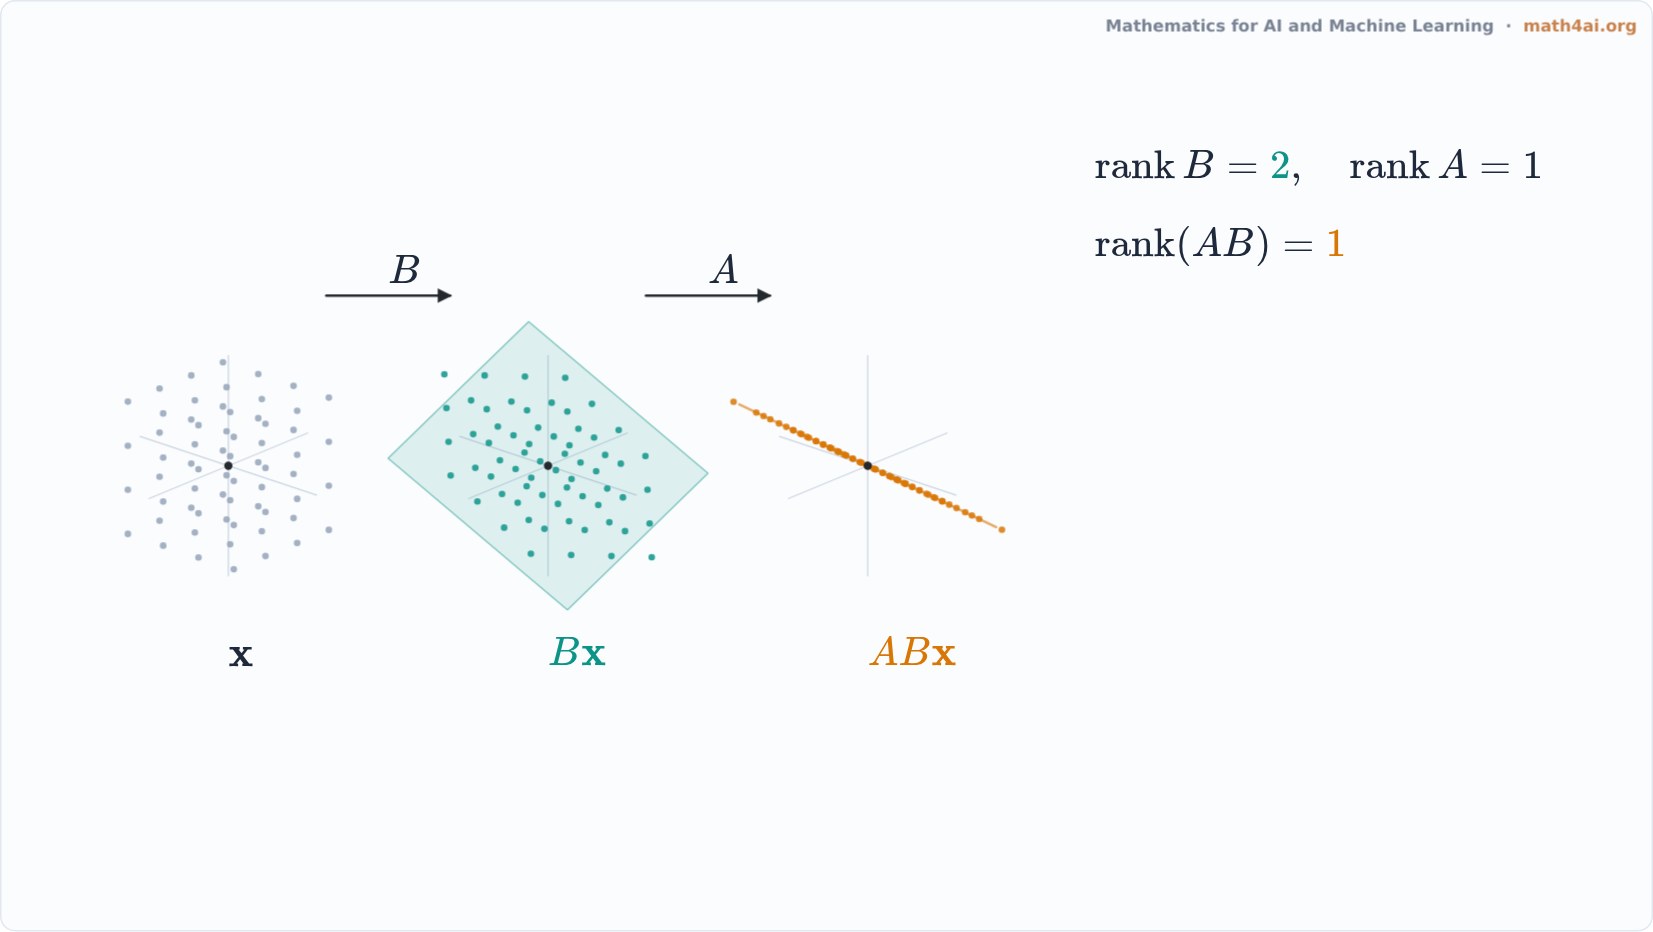 Preview1:30The Rank of a Product: Dimensions Can Only Be LostChapter 4
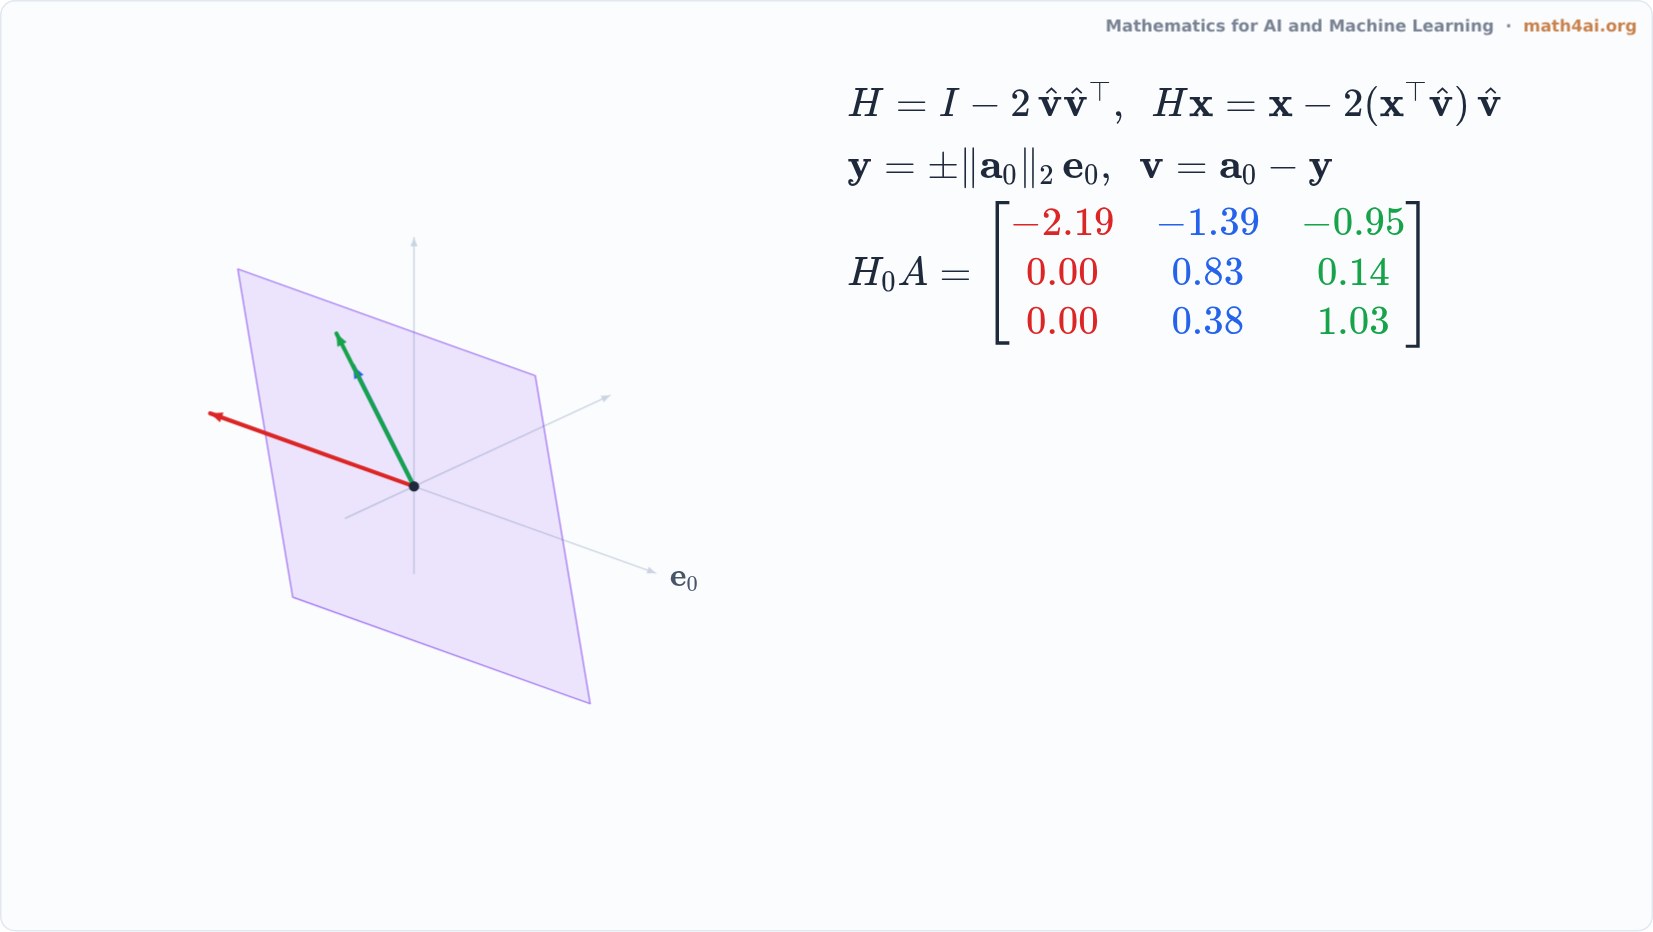 Preview1:56Householder QR: One Mirror per ColumnChapter 4
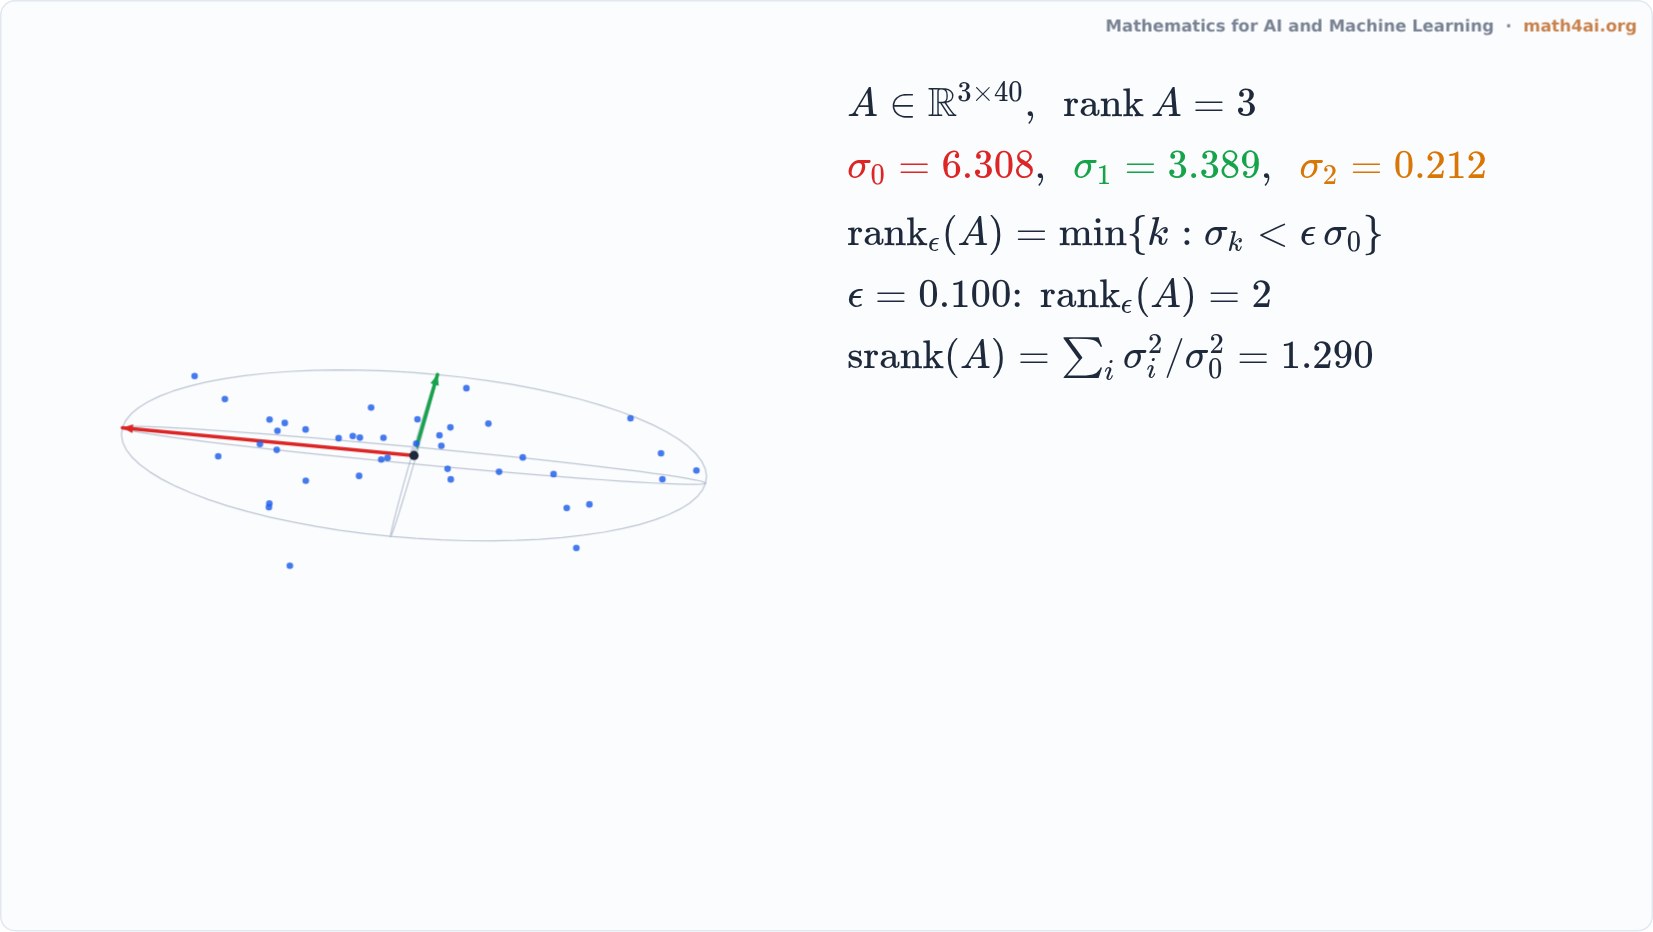 Preview1:24Numerical Rank: When Is a Pancake a Plane?Chapter 4
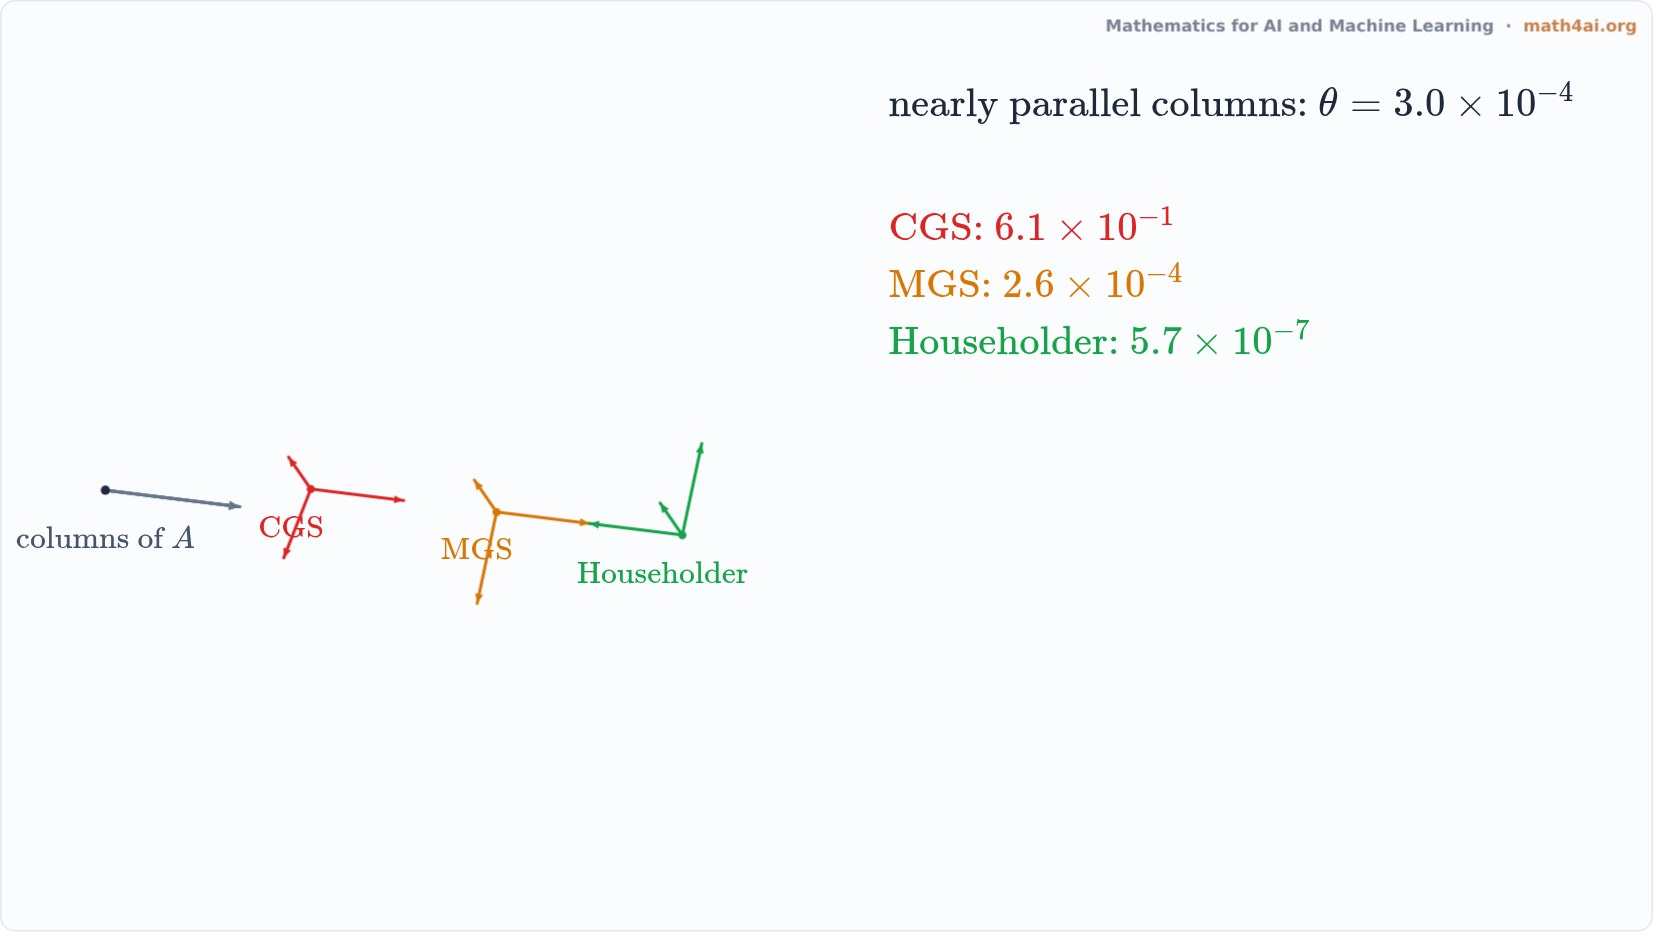 Preview1:39Gram-Schmidt or Householder: Losing the Right AnglesChapter 4
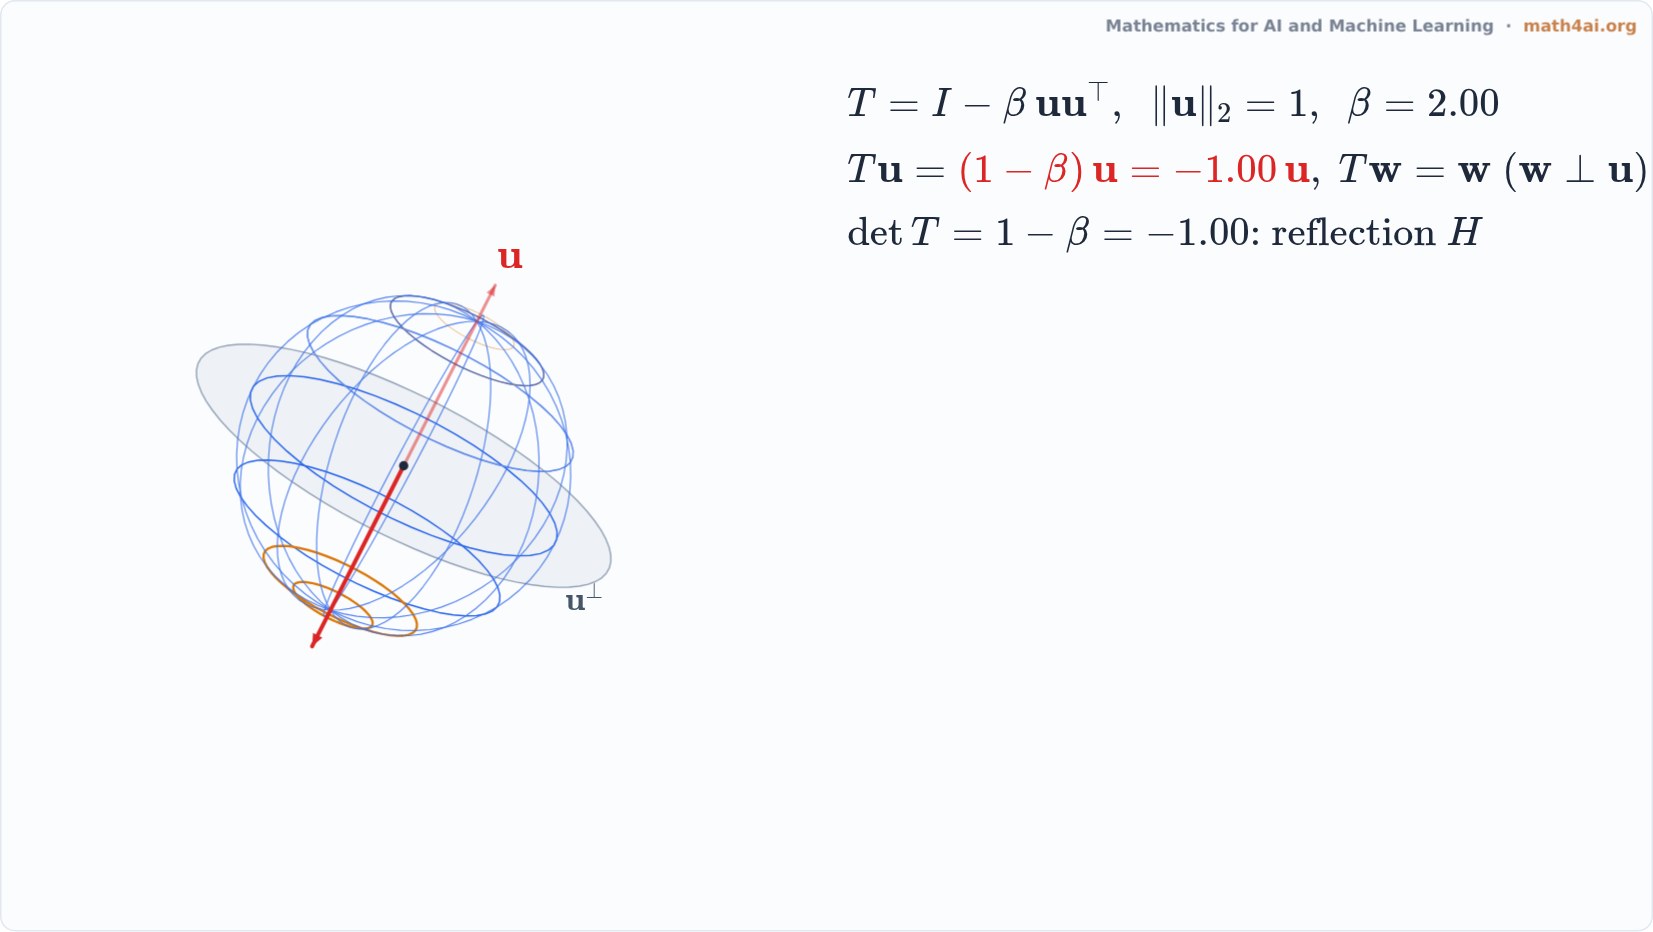 Preview1:41A Rank-One Change of the Identity: Identity, Projection, MirrorChapter 4
Chapter 5 Square Matrix and LU Decomposition
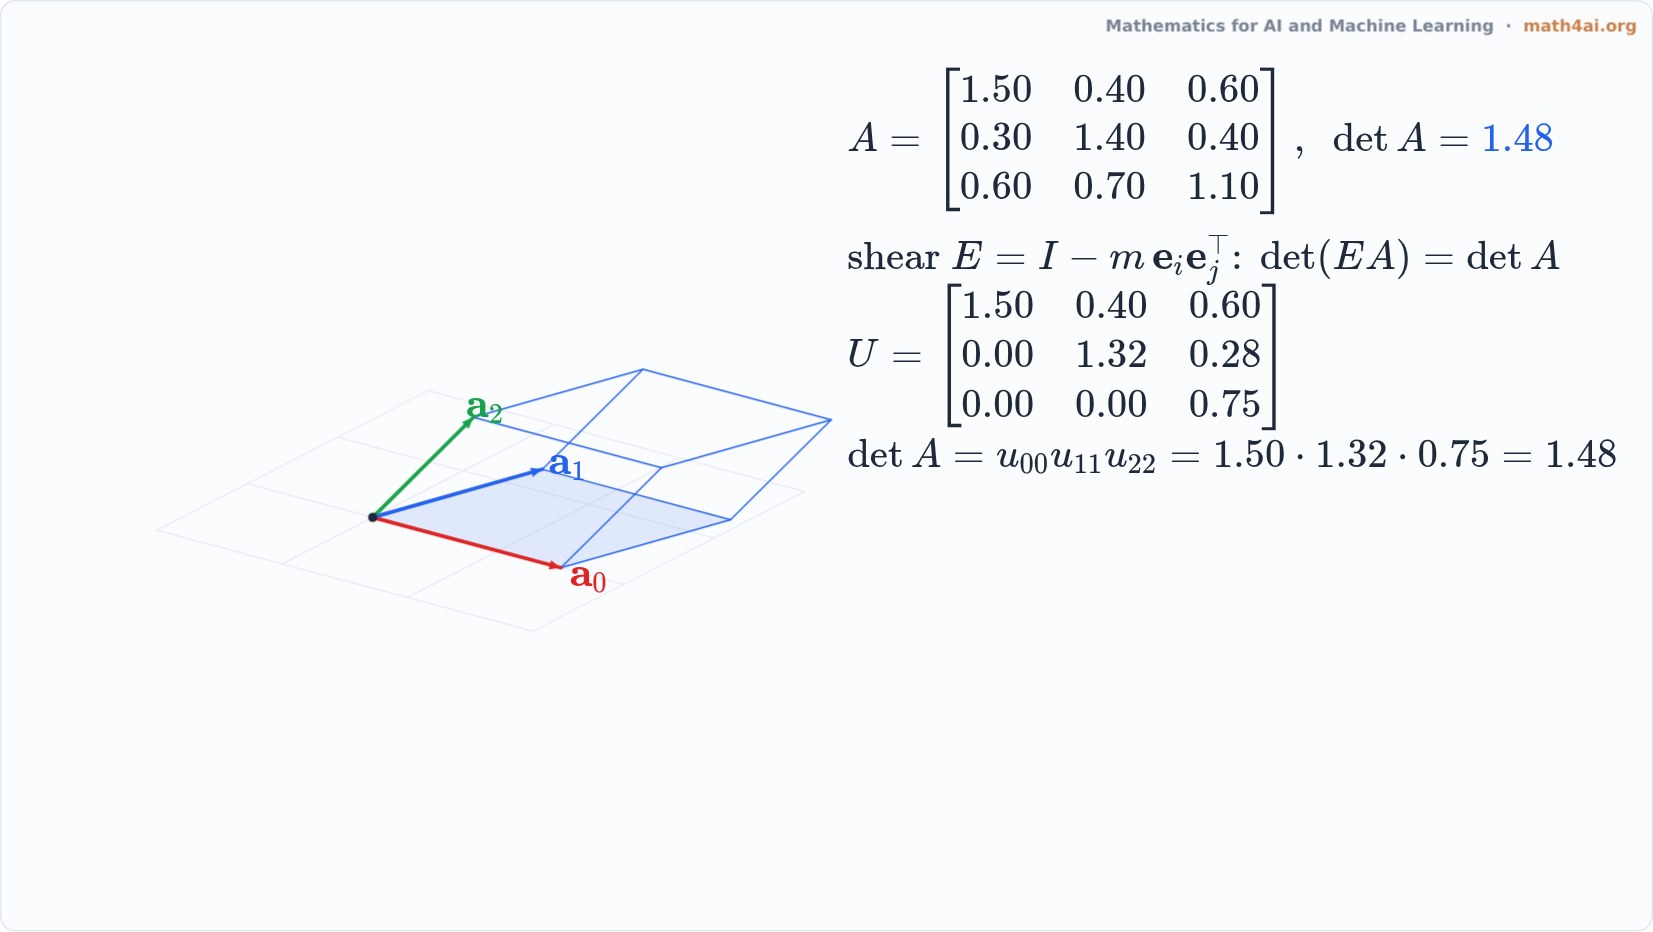 Interactive1:27The Determinant through LU: Shears Keep It, Pivots Give ItChapter 5
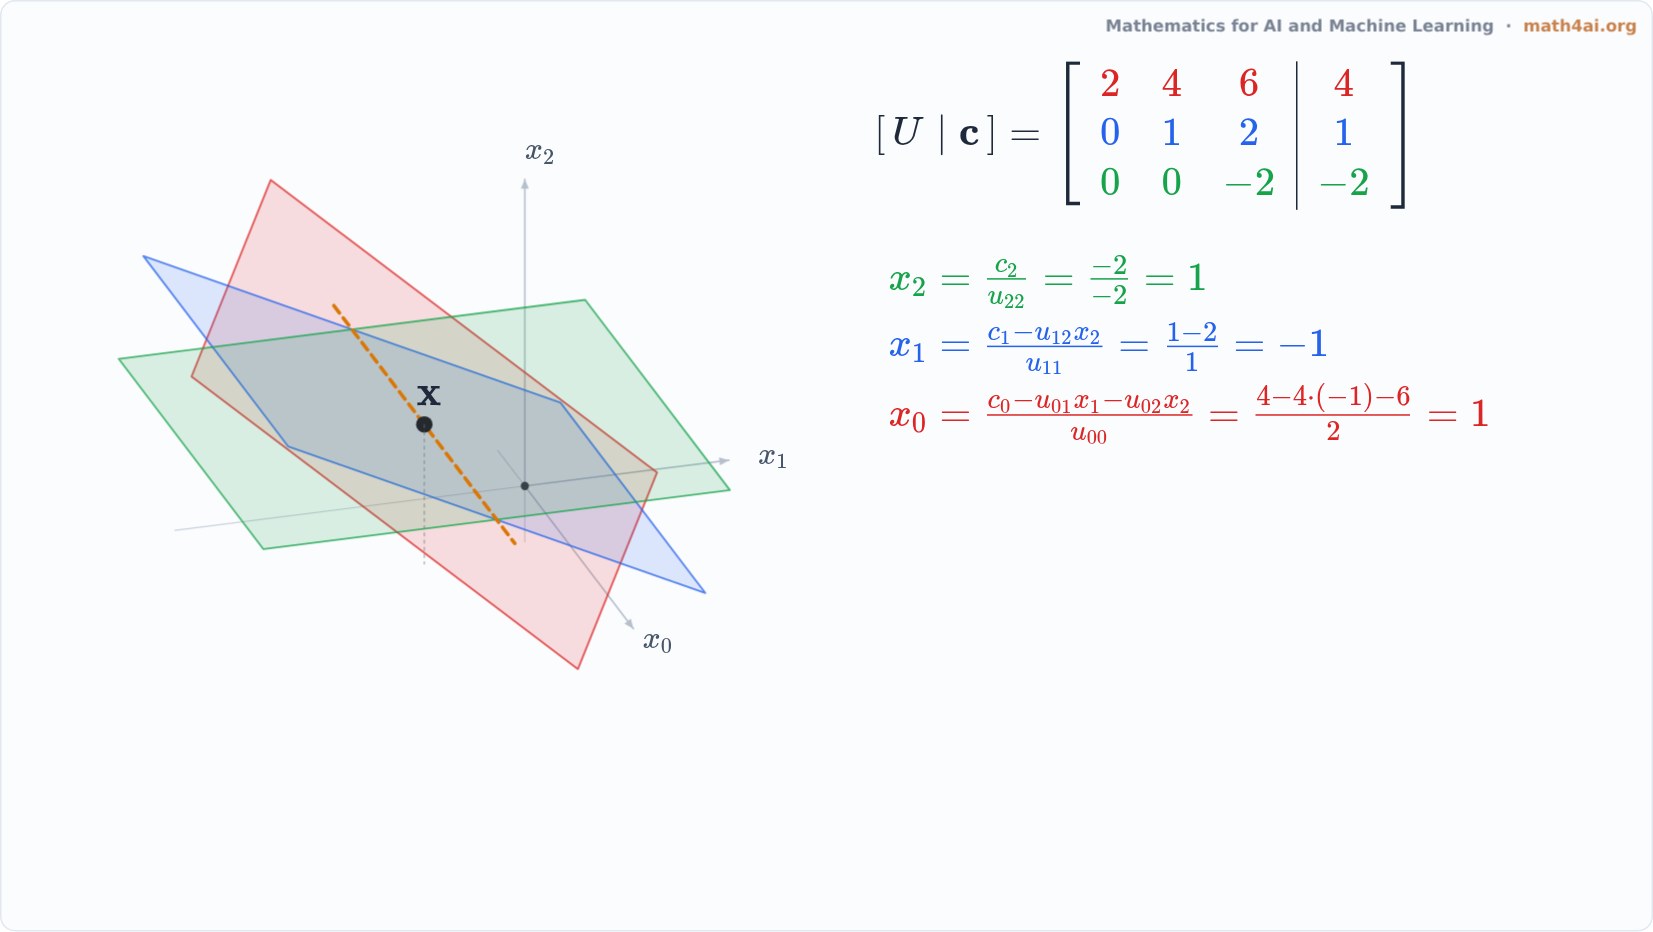 Preview1:40Back Substitution: A Plane, a Line, a PointChapter 5
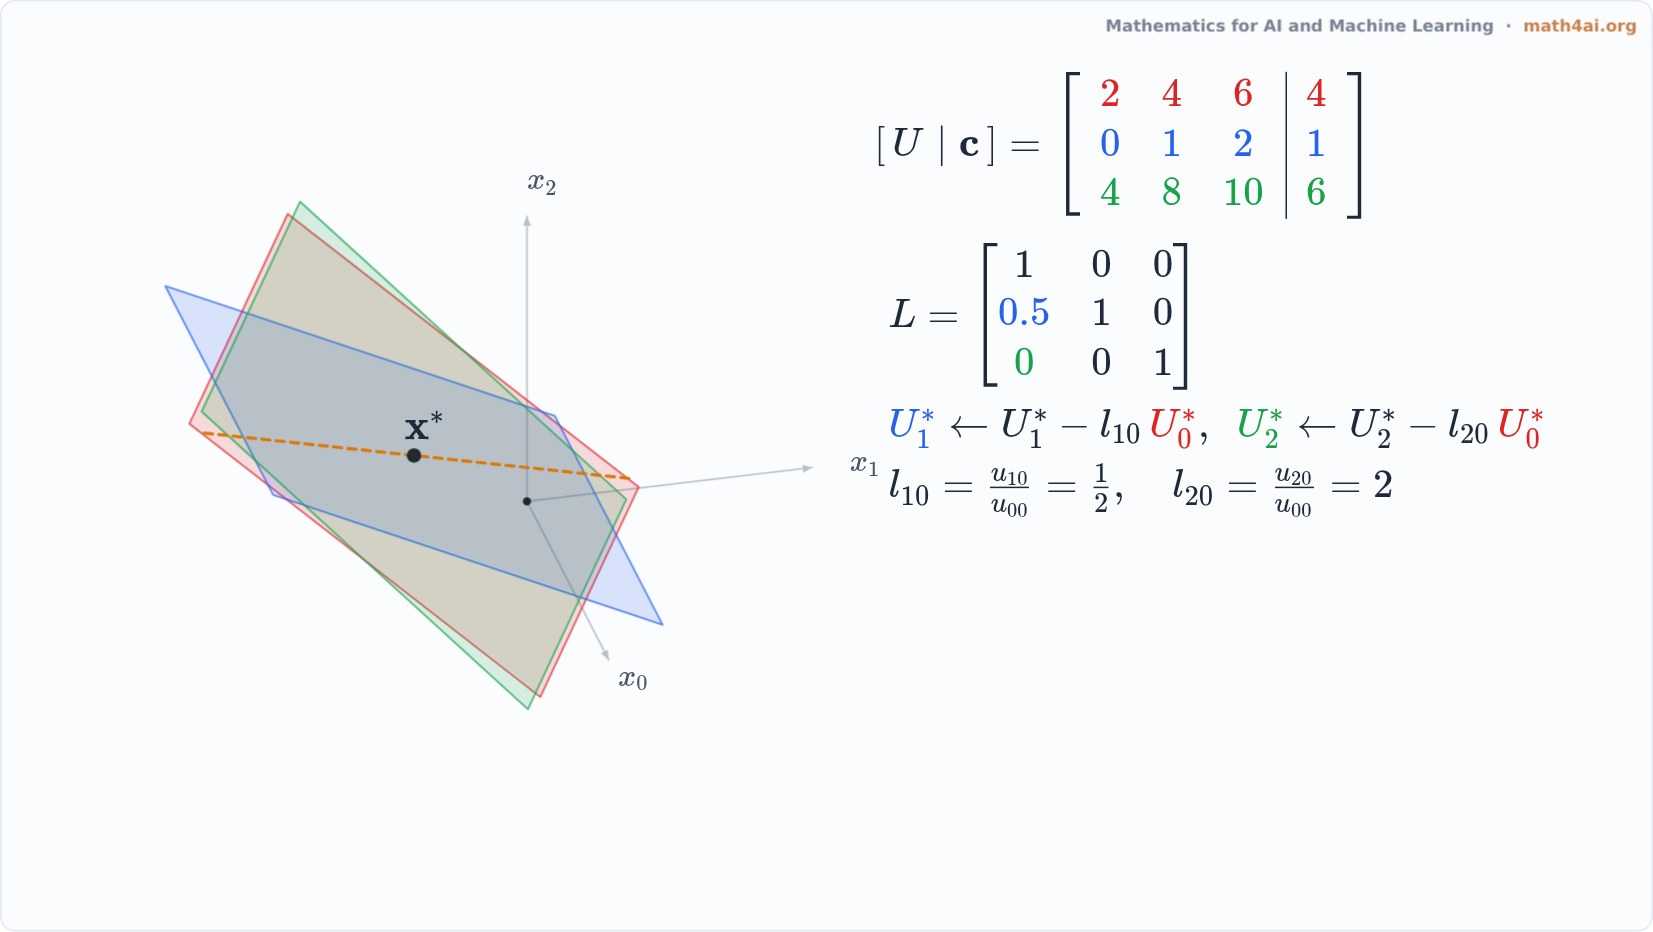 Preview1:46Gaussian Elimination: Planes That Swing Around a LineChapter 5
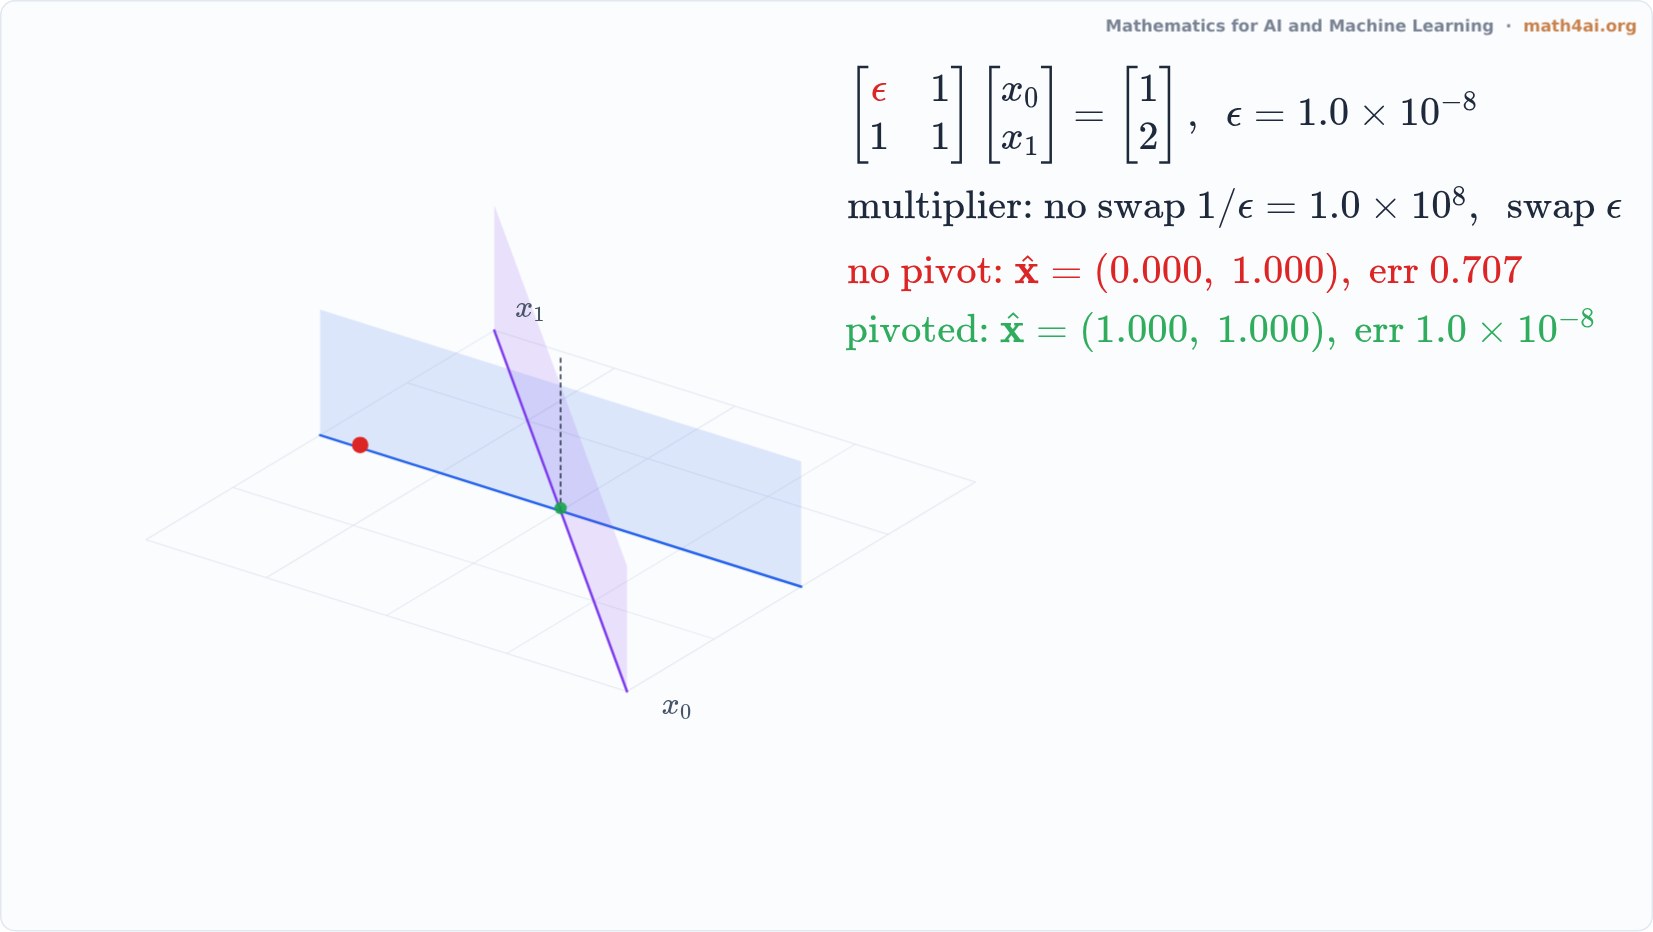 Preview1:45Pivoting: Why PLU Swaps RowsChapter 5
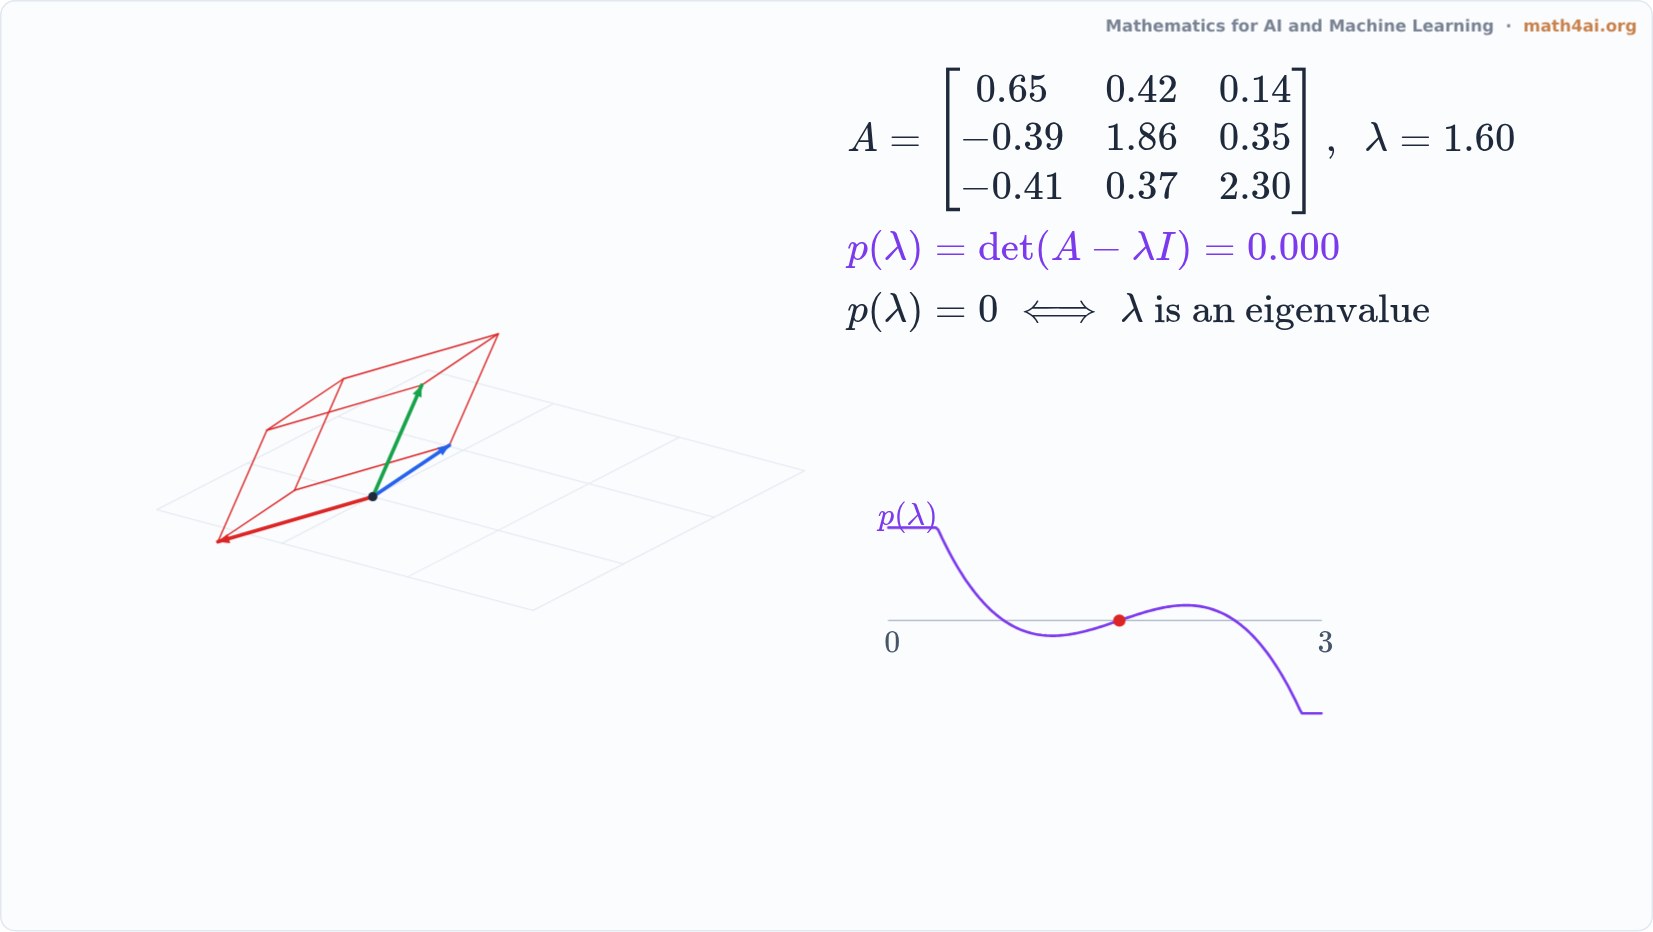 Preview1:22The Characteristic Polynomial: When the Box CollapsesChapter 5
Chapter 6 Geometric Transformation and Eigen Decomposition
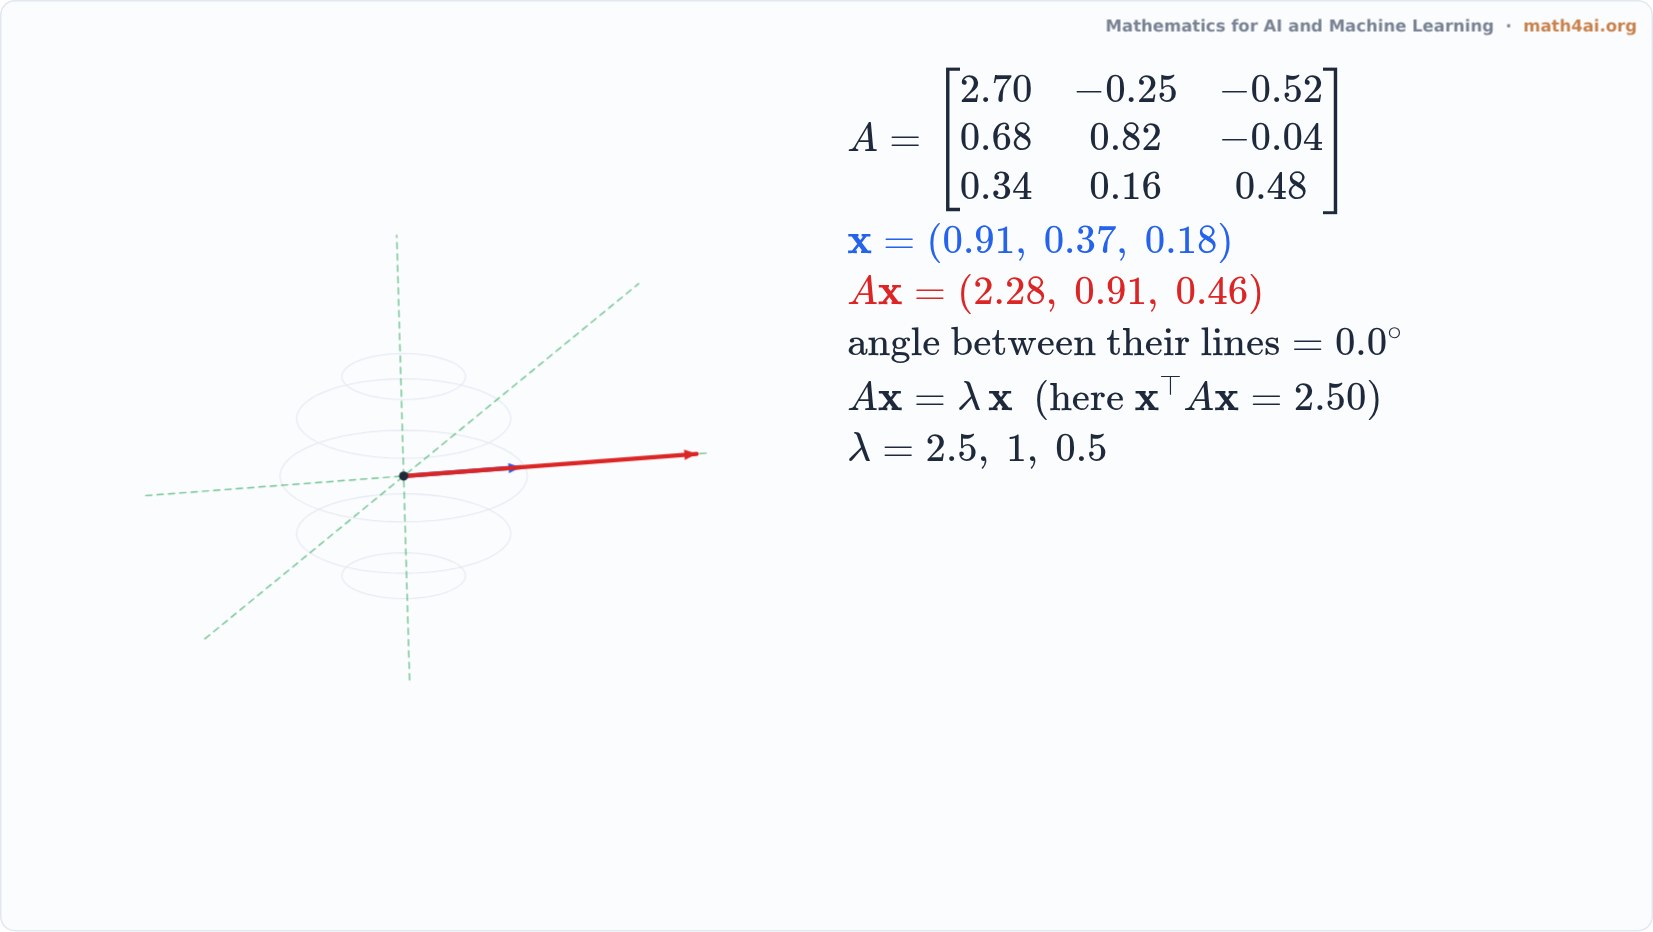 Interactive1:32Eigenvectors: the Directions a Matrix Does Not TurnChapter 6
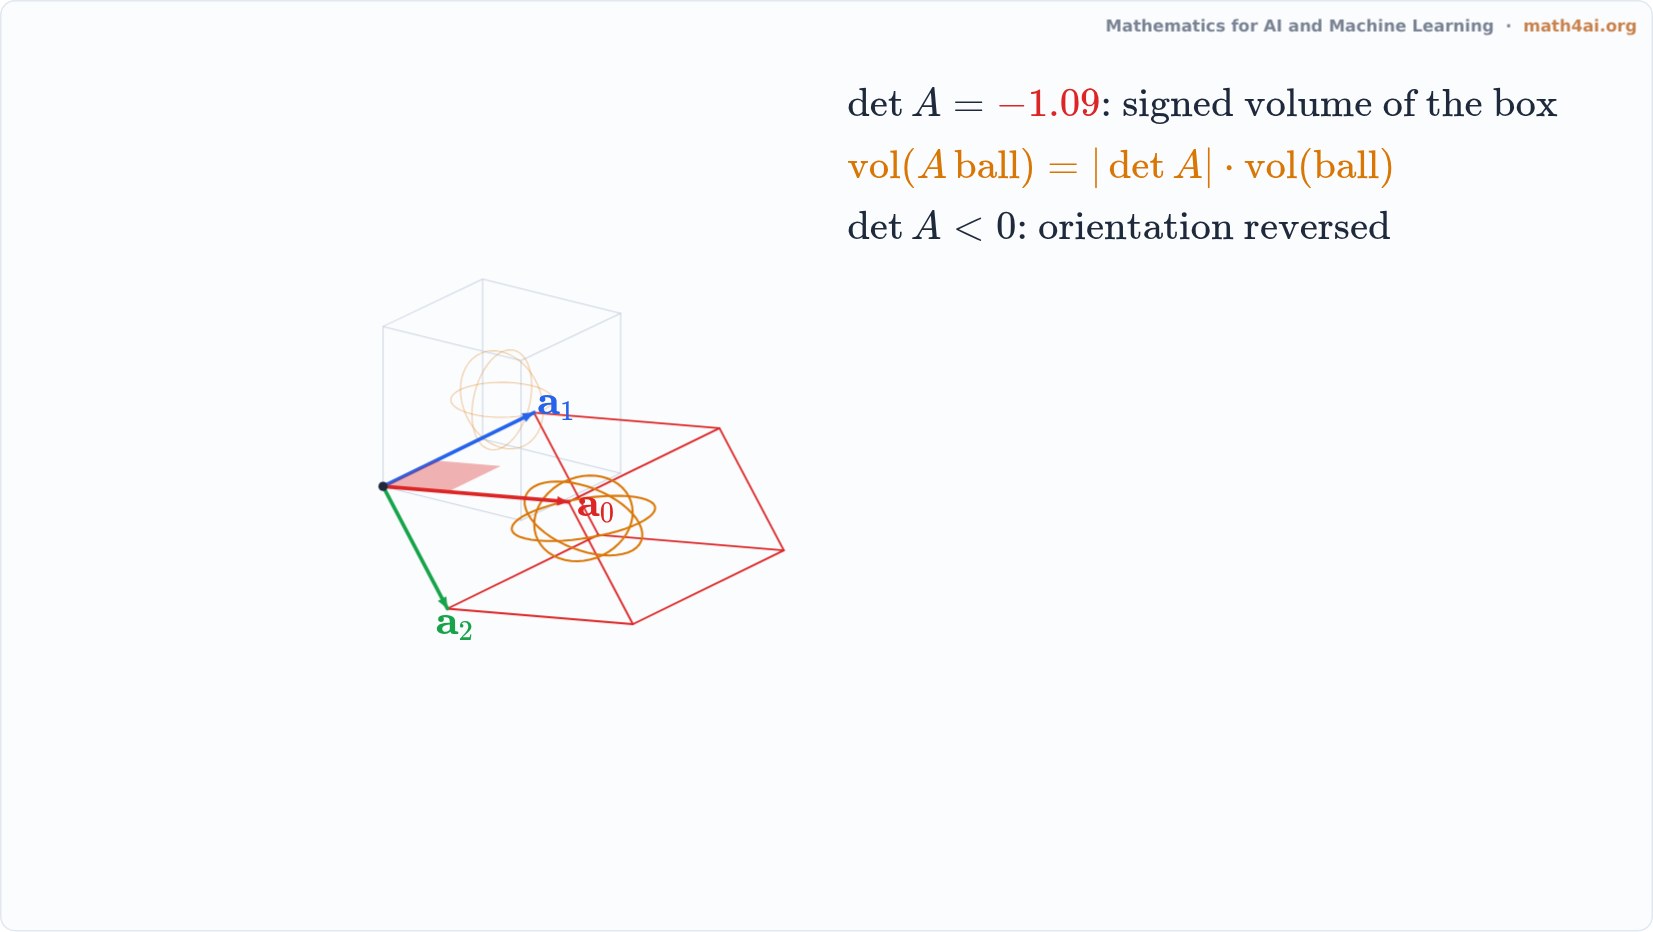 Preview1:42The Determinant as a Volume Factor, with a SignChapter 6
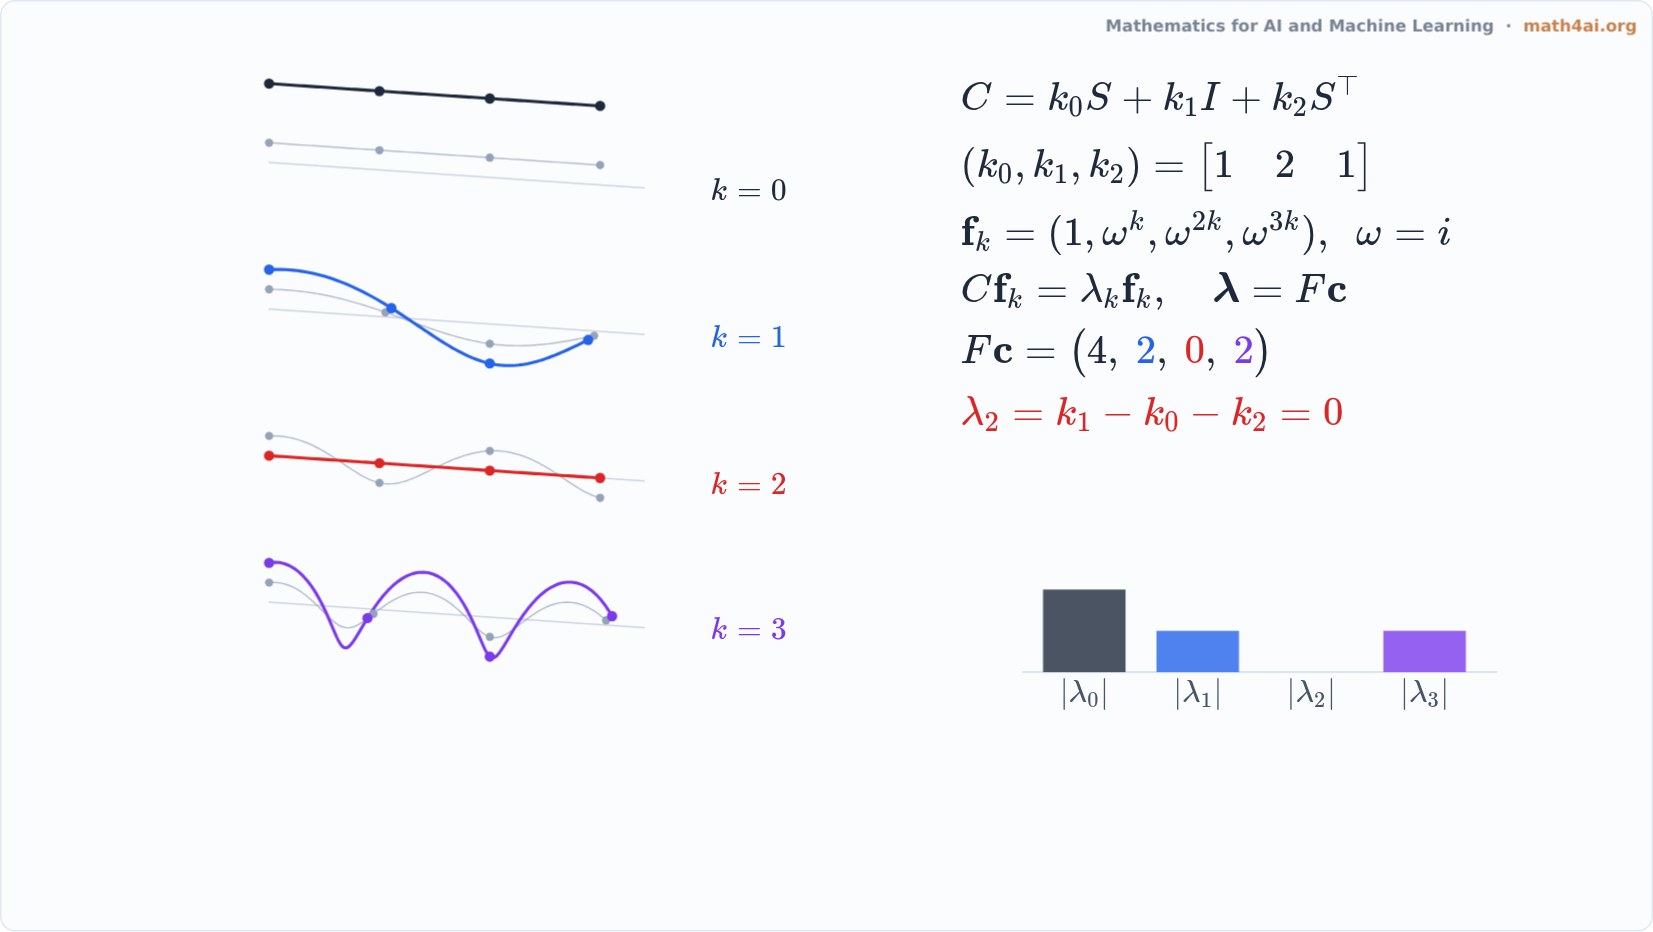 Preview1:43Convolution Is Multiplication in the Fourier BasisChapter 6
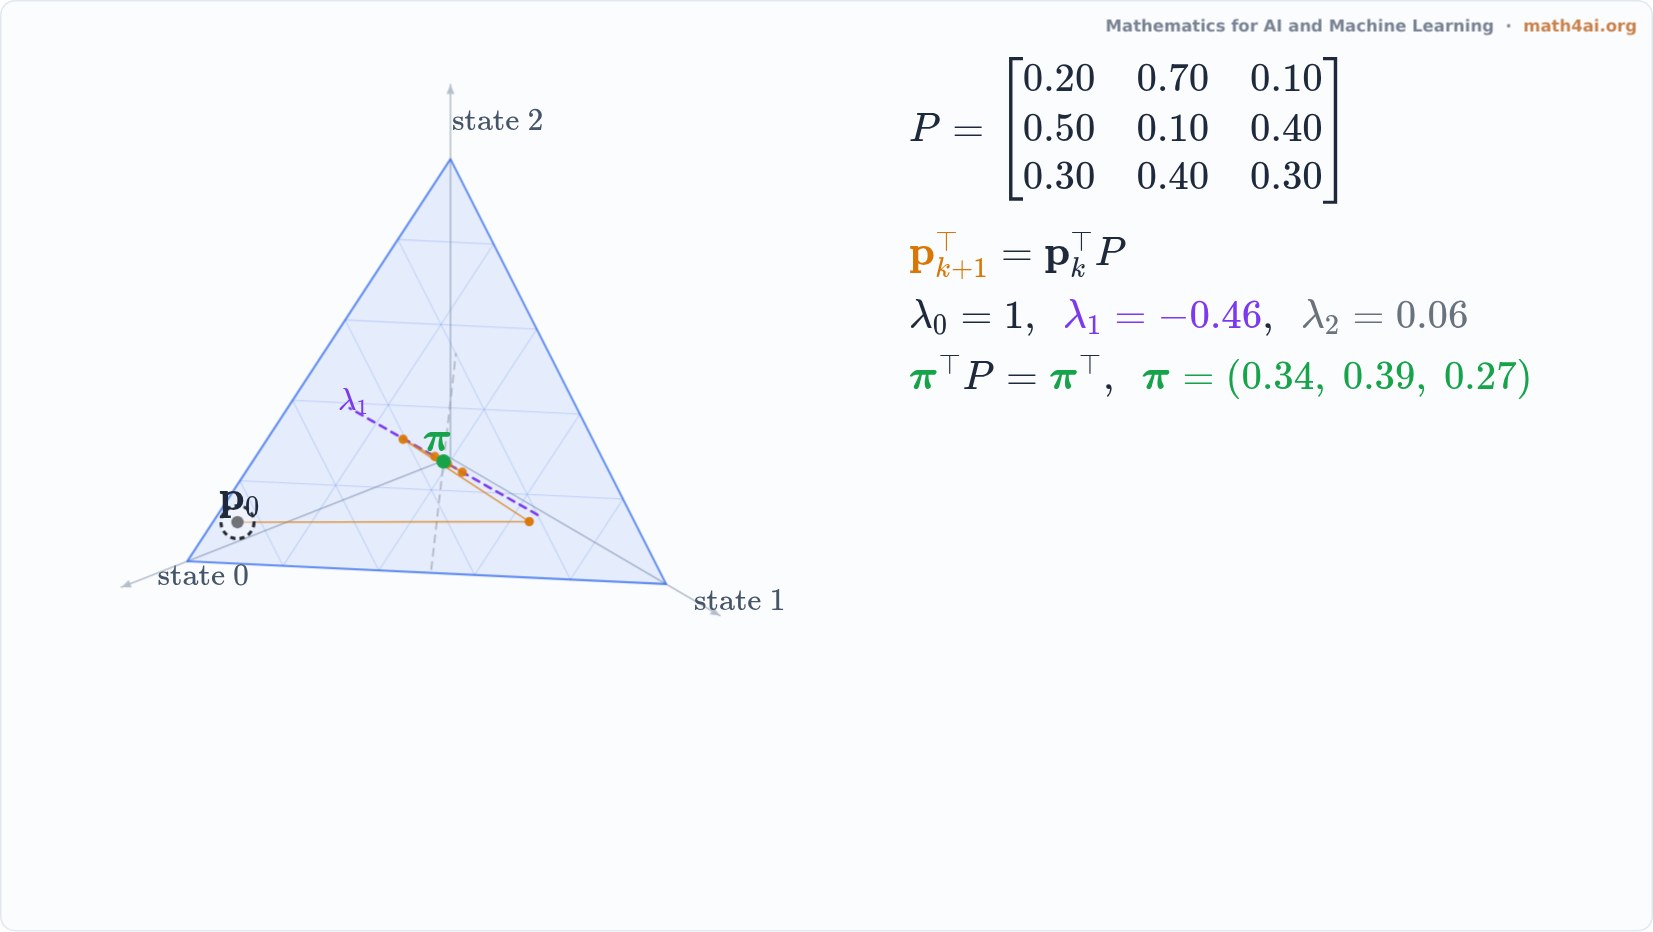 Preview1:46Power Method: A Markov Chain Finds Its EigenvectorChapter 6
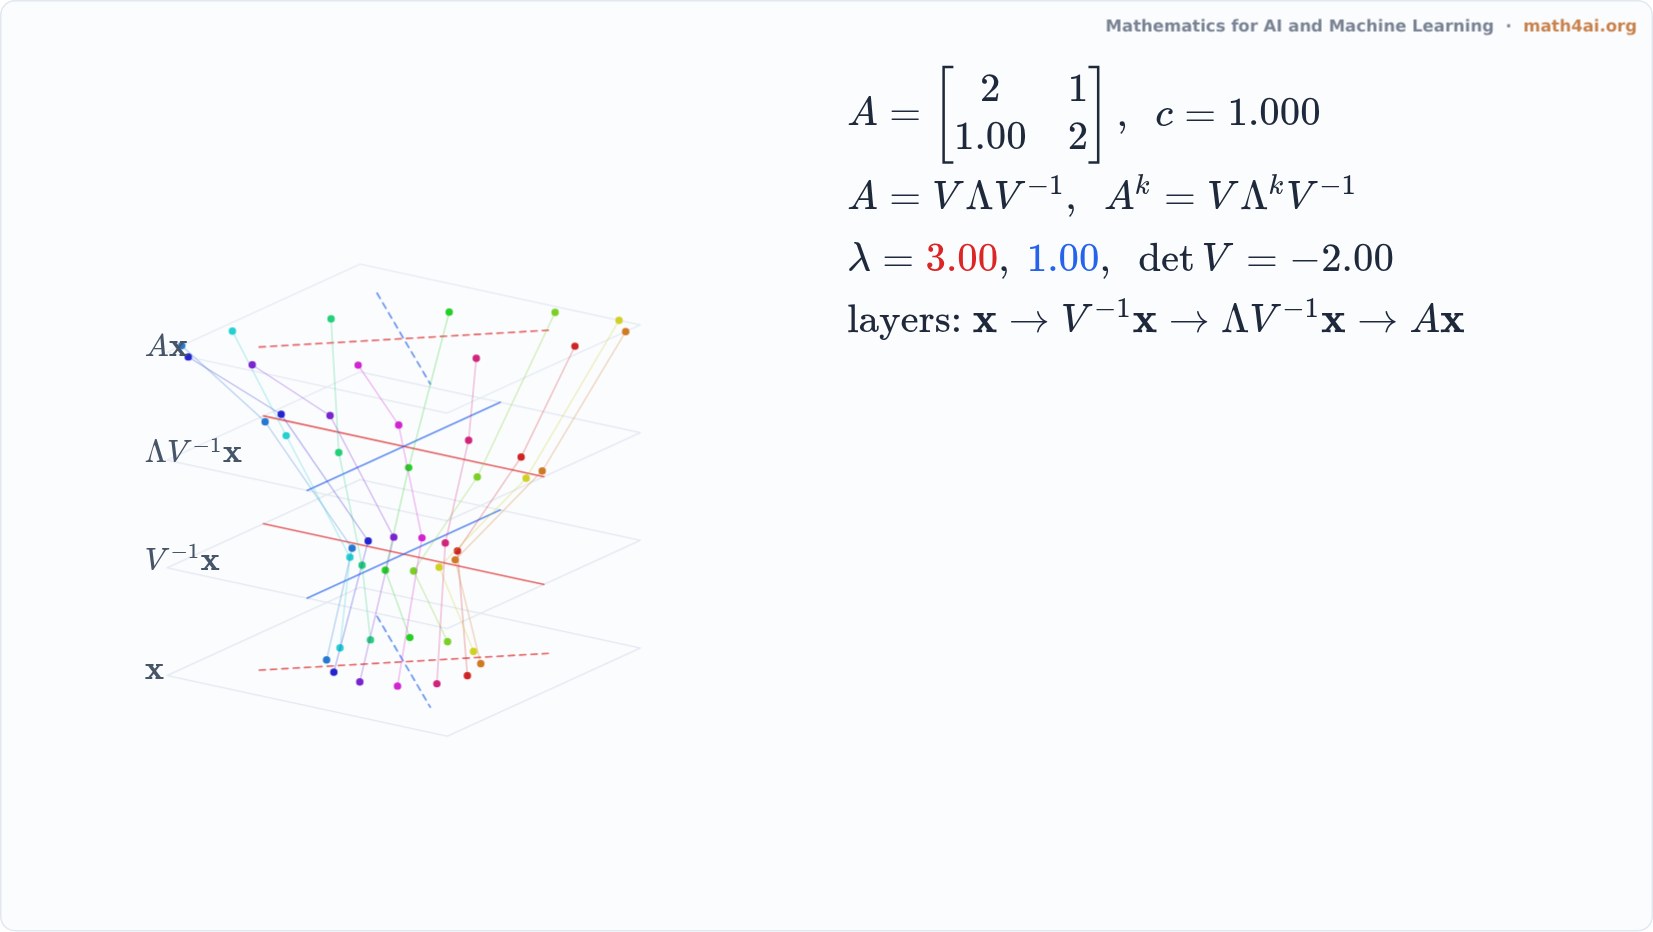 Preview1:44Diagonalization: Change Basis, Stretch, Change BackChapter 6
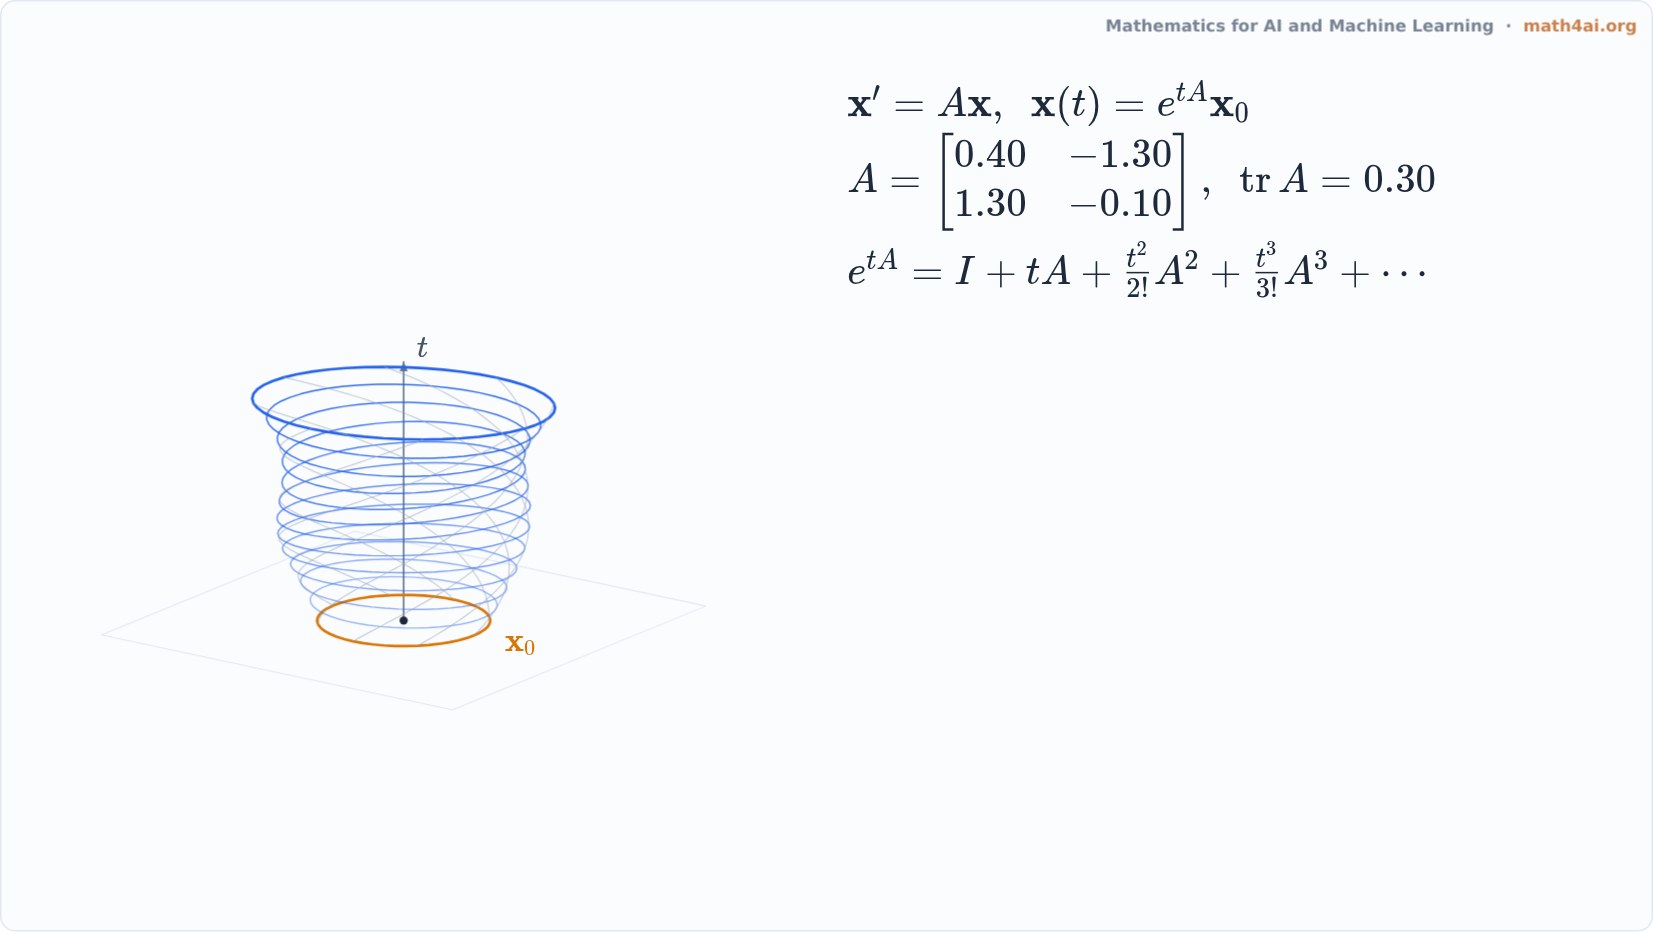 Preview1:36The Matrix Exponential: a Flow Whose Area Grows like e to the TraceChapter 6
Chapter 7 Symmetric Matrix
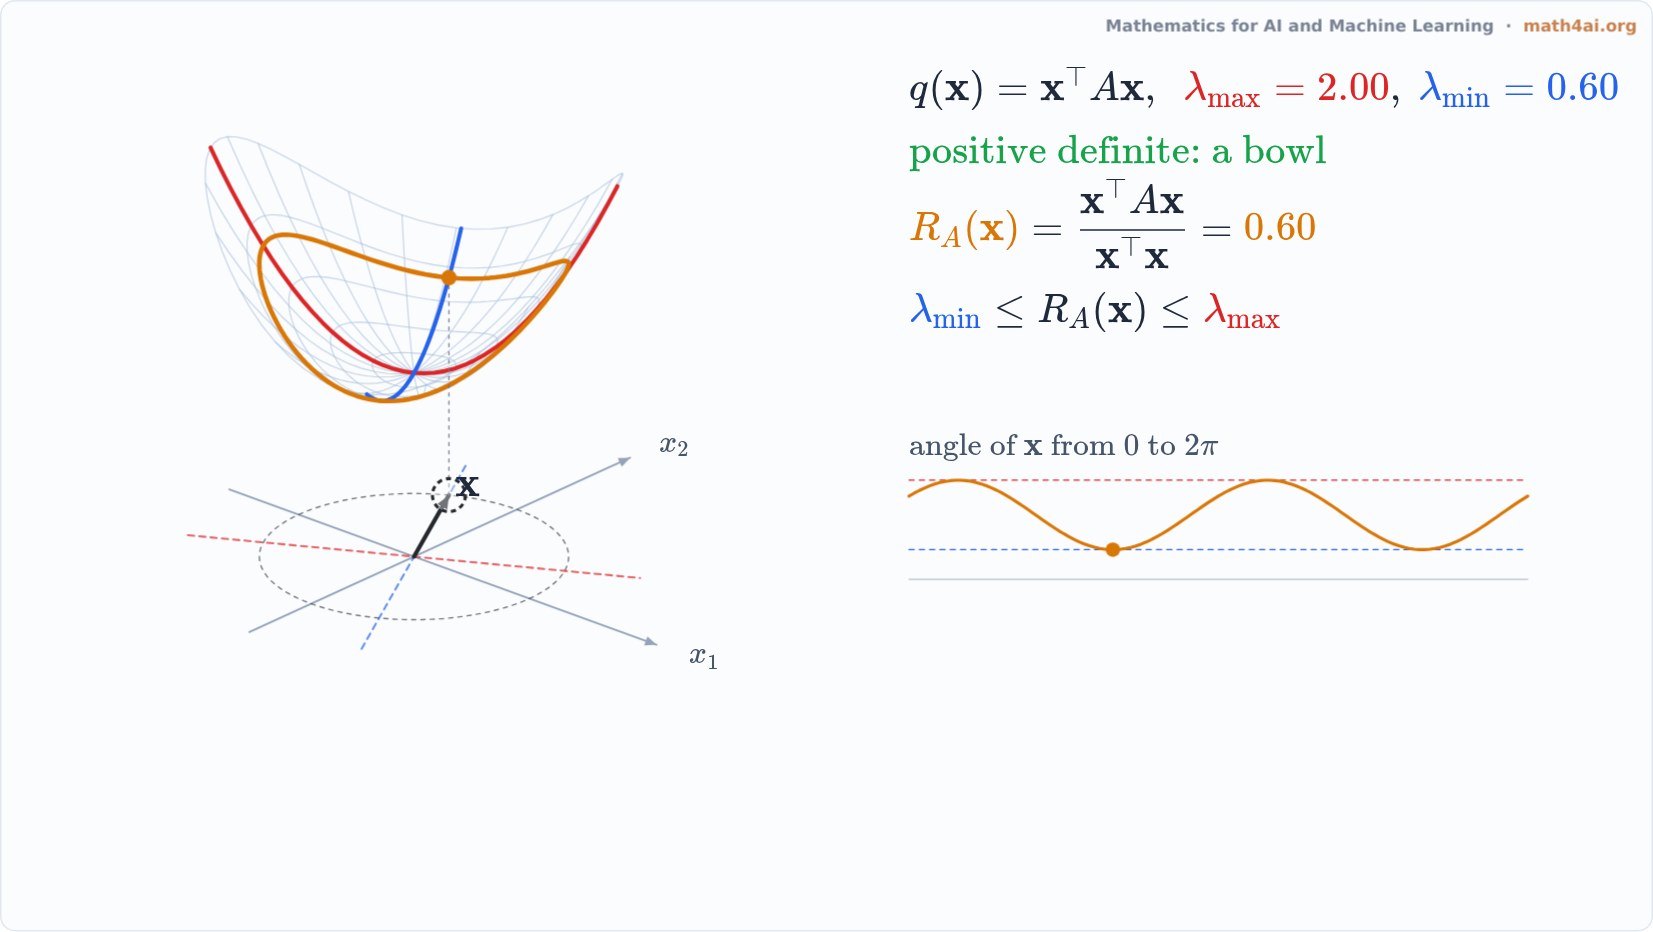 Interactive1:44Rayleigh Quotient: The Height of a Quadratic Form on the Unit CircleChapter 7
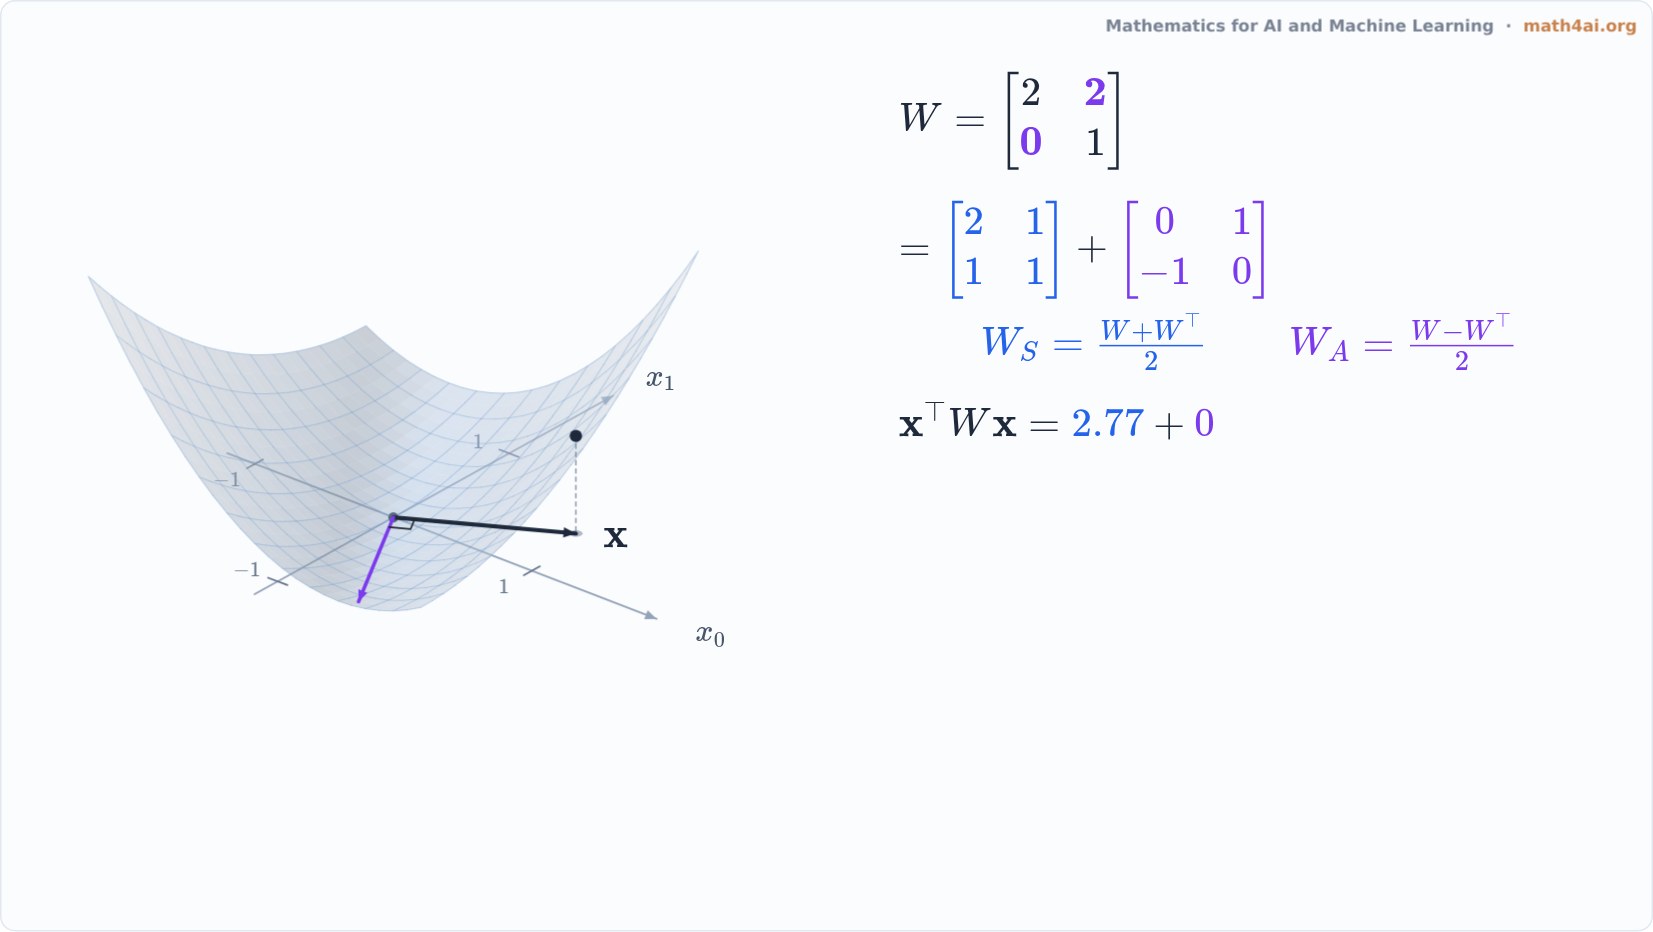 Preview1:29Quadratic Forms See Only the Symmetric PartChapter 7
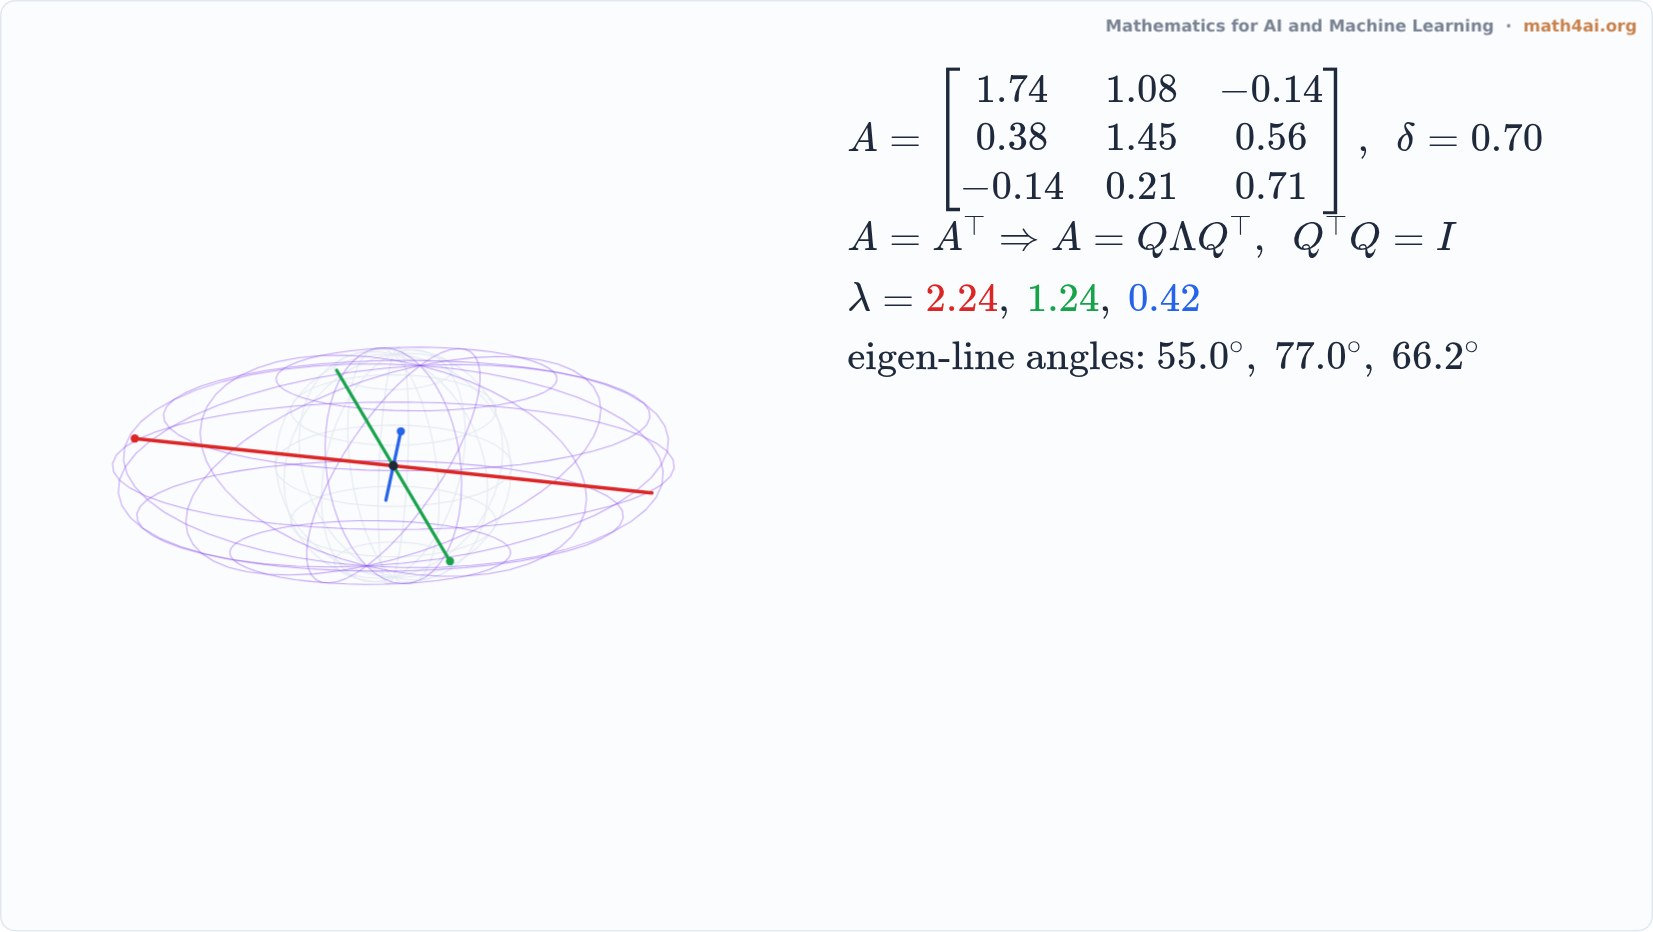 Preview1:29The Spectral Theorem: Symmetric Means Perpendicular EigenvectorsChapter 7
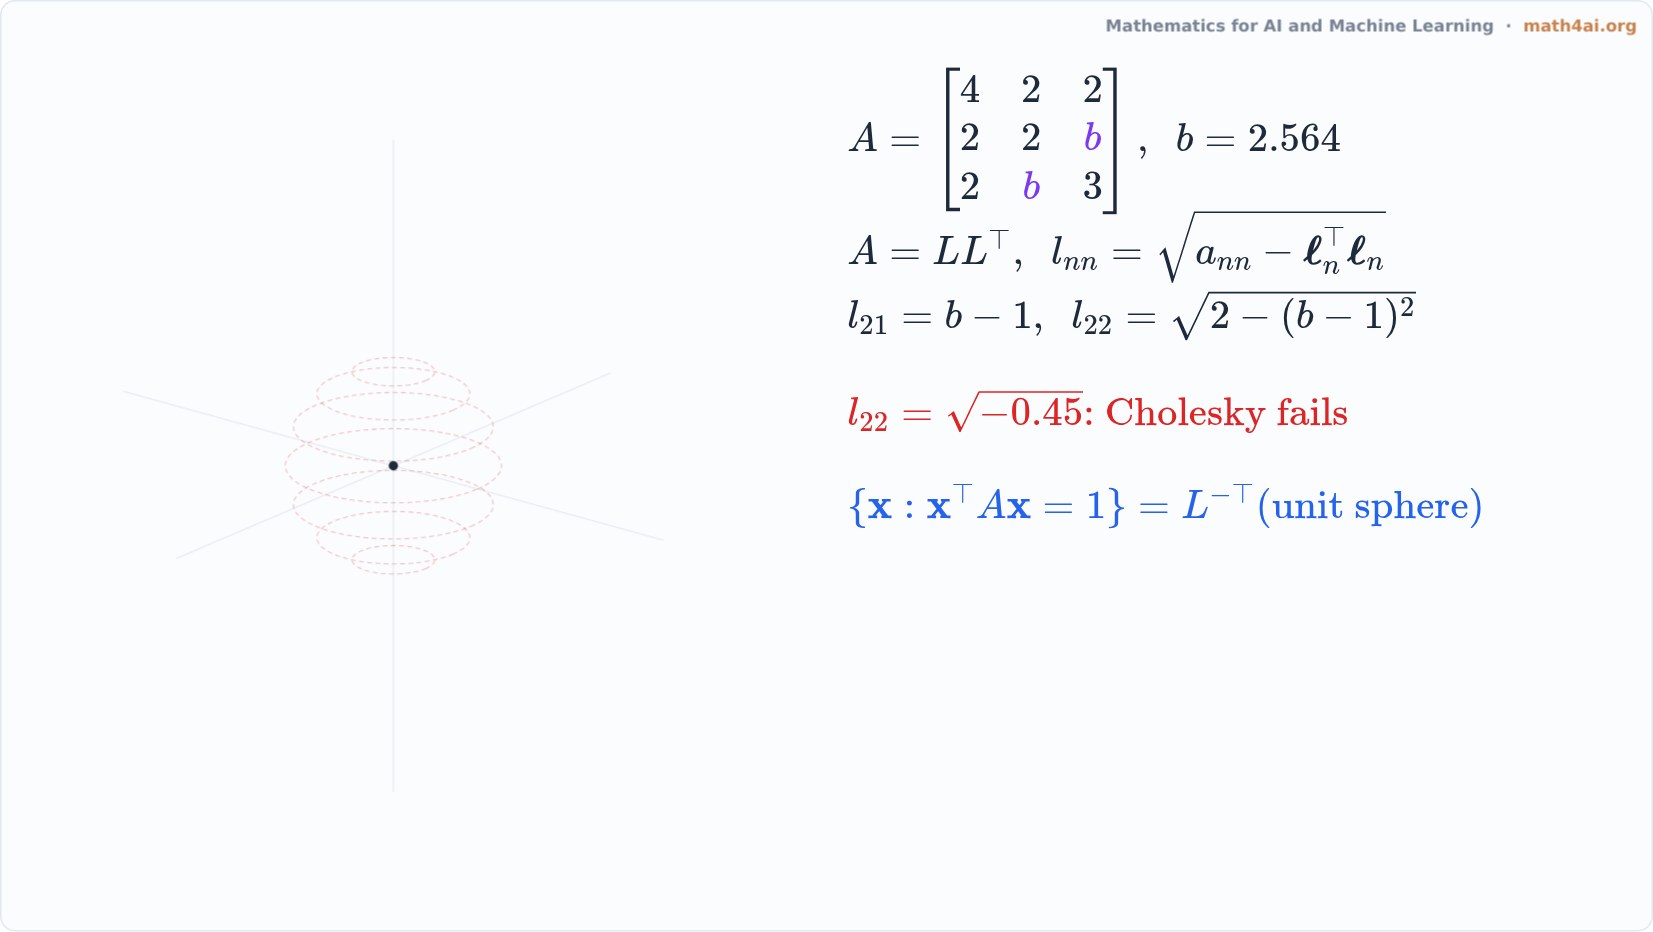 Preview1:35Cholesky: a Square Root That Exists Only for Positive Definite MatricesChapter 7
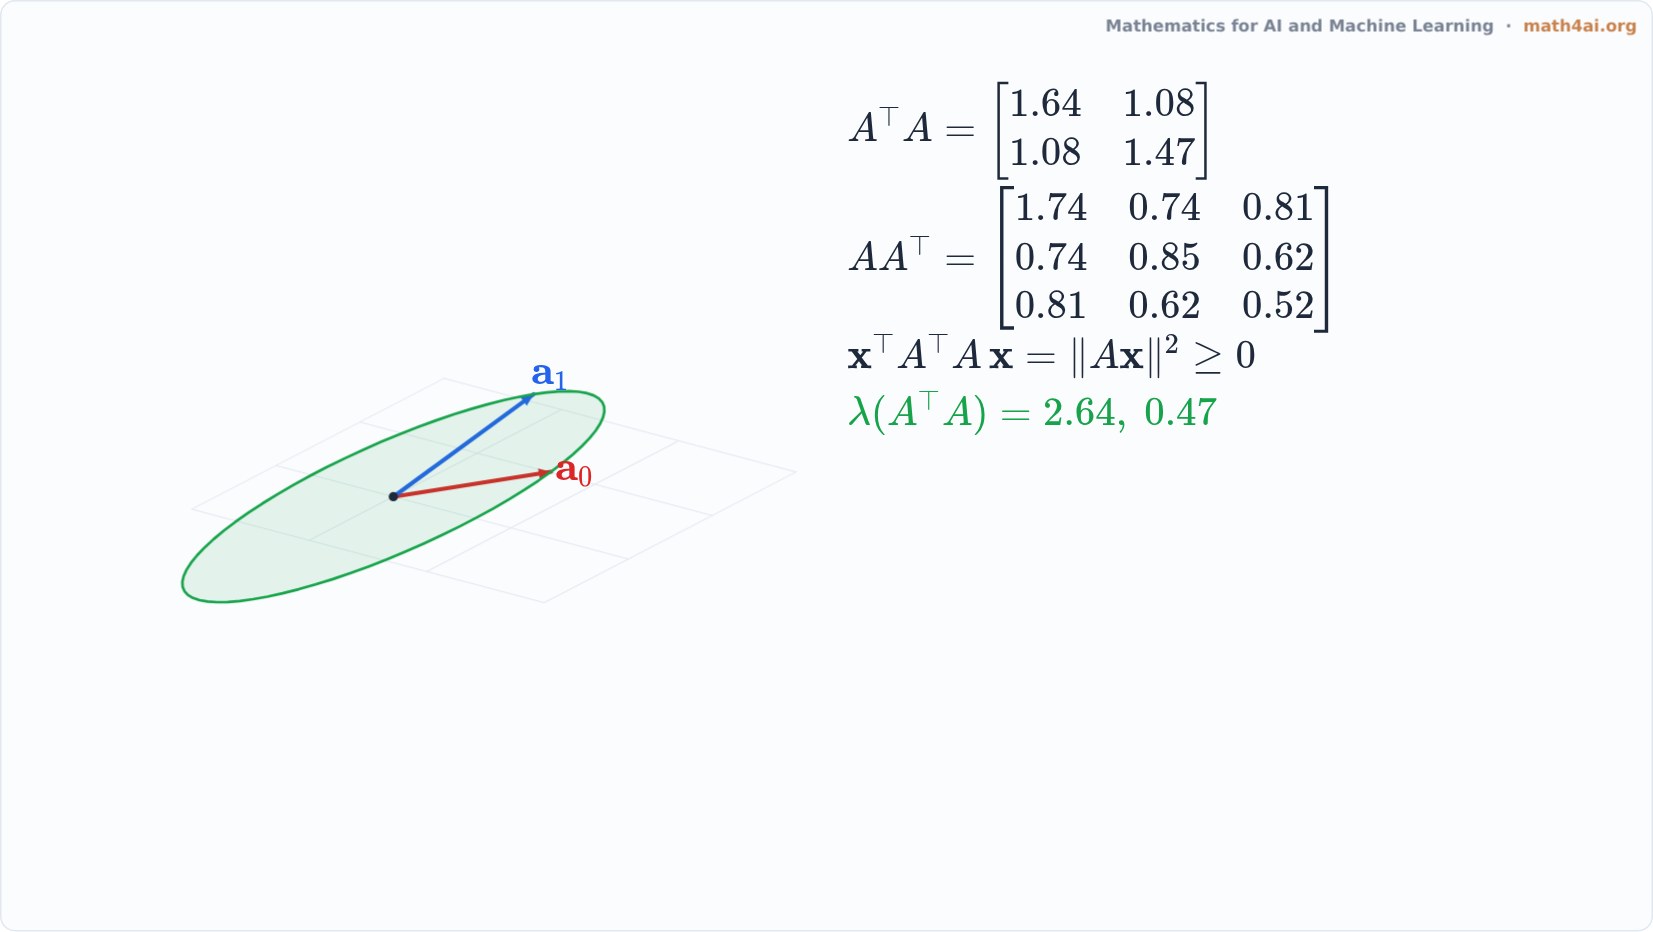 Preview1:40Gram Matrices: Two of Them, One Set of EigenvaluesChapter 7
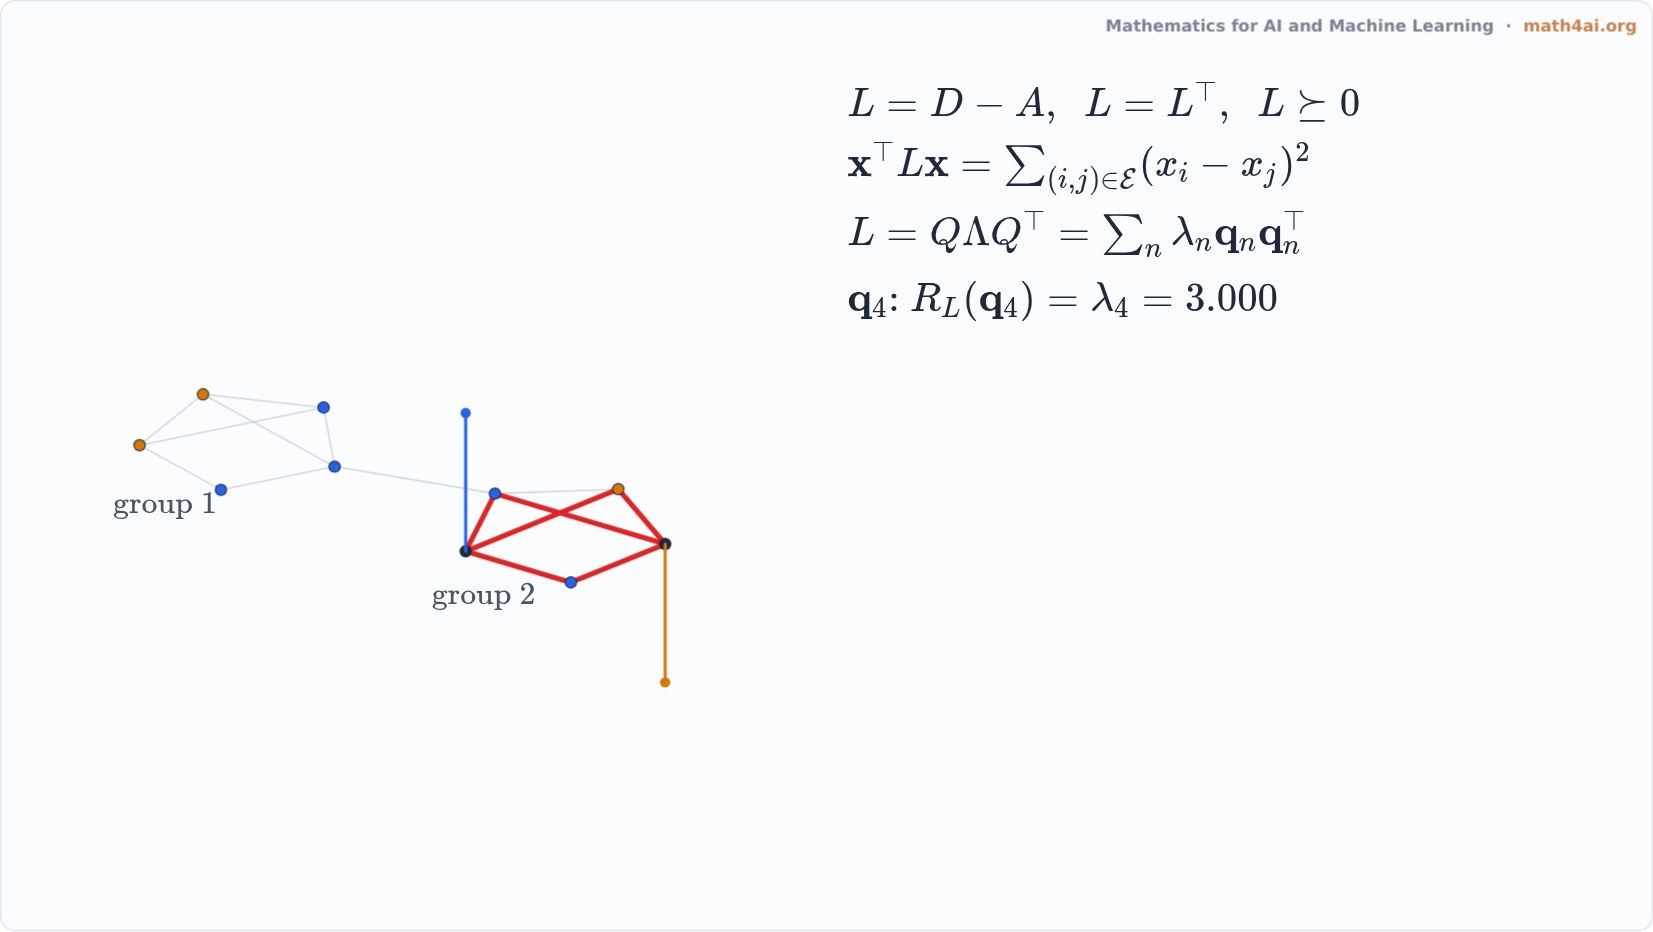 Preview1:26The Graph Laplacian: Smooth and Rough Signals on a GraphChapter 7
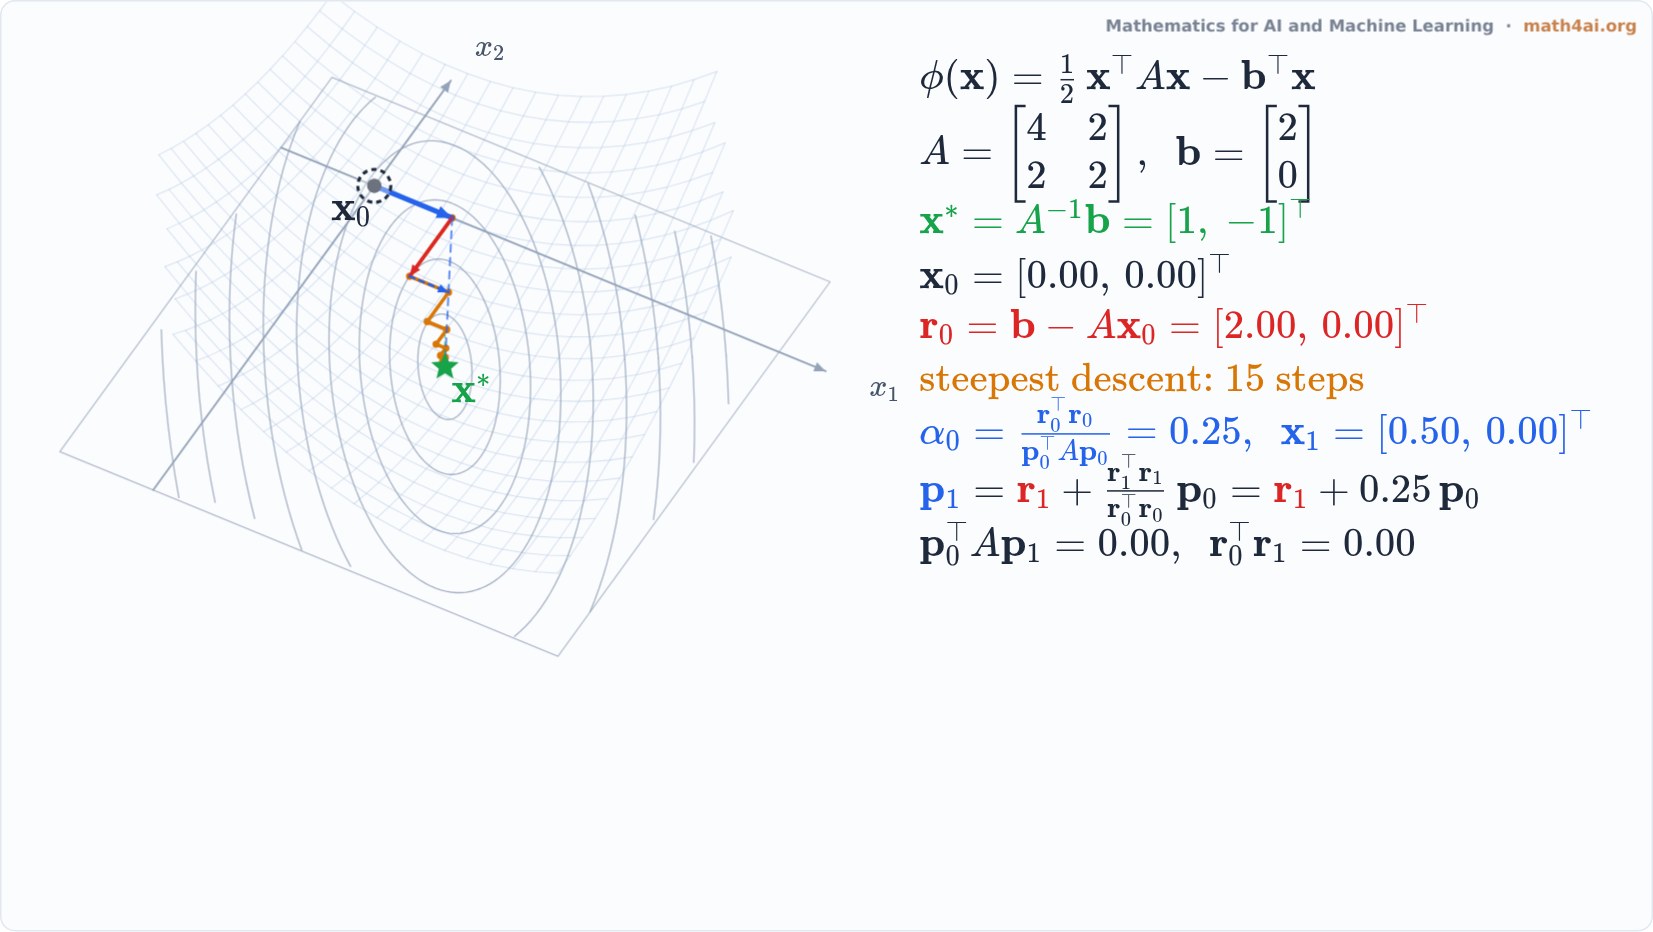 Preview1:58Conjugate Gradient: Two Steps to the BottomChapter 7
Chapter 8 Singular Value Decomposition (SVD)
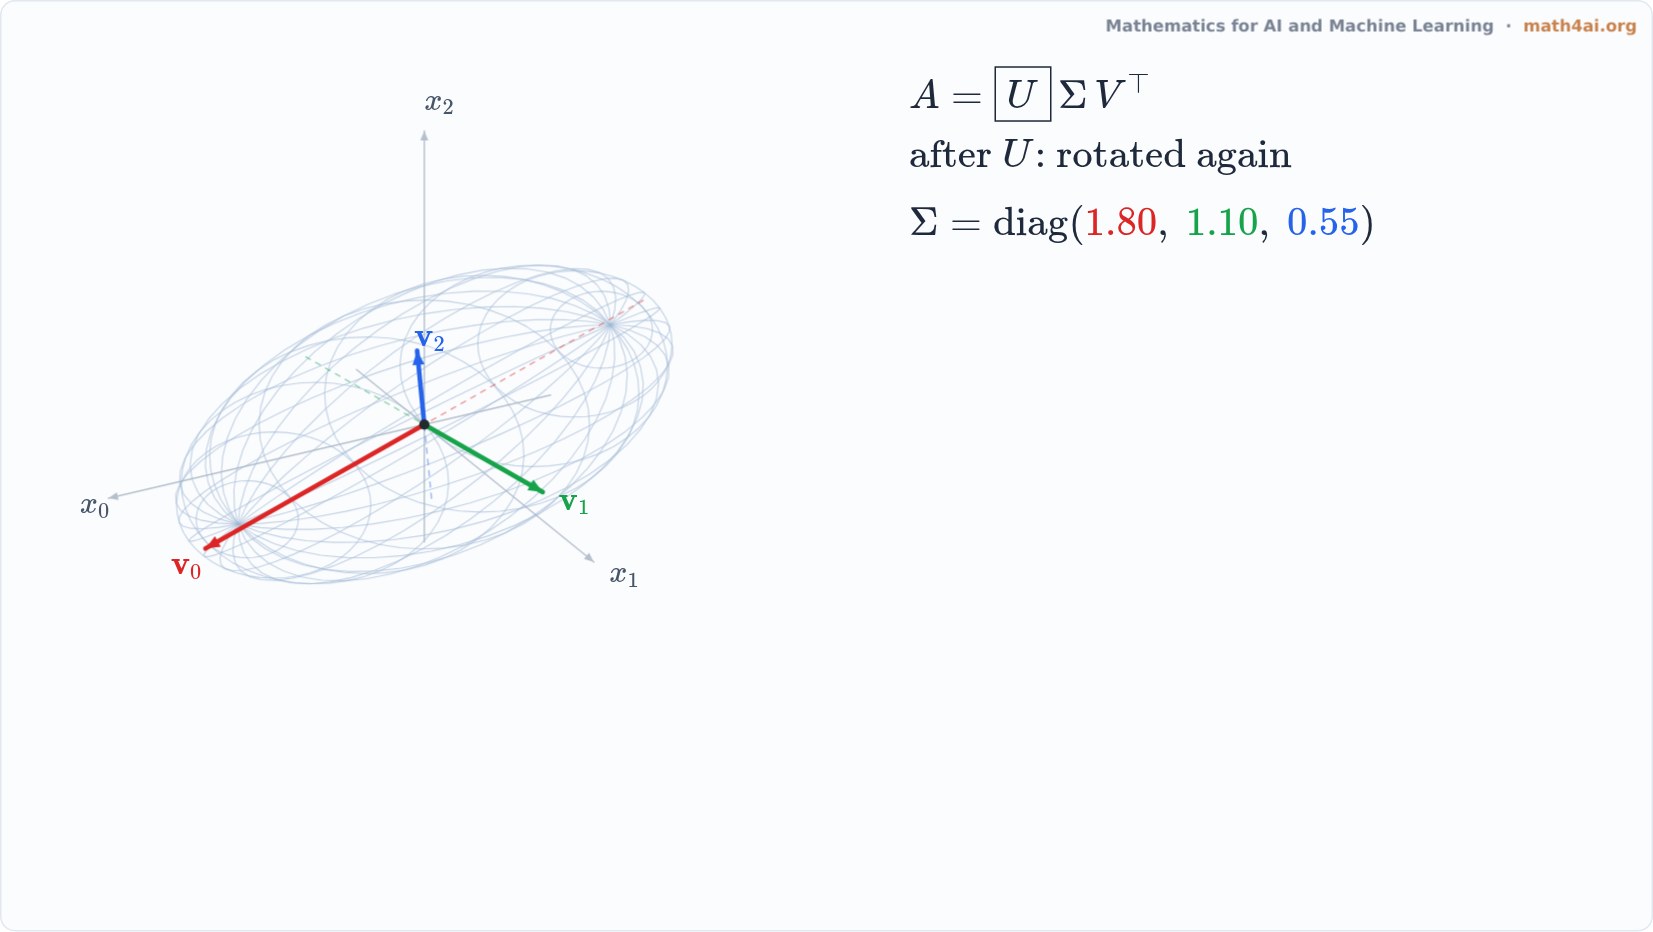 Interactive1:49SVD: Rotate, Stretch, RotateChapter 8
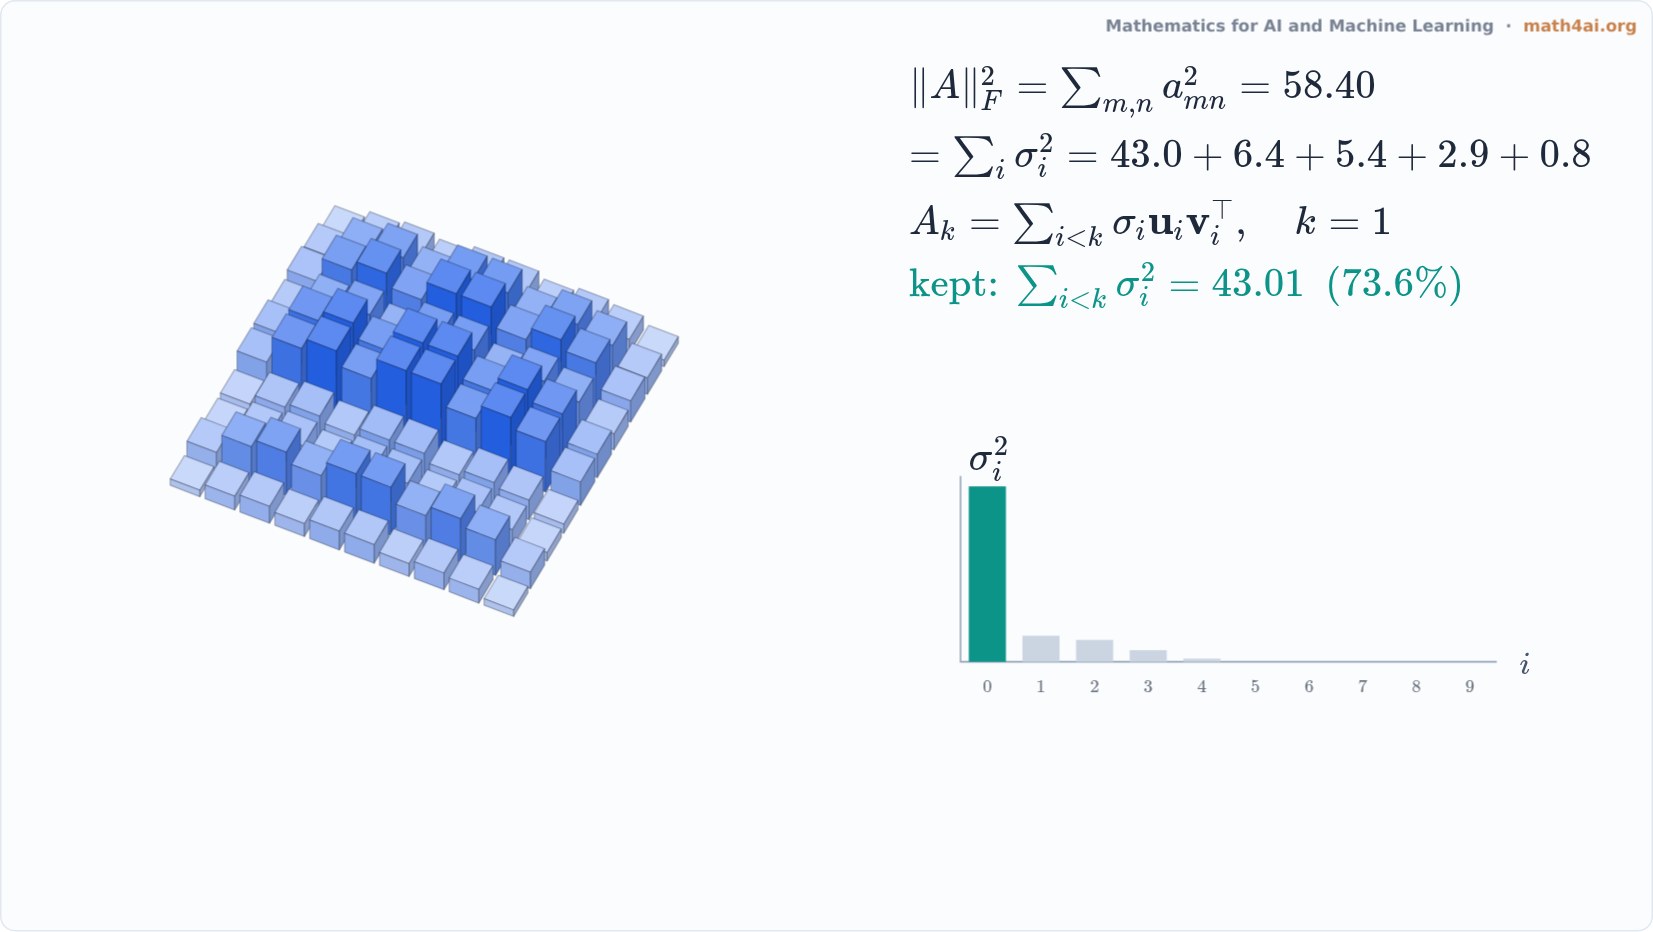 Preview1:31Energy from Singular Values: Rebuild a Picture Layer by LayerChapter 8
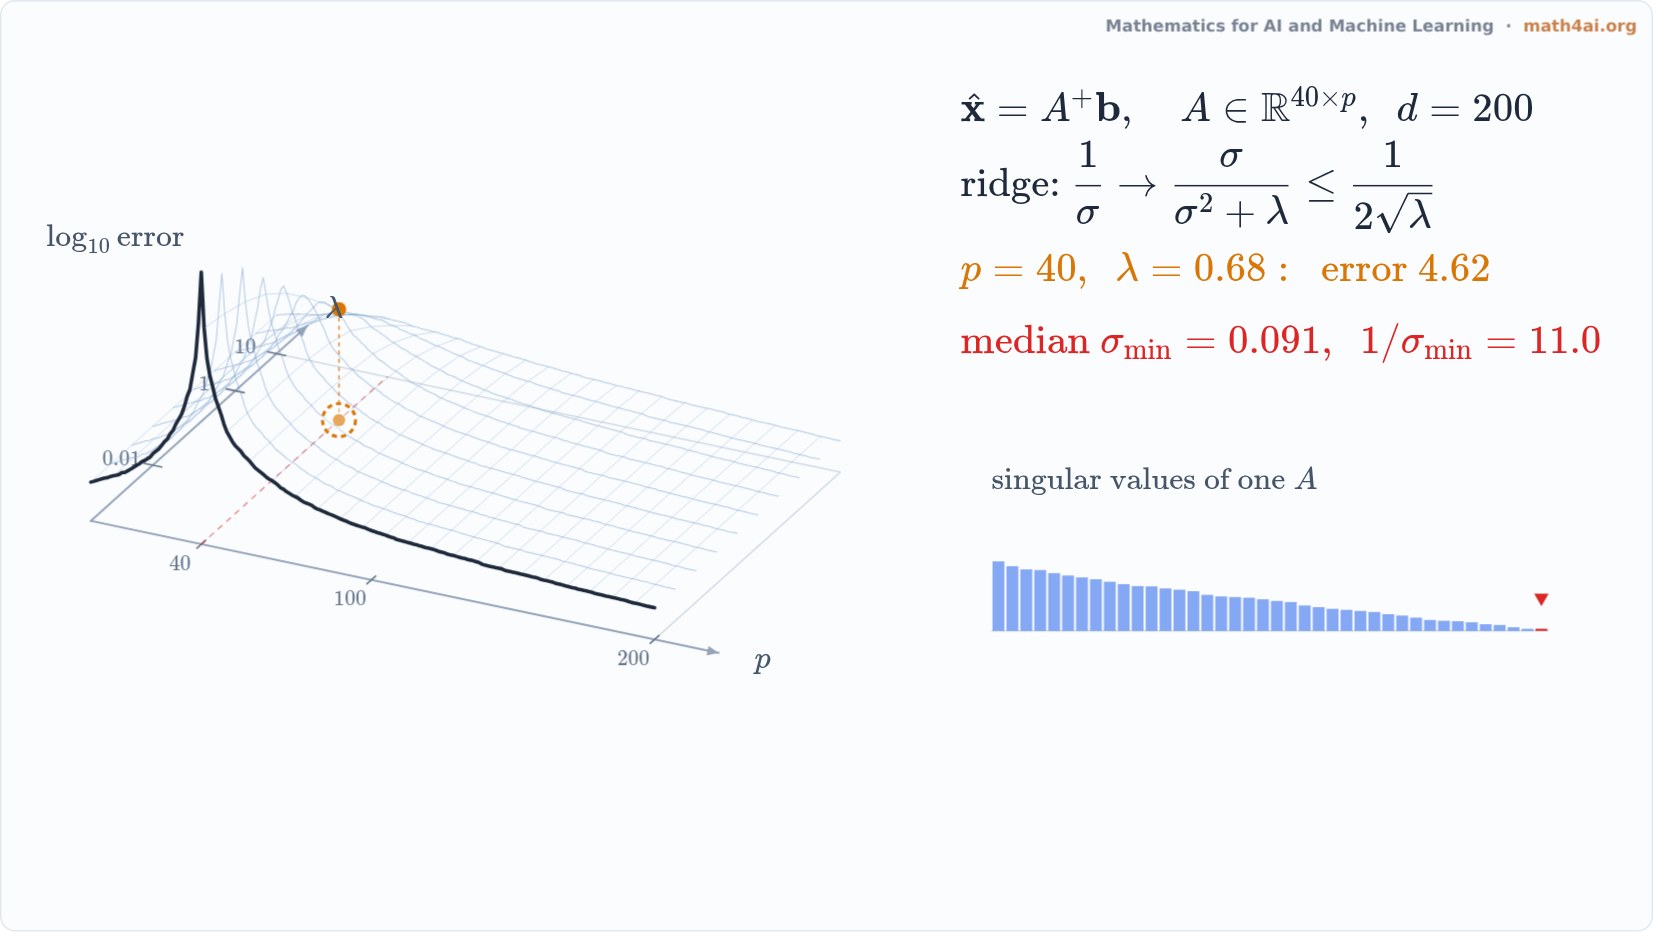 Preview1:33Double Descent at the Interpolation ThresholdChapter 8
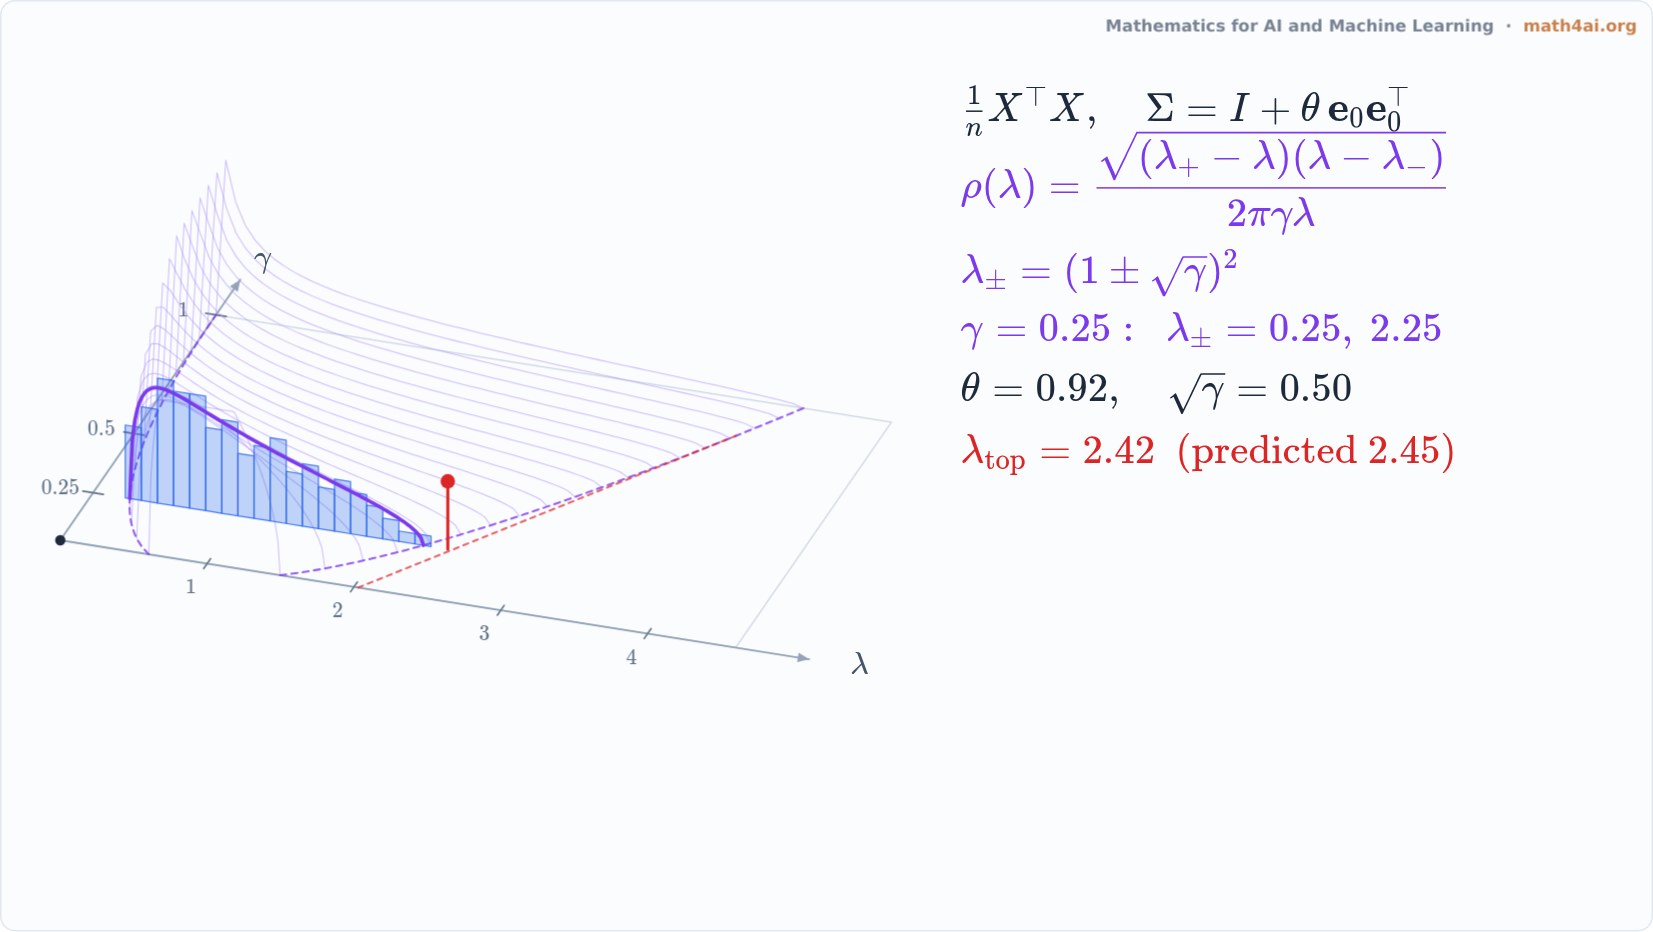 Preview1:32The Marchenko-Pastur Law and the Escaping EigenvalueChapter 8
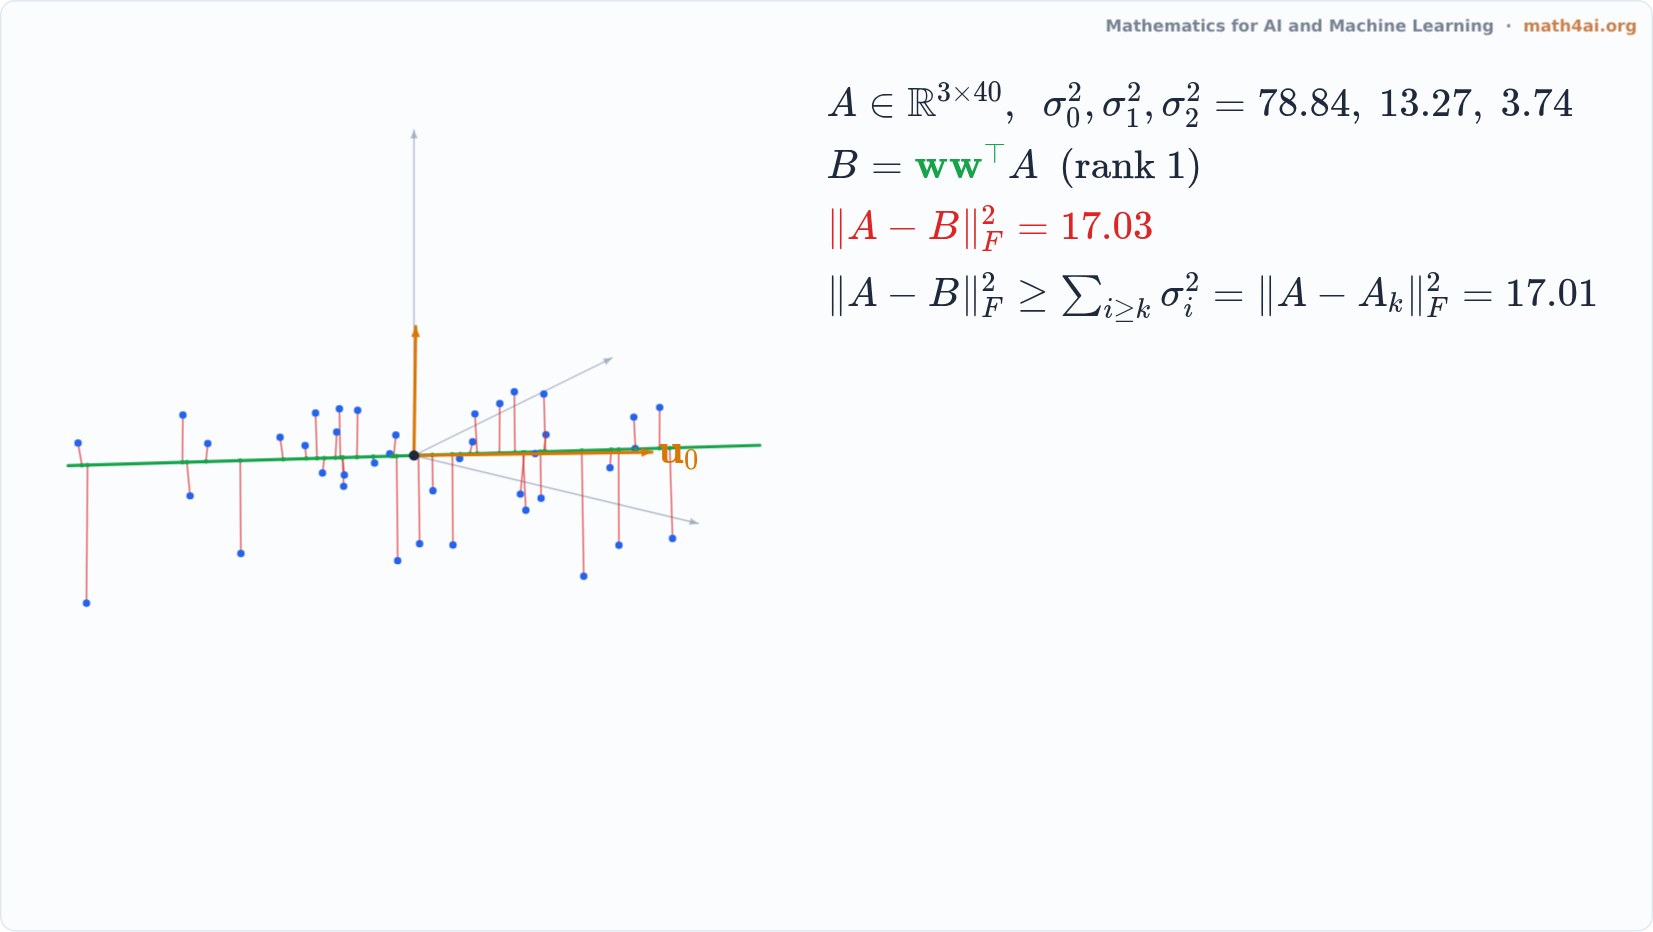 Preview1:43Eckart-Young: the Best Low-Rank ApproximationChapter 8
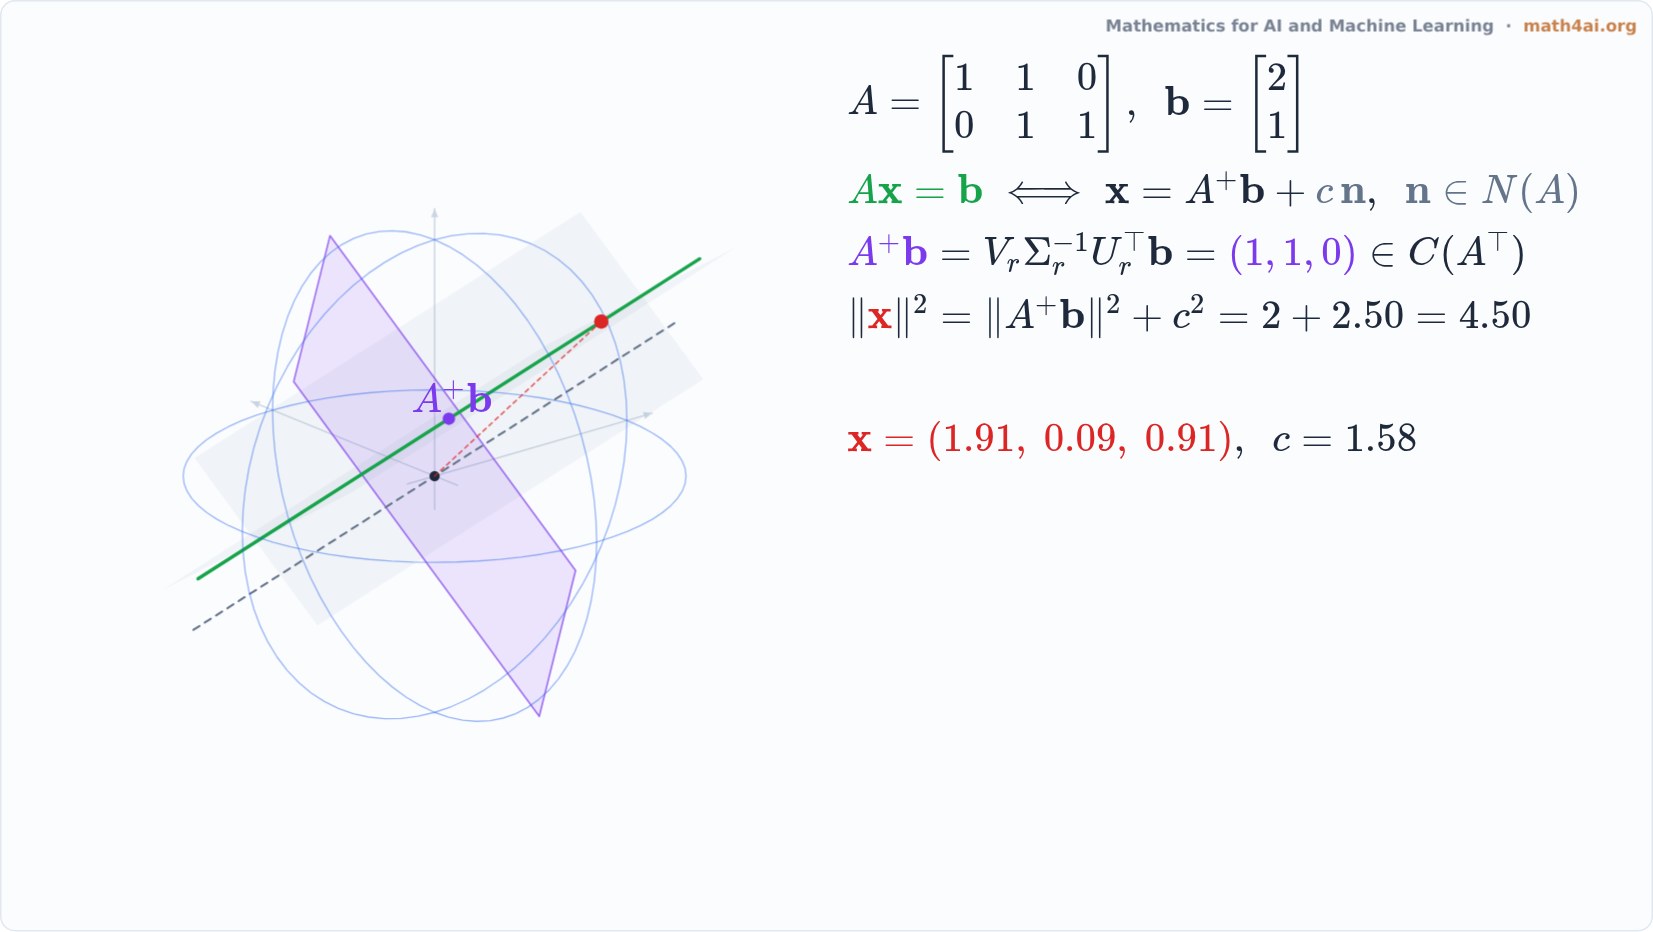 Preview1:46The Pseudoinverse: the Shortest SolutionChapter 8
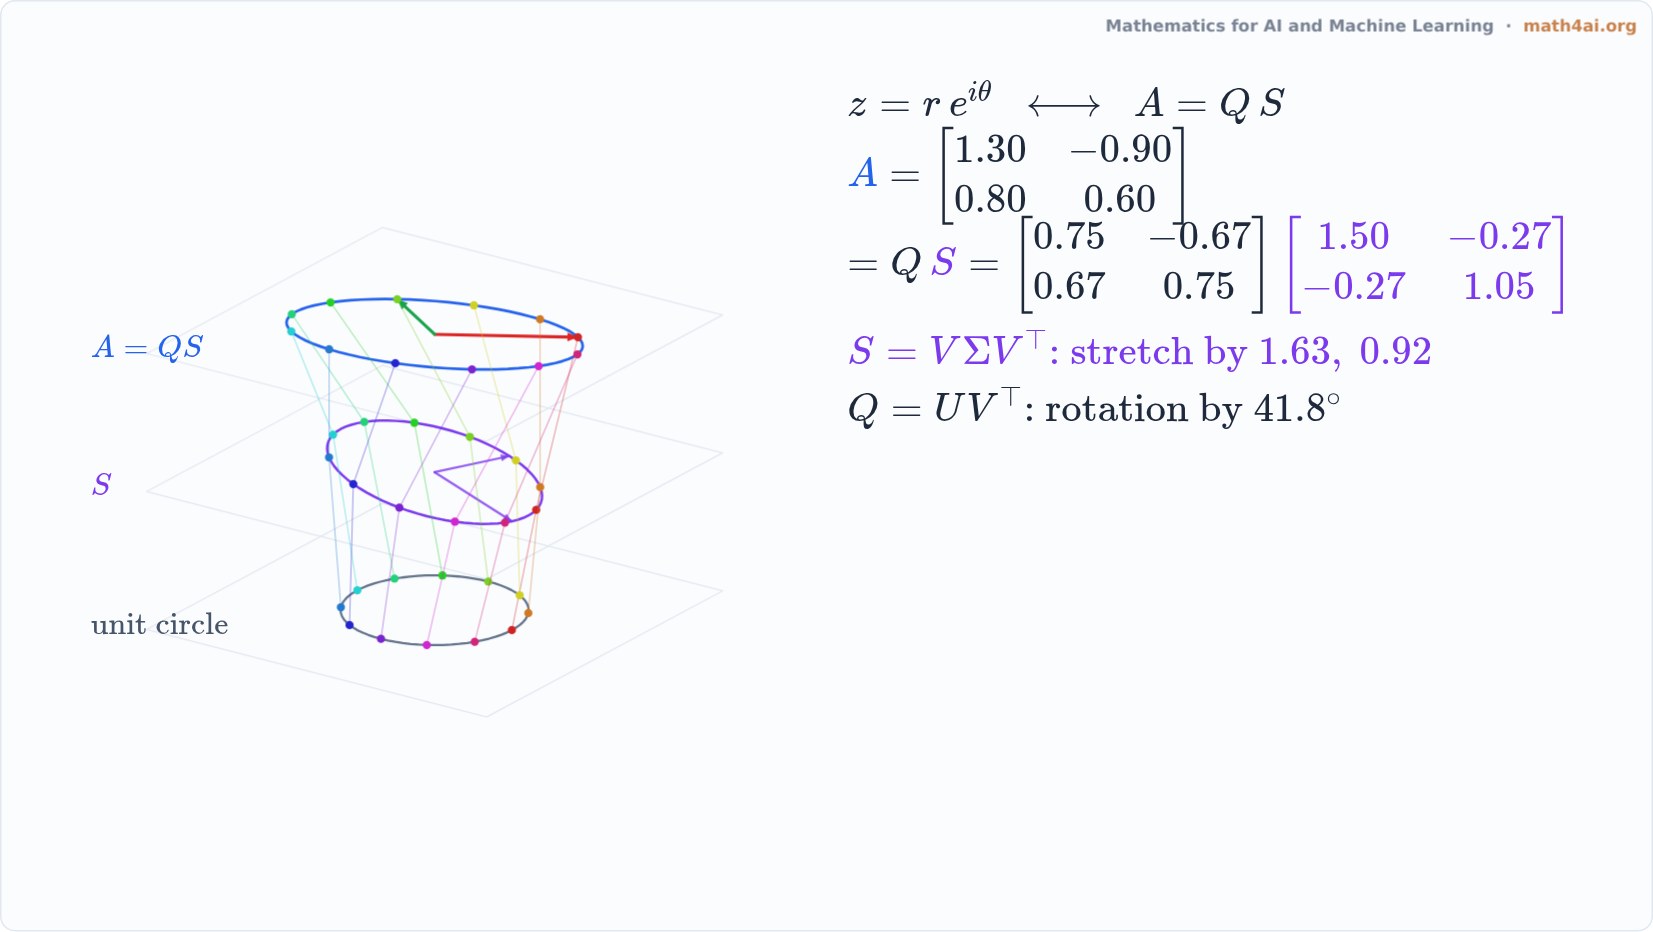 Preview1:31Polar Decomposition: Stretch, then RotateChapter 8
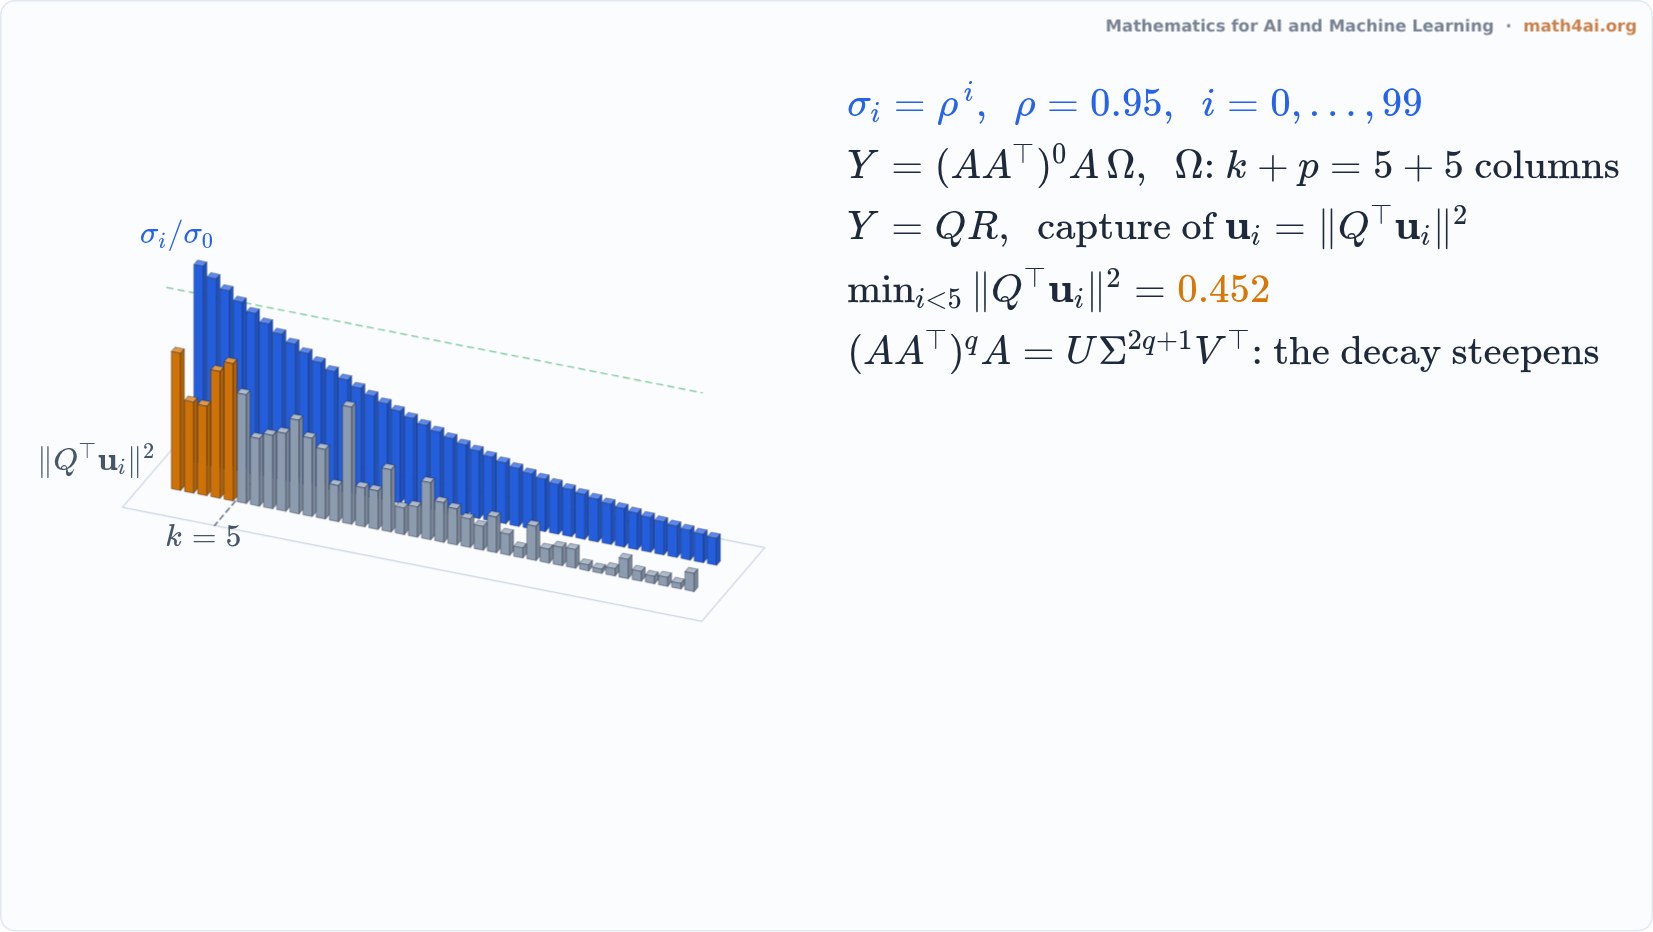 Preview1:47Randomized SVD: Catching the Top DirectionsChapter 8
Chapter 9 Matrix Decompositions and Beyond
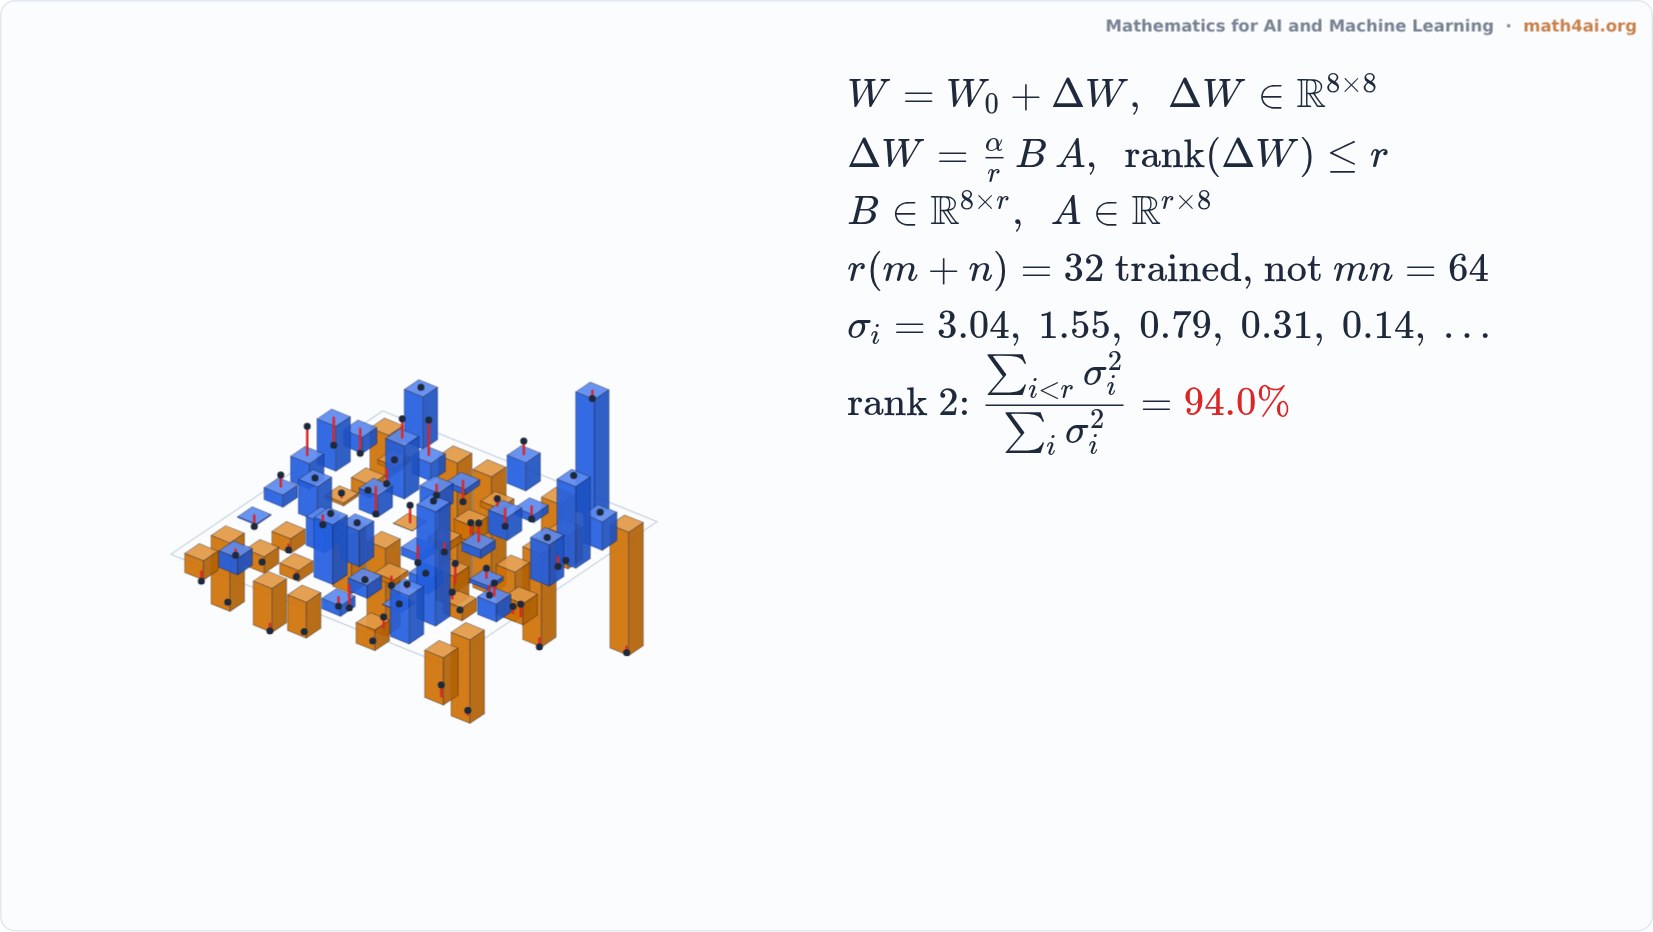 Interactive1:34LoRA: a Low-Rank UpdateChapter 9
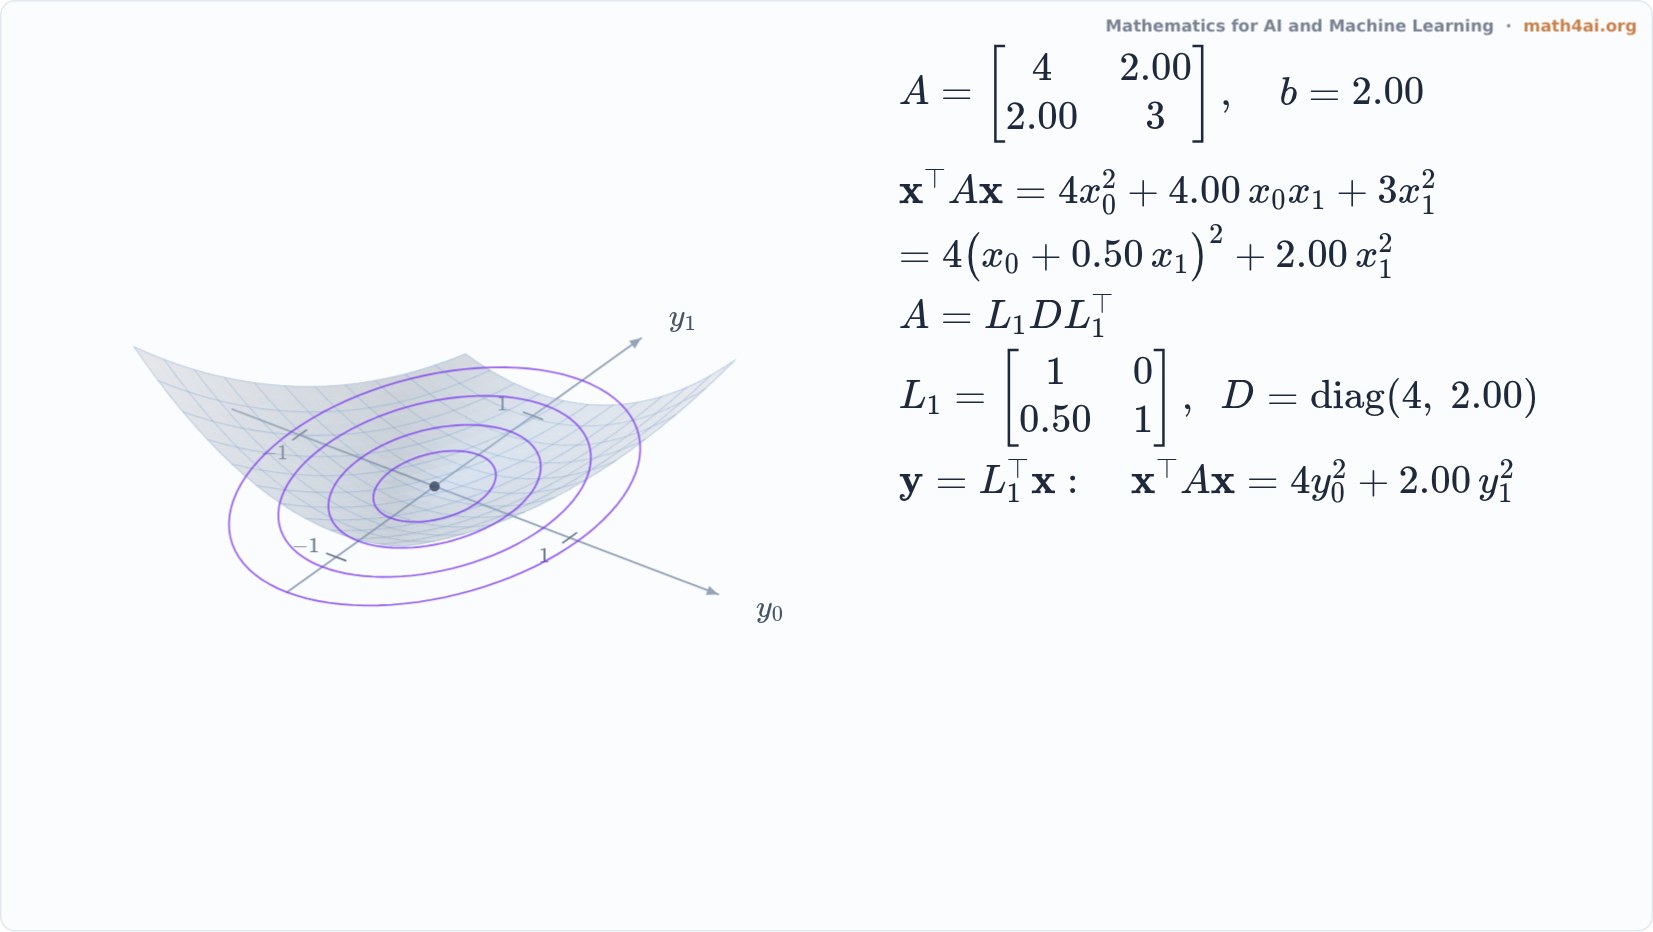 Preview1:48LDL Is Completing the SquareChapter 9
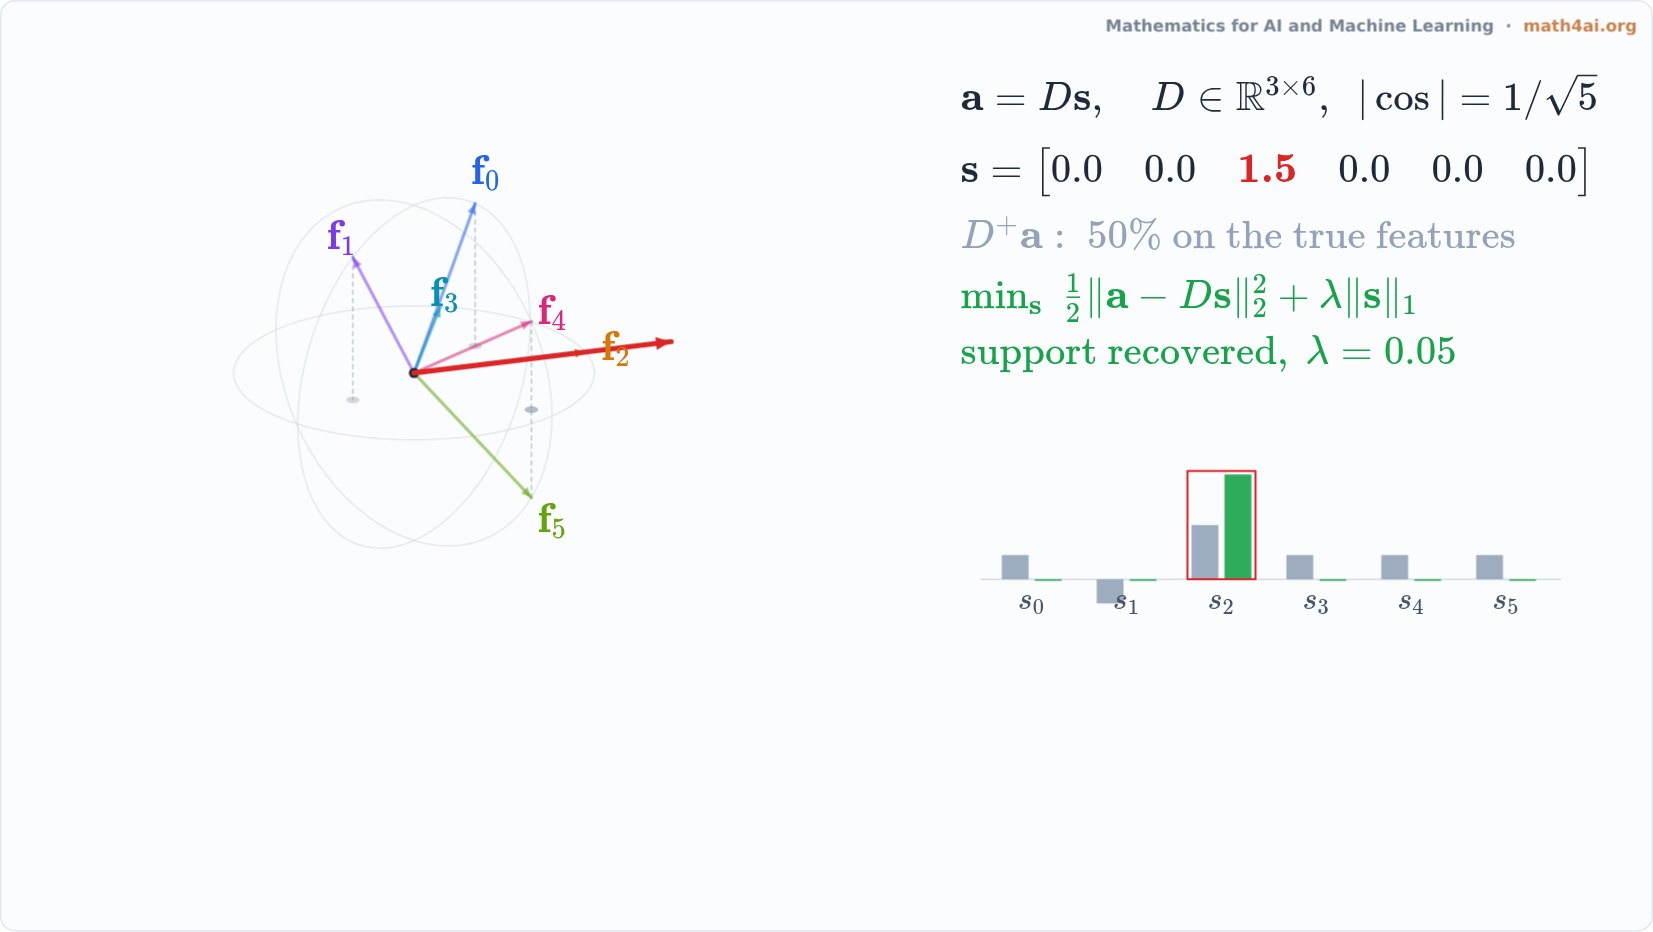 Preview1:25Superposition and Sparse CodingChapter 9
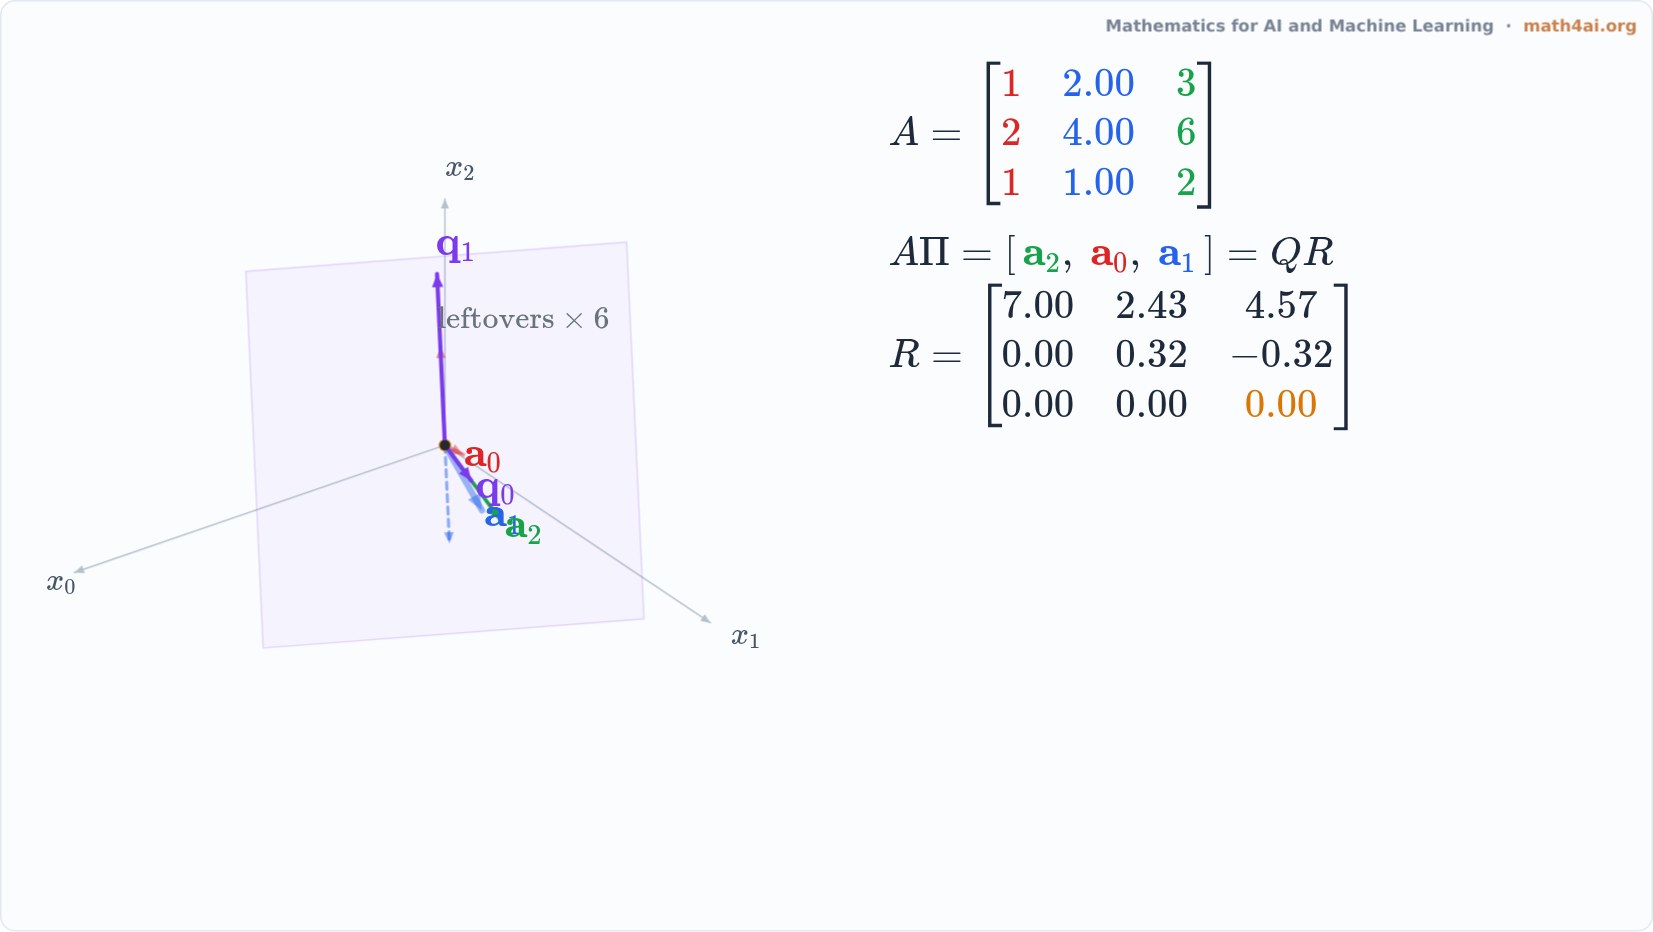 Preview1:47Rank-Revealing QR: Pick the Columns in a Good OrderChapter 9
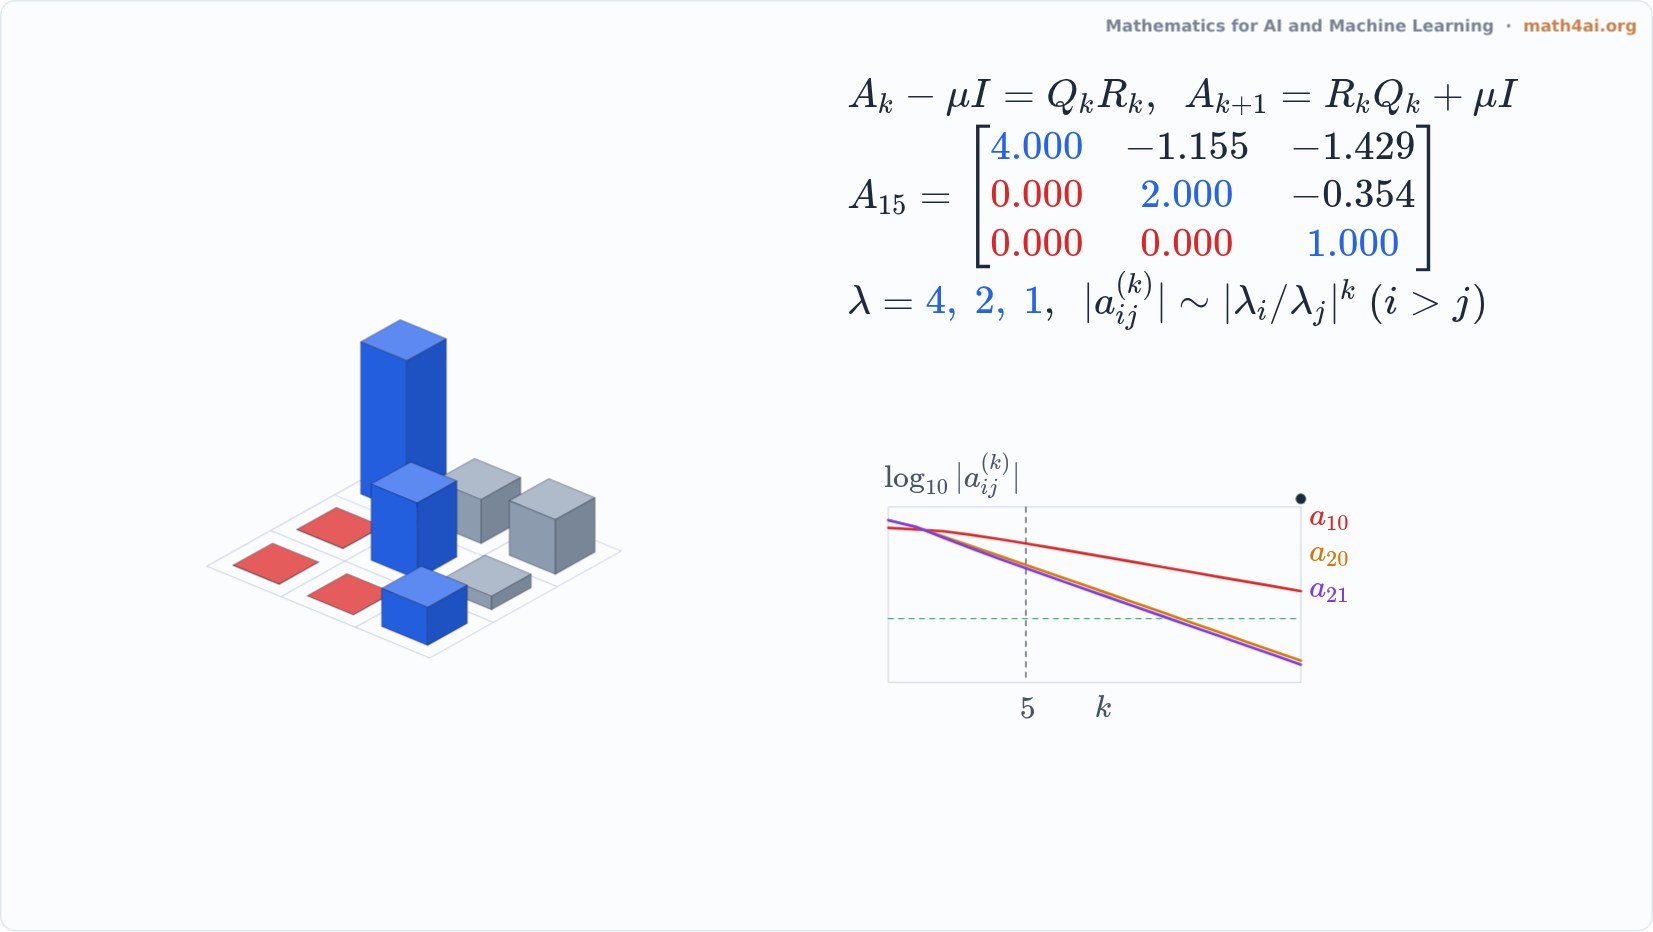 Preview1:56The QR Algorithm: Sweeping a Matrix into Schur FormChapter 9
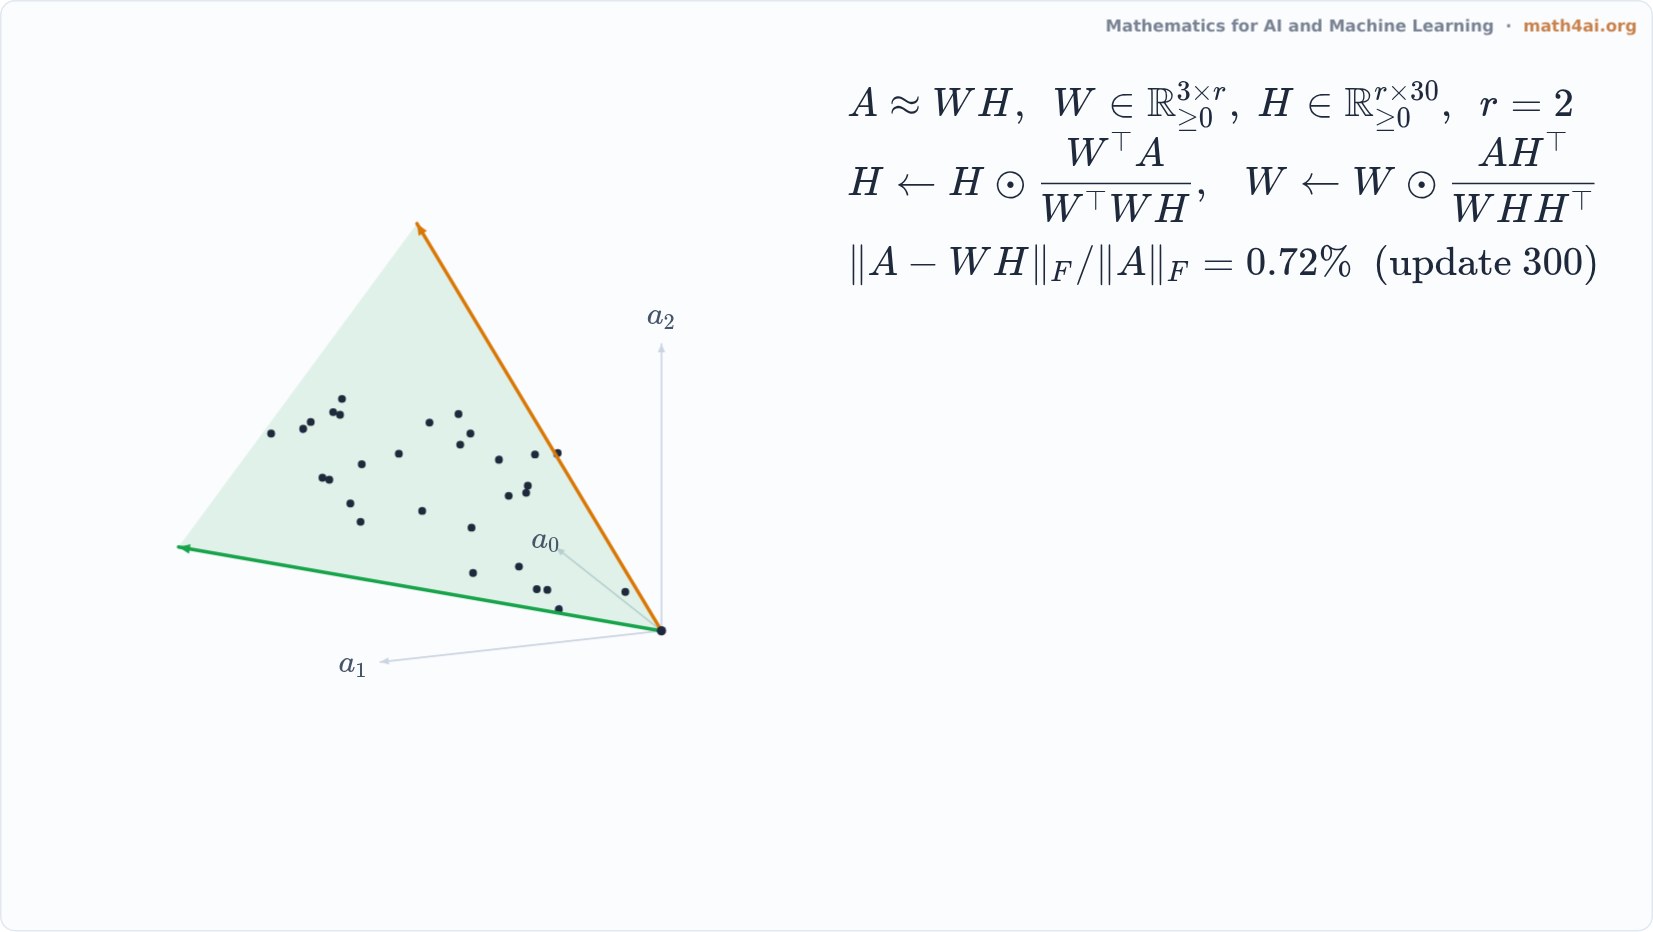 Preview1:36Non-Negative Matrix Factorization: a Cone of PartsChapter 9
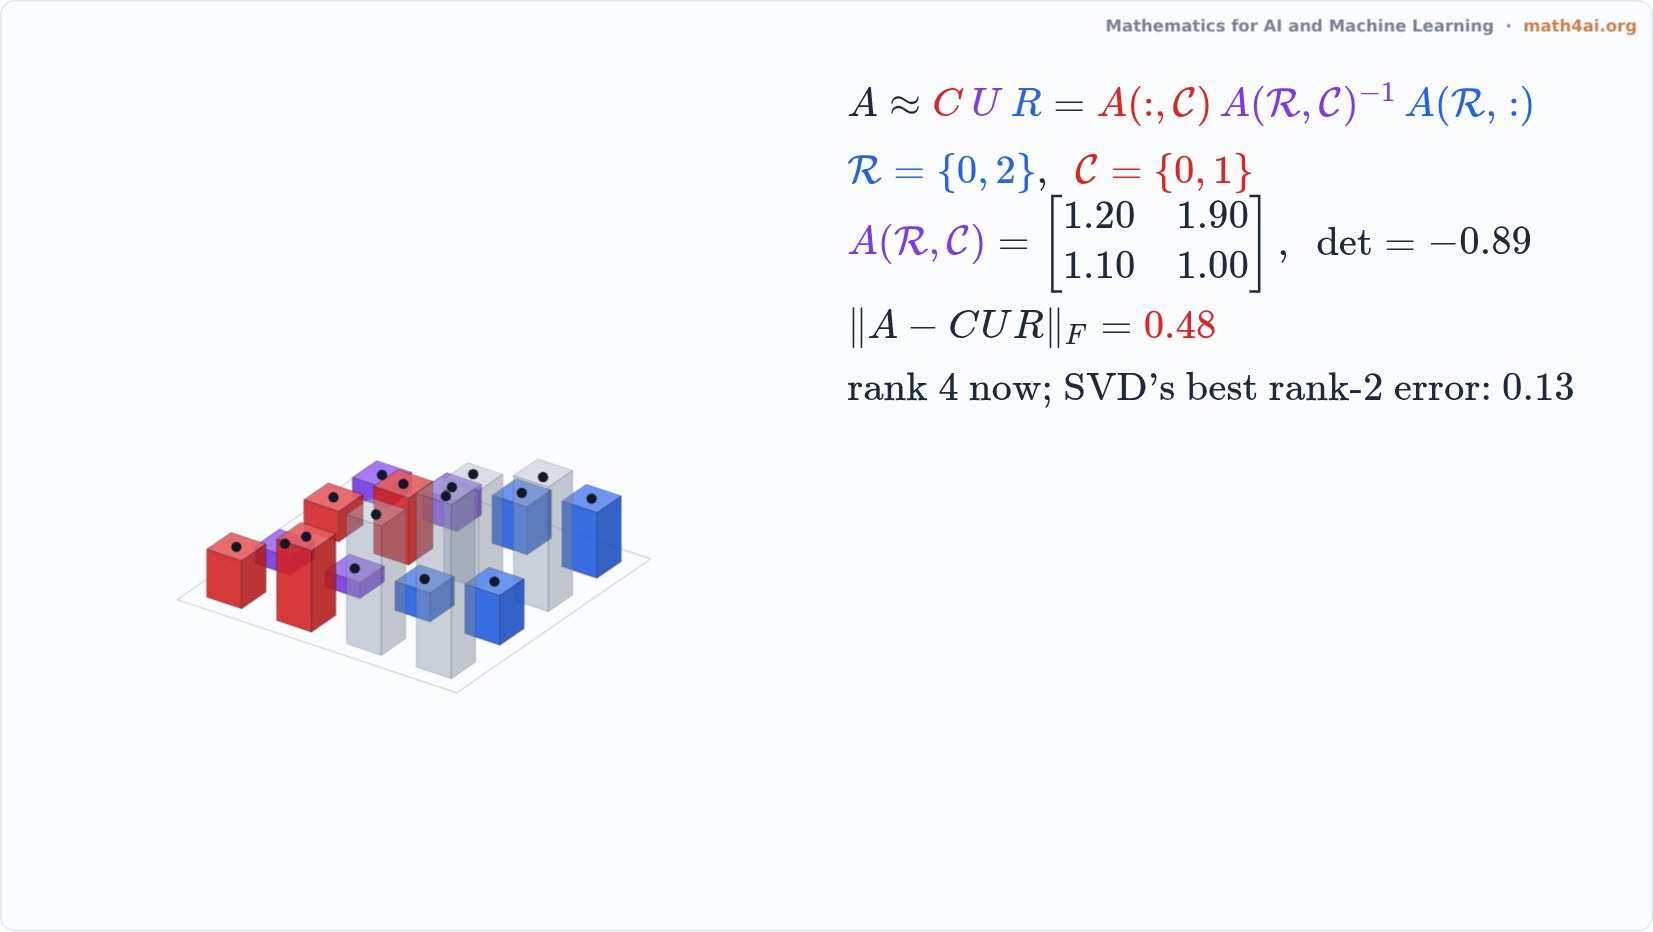 Preview1:33CUR: Rebuilding a Matrix from Its Own Rows and ColumnsChapter 9
Chapter 10 Matrix Block Partitioning
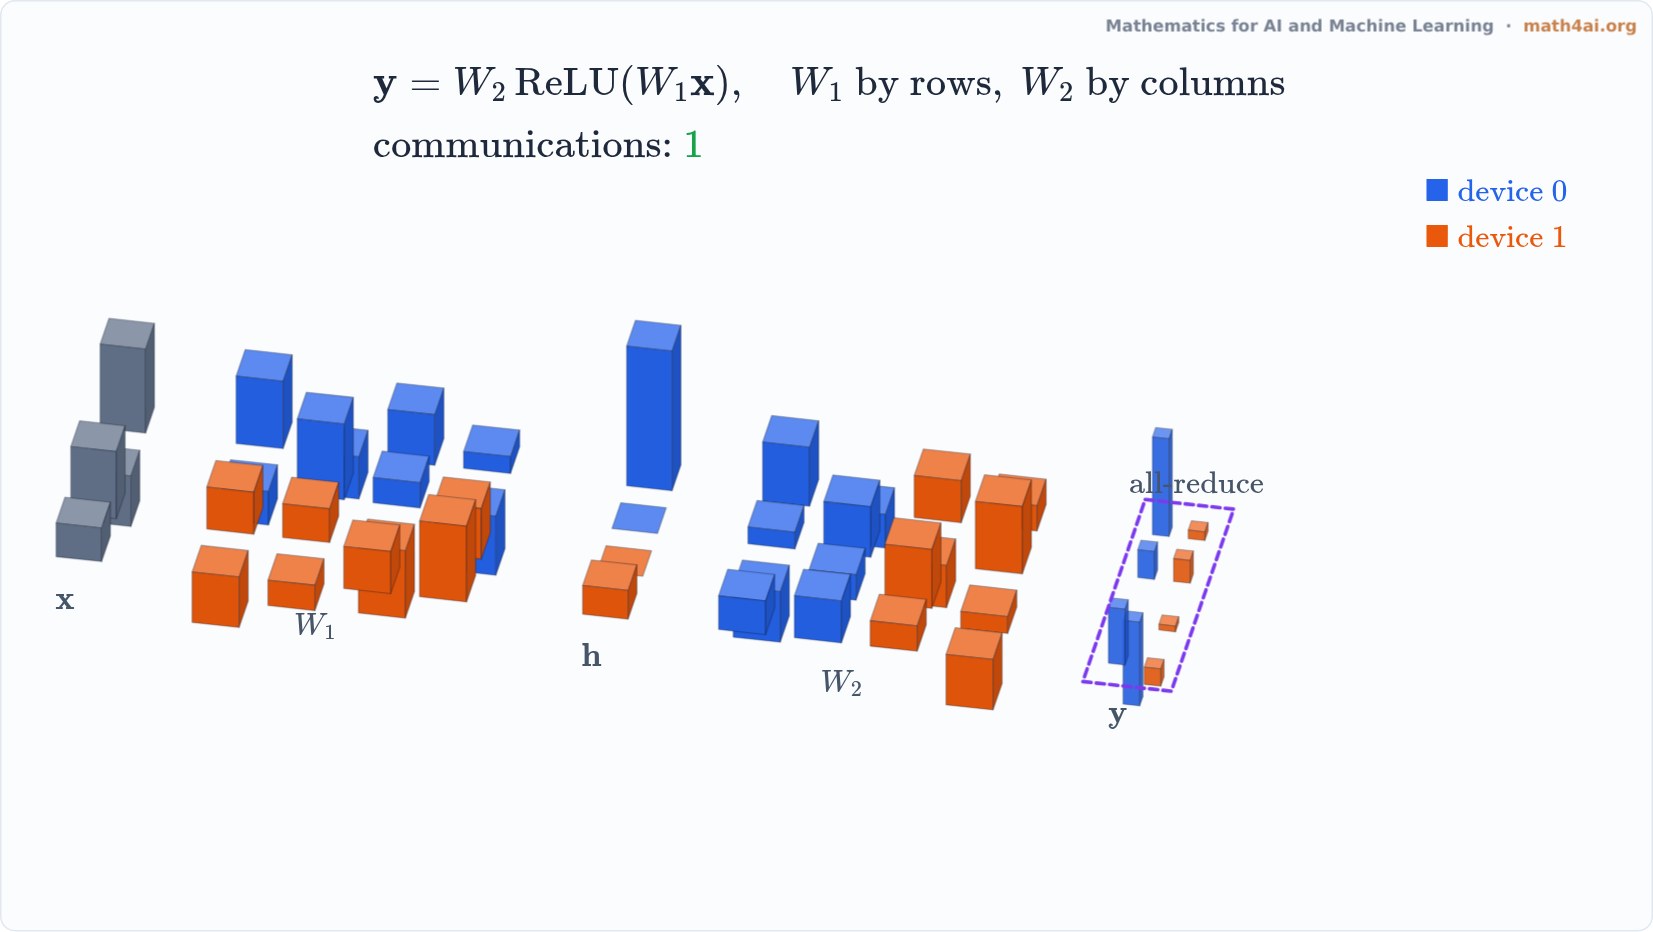 Interactive2:11Tensor Parallelism: Block Products Across DevicesChapter 10
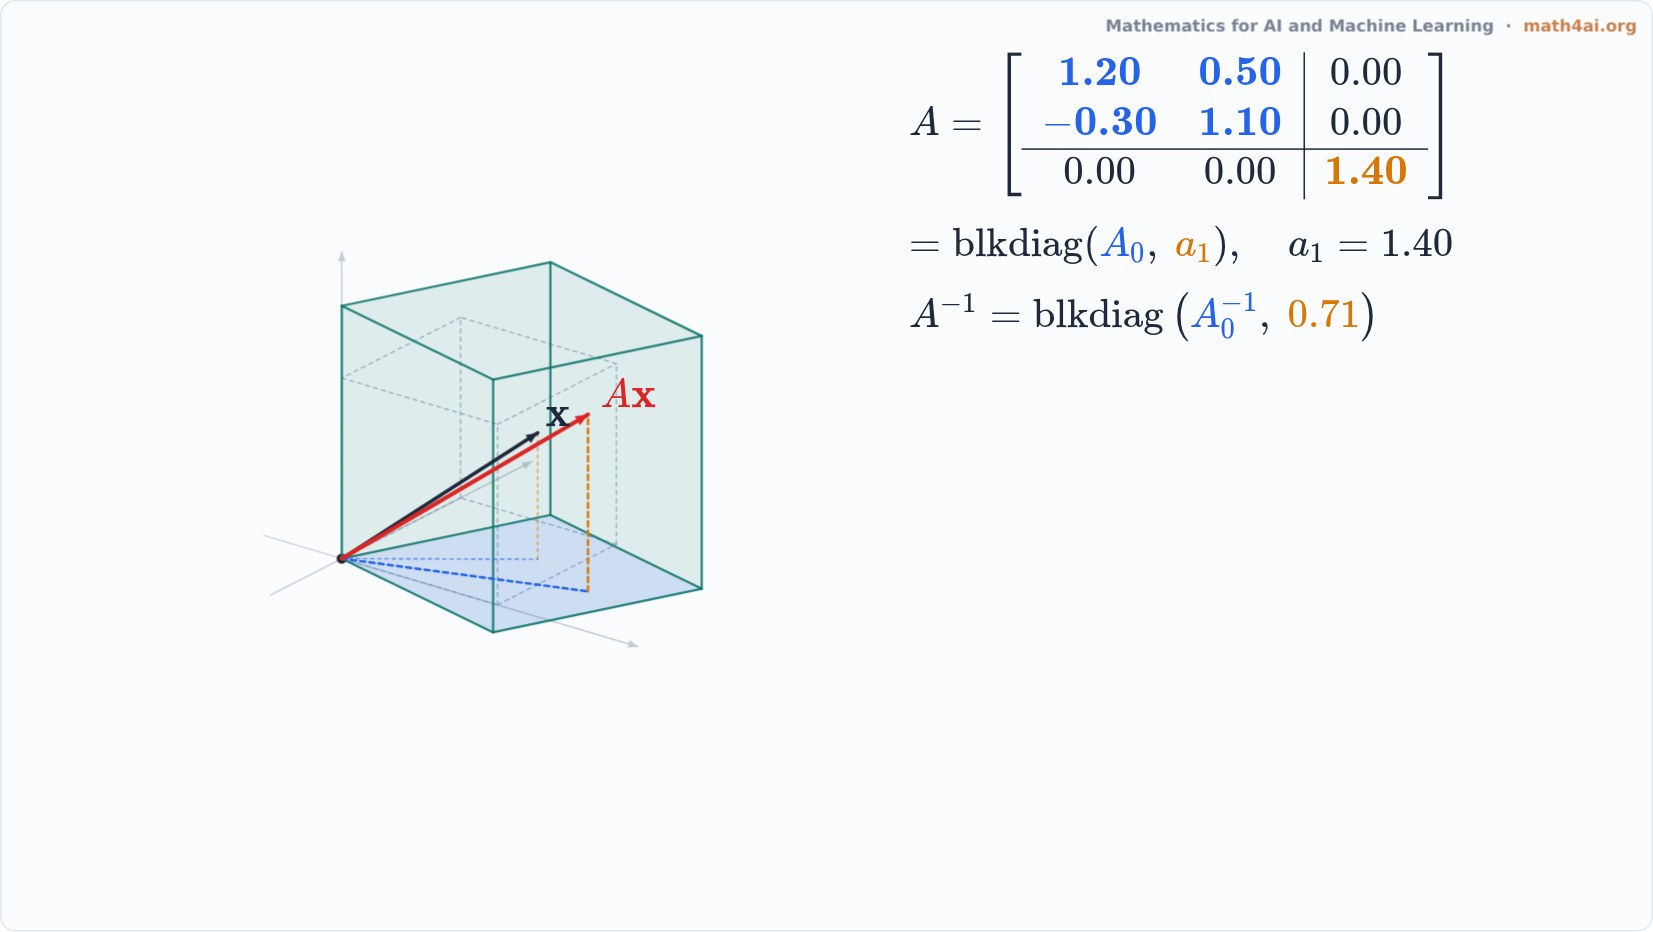 Preview1:24Block Diagonal Matrices: Separate WorldsChapter 10
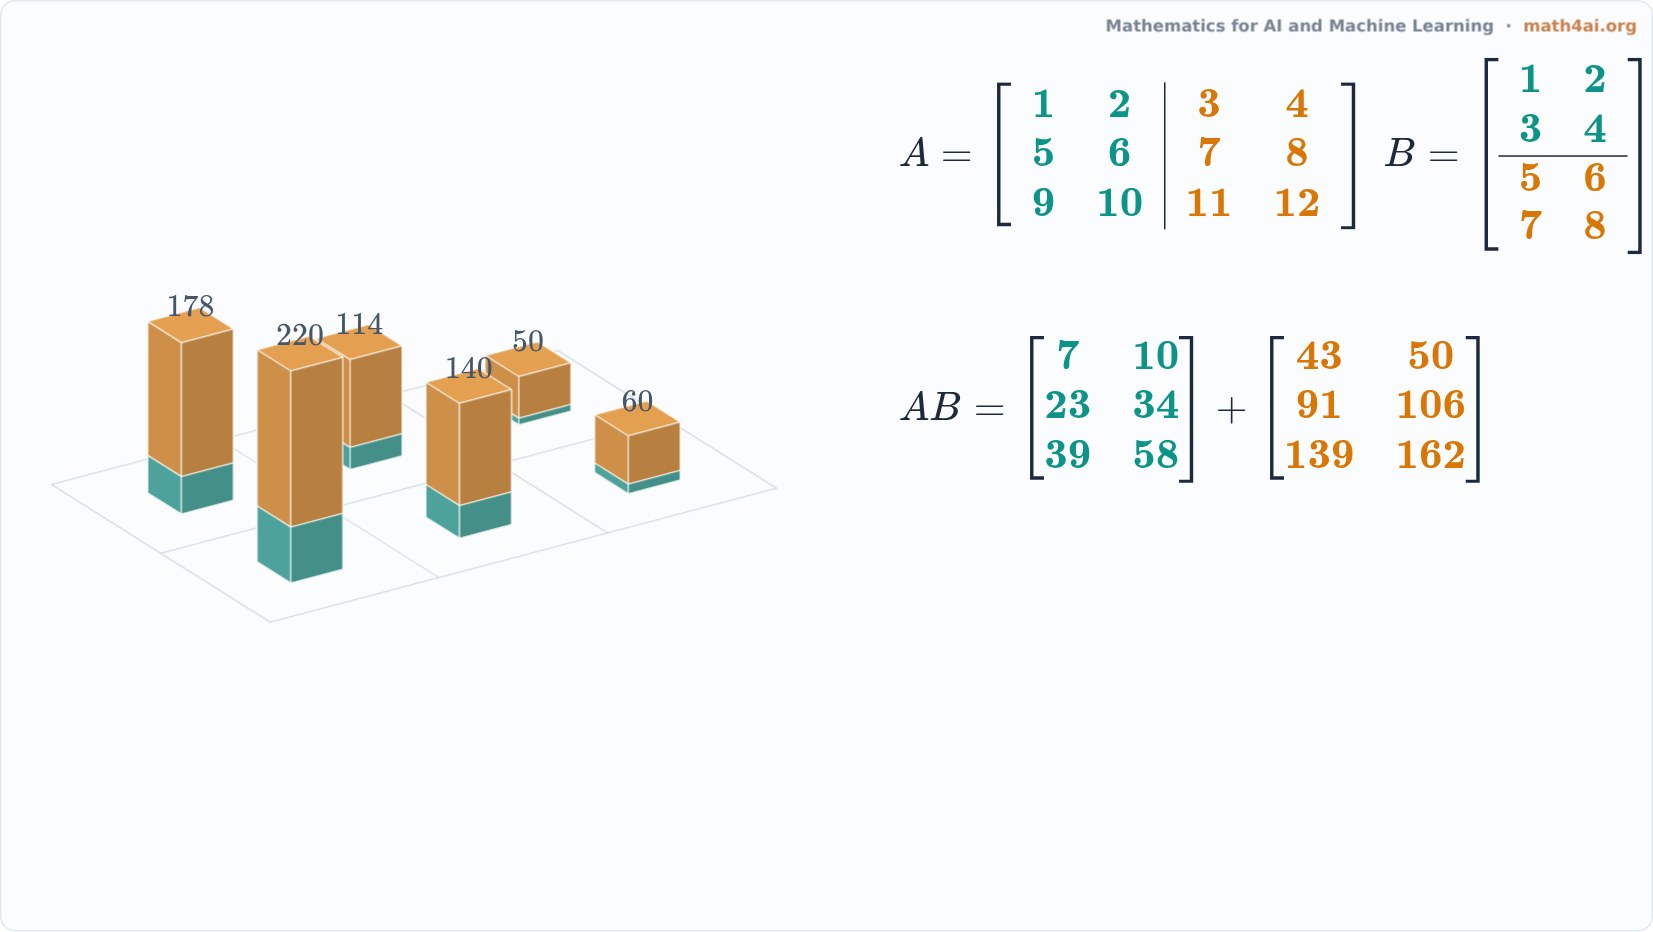 Preview1:28Block Multiplication: Blocks Multiply Like NumbersChapter 10
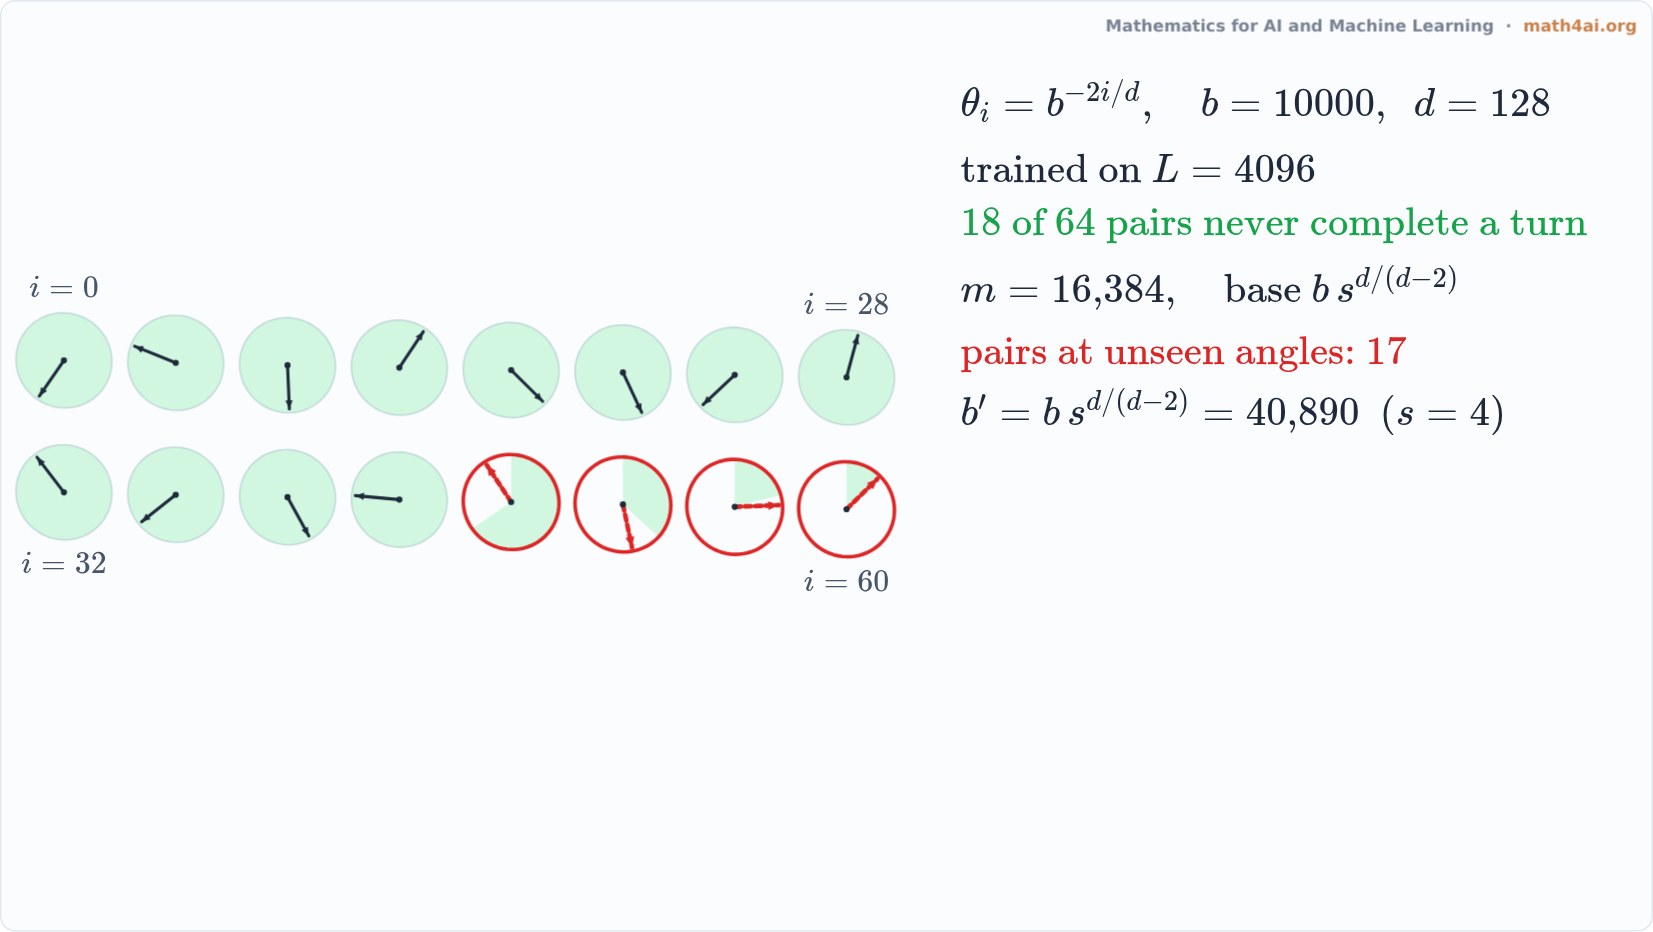 Preview1:39Longer Contexts with Rotary PositionsChapter 10
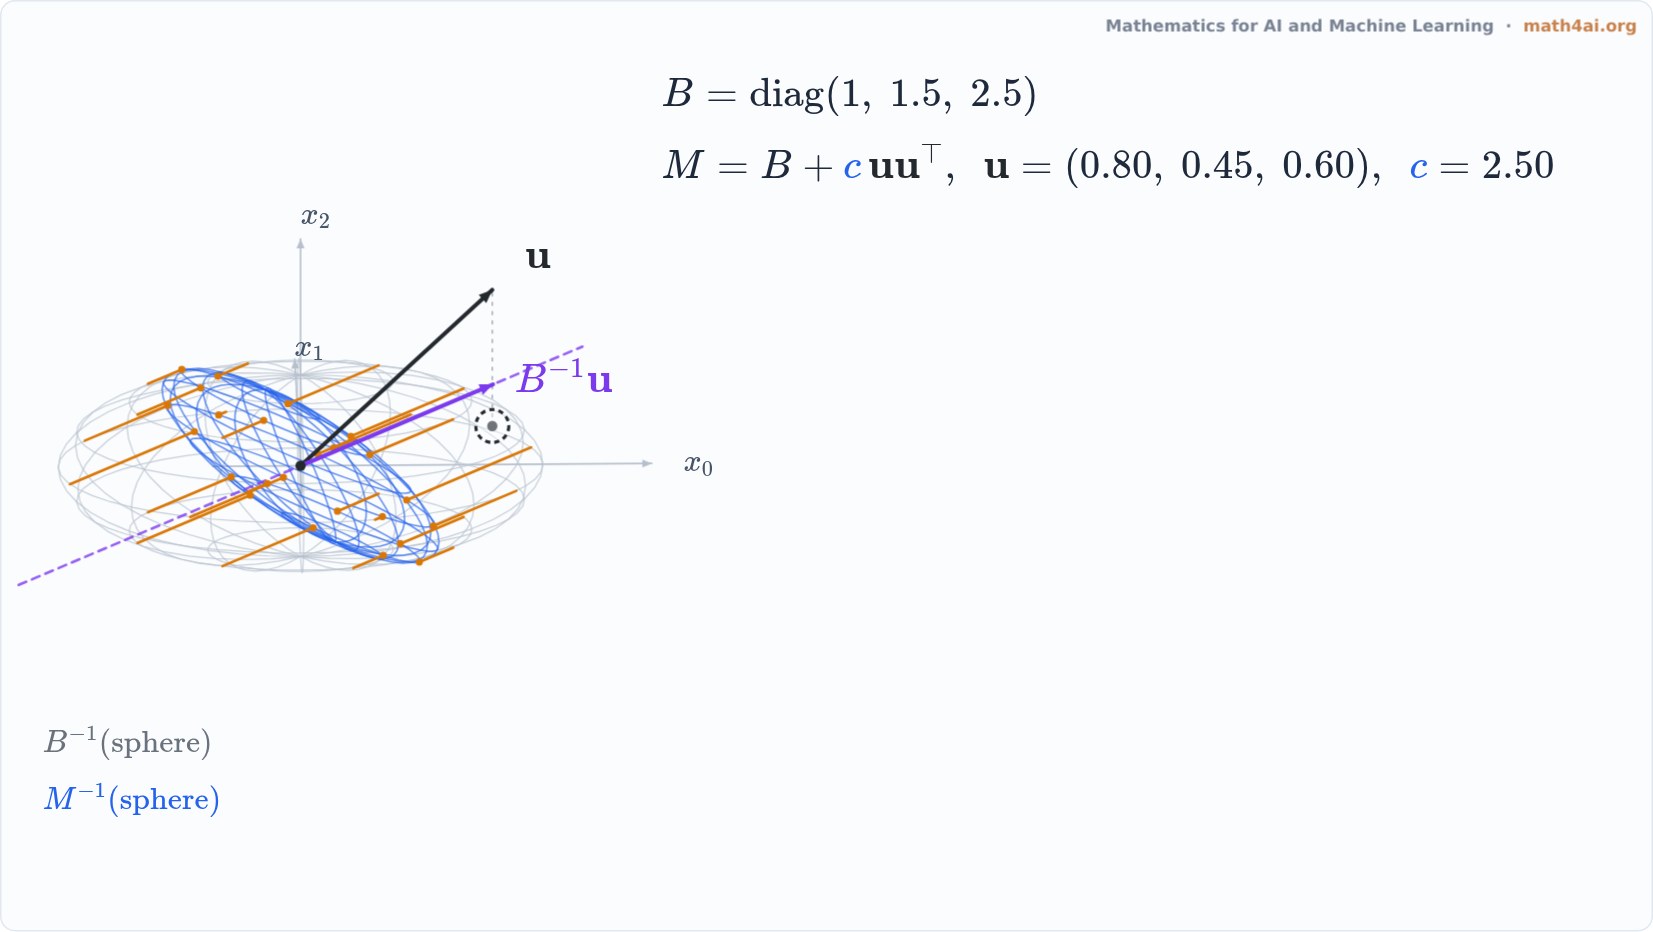 Preview2:20Woodbury Identity: a Rank-One Update of the InverseChapter 10
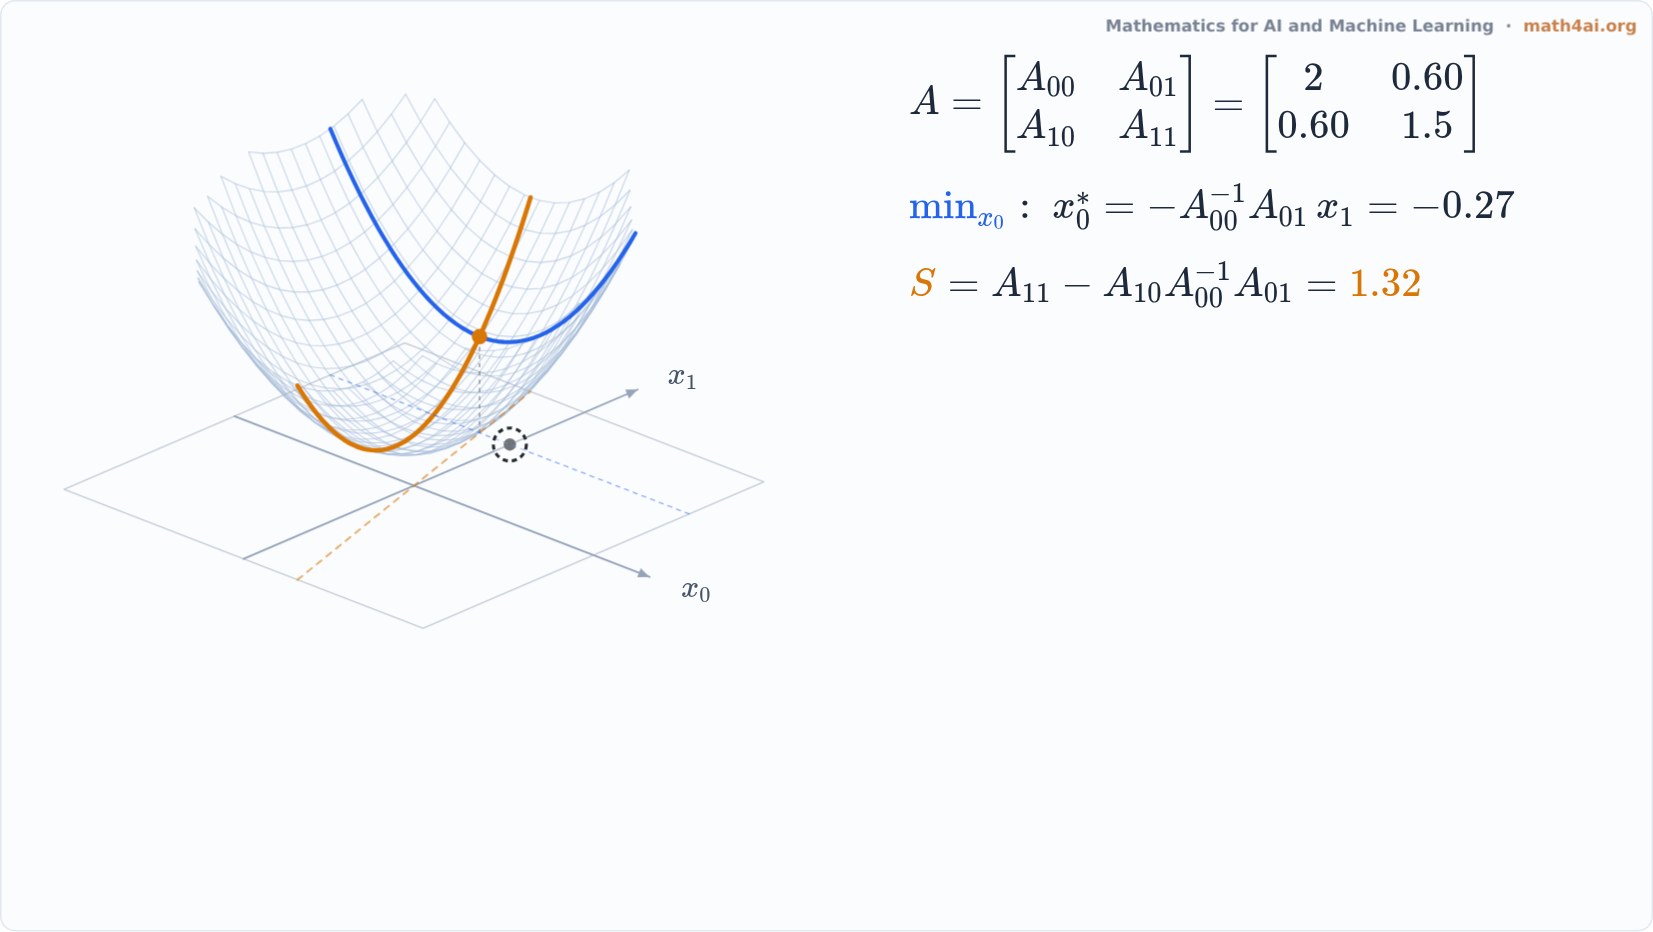 Preview1:40Schur Complement: What Is Left After Minimizing Out a BlockChapter 10
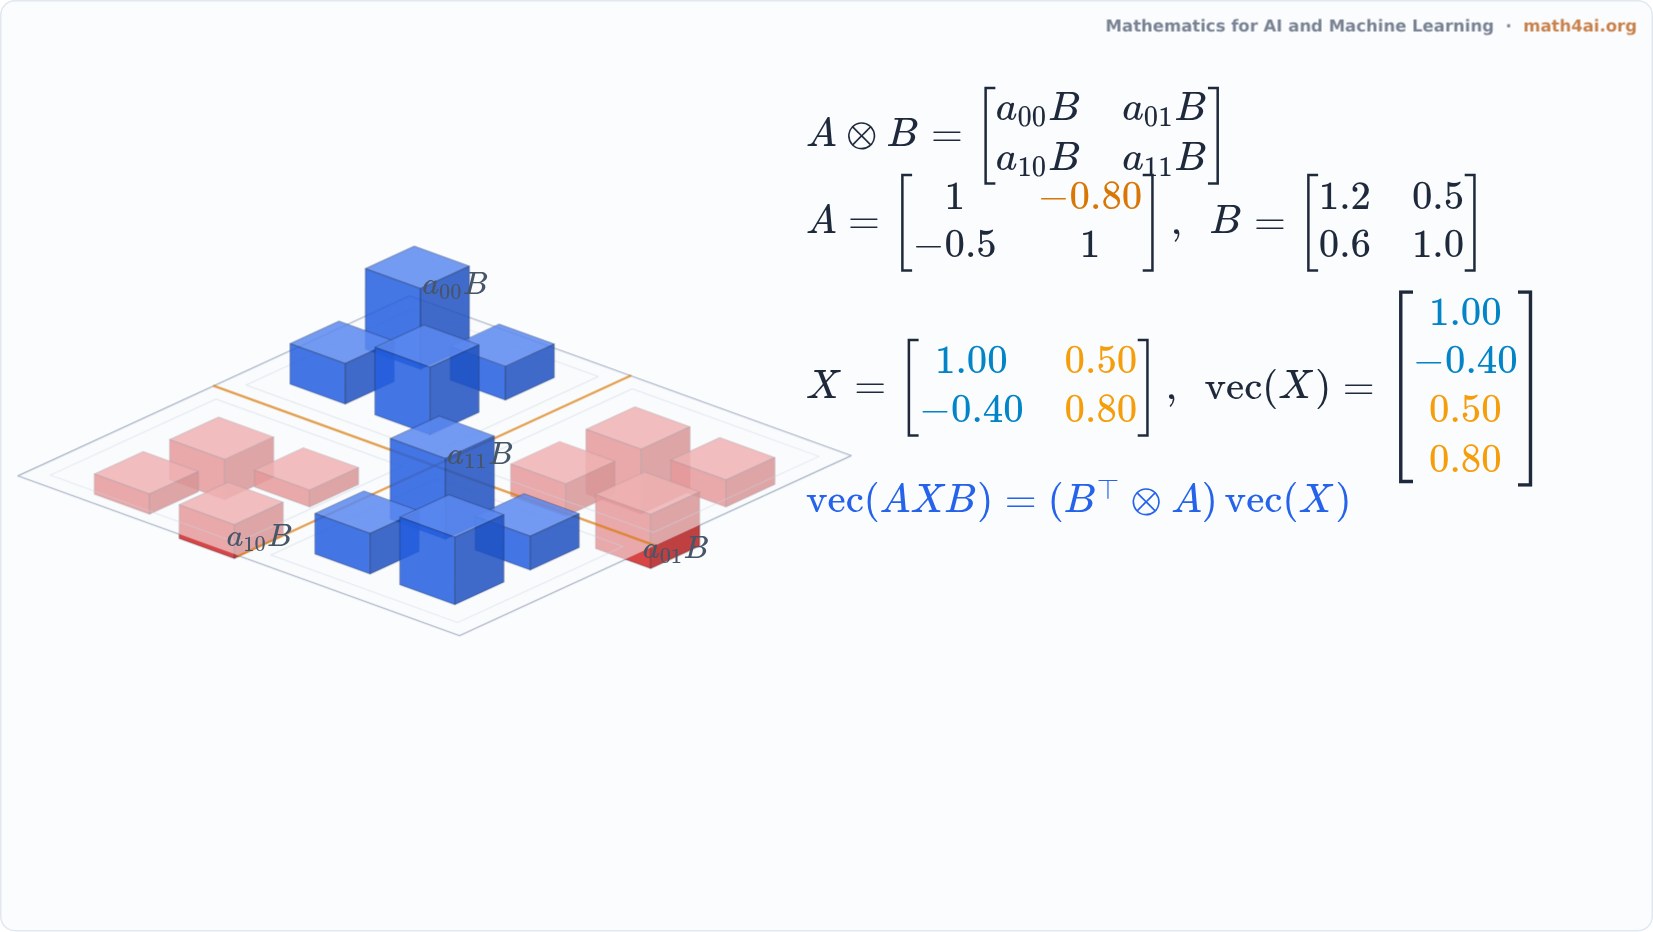 Preview1:32Kronecker Product and the Vectorization IdentityChapter 10
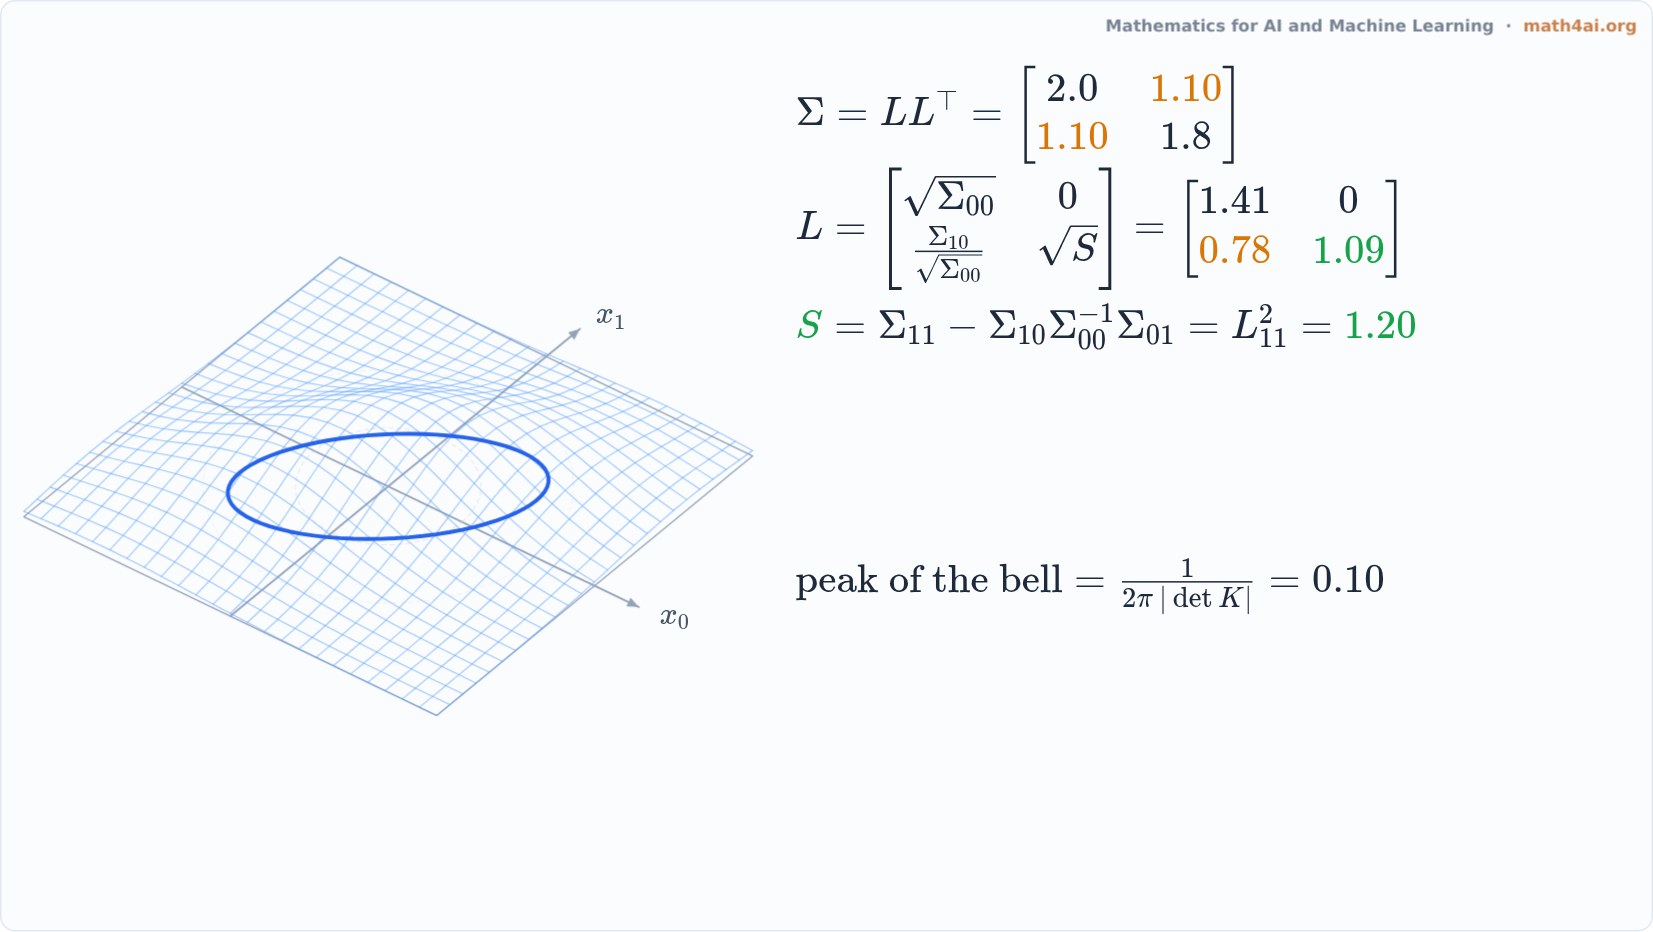 Preview1:40Block Cholesky: Two Steps to a CircleChapter 10
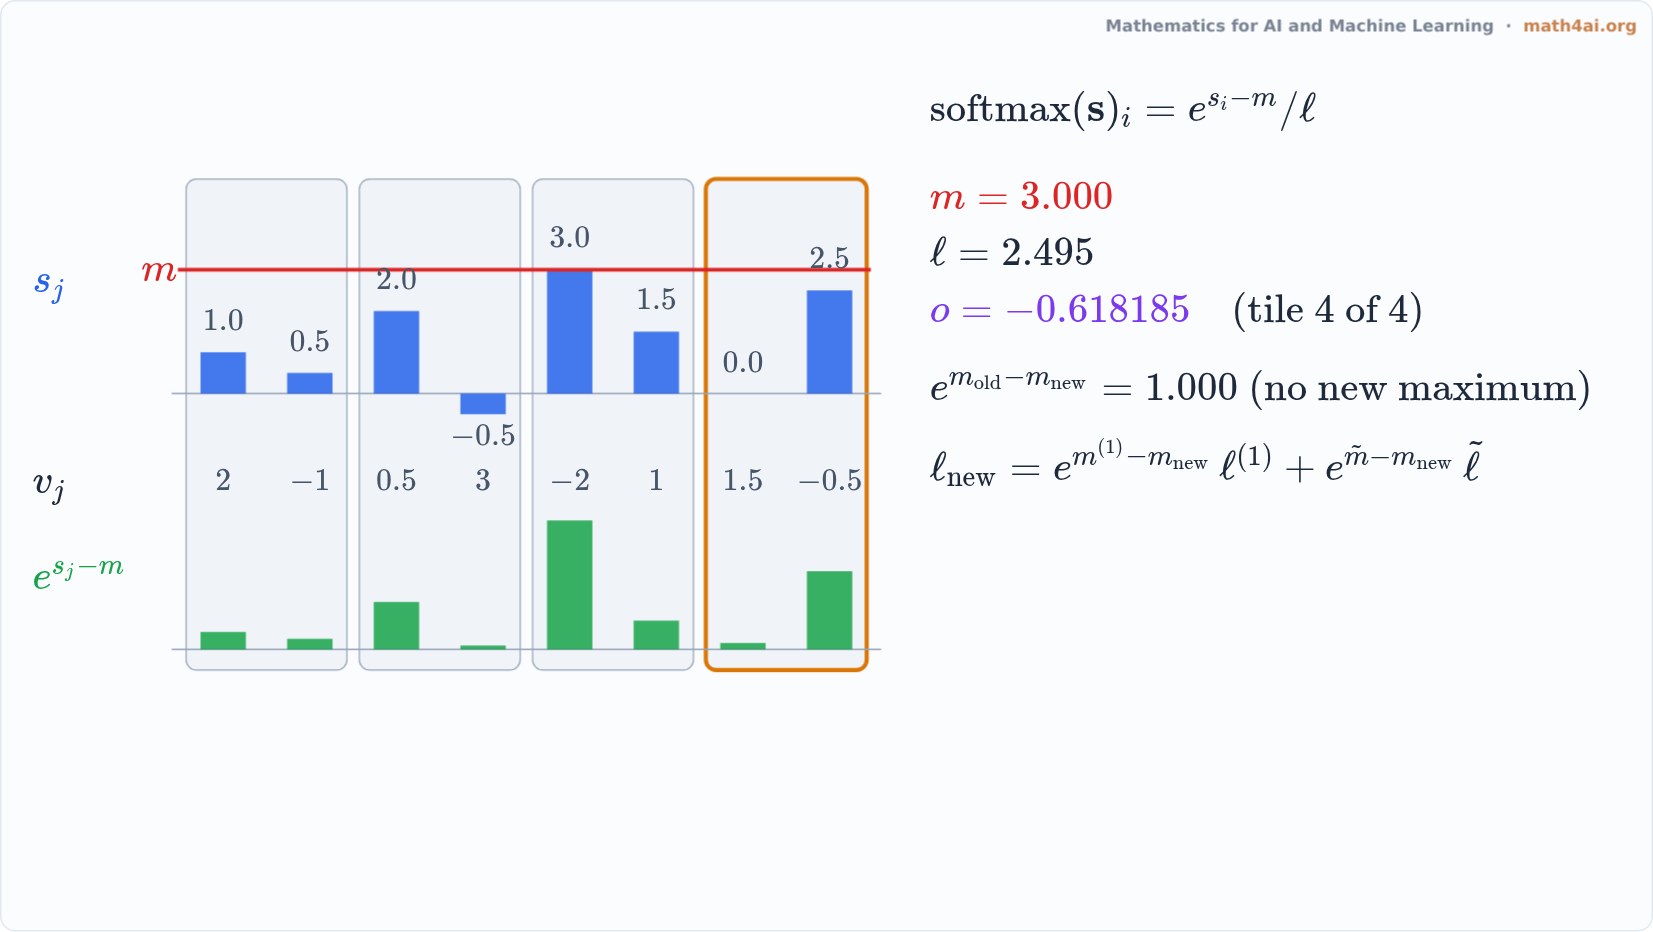 Preview1:30Online Softmax, One Tile at a TimeChapter 10
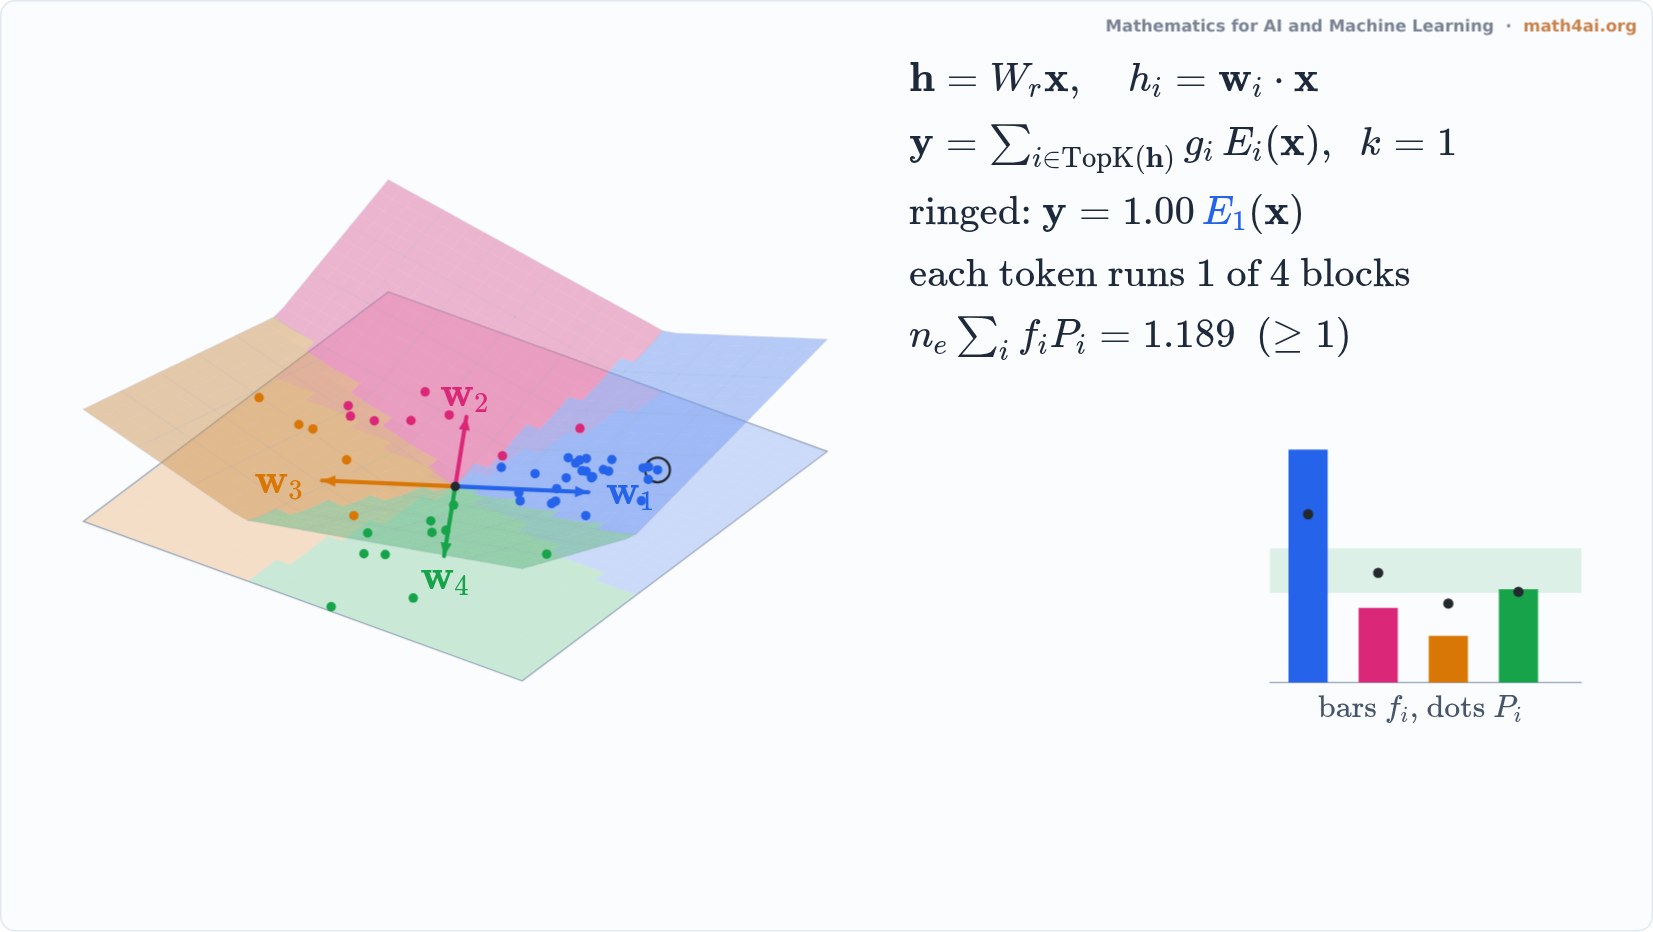 Preview1:56Mixture of Experts: Routing Tokens to a Few BlocksChapter 10
Chapter 11 Matrix Calculus
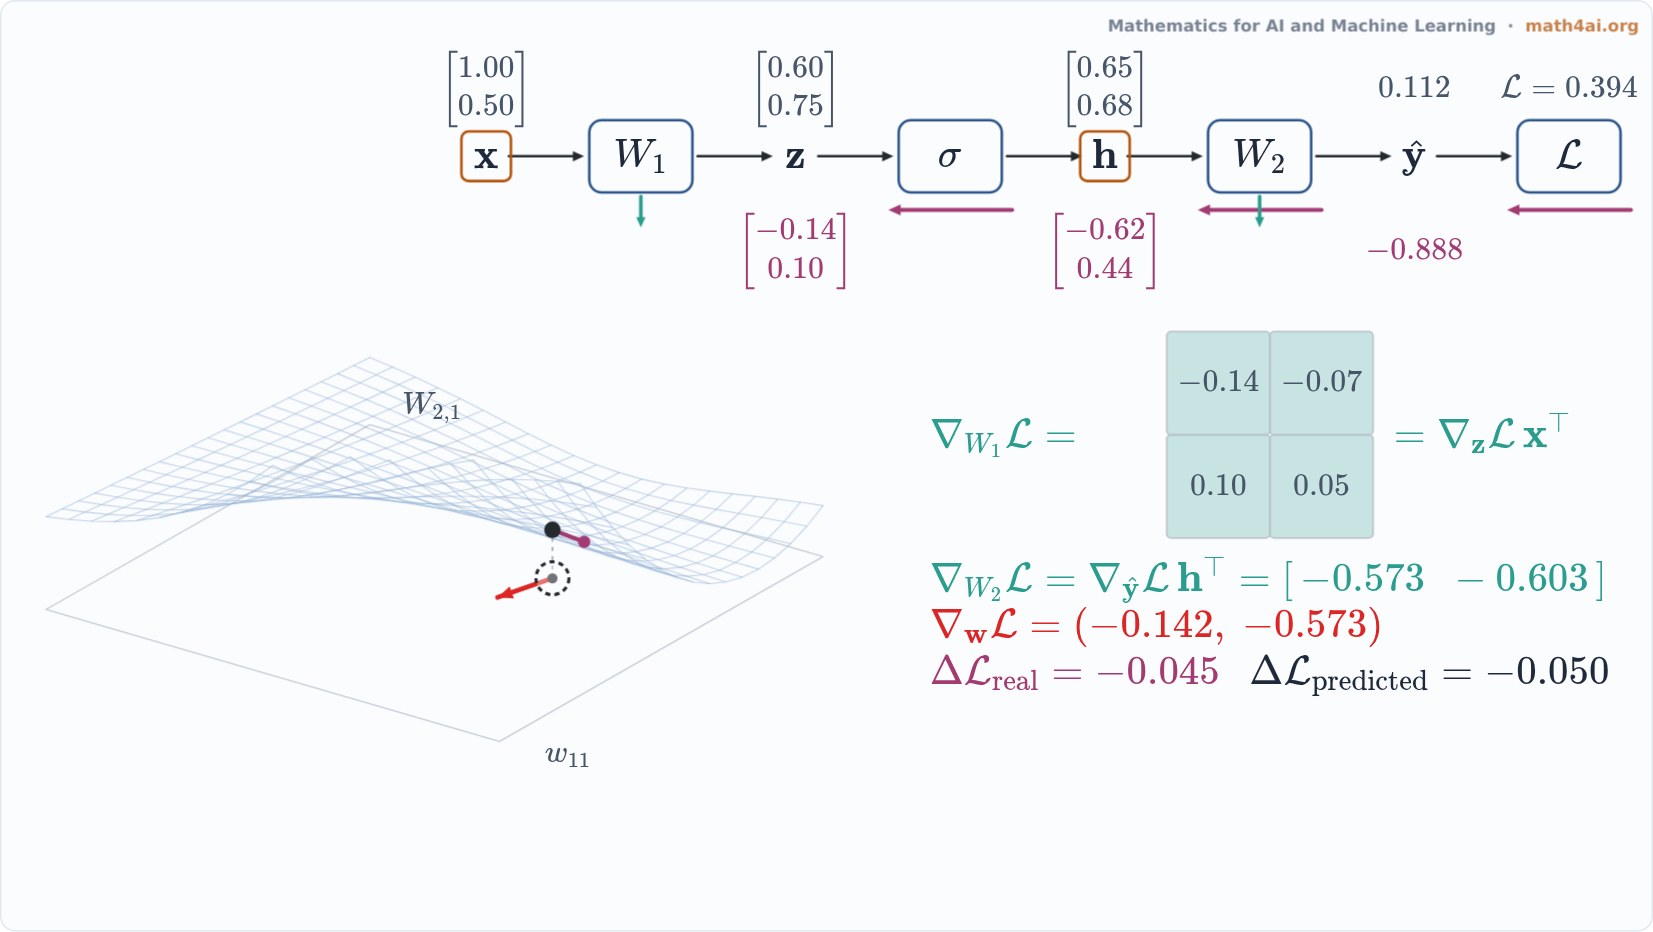 Interactive1:54Backpropagation, One VJP per LayerChapter 11
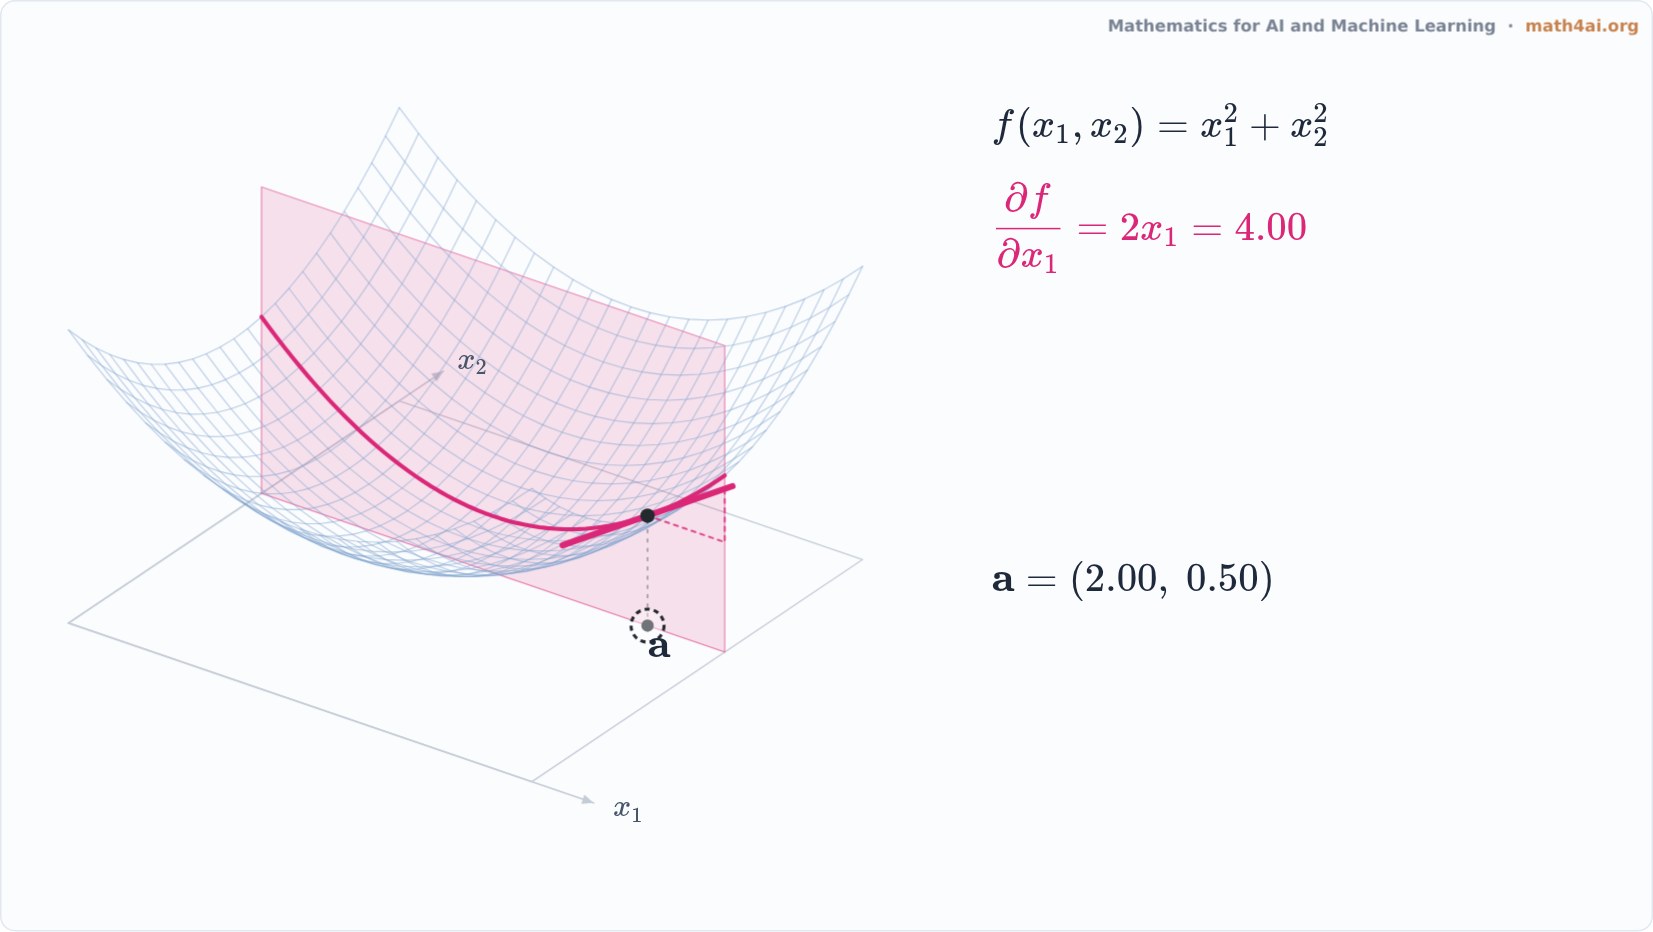 Preview1:27Partial Derivatives Are Two SlicesChapter 11
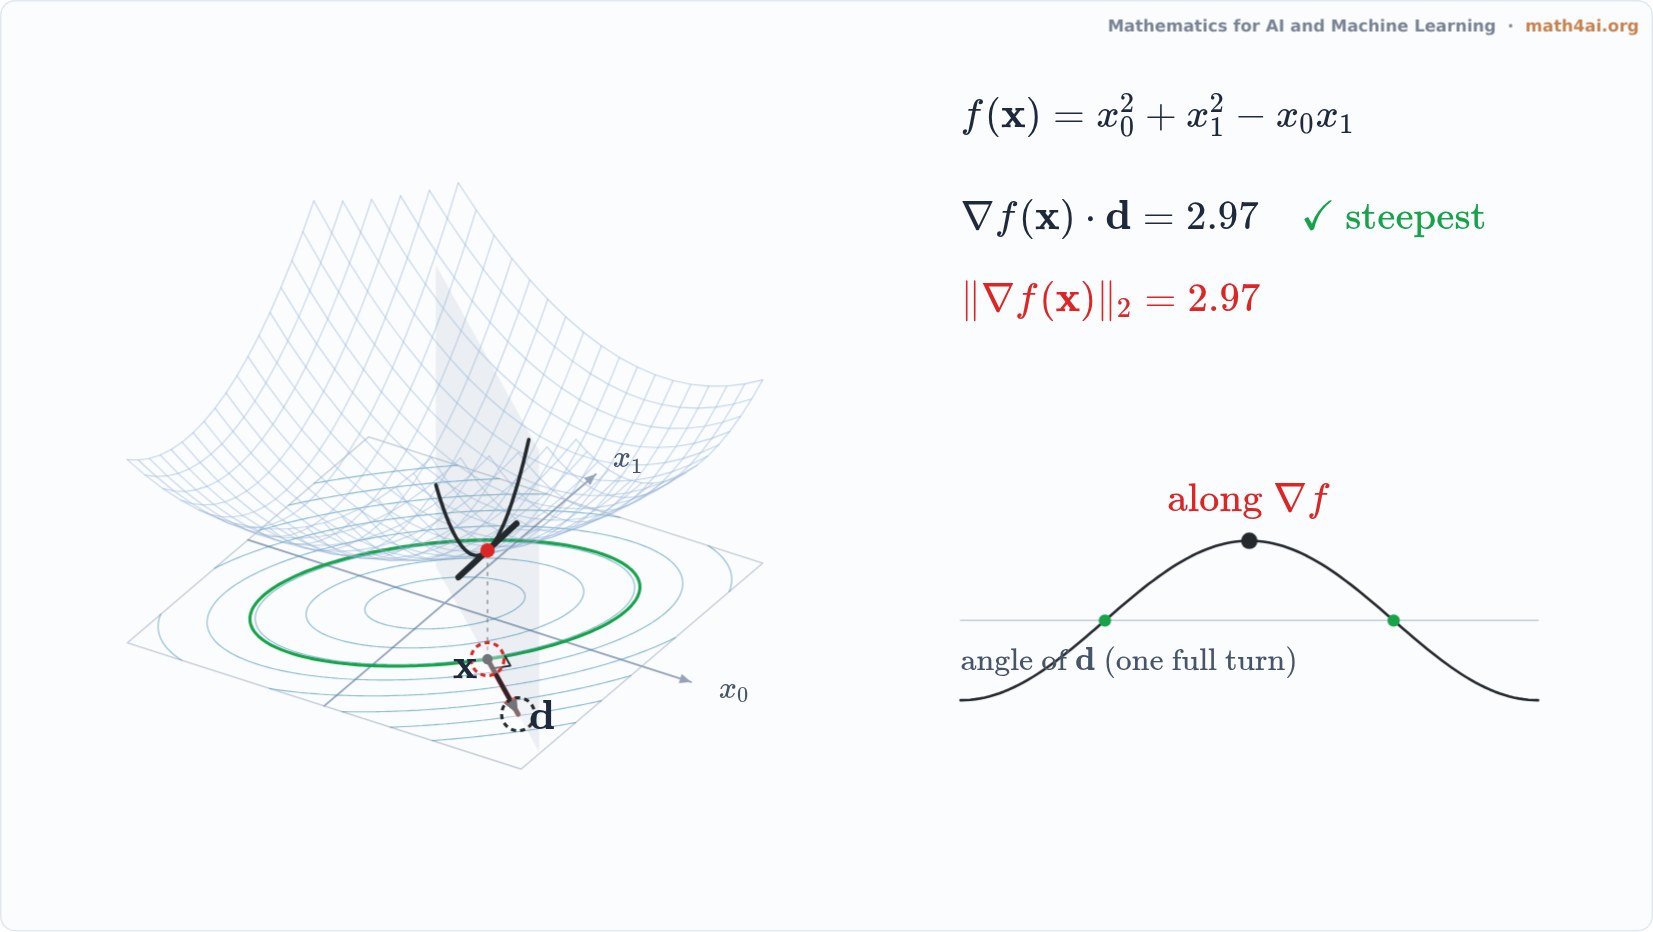 Preview1:34The Gradient Is the Steepest DirectionChapter 11
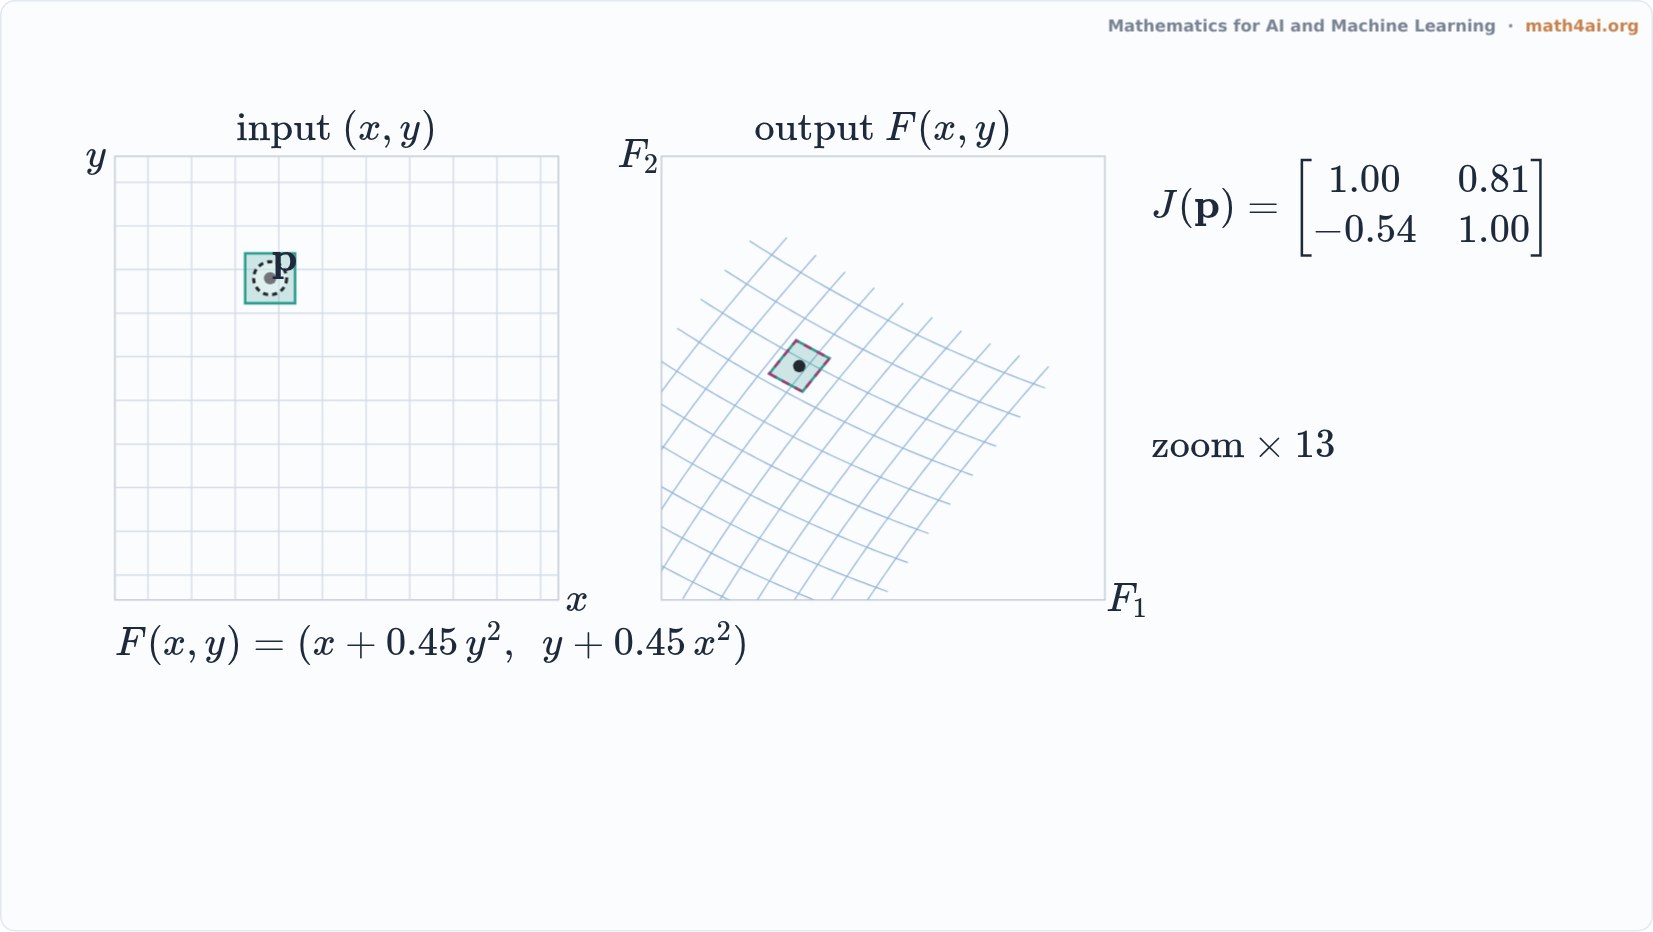 Preview1:42Jacobian Matrix: Linearizing a MapChapter 11
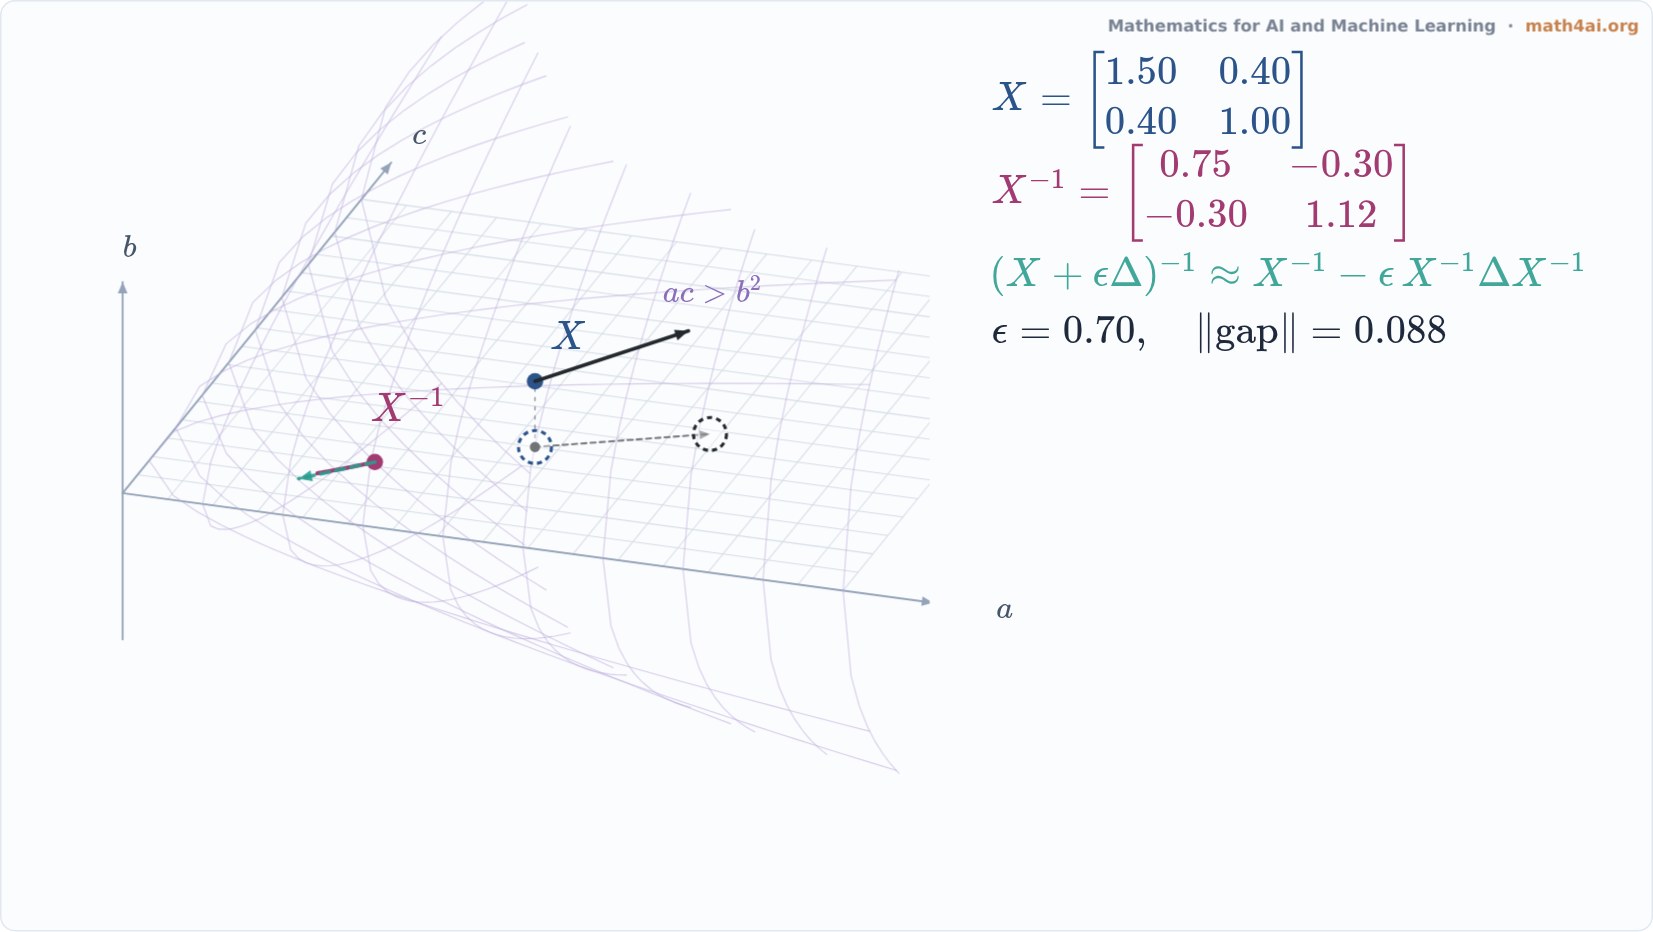 Preview1:43The Derivative of the Matrix InverseChapter 11
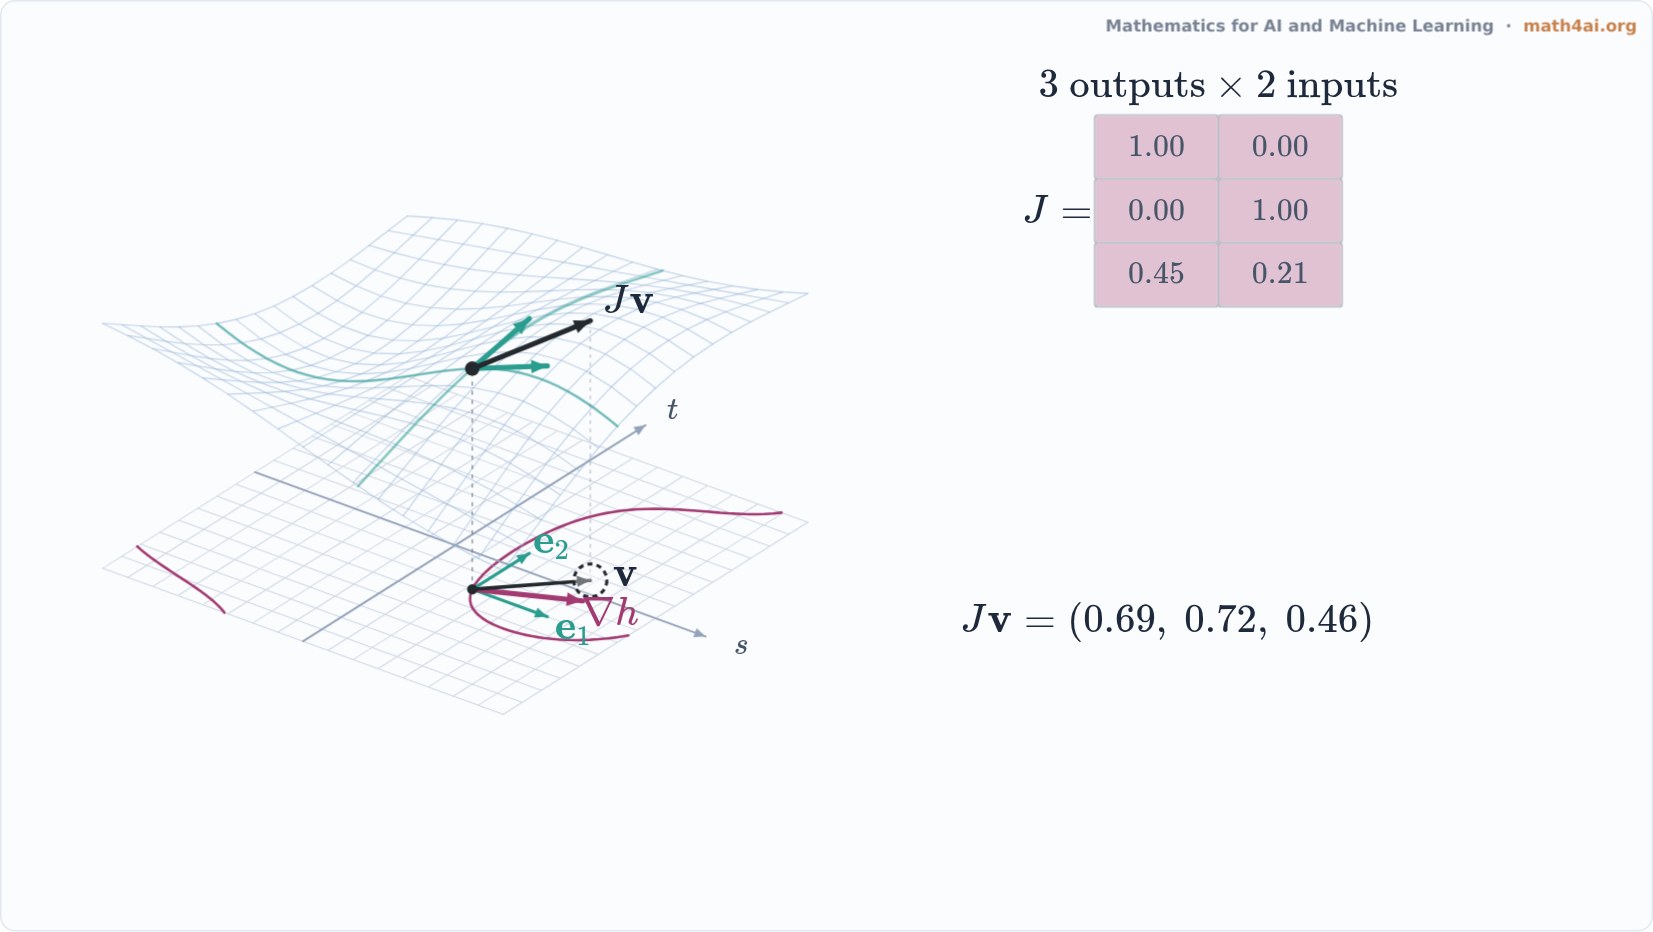 Preview1:54Forward or Reverse: Filling the JacobianChapter 11
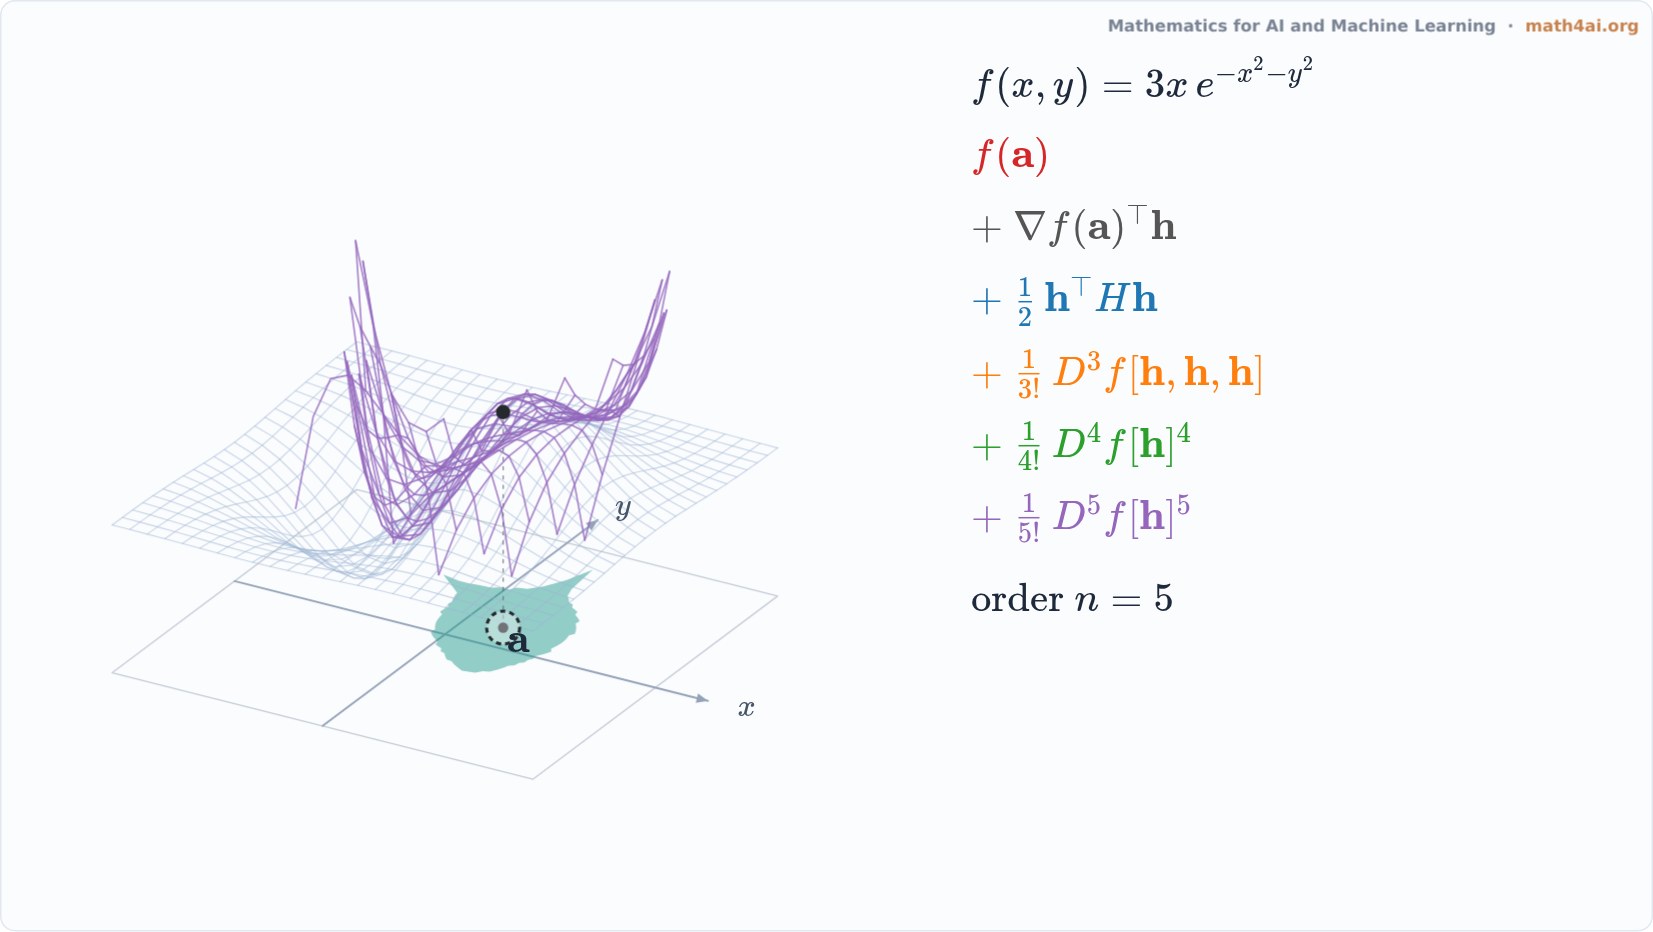 Preview1:32Taylor Expansion, One Term at a TimeChapter 11
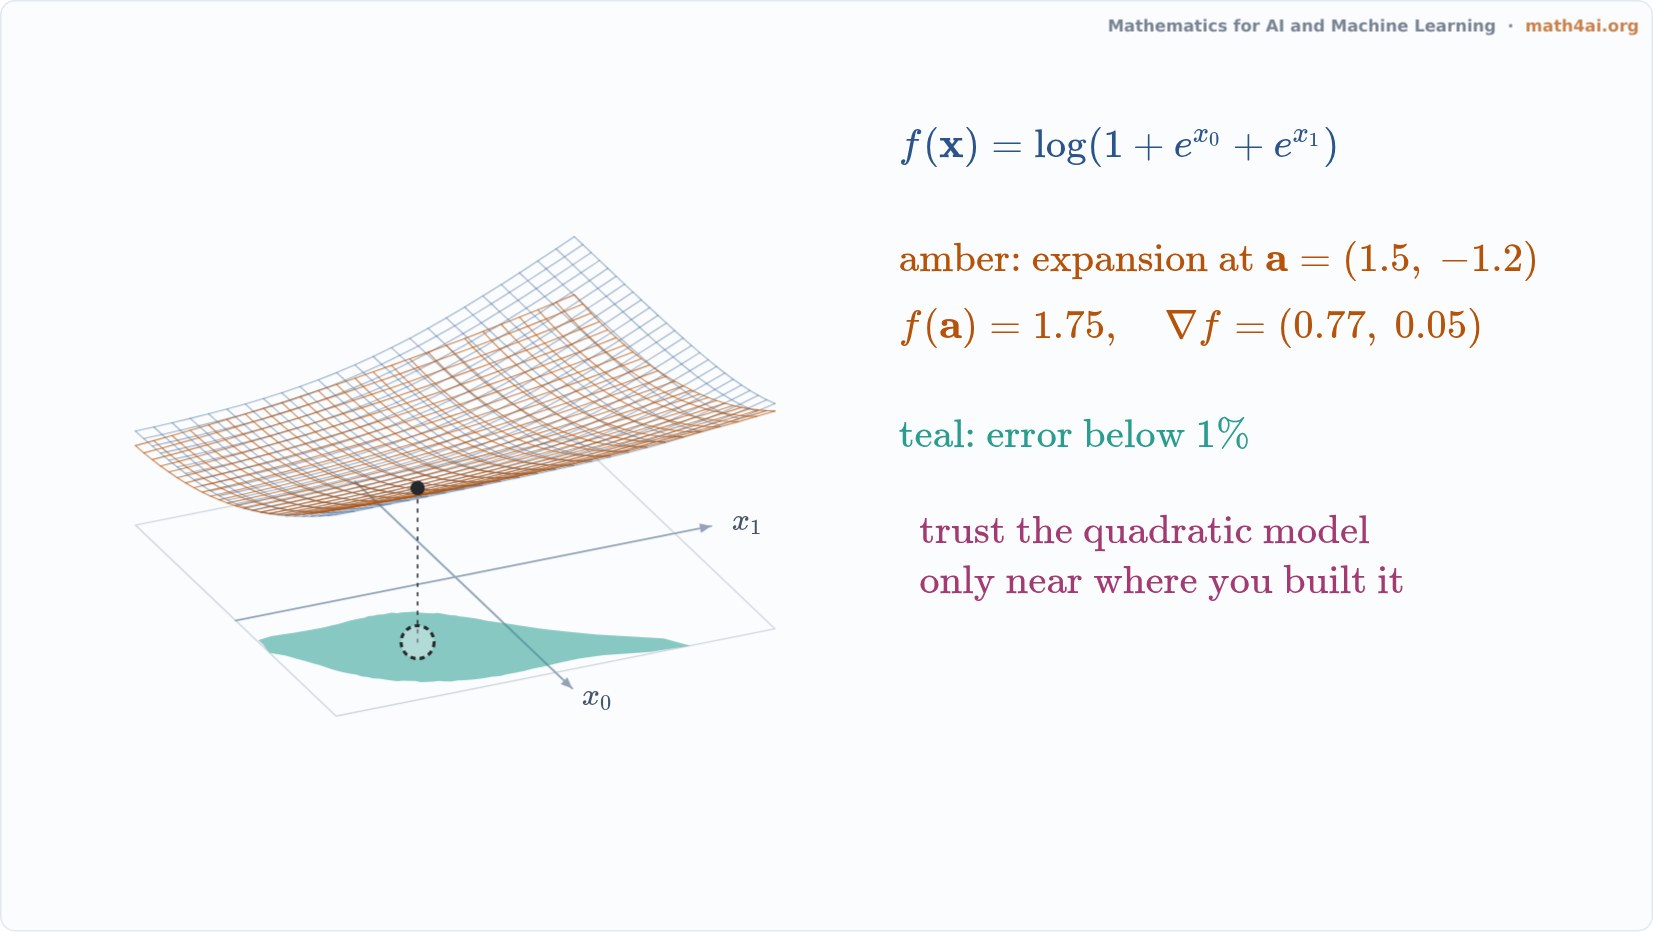 Preview1:30Second-Order Taylor: Where the Quadratic Model Can Be TrustedChapter 11
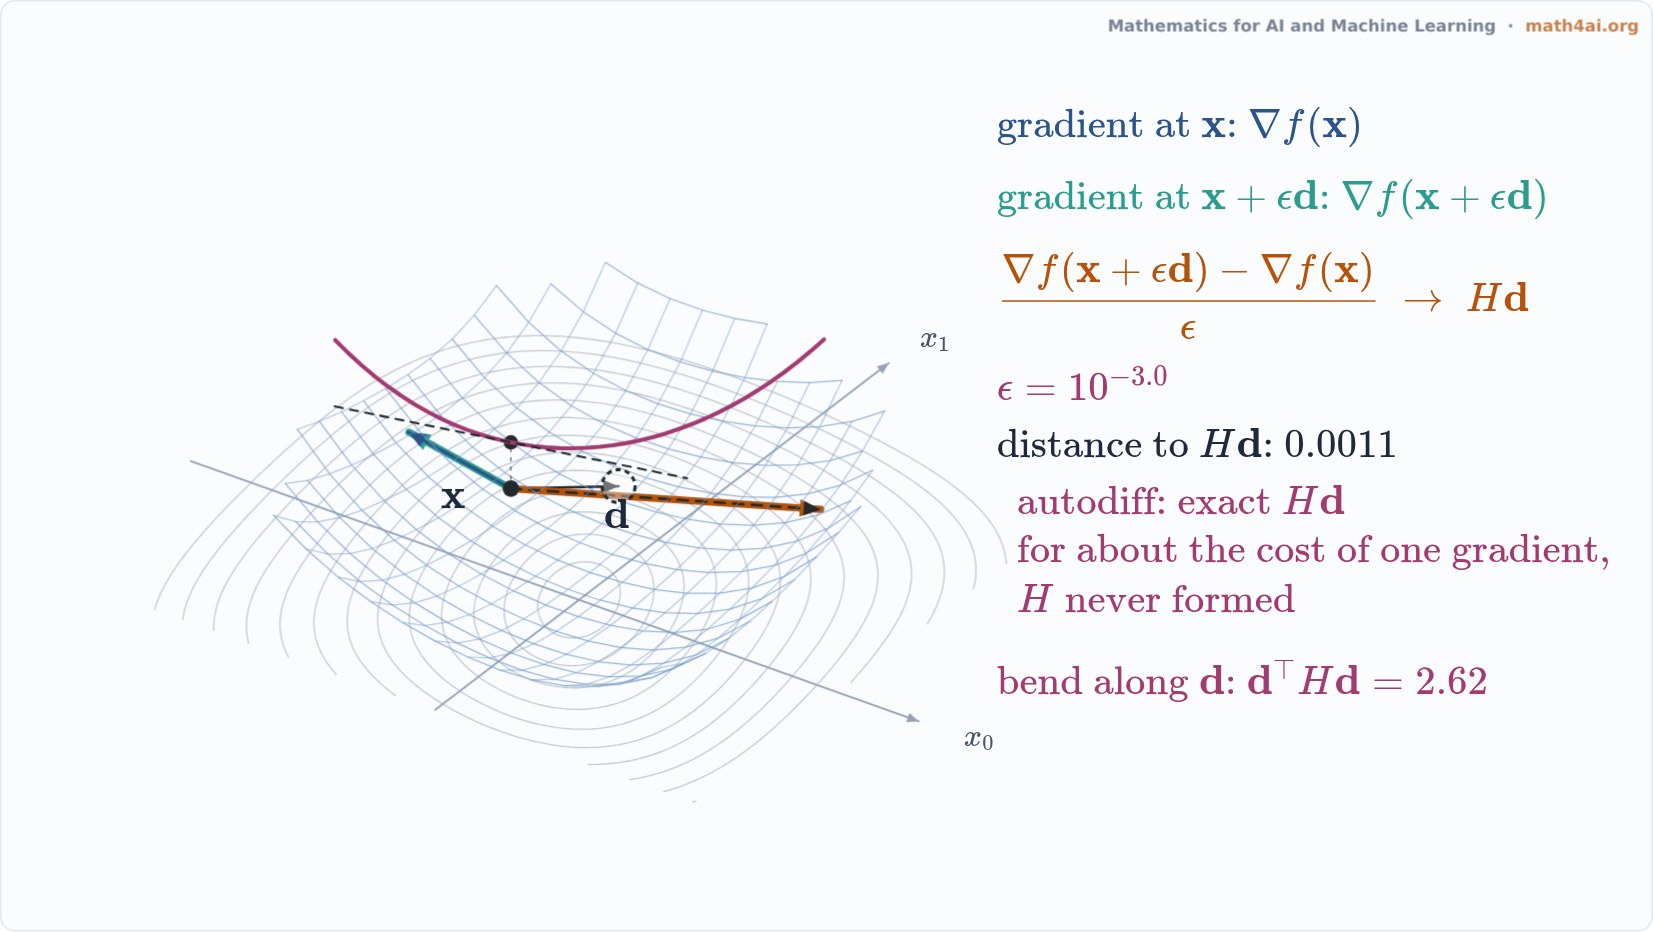 Preview1:38A Hessian-Vector Product from Two GradientsChapter 11
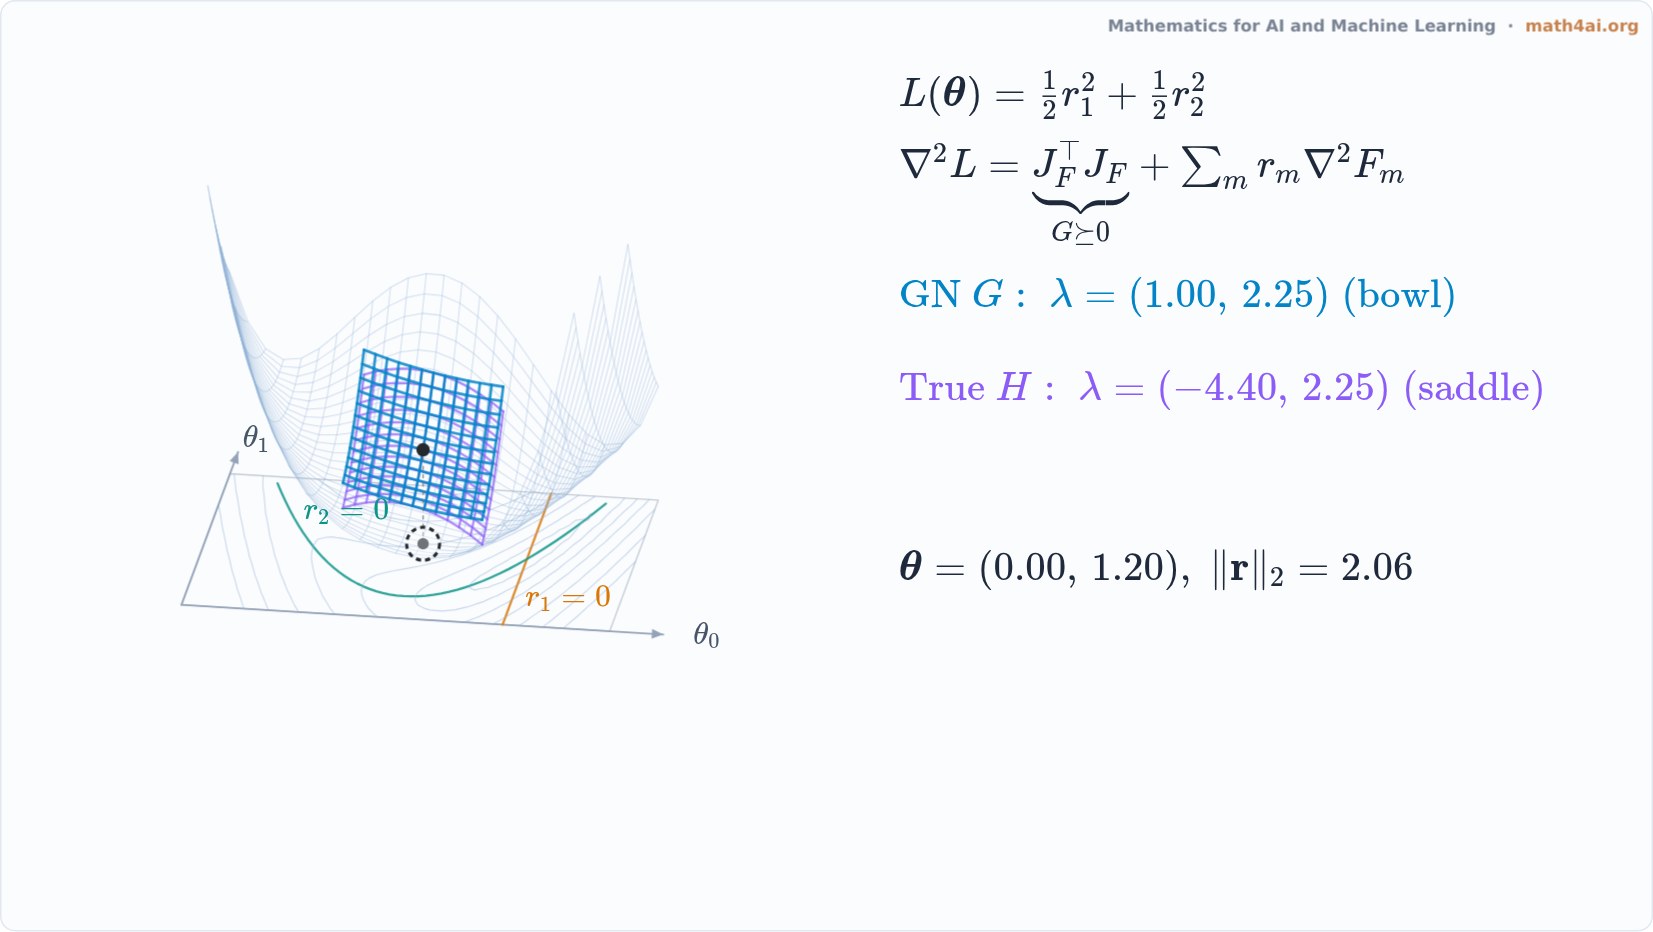 Preview1:34The Gauss–Newton MatrixChapter 11
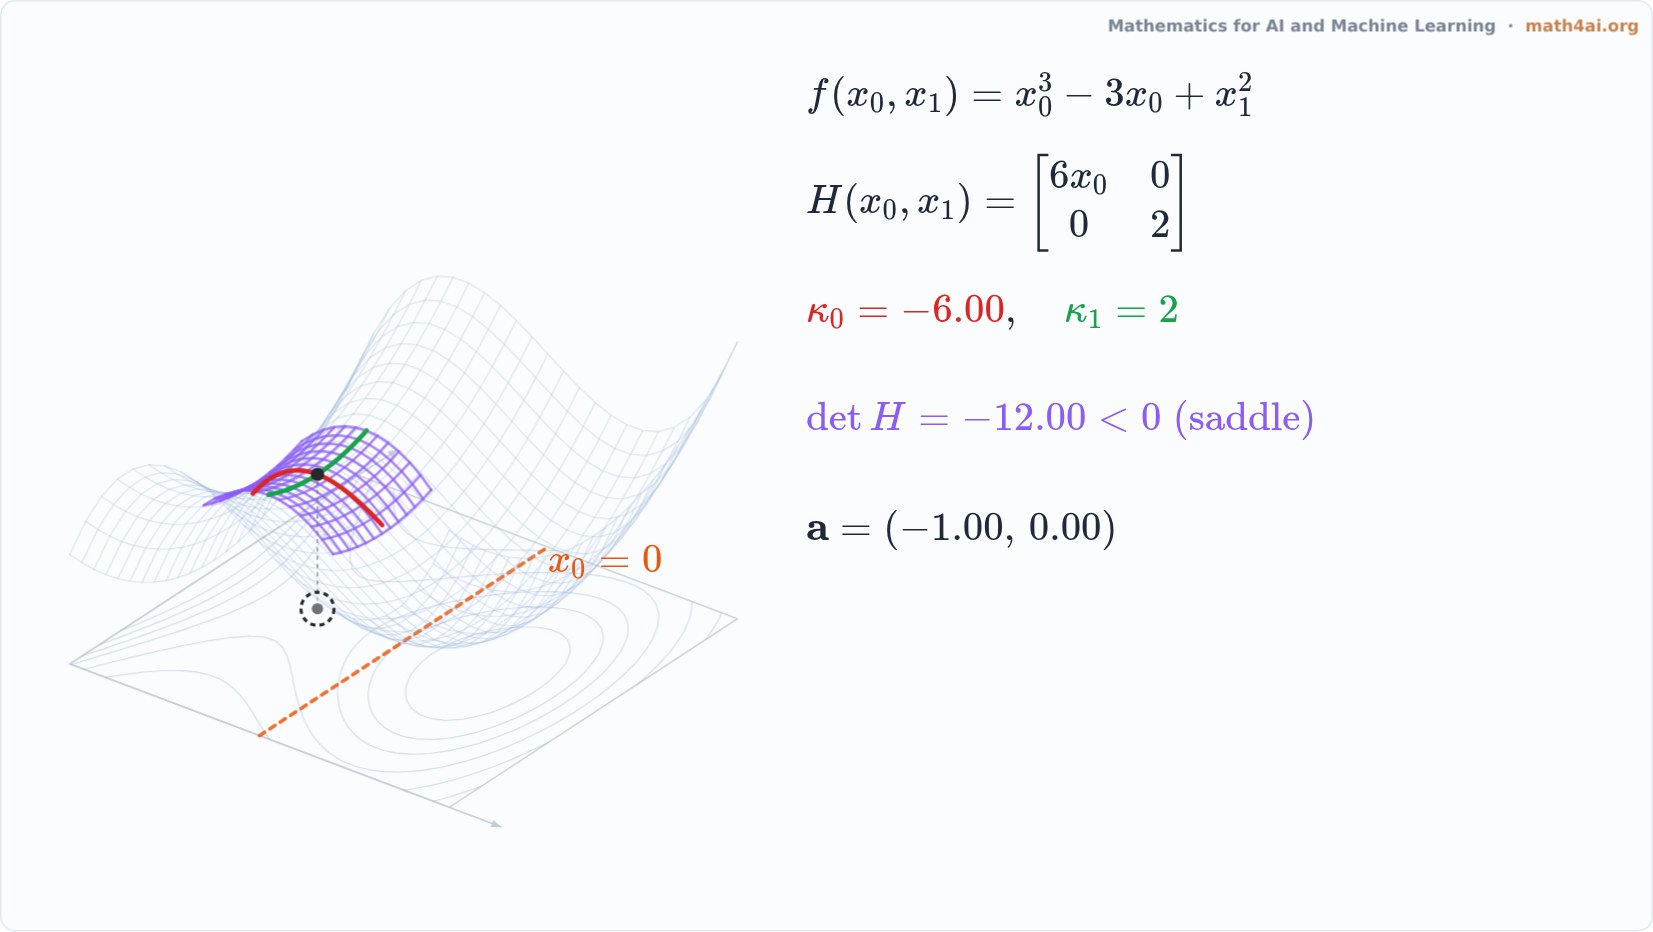 Preview1:44Hessian Matrix: Bowls, Saddles and Curvature DirectionsChapter 11
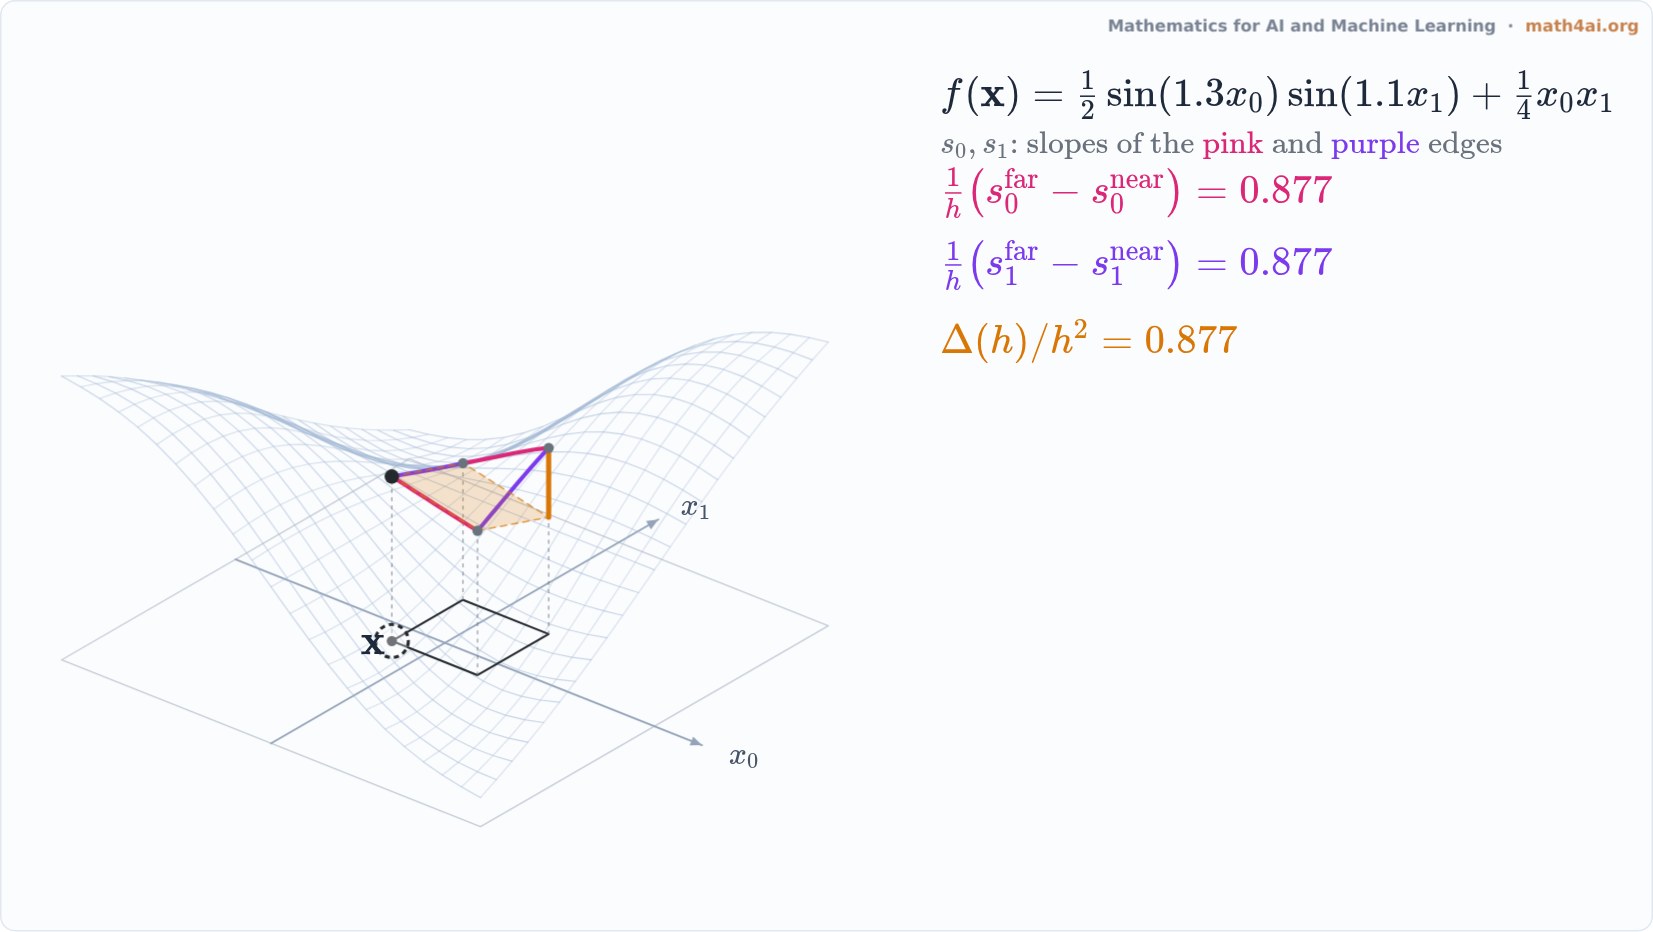 Preview1:37Why the Hessian Is SymmetricChapter 11
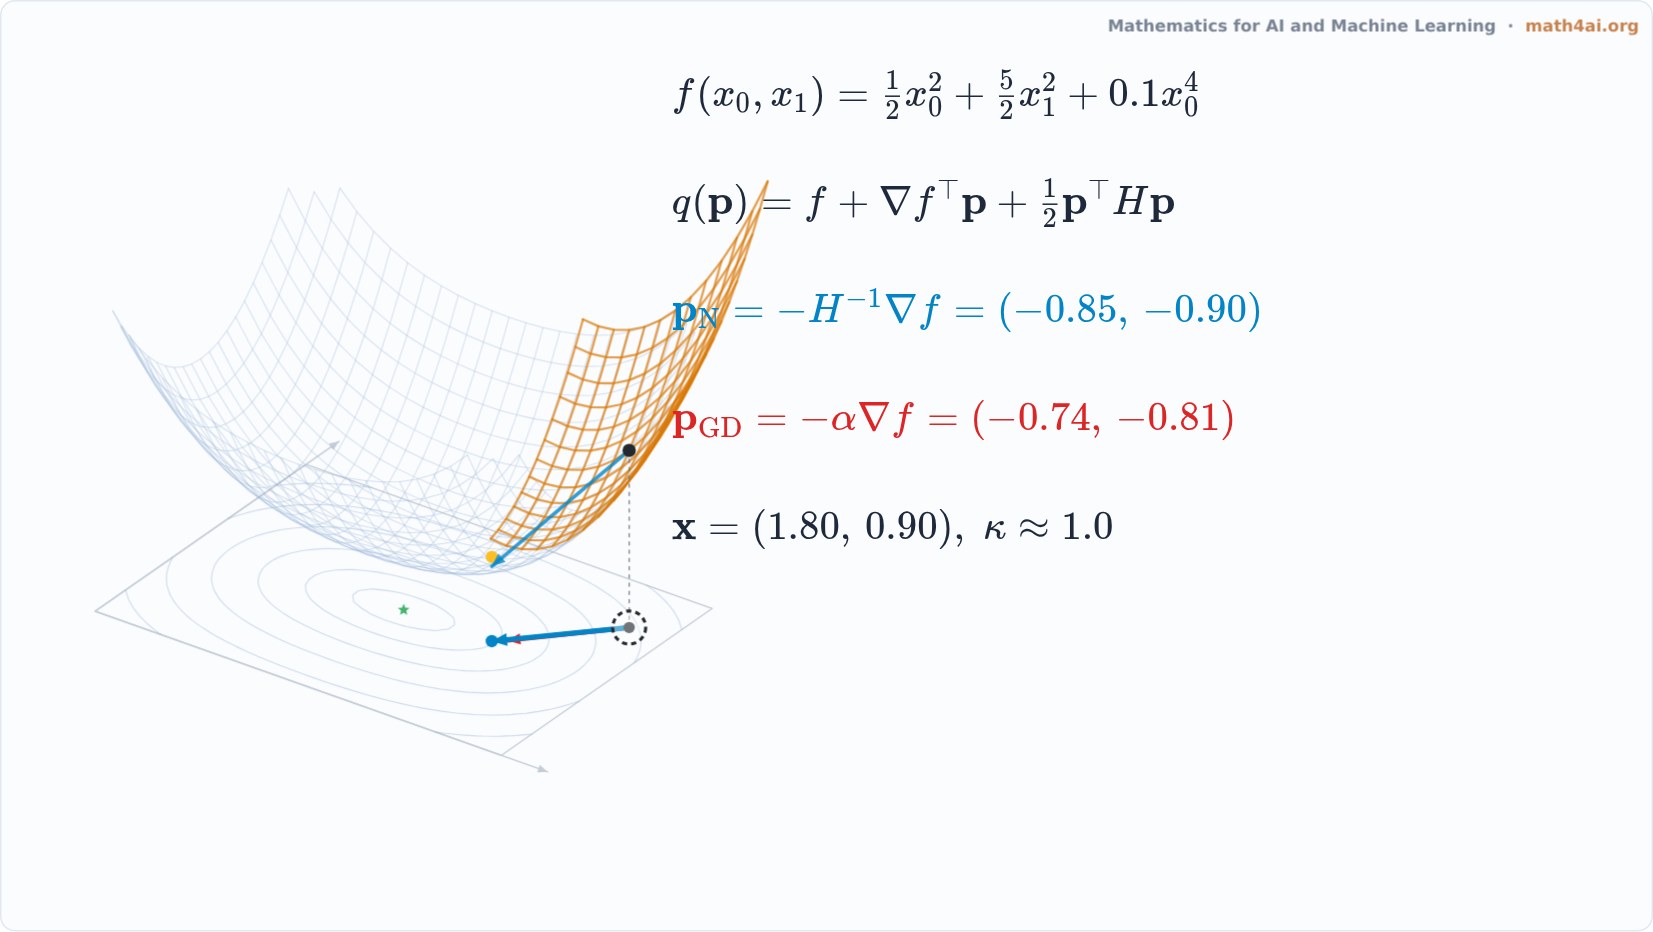 Preview1:26The Newton Step: Jumping to the Taylor Bowl's BottomChapter 11
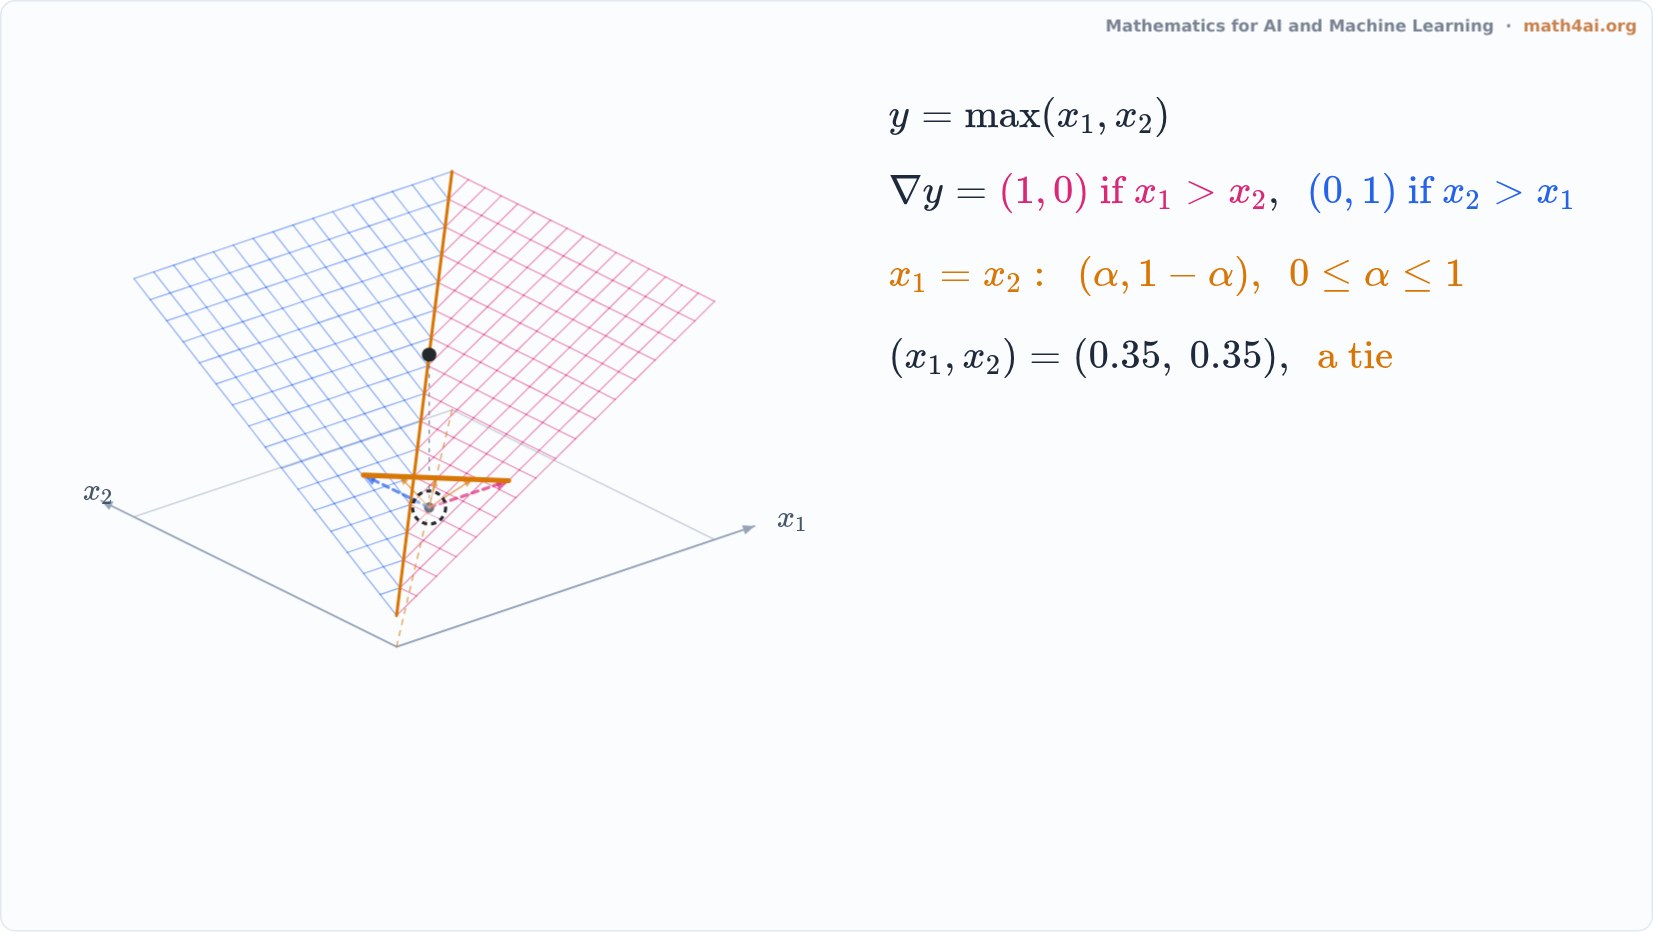 Preview2:36Corners, Maxima and Steps in the Chain RuleChapter 11
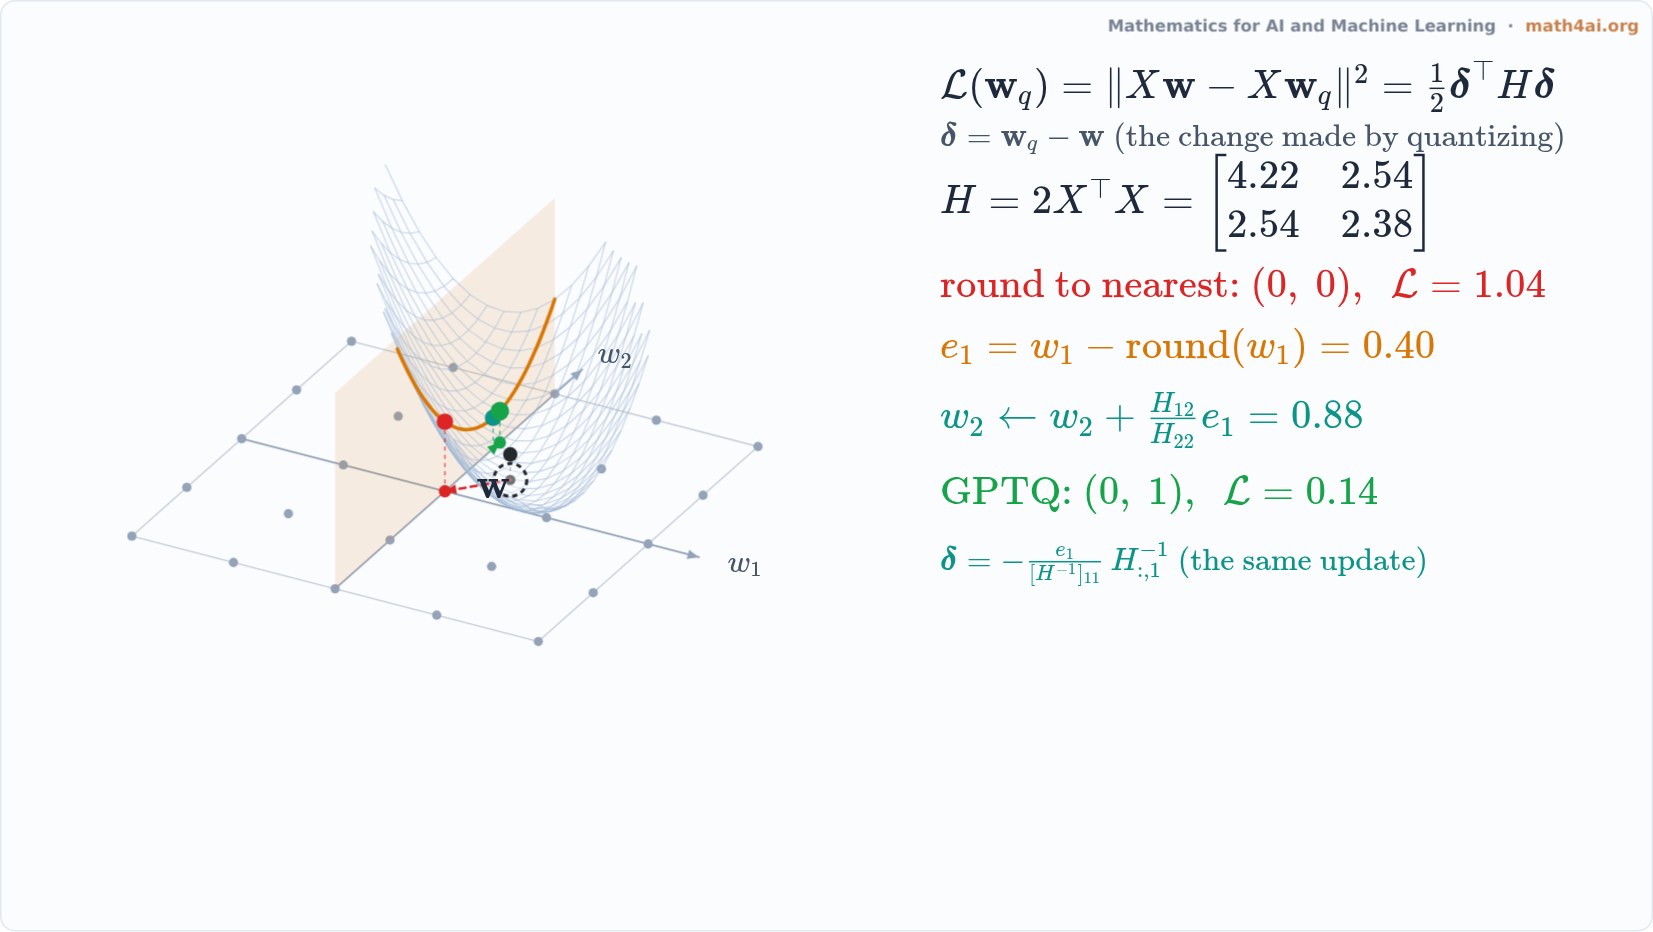 Preview1:59GPTQ: Rounding with the HessianChapter 11
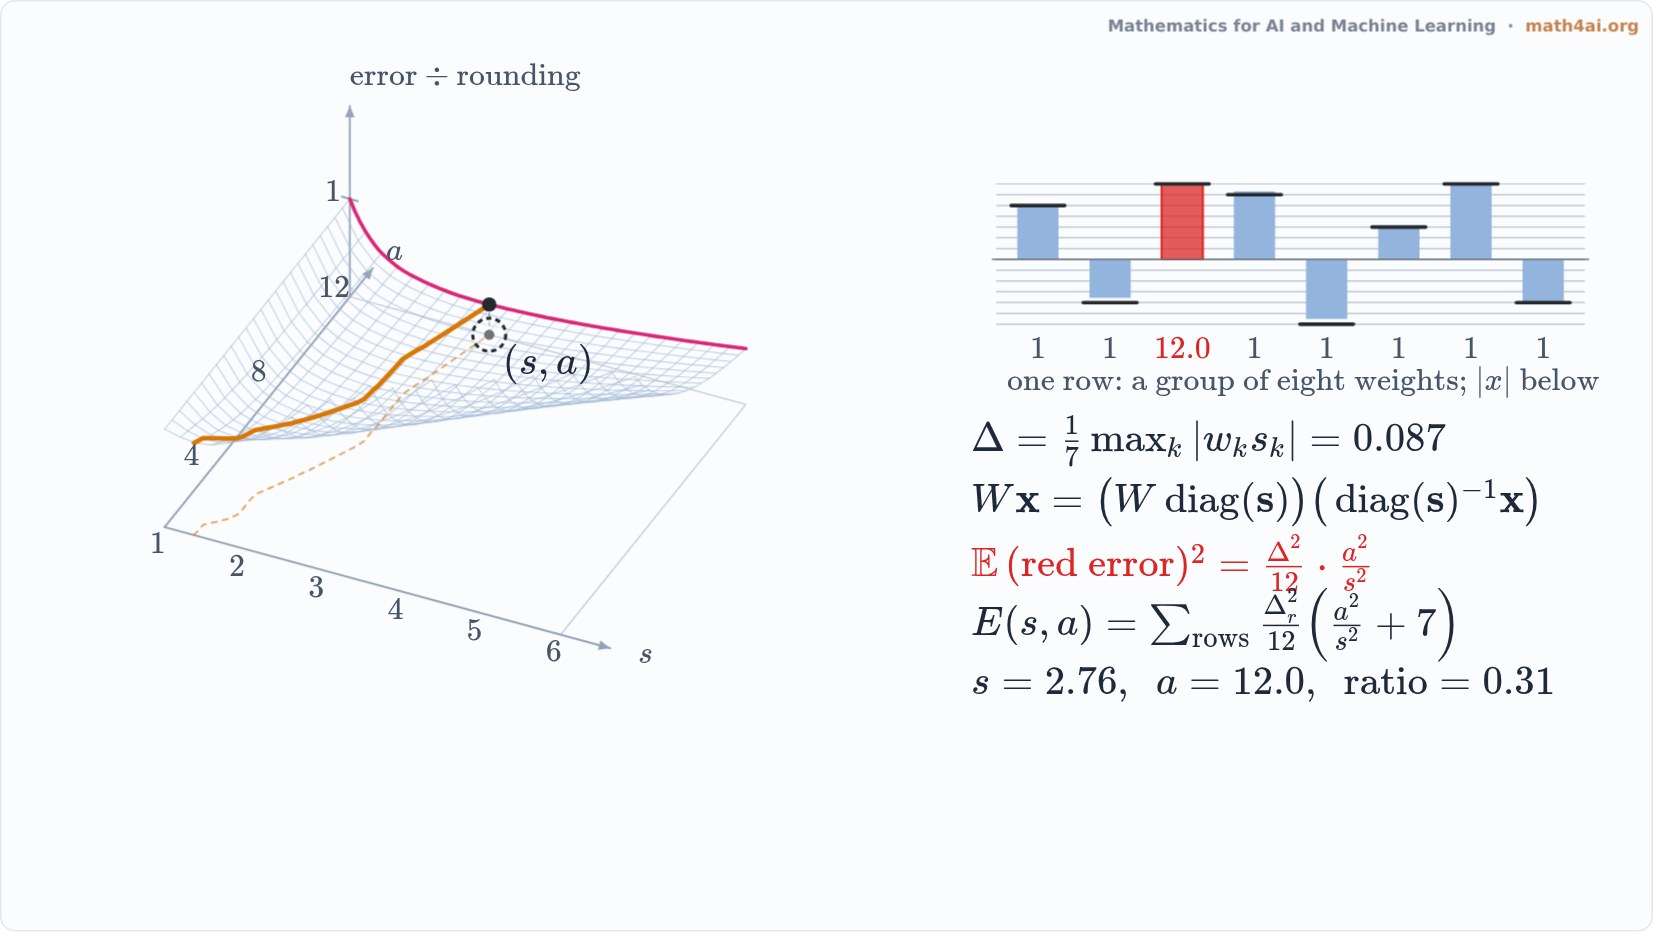 Preview2:12AWQ: Activation-Aware Weight QuantizationChapter 11
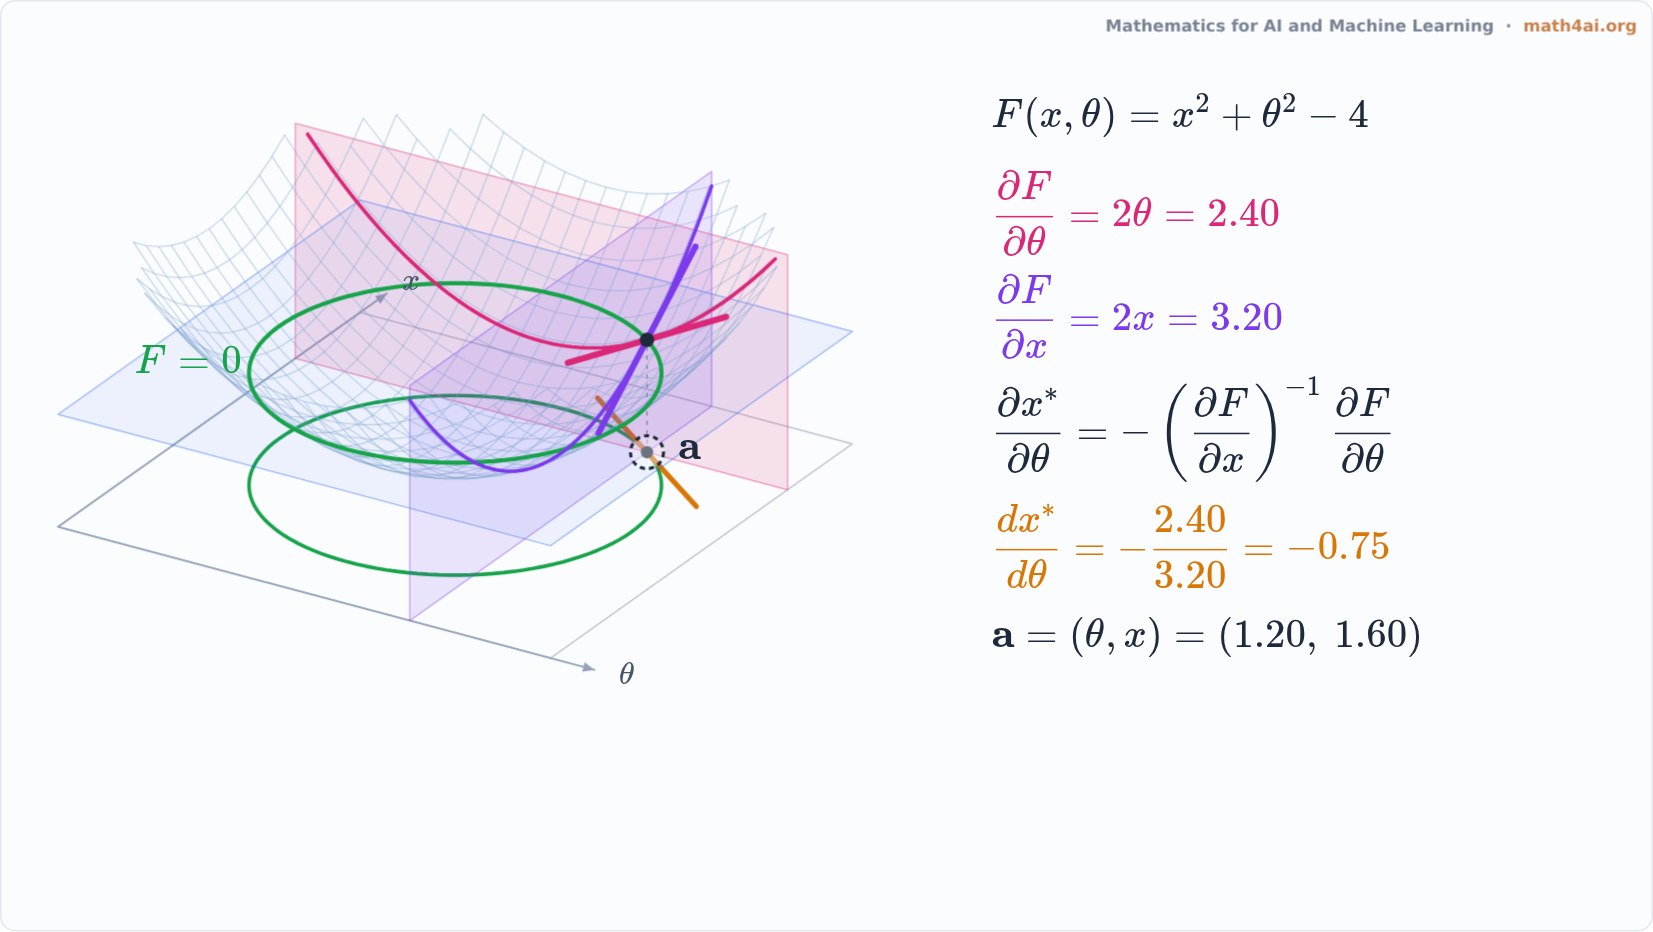 Preview1:41The Implicit Function TheoremChapter 11
Chapter 12 Optimization Methods
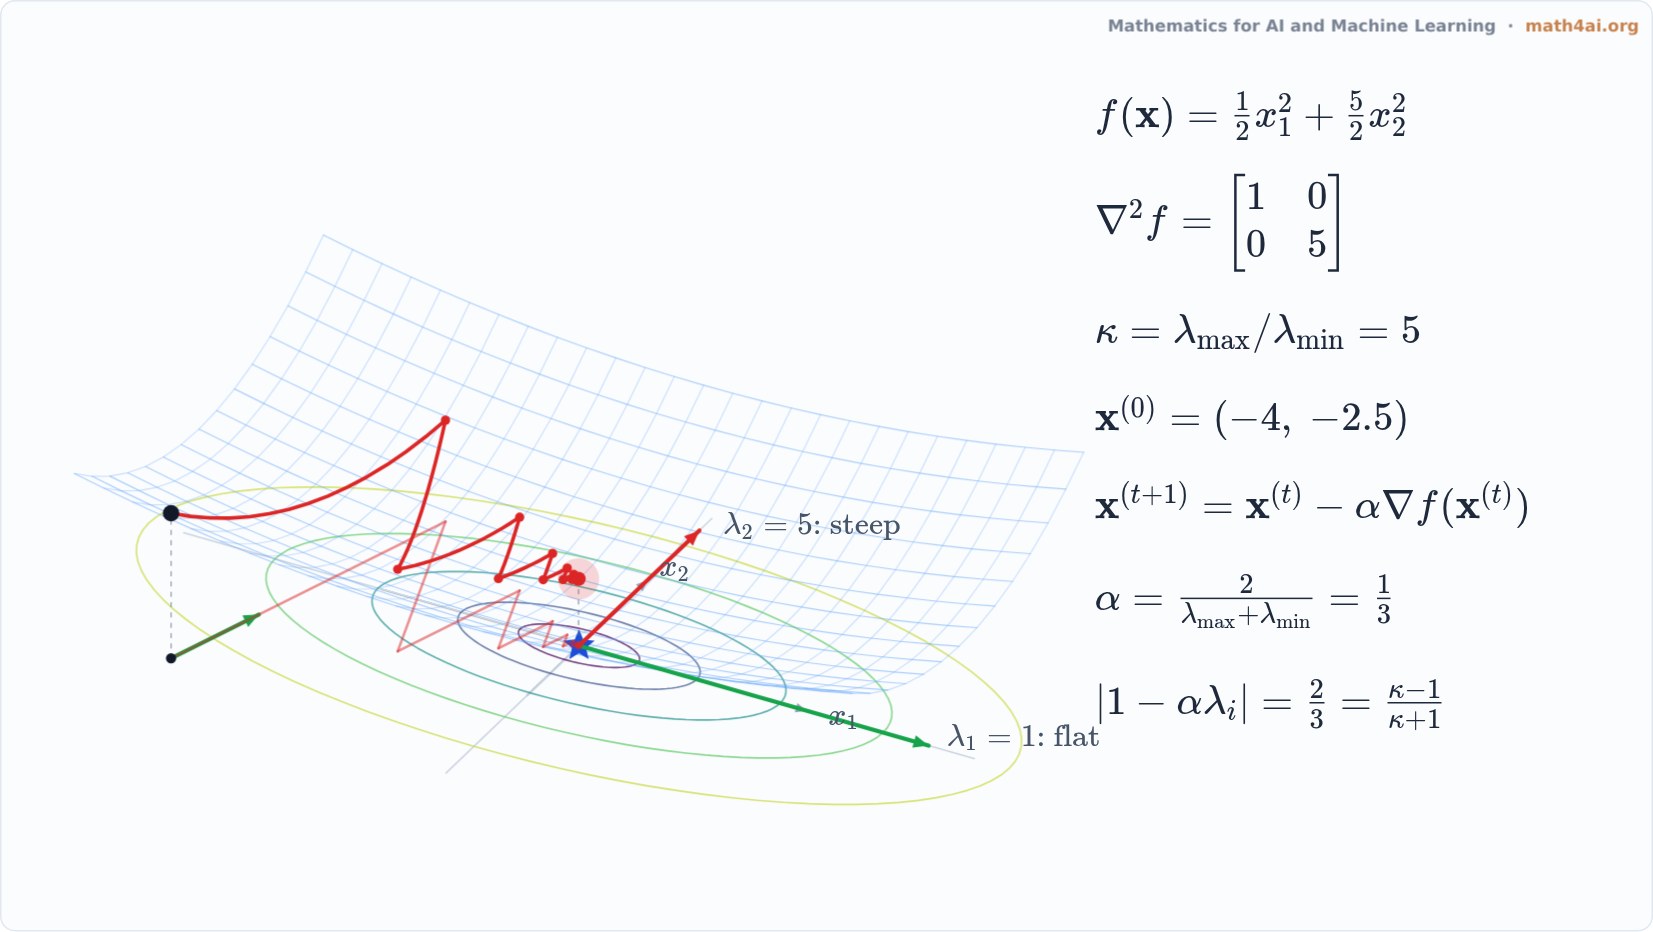 Interactive1:08Gradient Descent in an Ill-Conditioned ValleyChapter 12
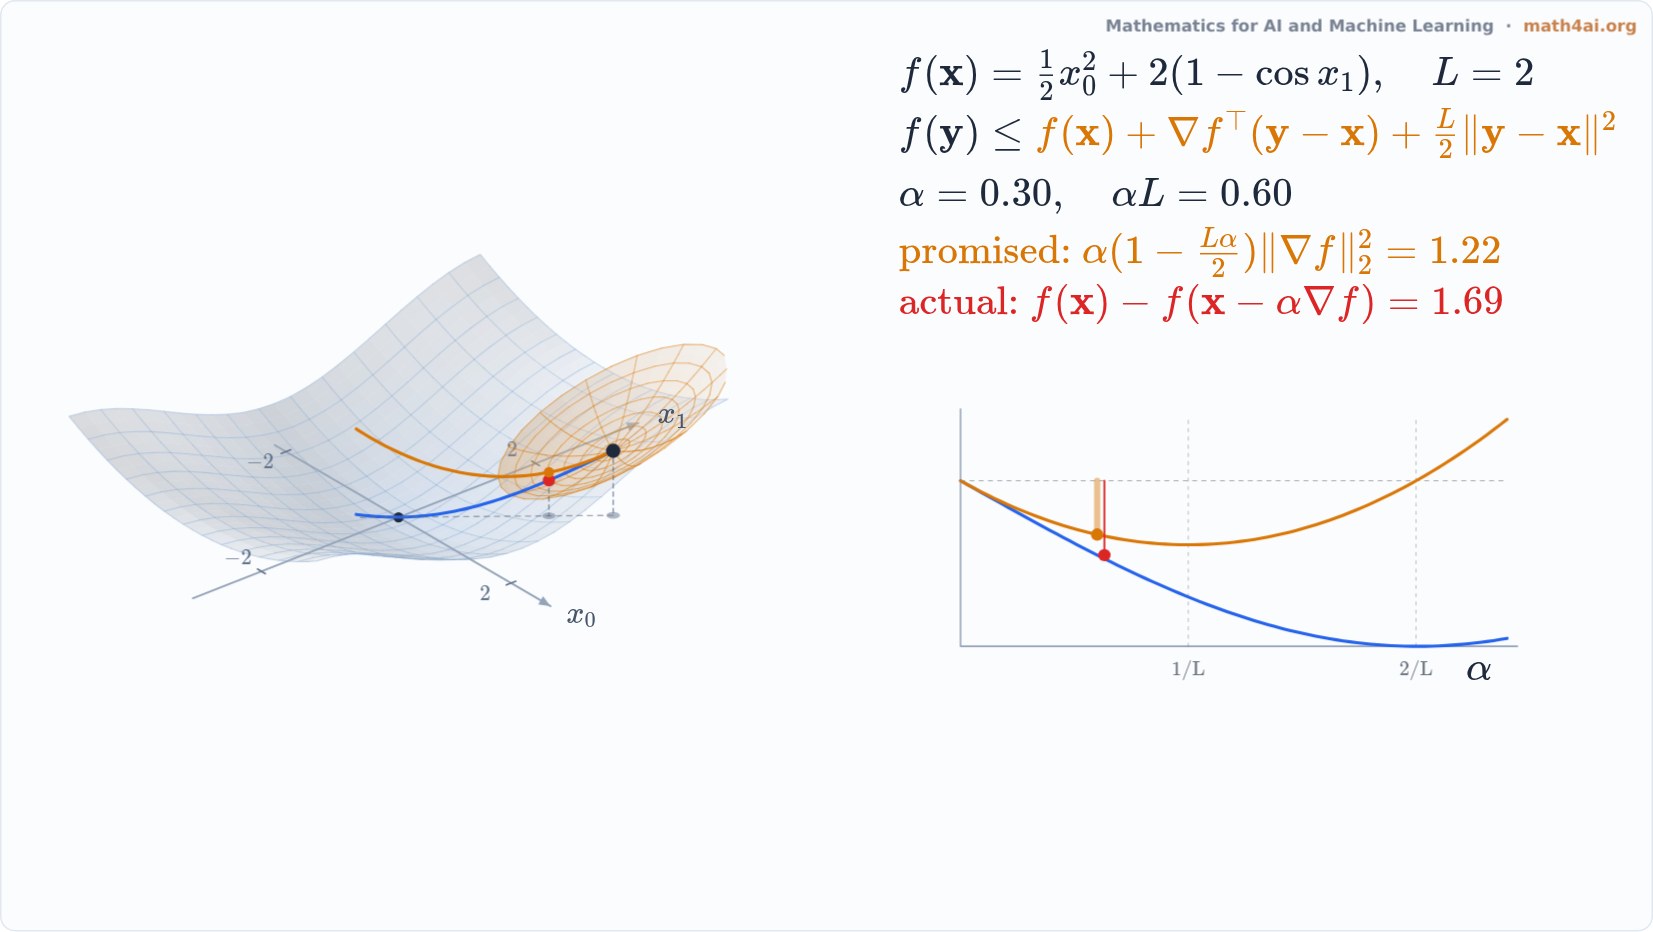 Preview1:28The Descent Lemma: A Bowl That Bounds Every StepChapter 12
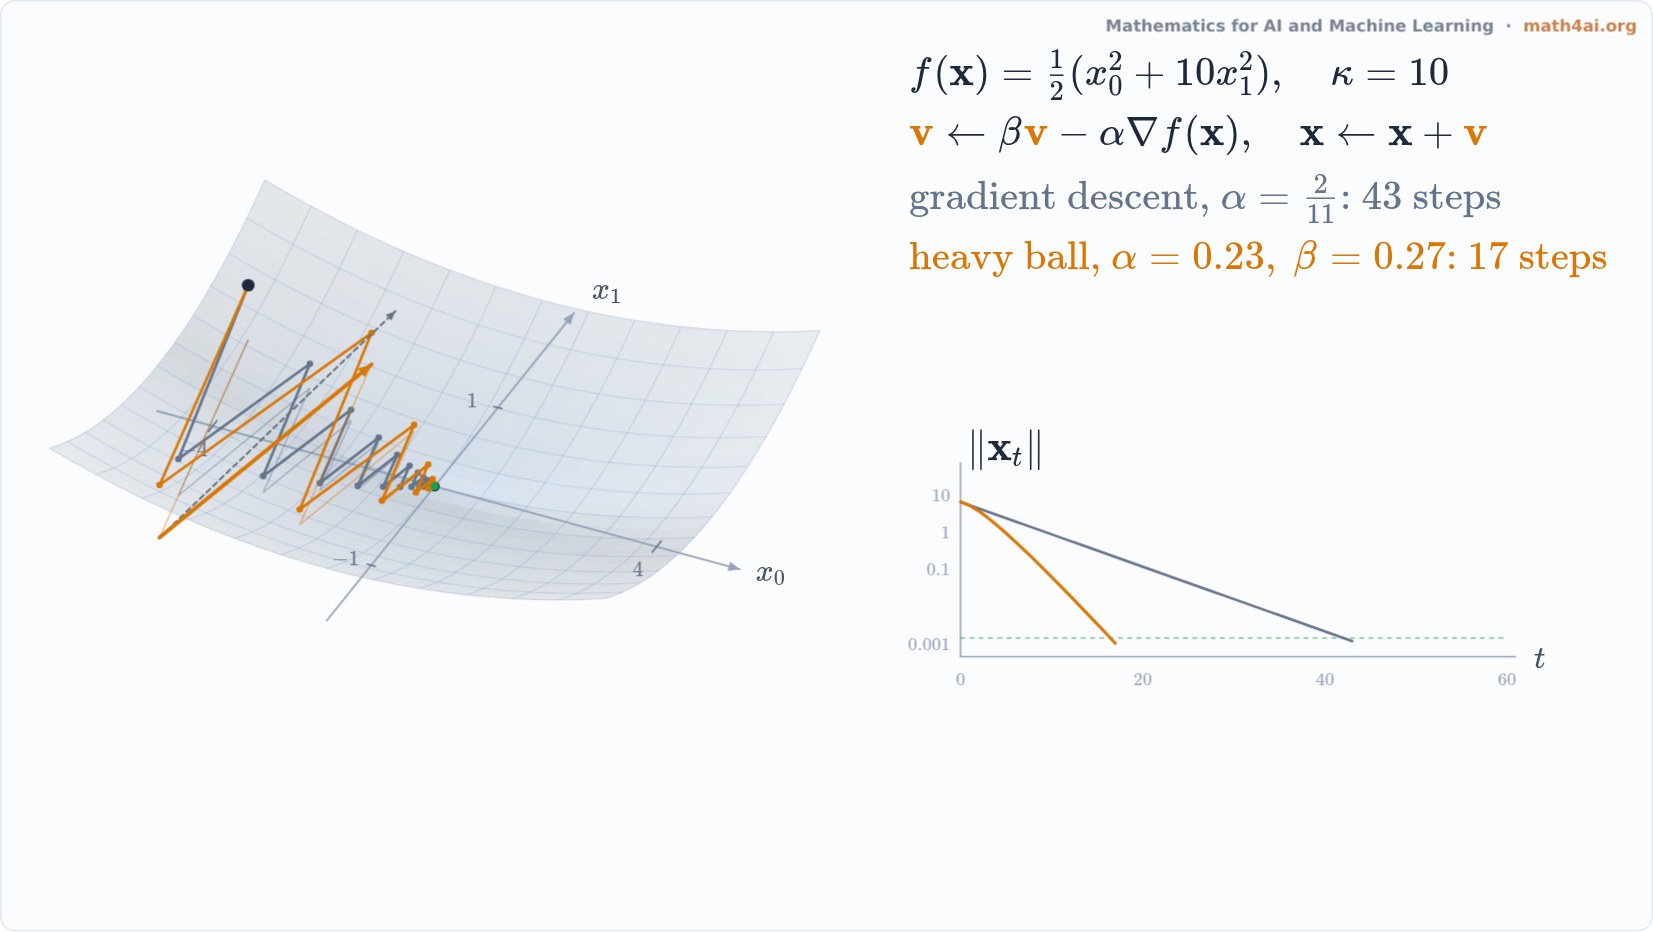 Preview1:33Heavy-Ball Momentum: Zig-Zags Cancel, the Valley Floor Adds UpChapter 12
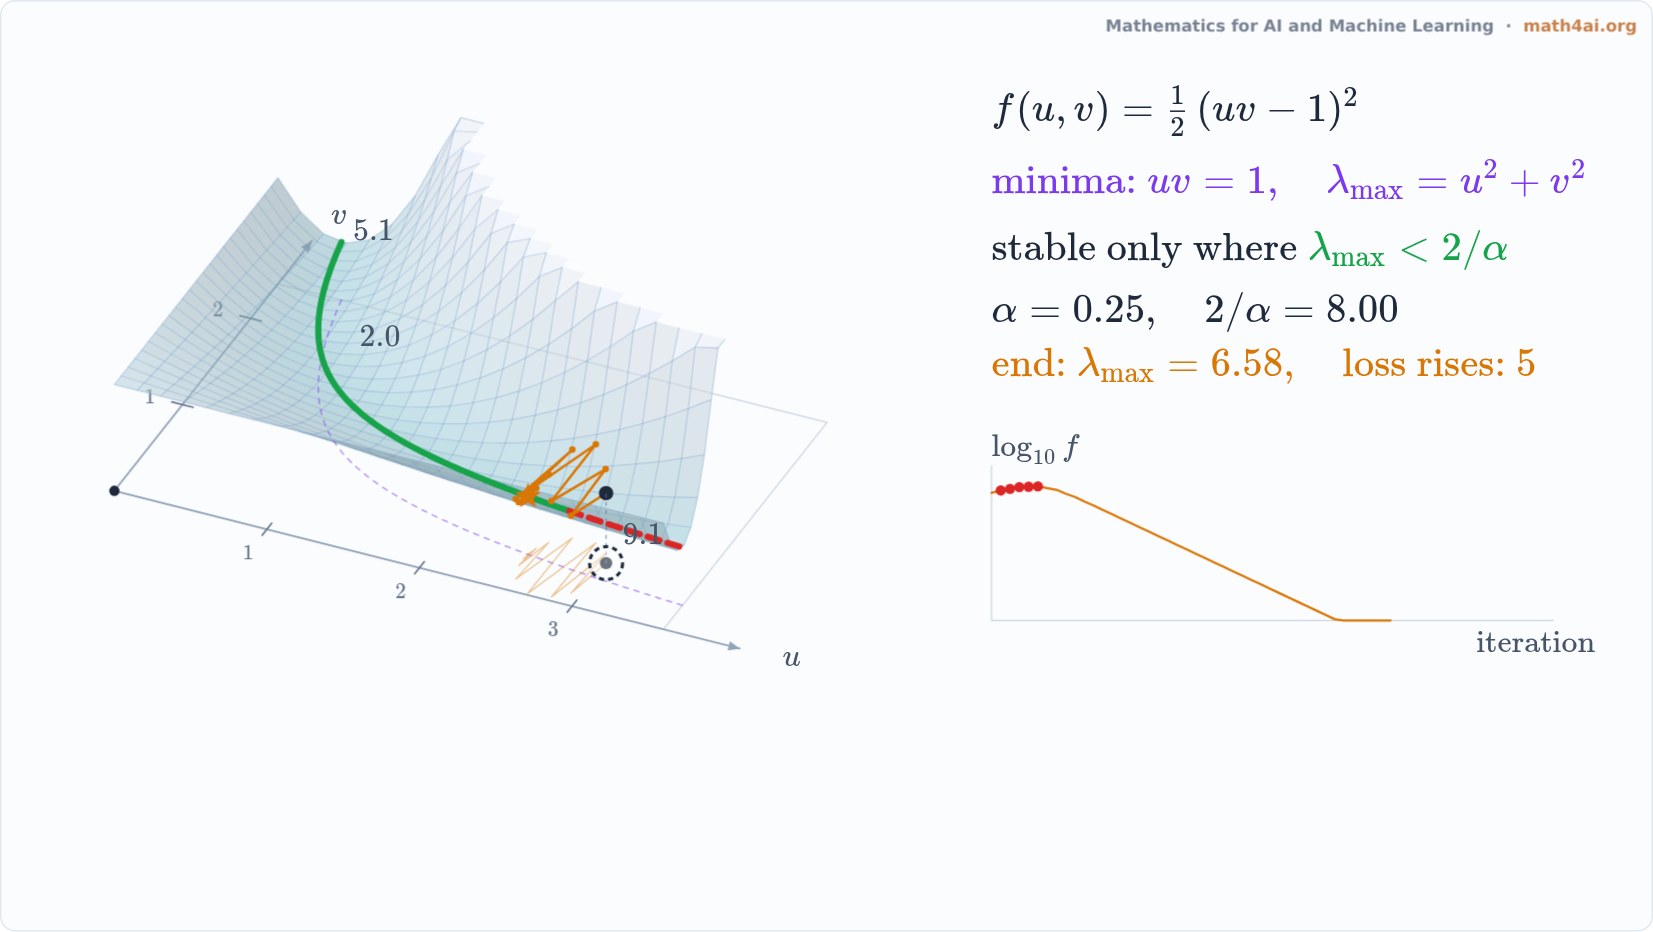 Preview1:43A Large Step Selects a Flatter MinimumChapter 12
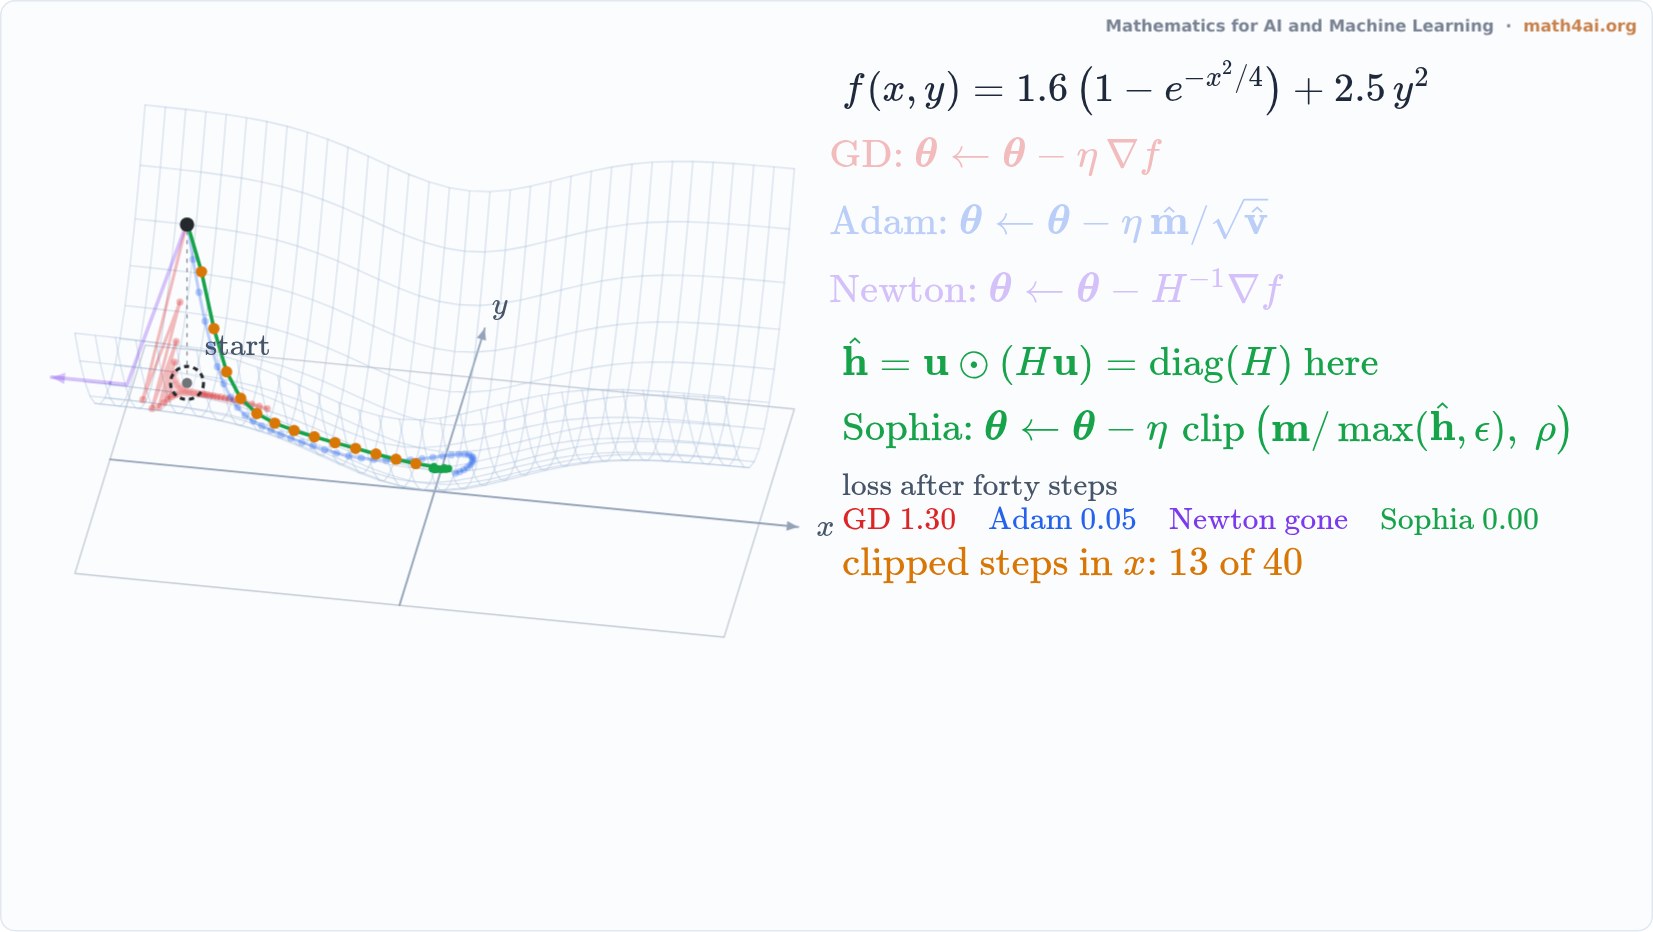 Preview2:12Sophia: Newton Steps with a ClipChapter 12
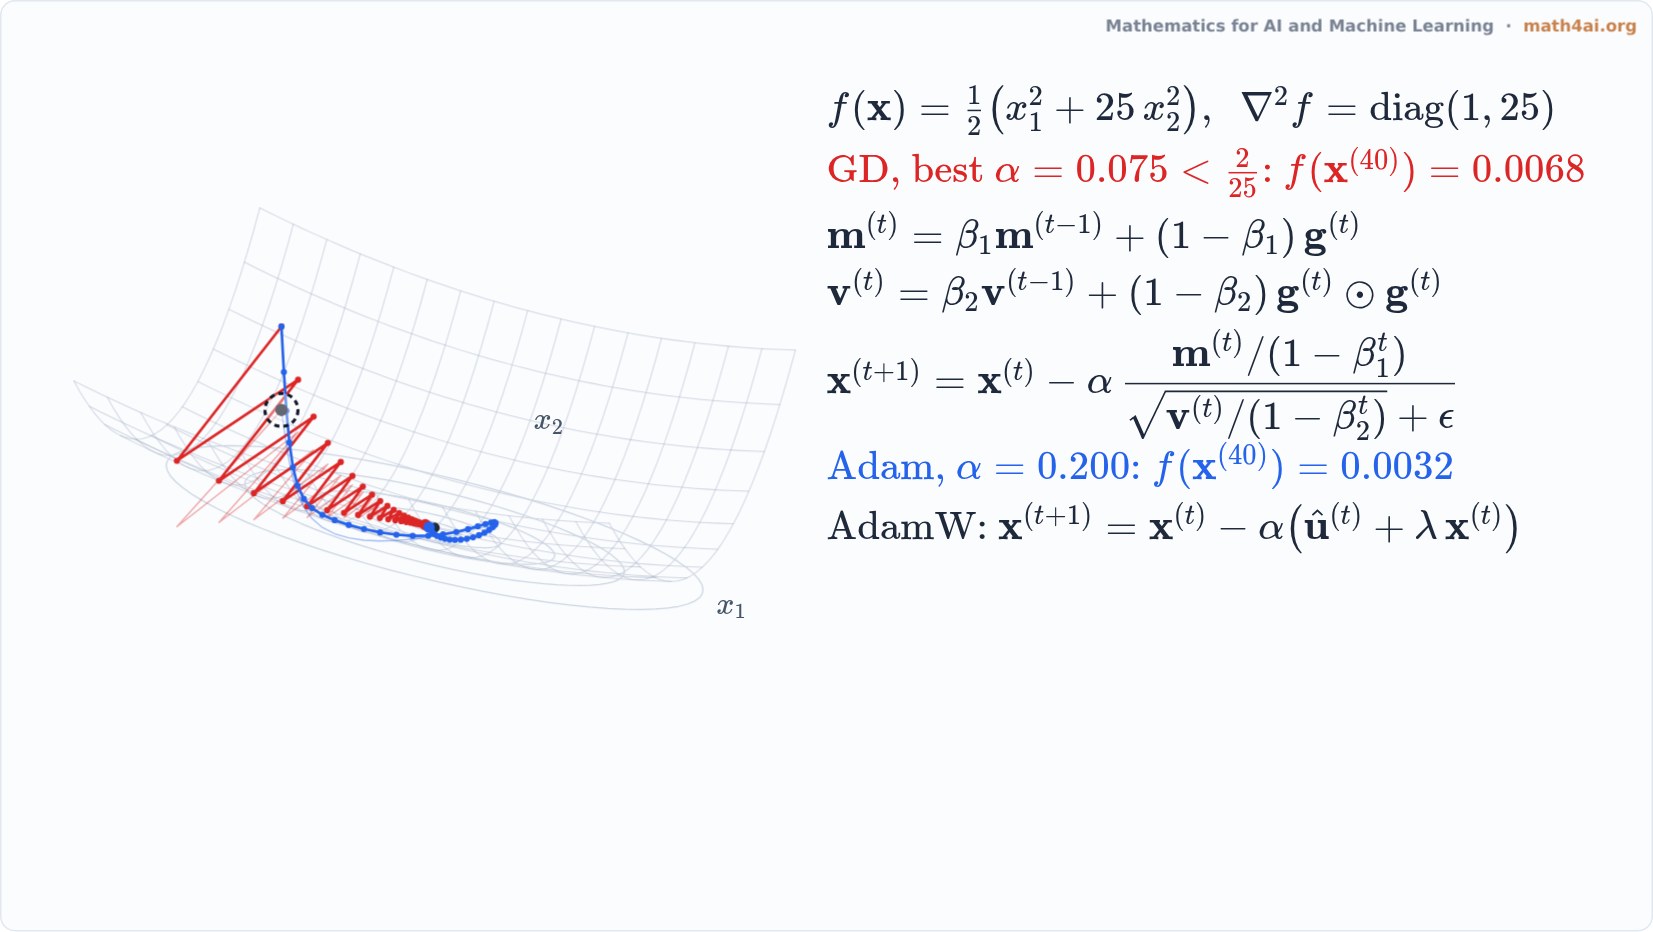 Preview2:14Adam and AdamW: A Step Size for Every CoordinateChapter 12
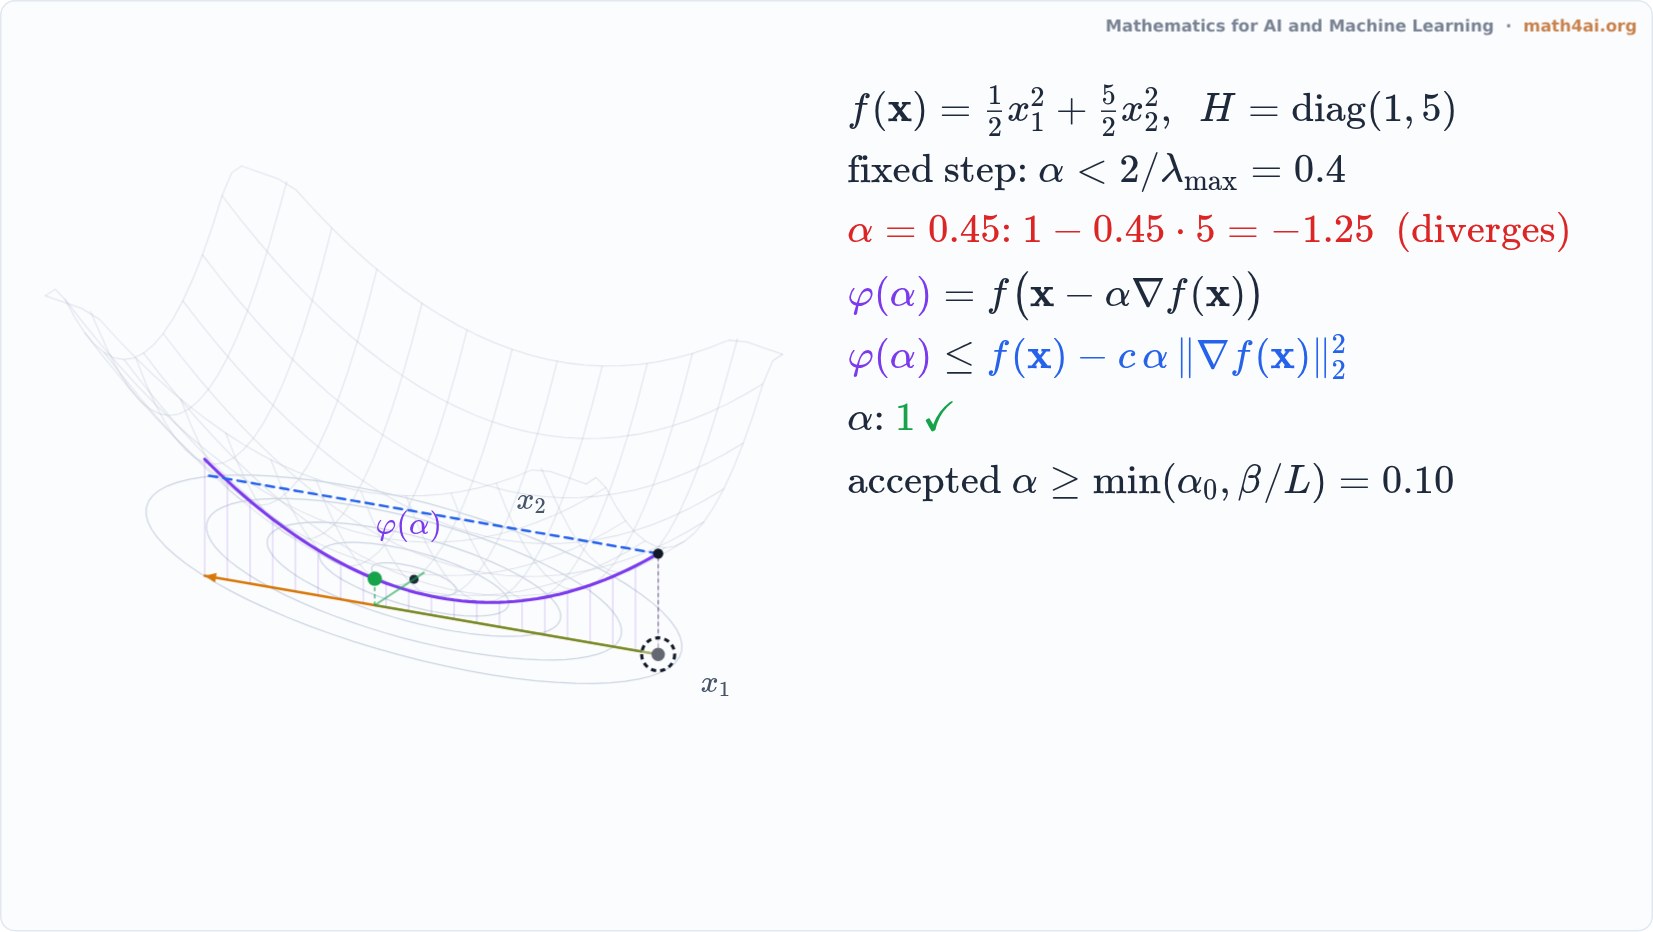 Preview1:55Backtracking Line Search and the Armijo ConditionChapter 12
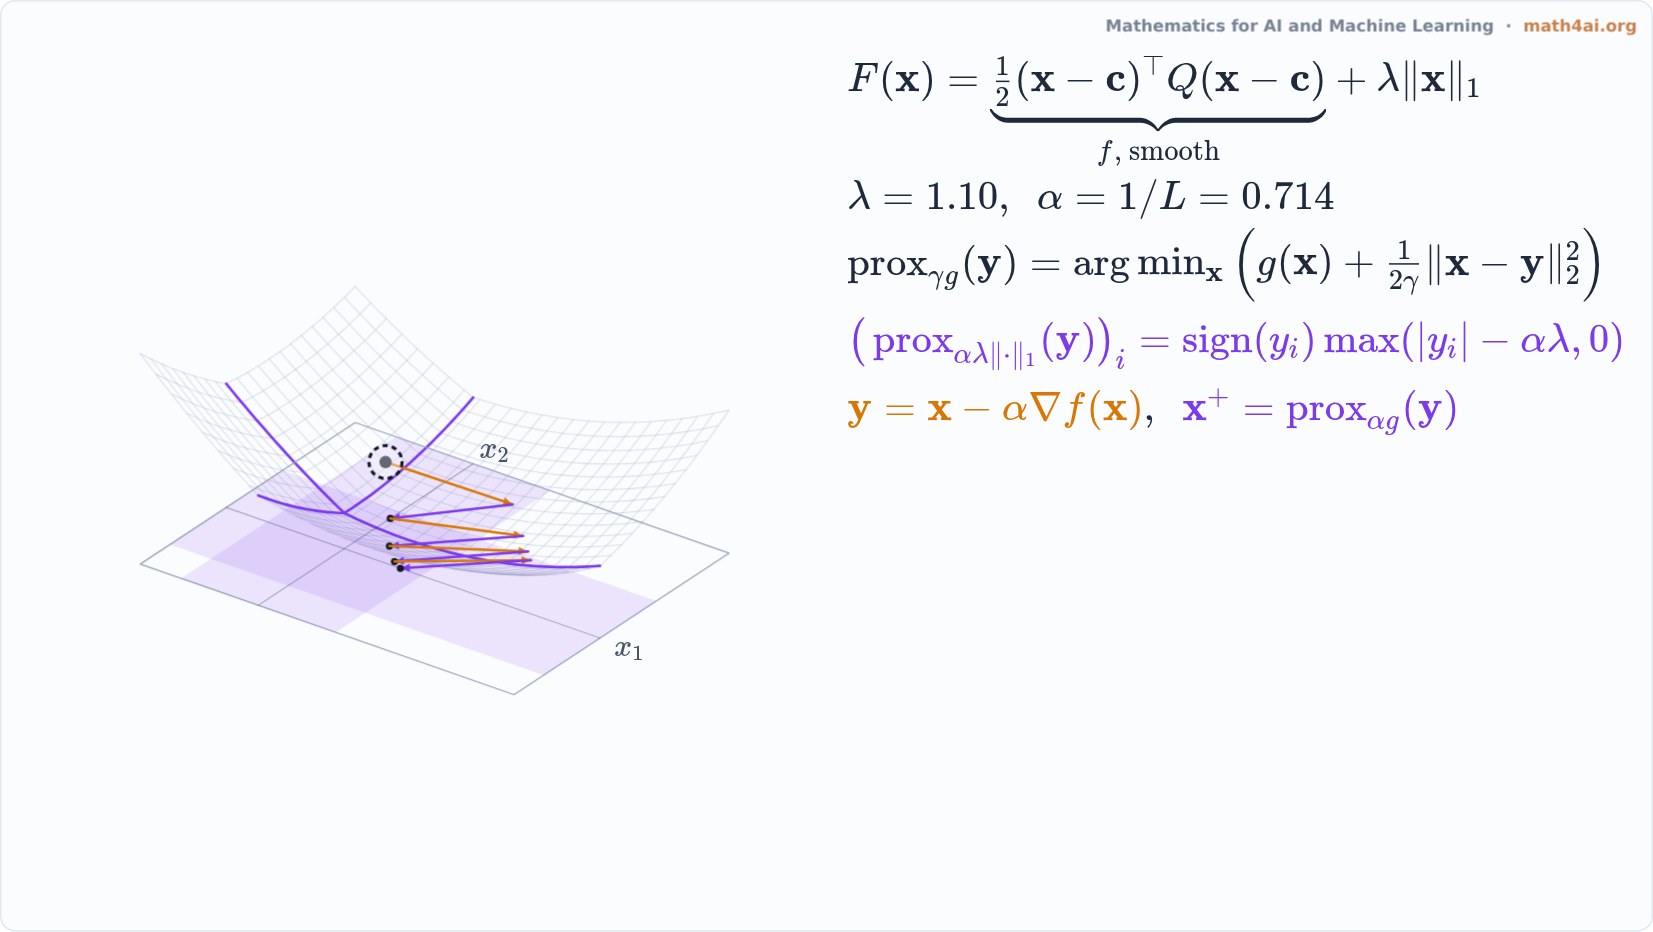 Preview1:50Proximal Gradient and Soft-Thresholding: Exact ZerosChapter 12
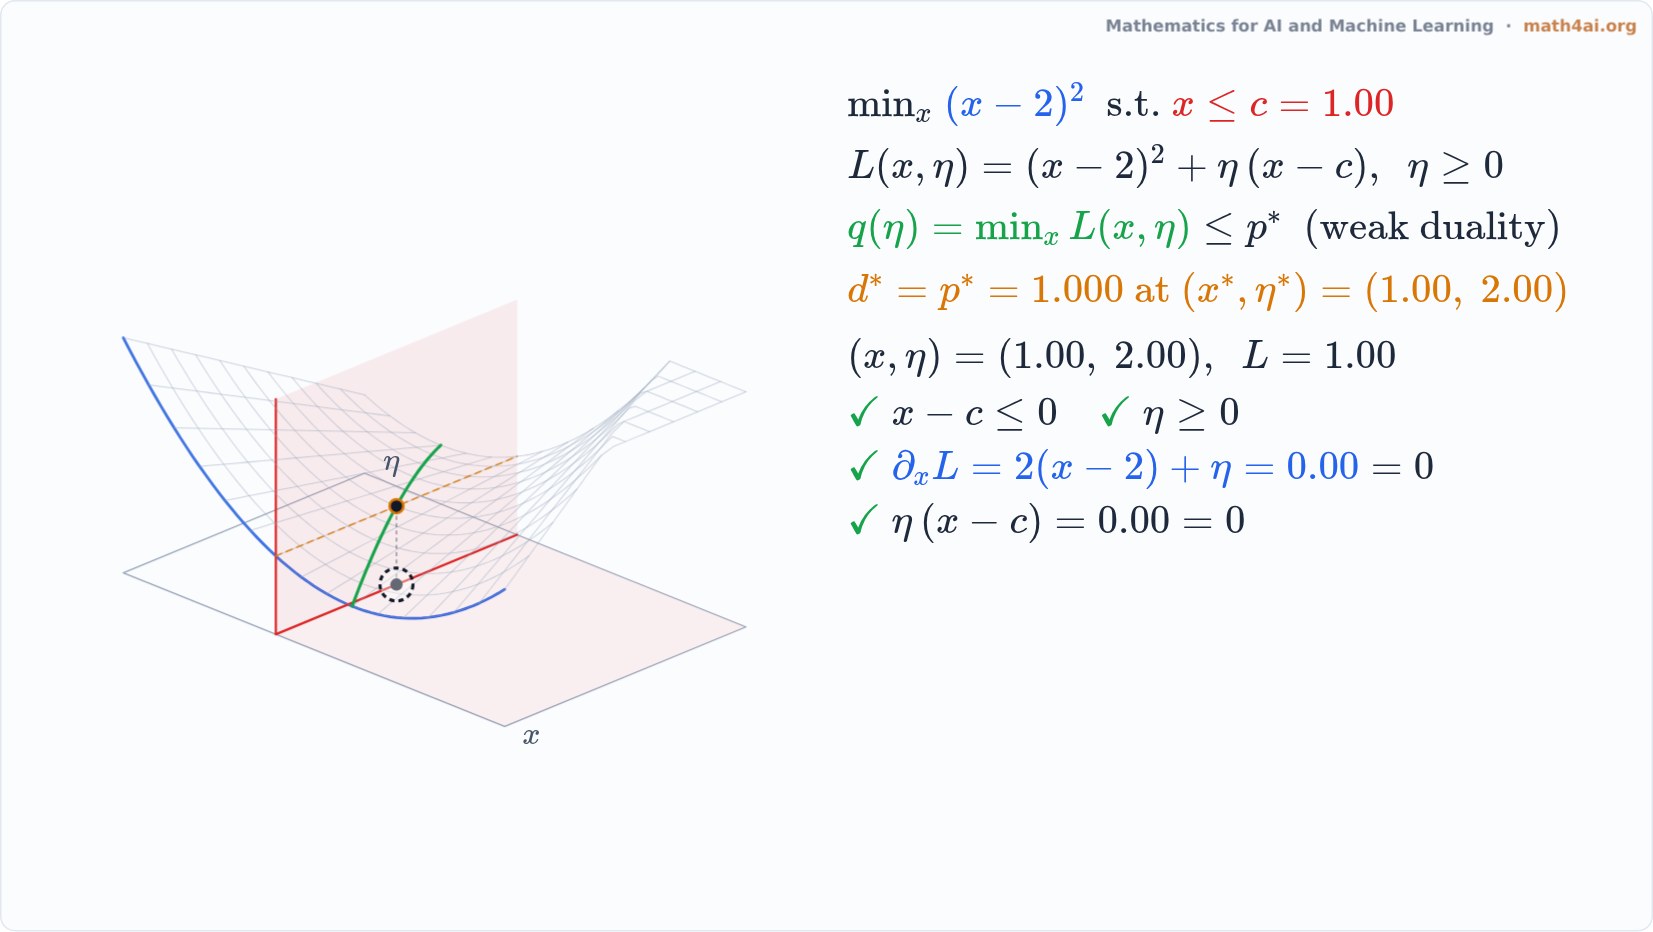 Preview1:53KKT Conditions: the Saddle Point of the LagrangianChapter 12
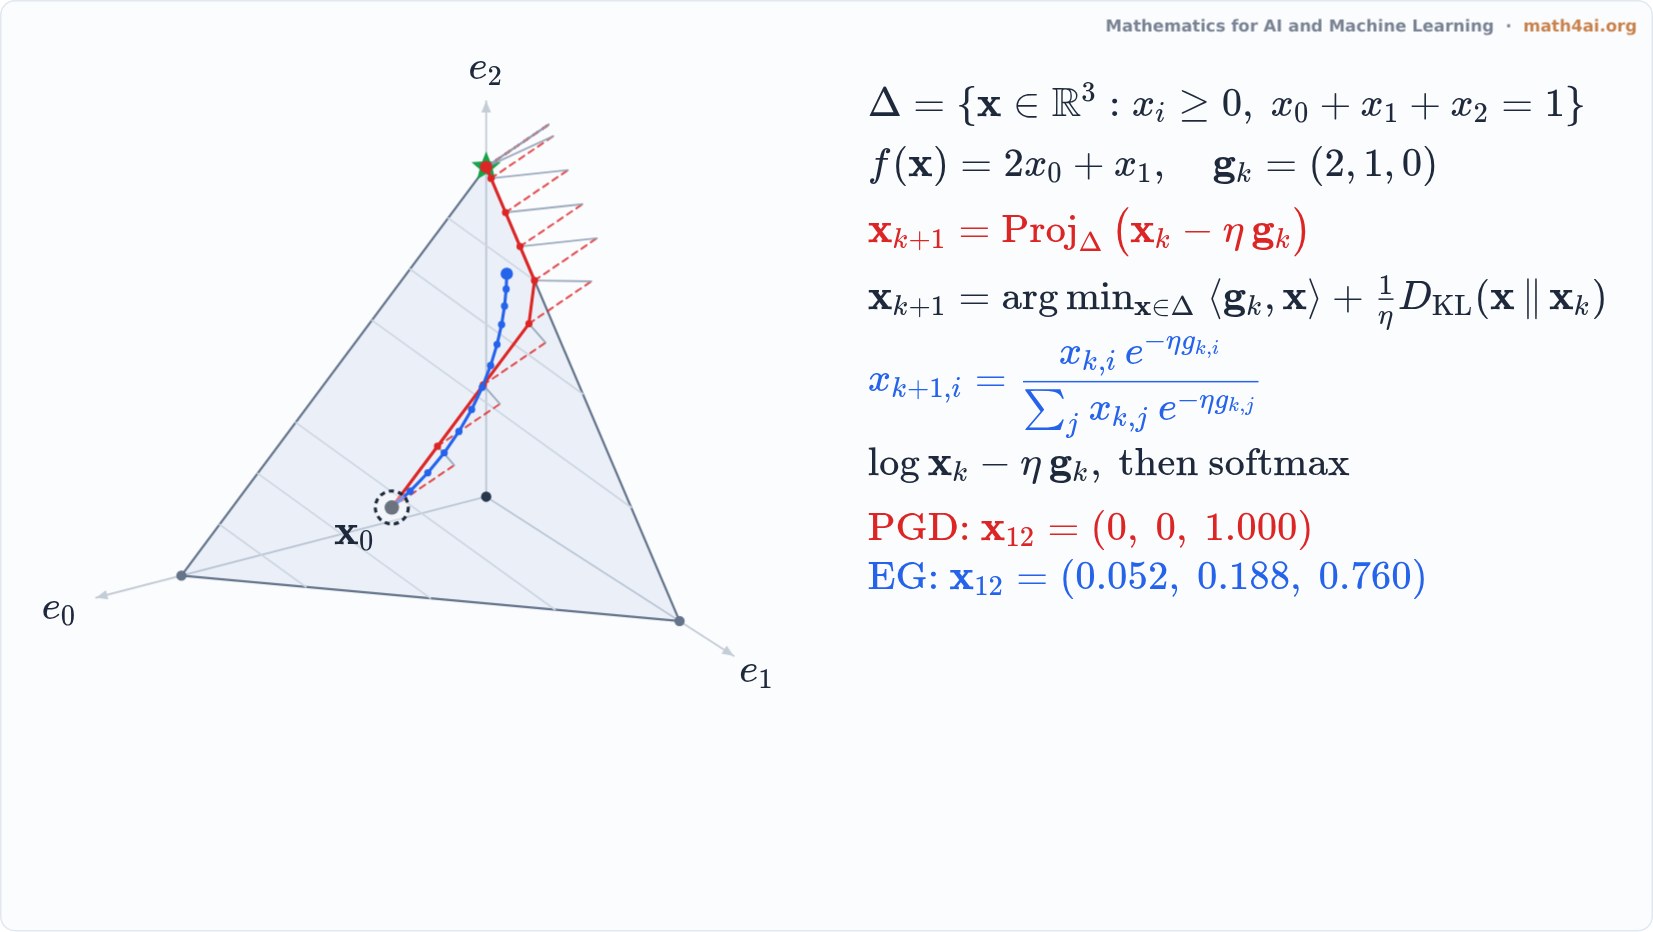 Preview1:52Mirror Descent Stays Inside the SimplexChapter 12
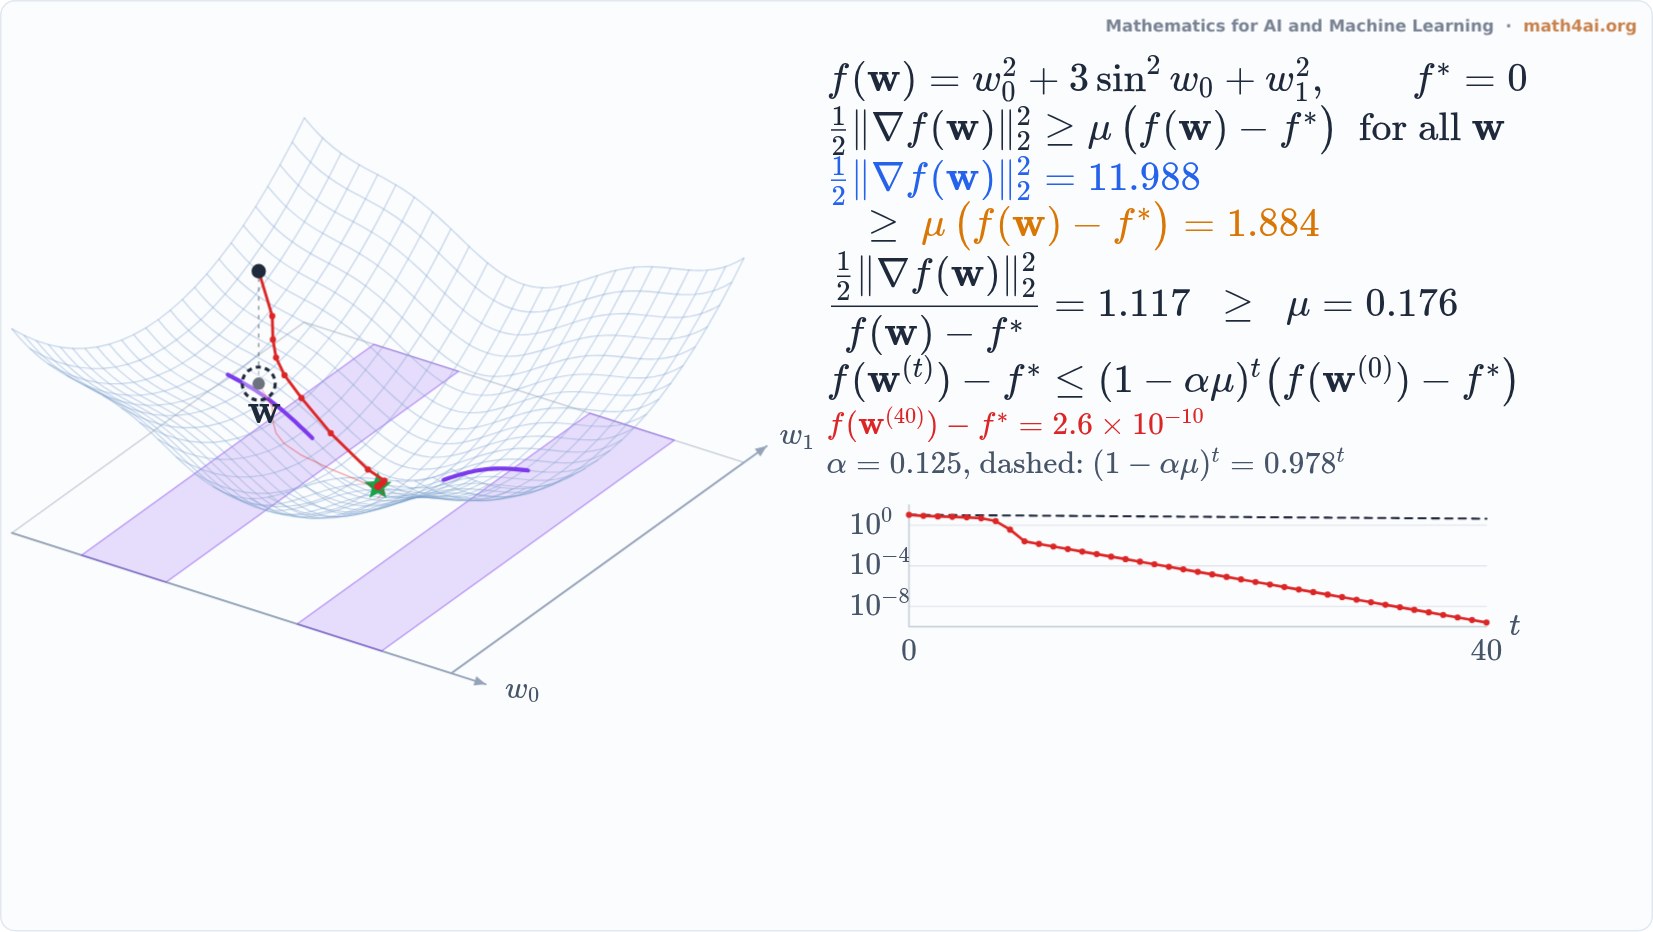 Preview1:55The Polyak-Łojasiewicz ConditionChapter 12
Chapter 13 Probability and Random Variables
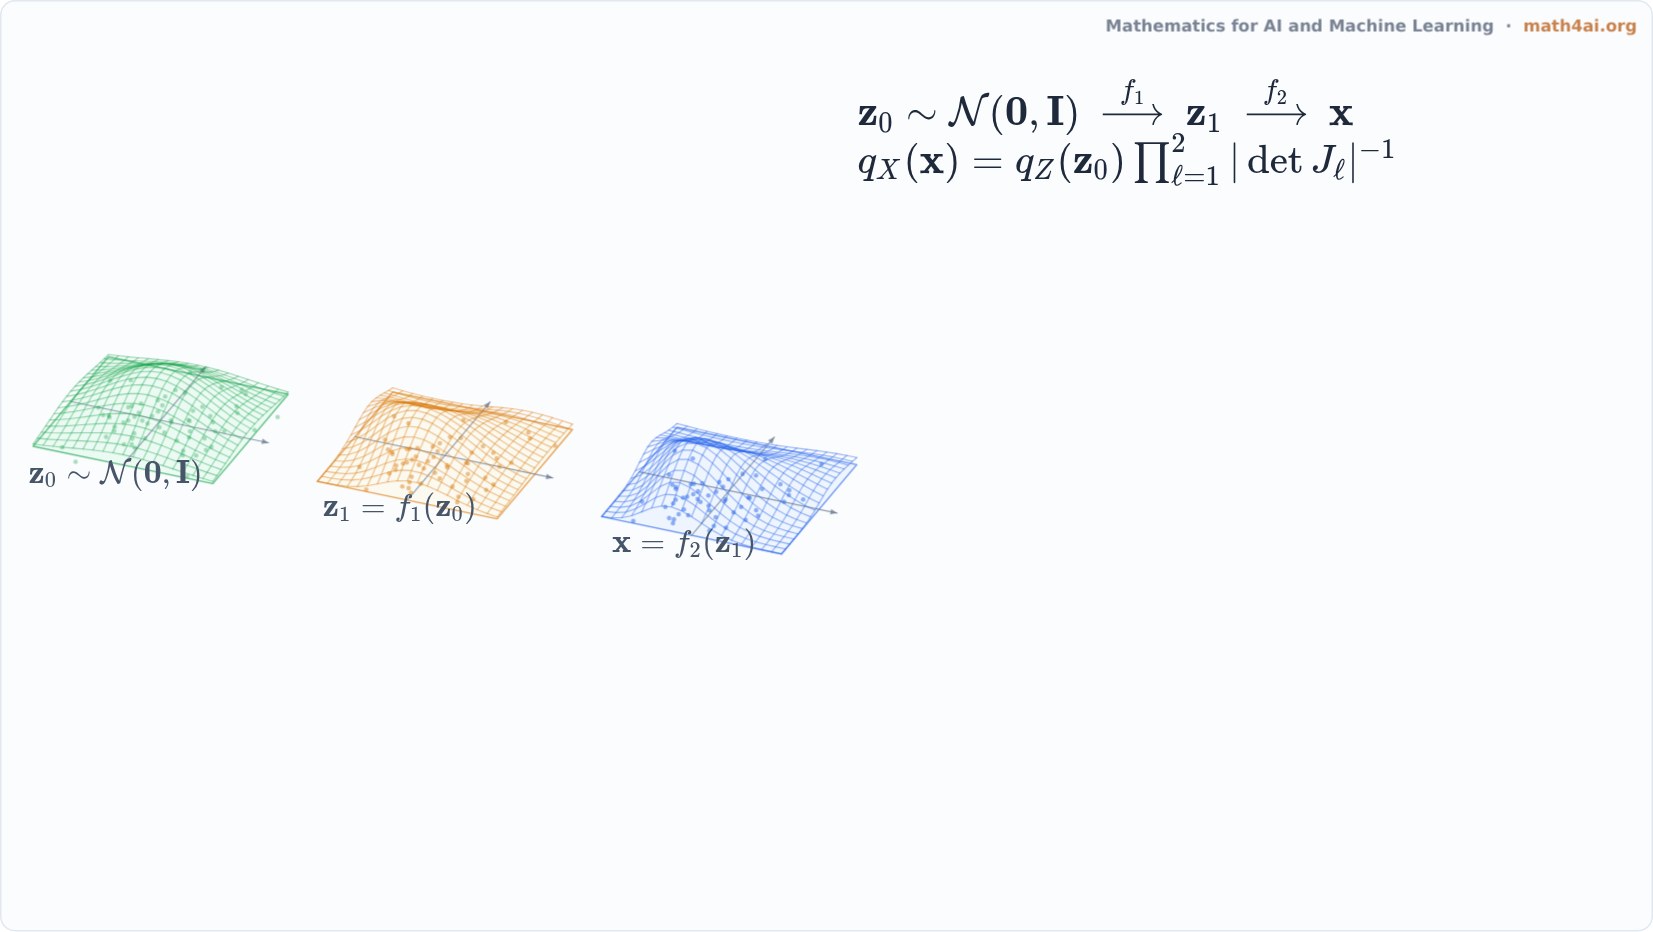 Interactive1:35Normalizing Flows: Chaining Invertible MapsChapter 13
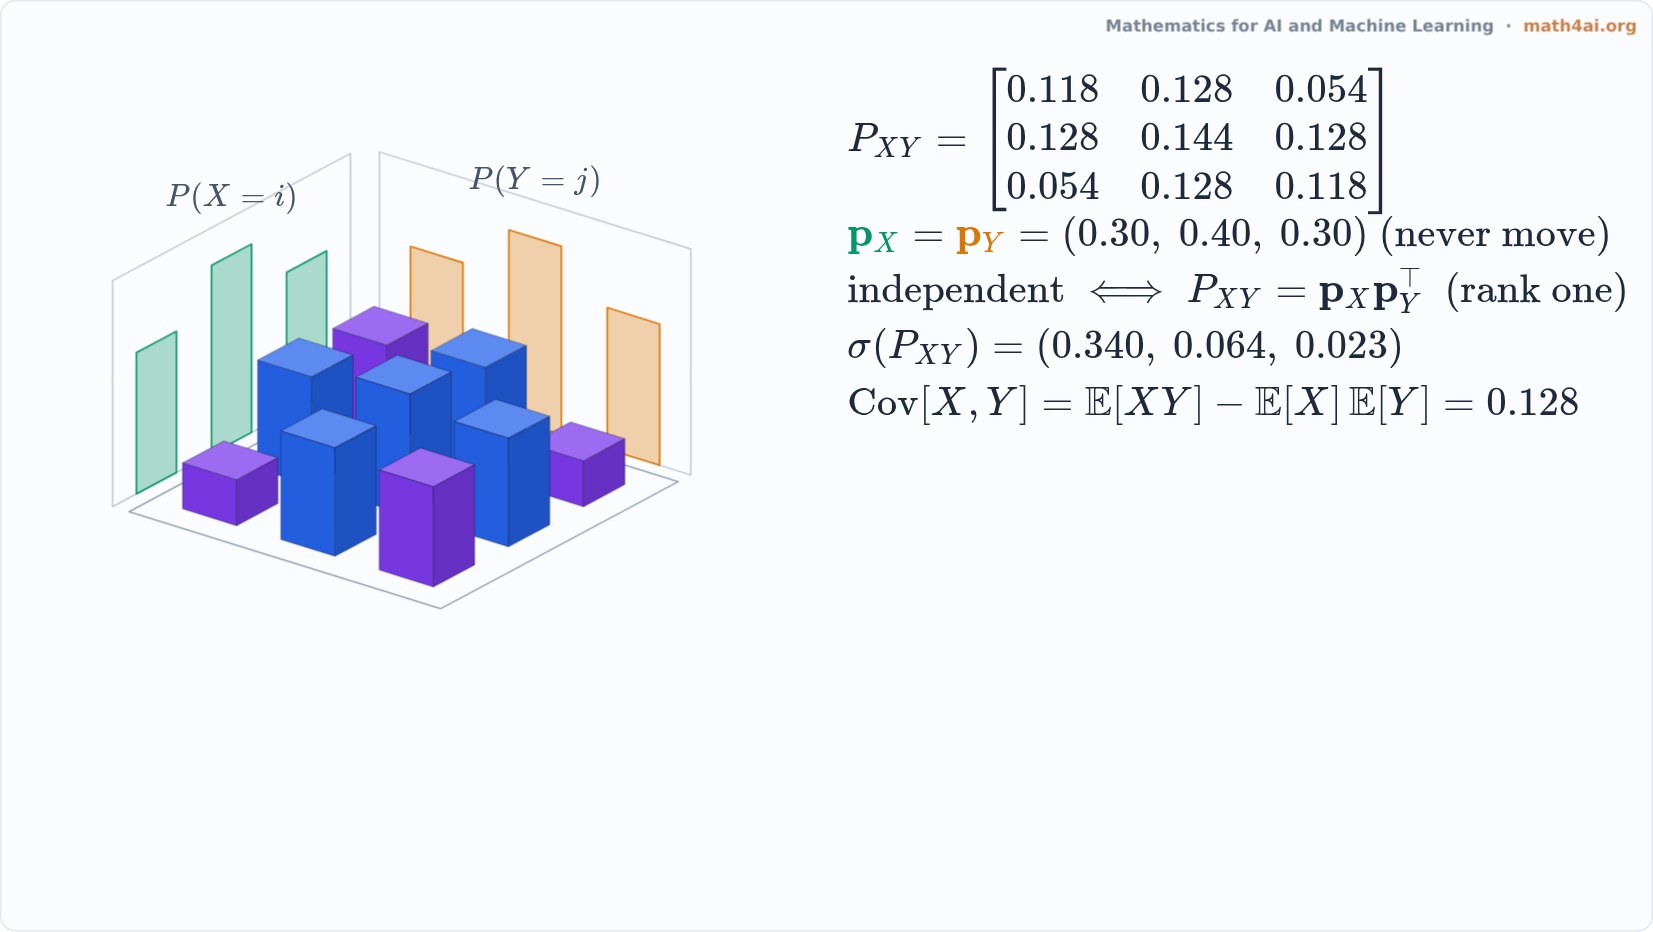 Preview1:38Independence as an Outer ProductChapter 13
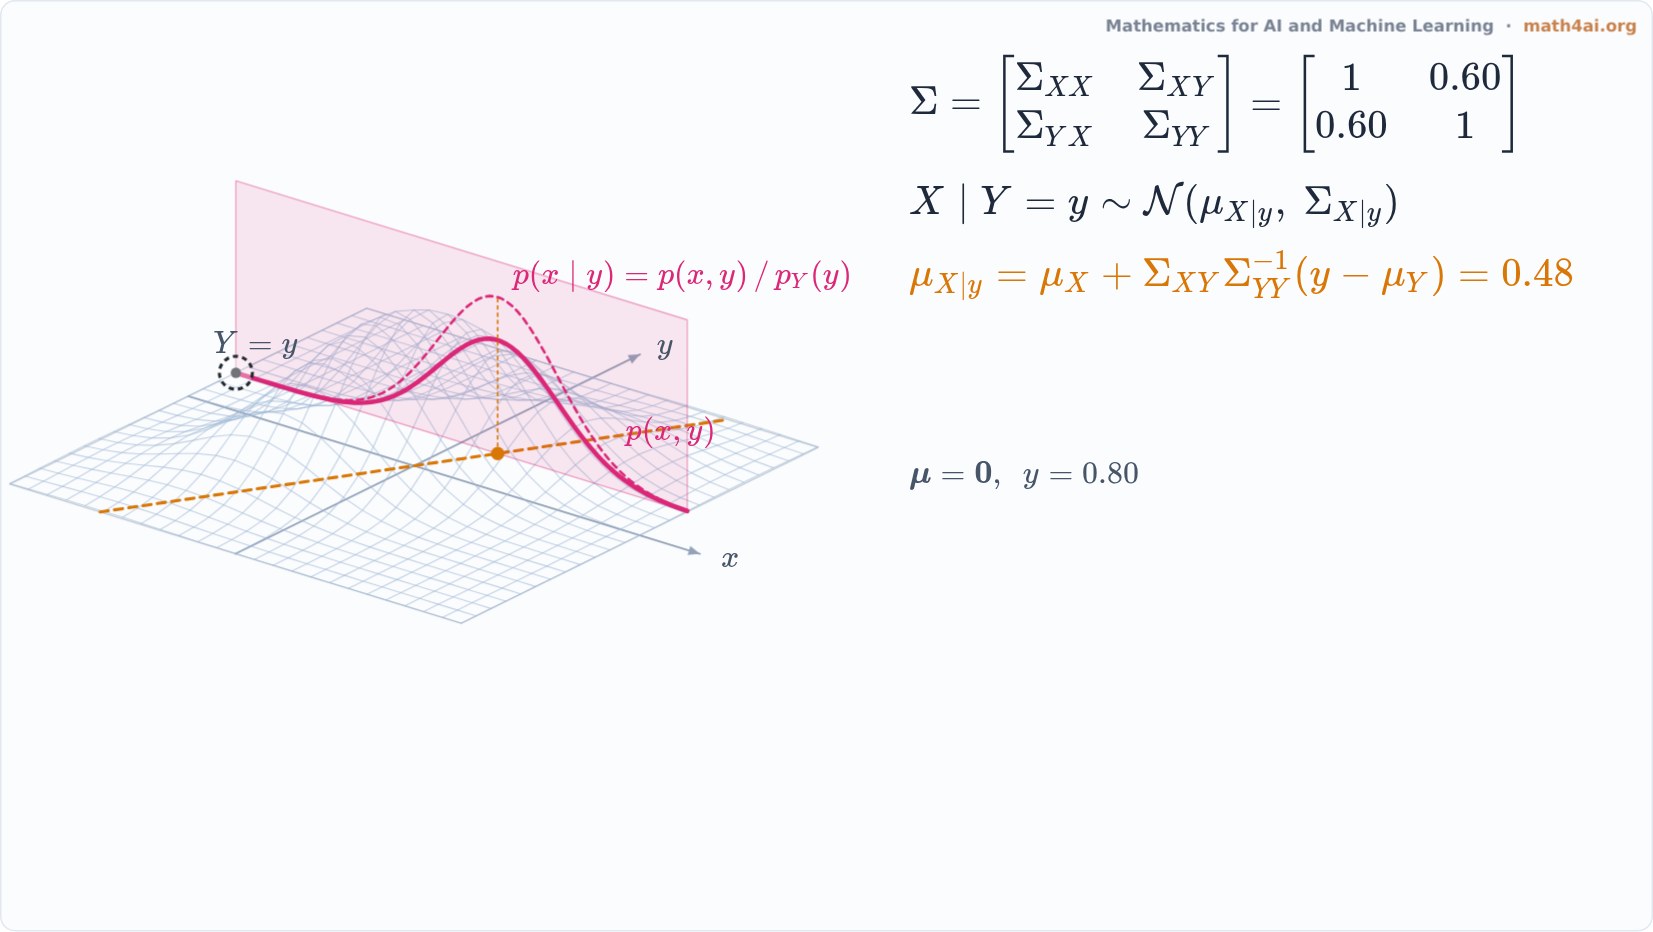 Preview1:40Conditional Gaussian: A Slice of the BellChapter 13
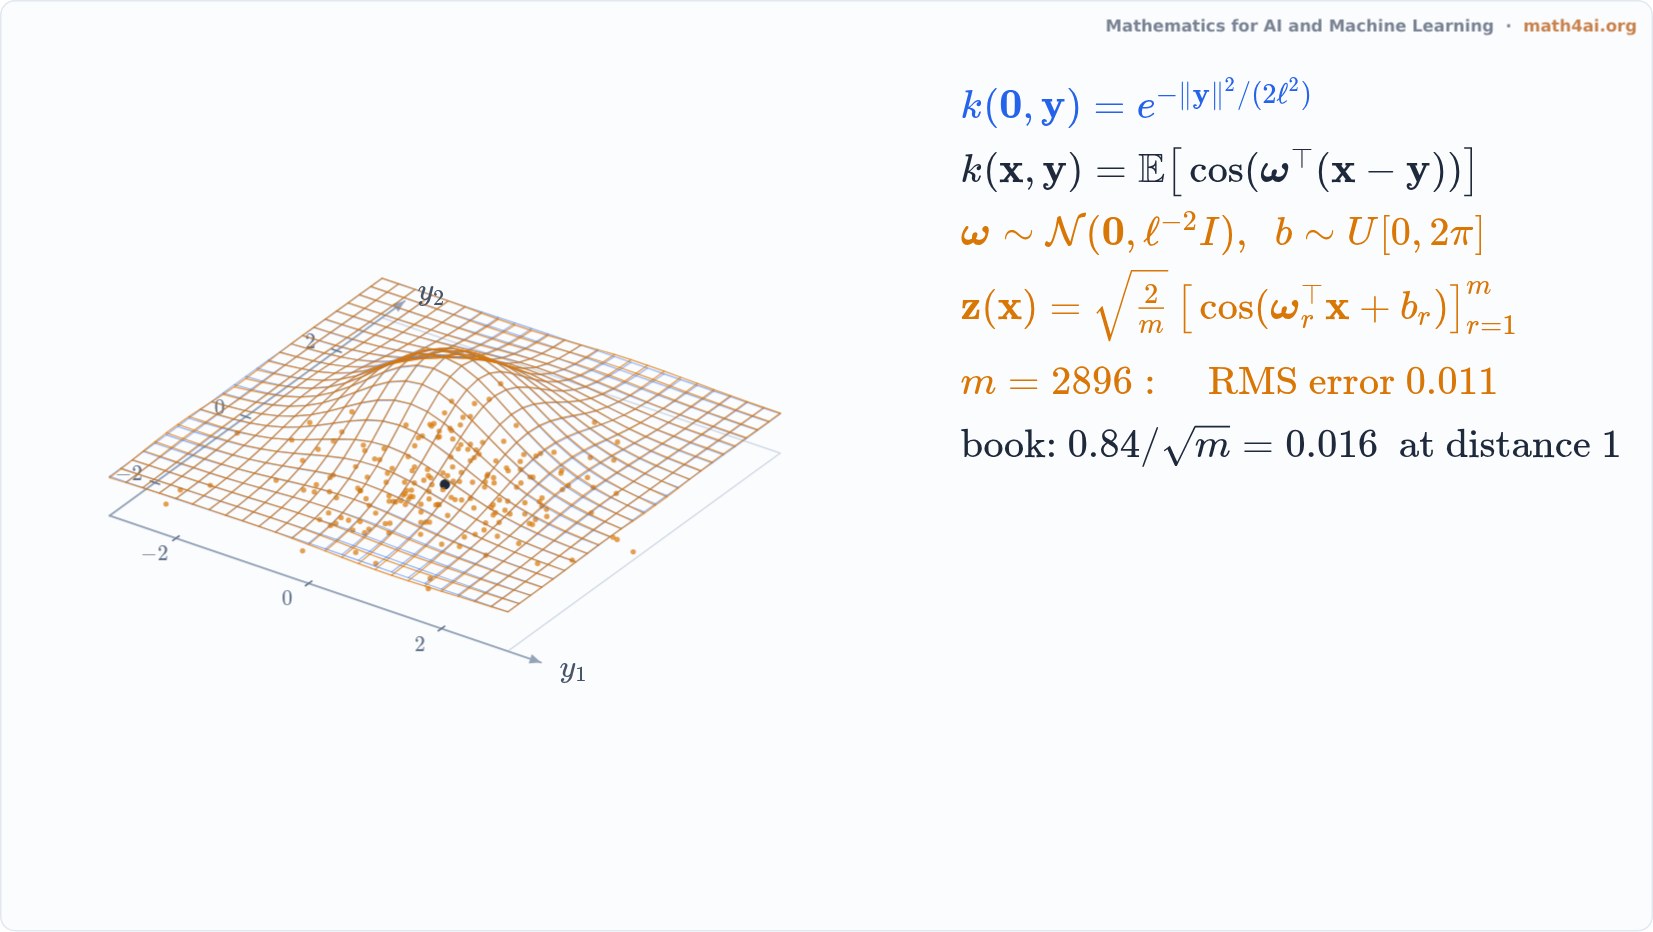 Preview1:22Random Fourier FeaturesChapter 13
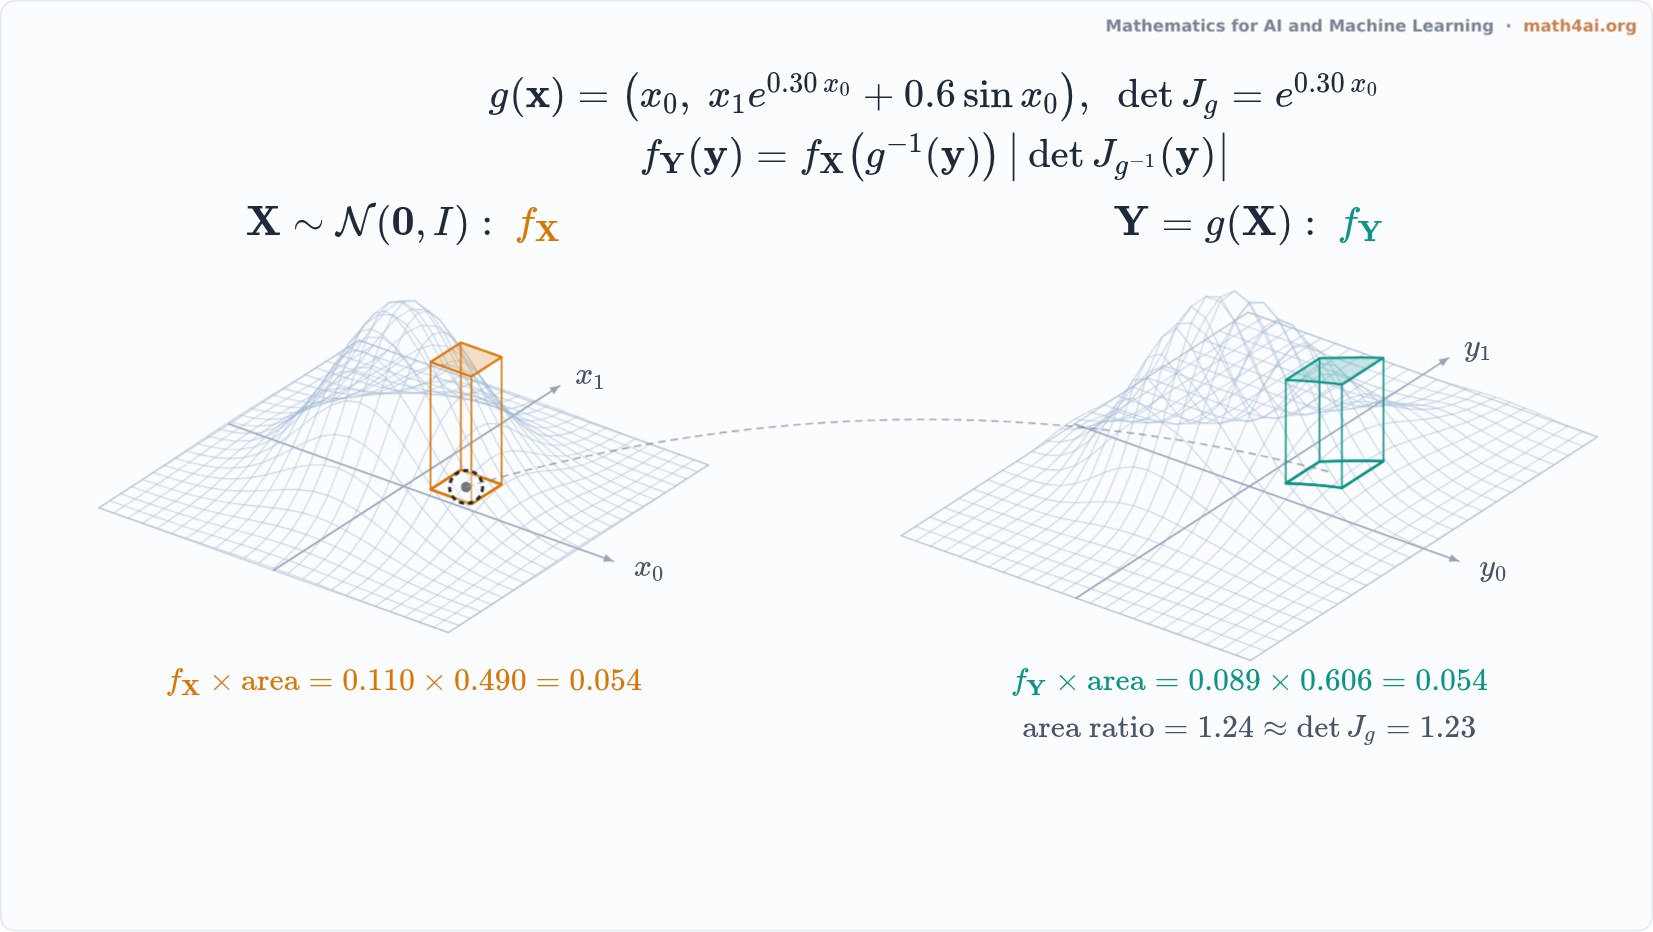 Preview1:46Change of Variables: Same Probability, Different AreaChapter 13
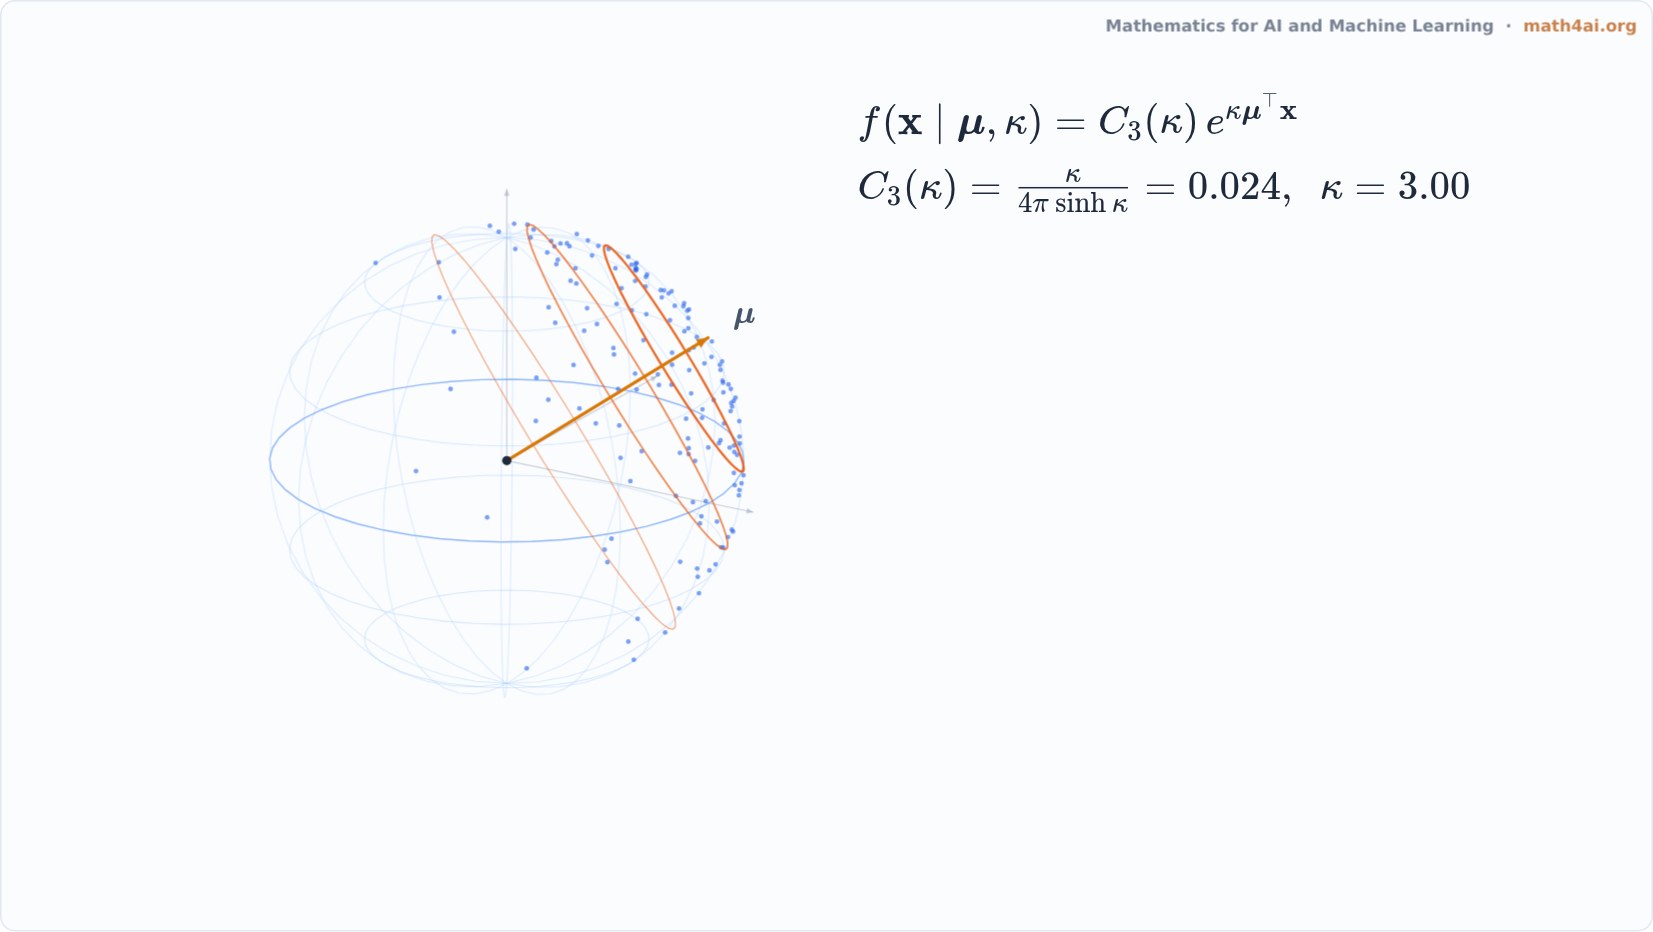 Preview1:35The von Mises-Fisher Distribution: A Gaussian for DirectionsChapter 13
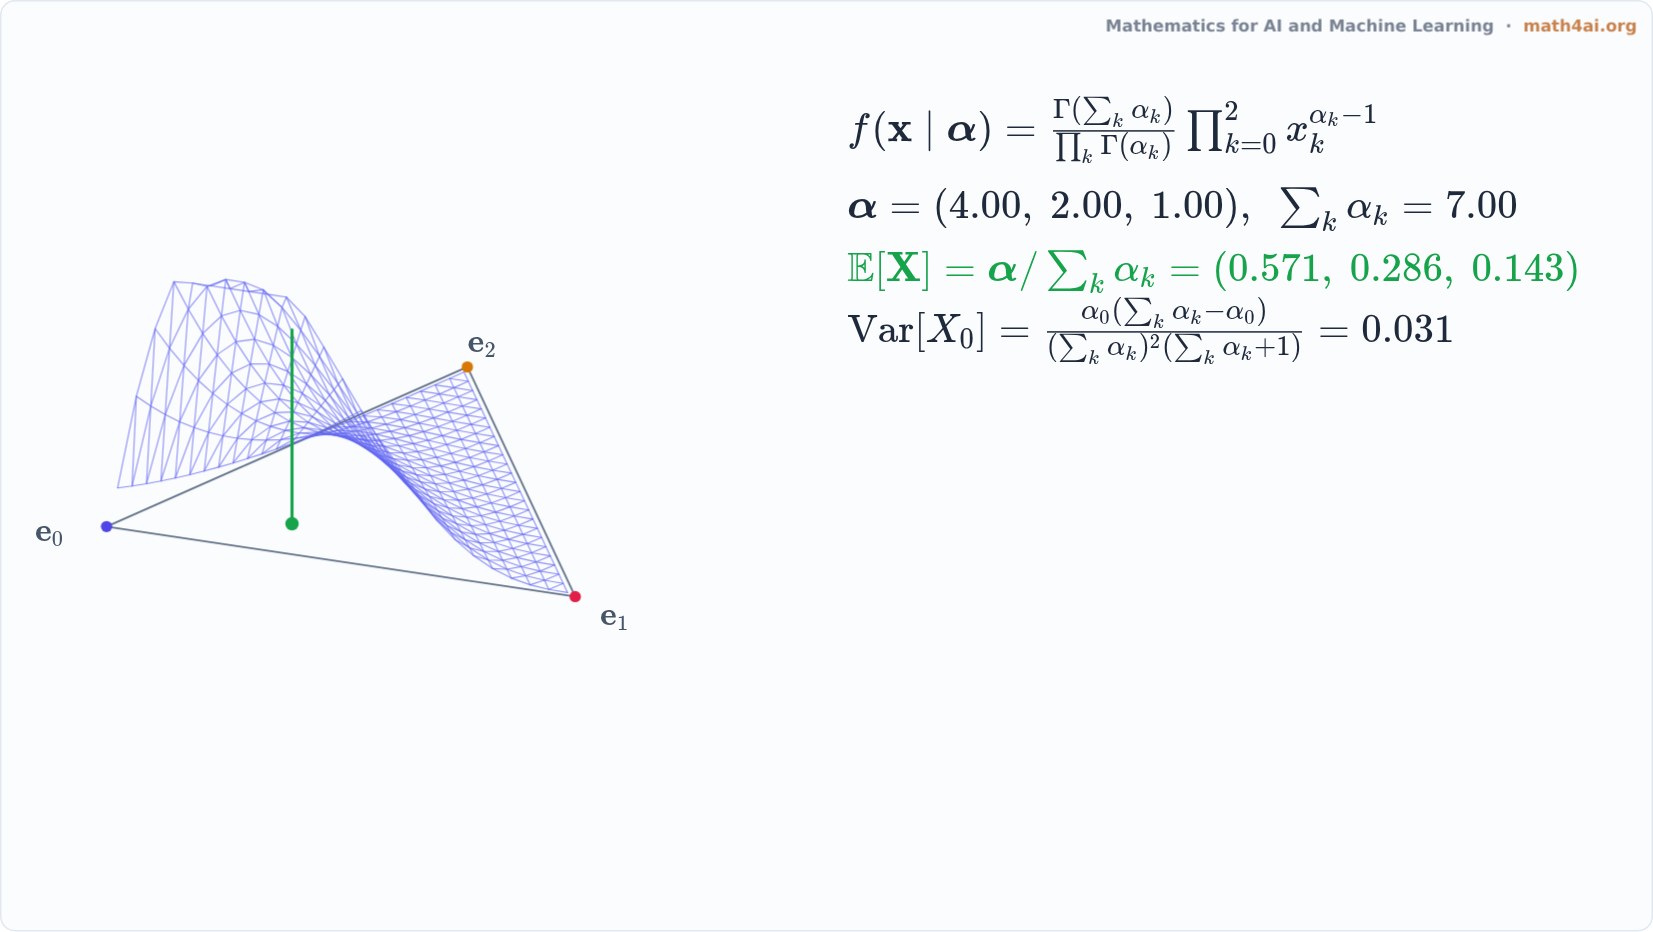 Preview1:42The Dirichlet Distribution: A Density on the SimplexChapter 13
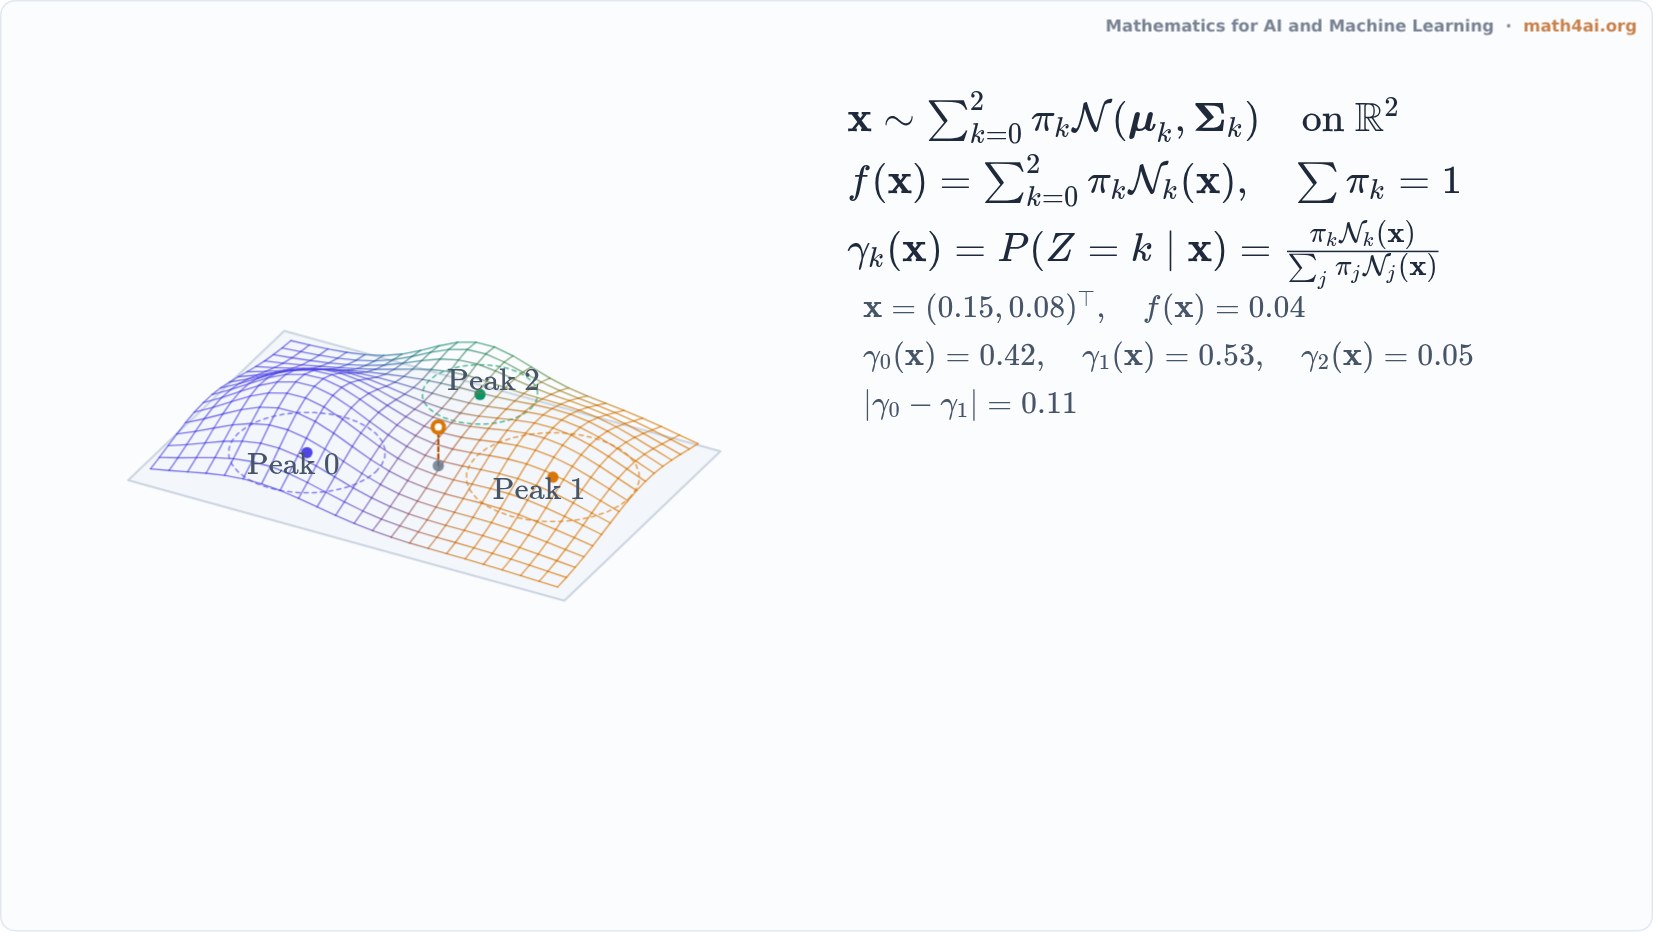 Preview1:14Gaussian Mixture Model: Multimodal TerrainChapter 13
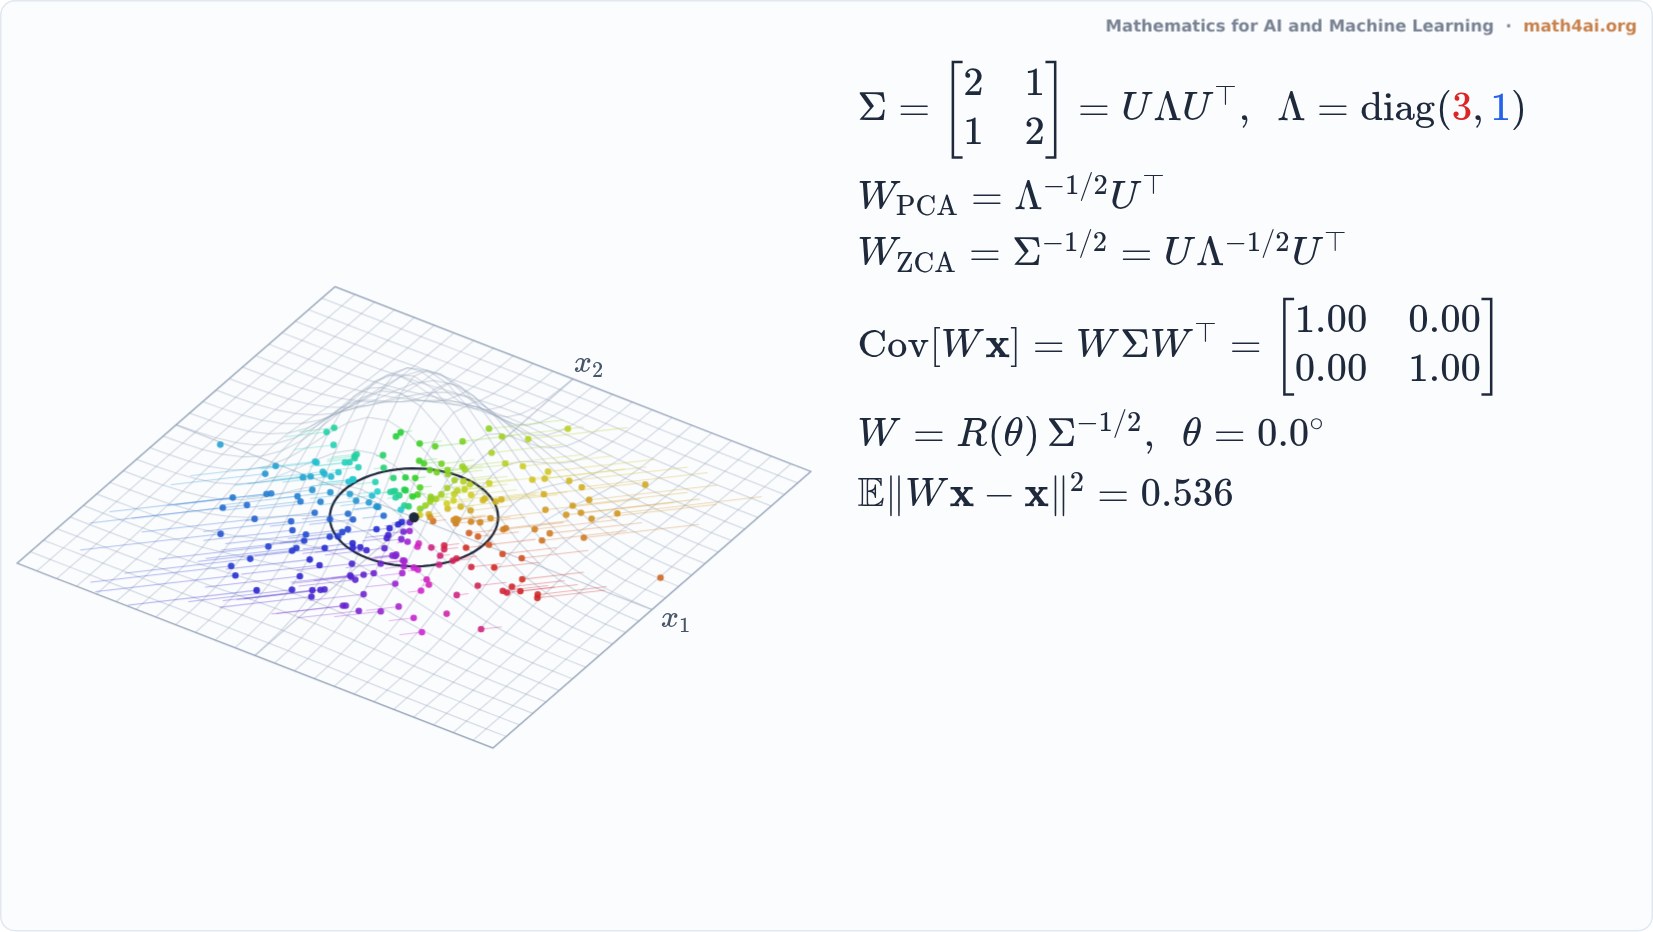 Preview1:41Whitening: PCA and ZCAChapter 13
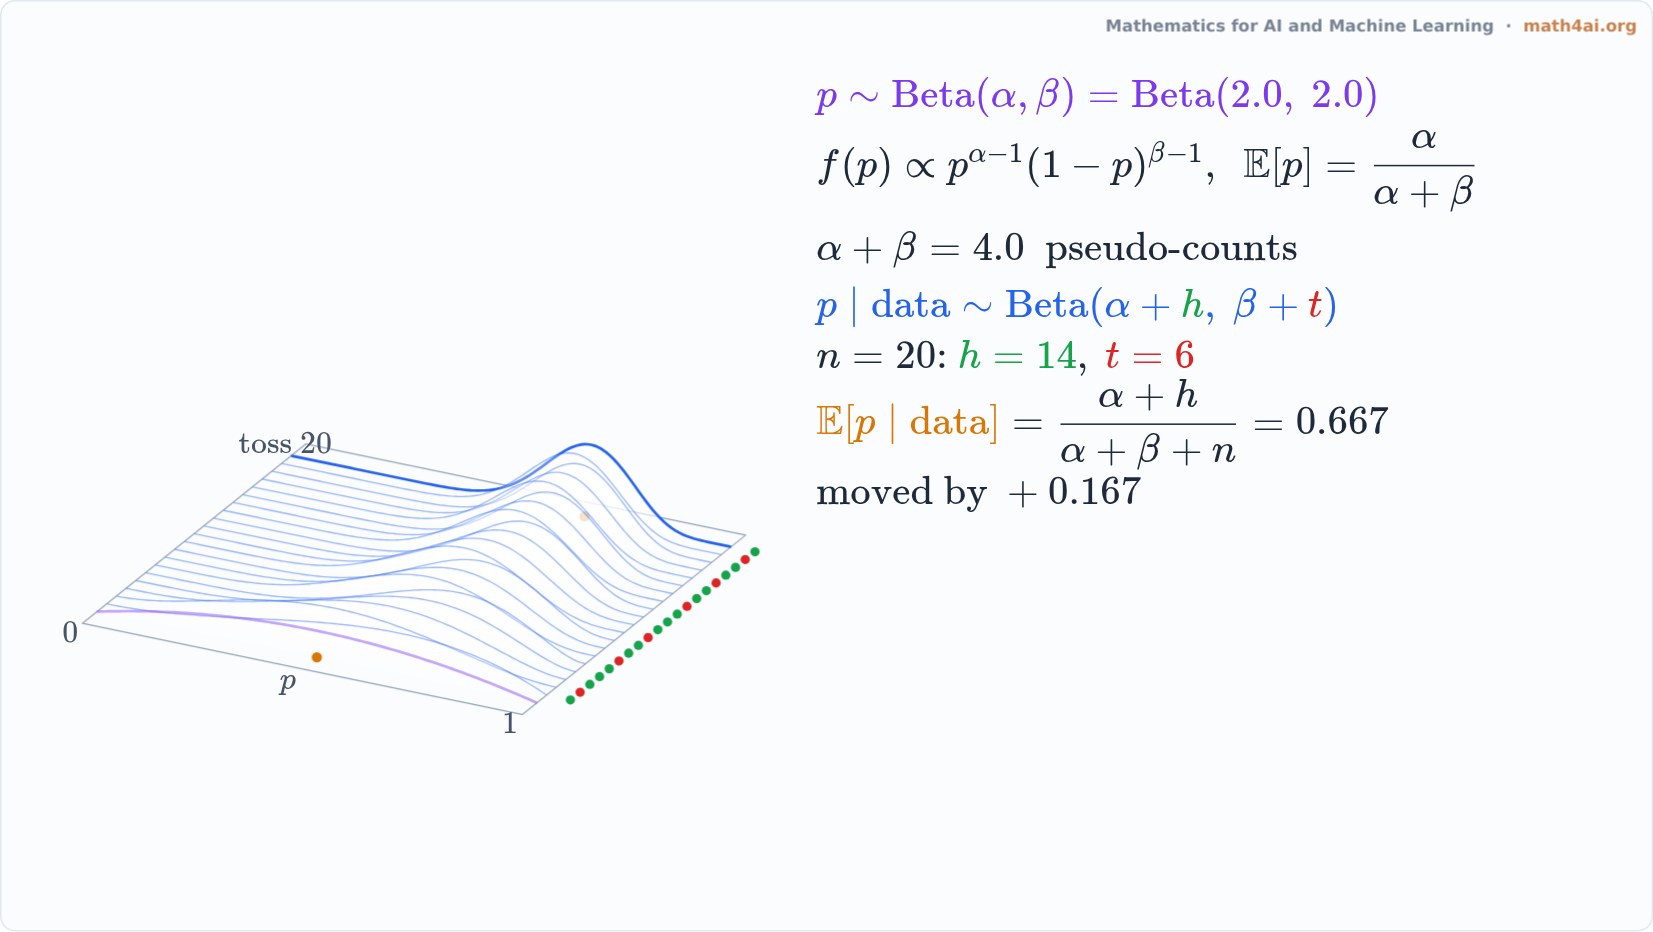 Preview1:36Beta and Bernoulli: Updating with Pseudo-CountsChapter 13
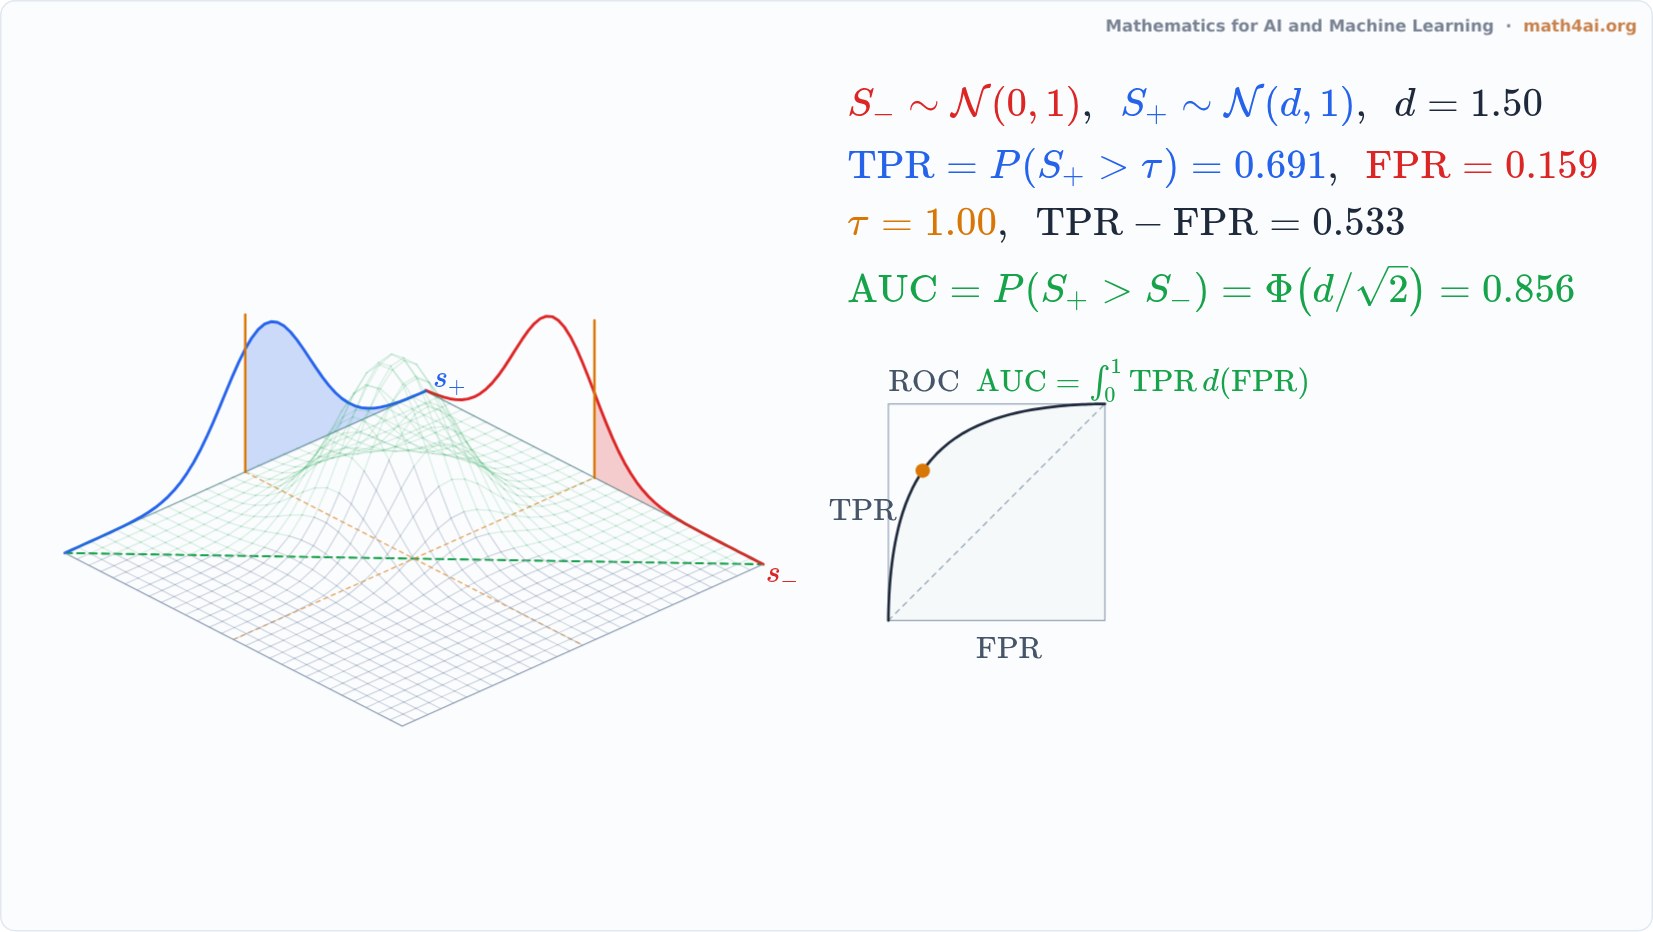 Preview1:43ROC Curve and AUC: the Mass Above the DiagonalChapter 13
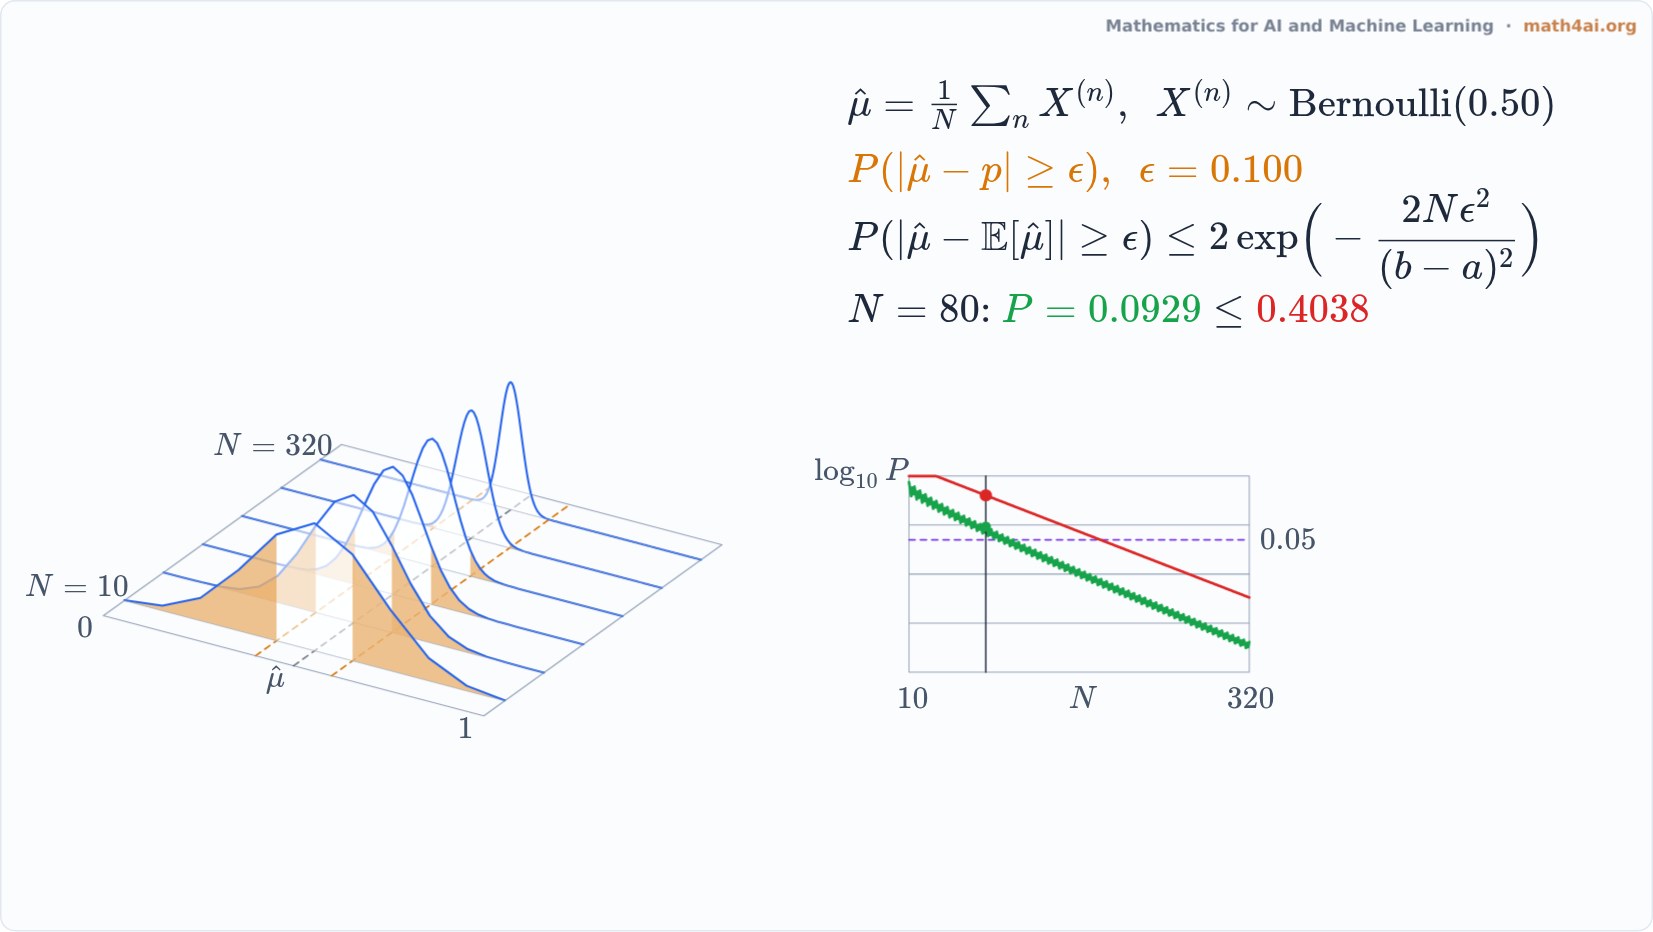 Preview1:40Hoeffding's Inequality: How Fast a Sample Mean SettlesChapter 13
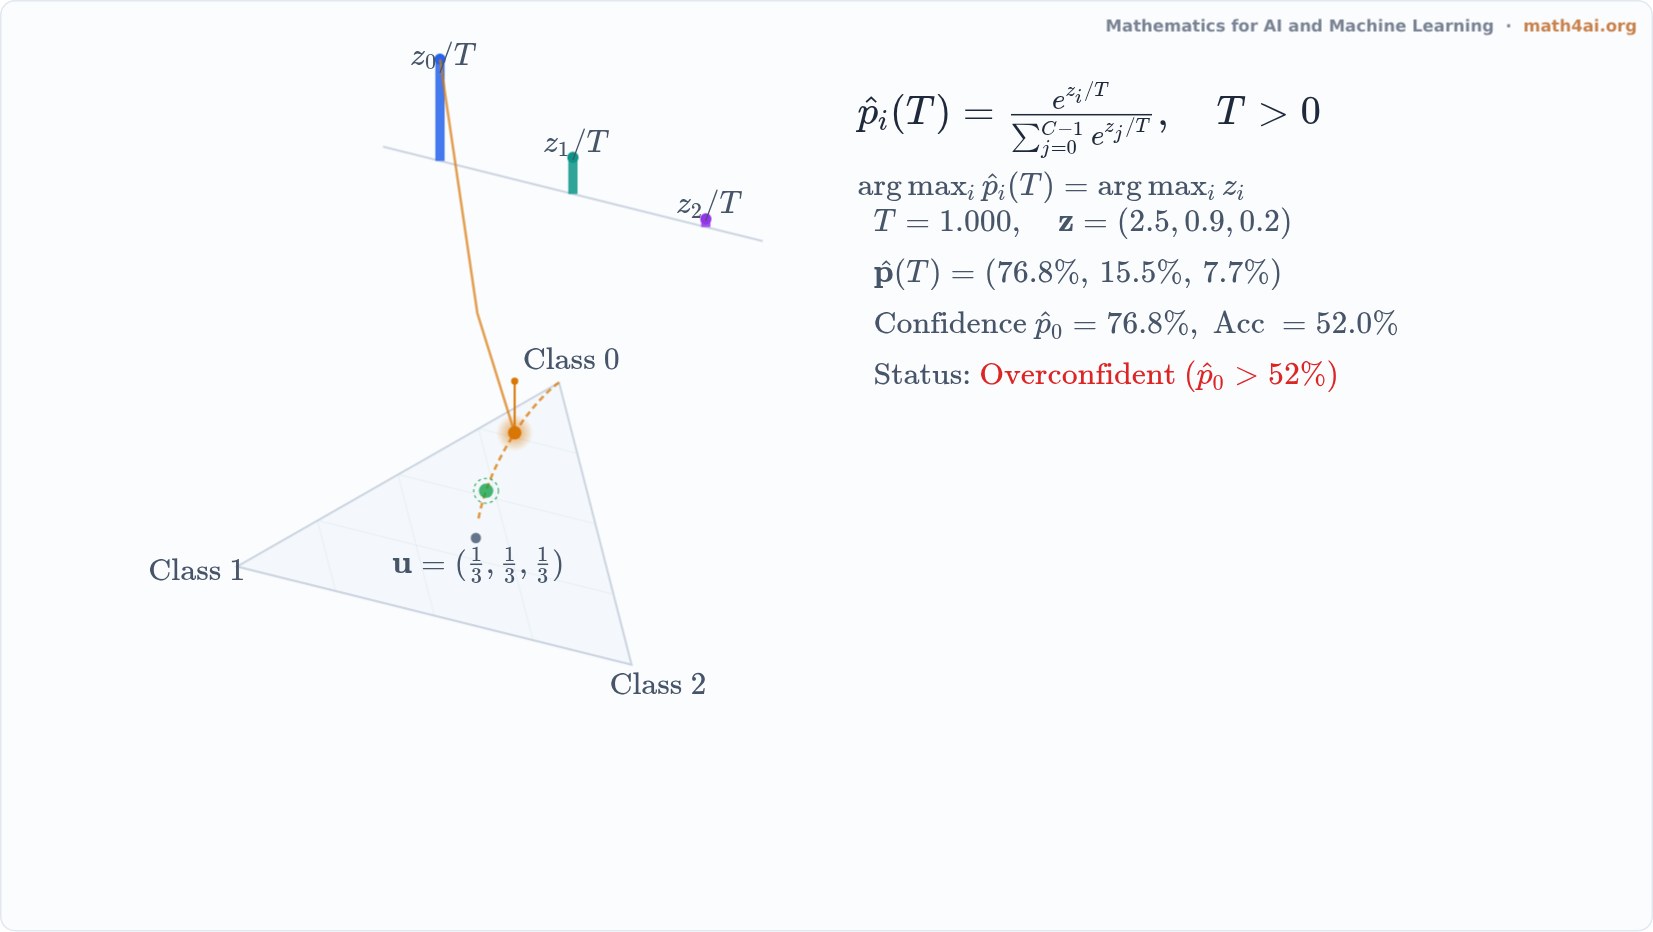 Preview1:25Temperature Scaling: Calibrating a SoftmaxChapter 13
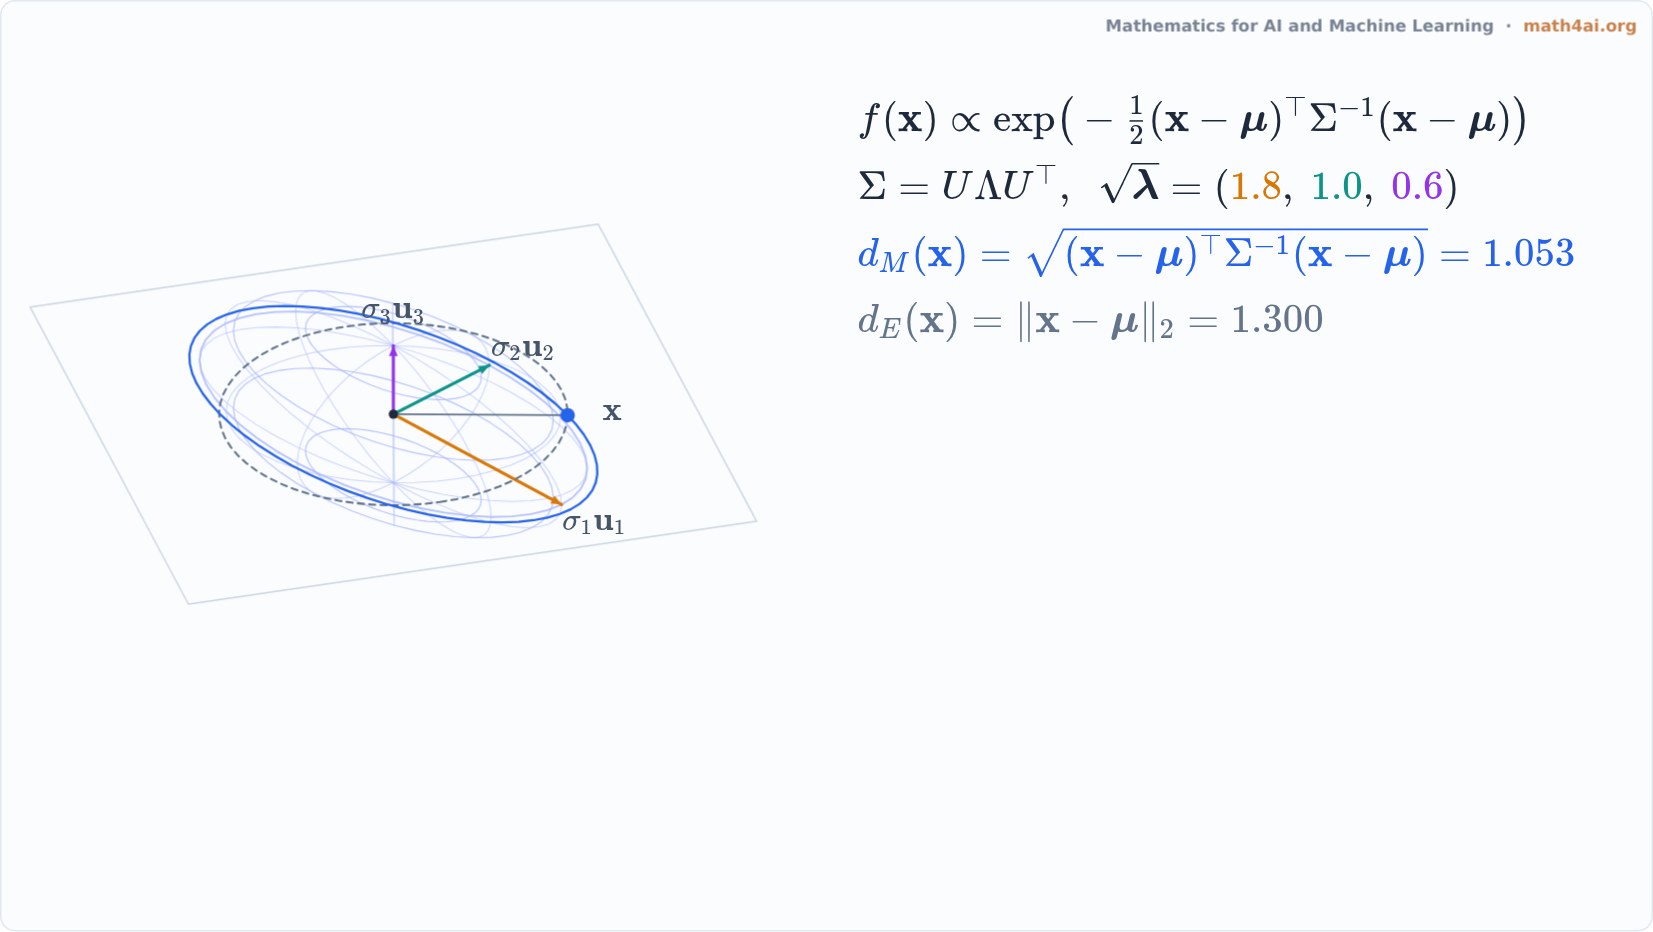 Preview1:34Mahalanobis Distance: The Ellipsoids of a GaussianChapter 13
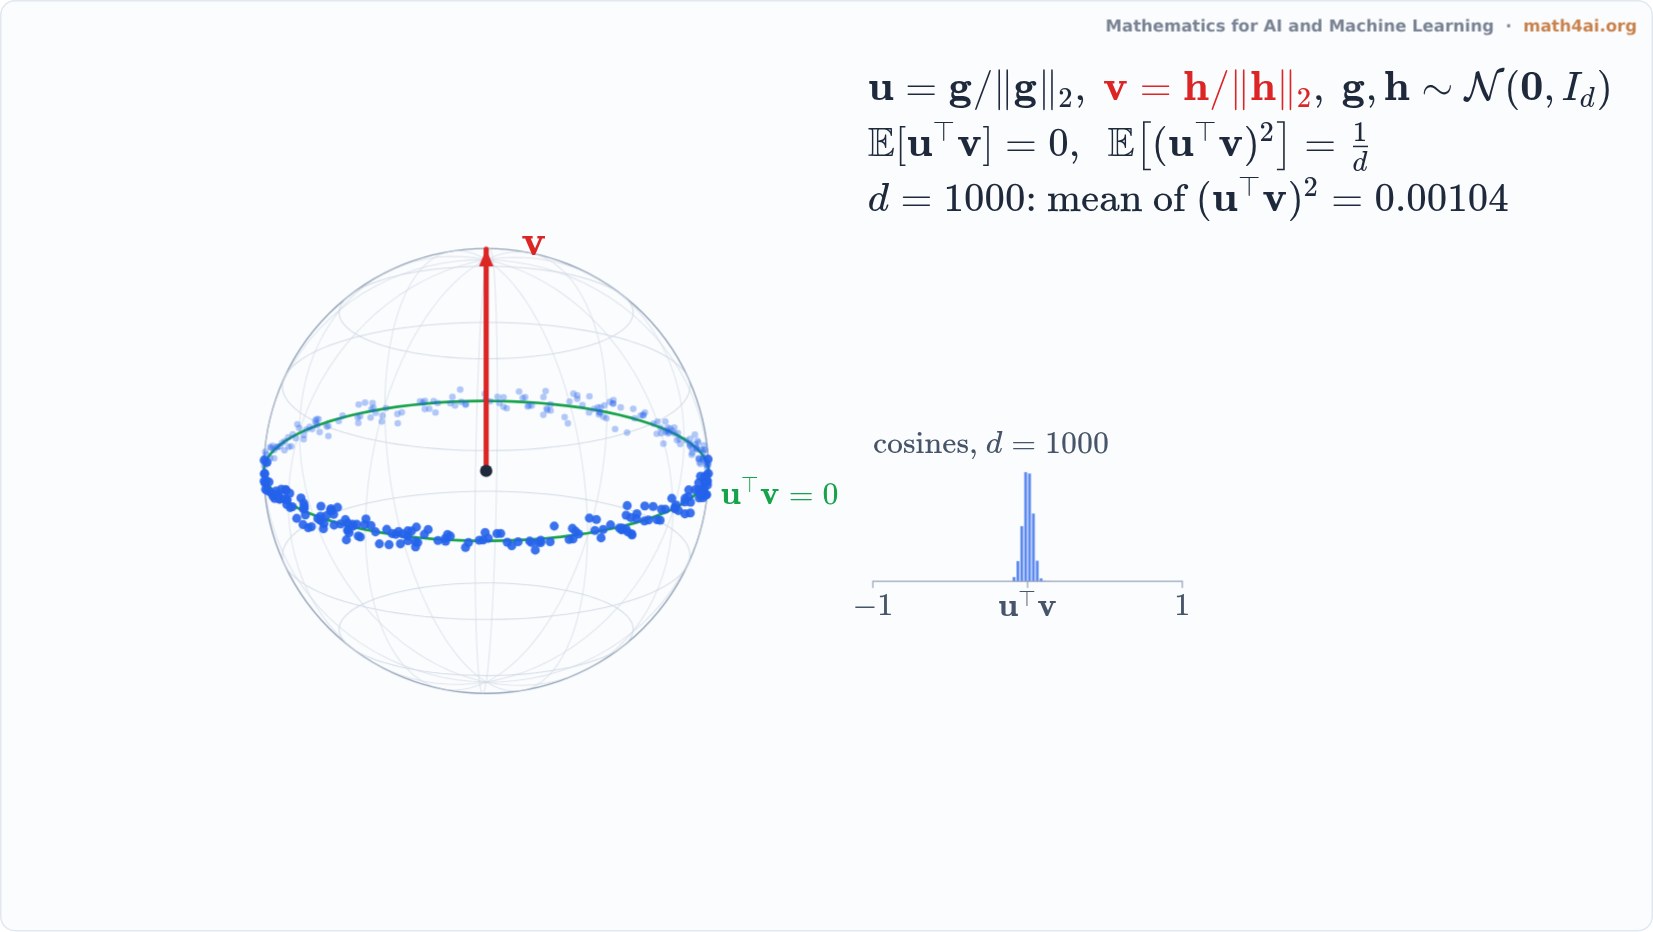 Preview2:09Random Directions Are Nearly OrthogonalChapter 13
Chapter 14 Information Theory
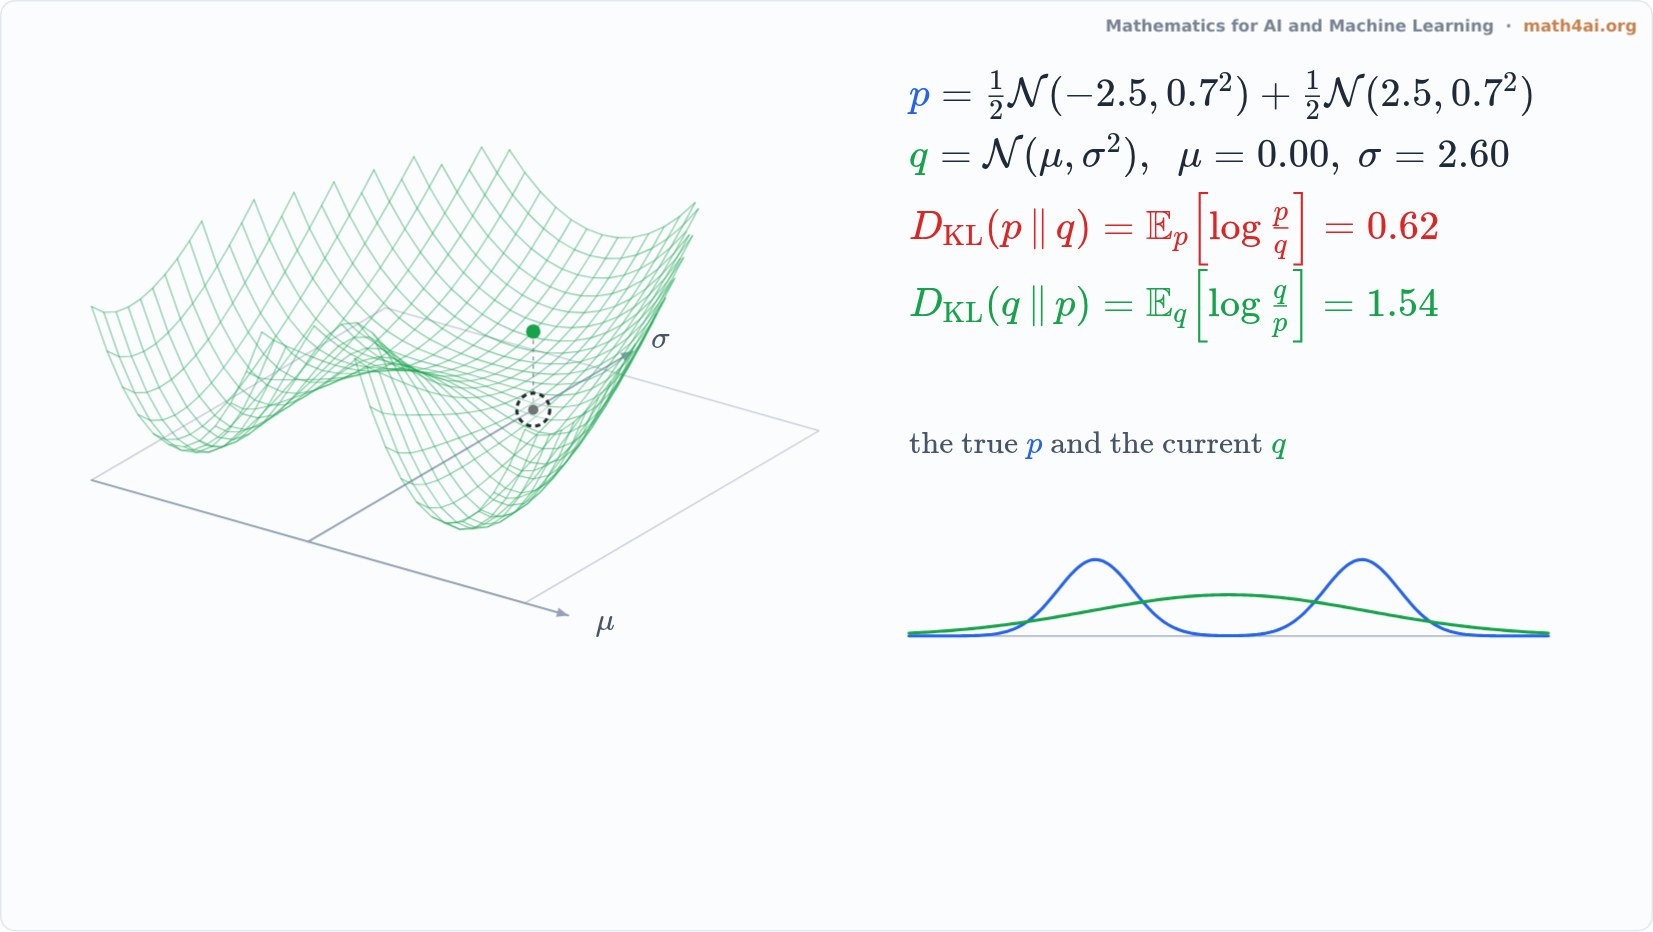 Interactive1:42KL Divergence: Two Orders, Two Different FitsChapter 14
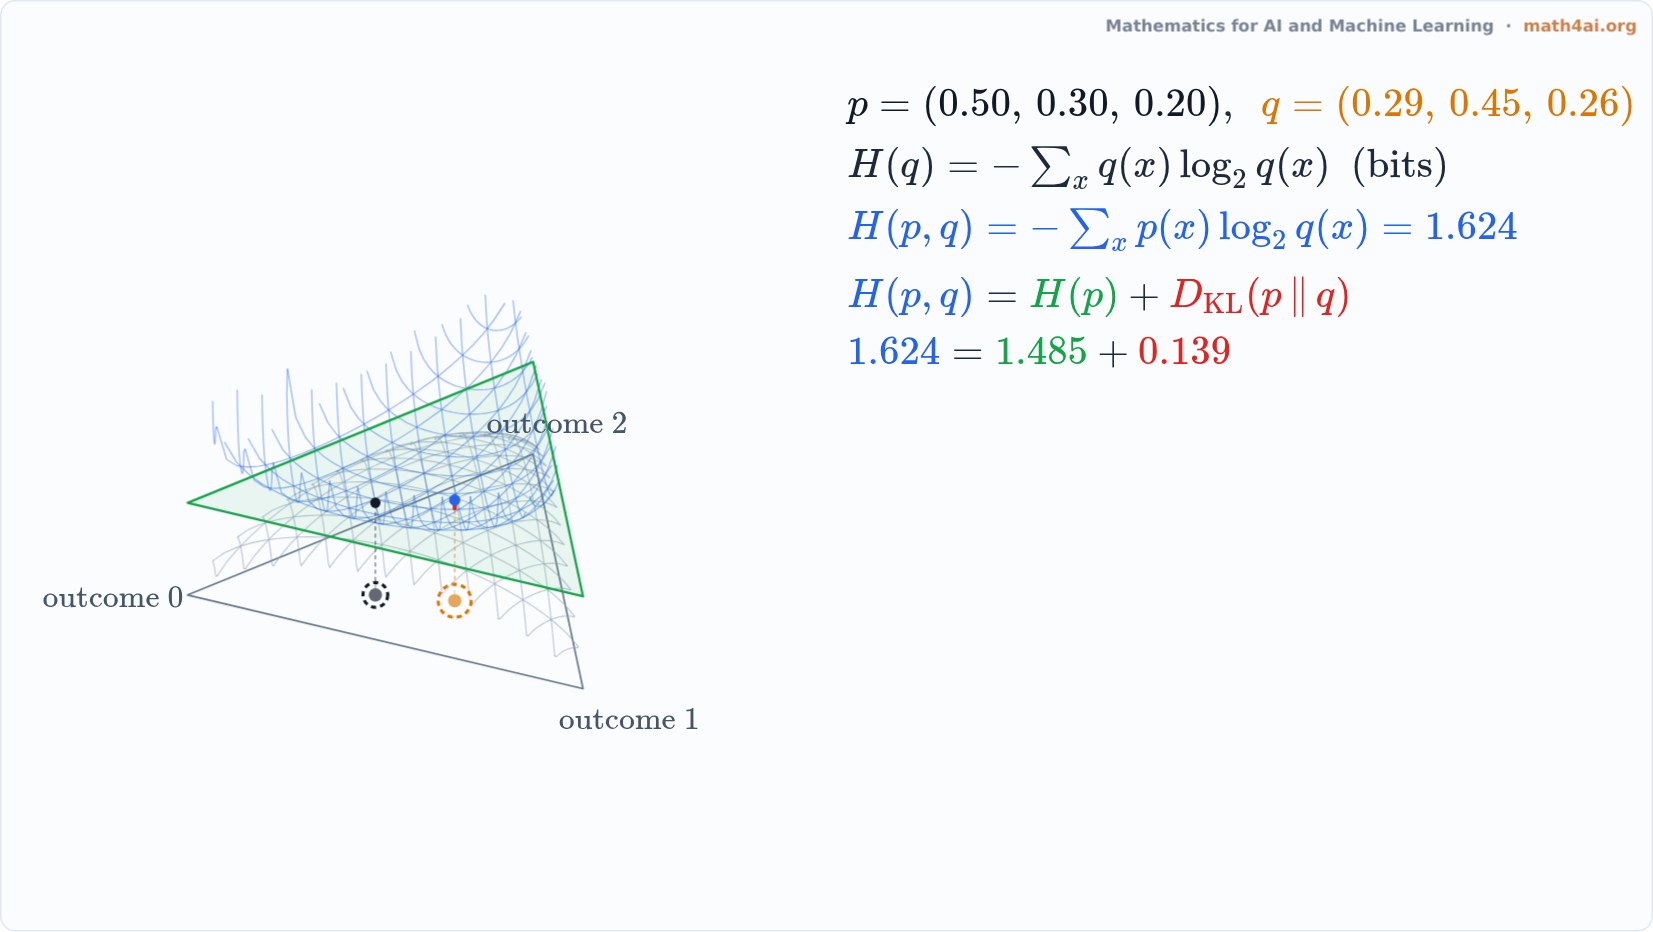 Preview1:57Entropy, Cross-Entropy and KL: the Wasted BitsChapter 14
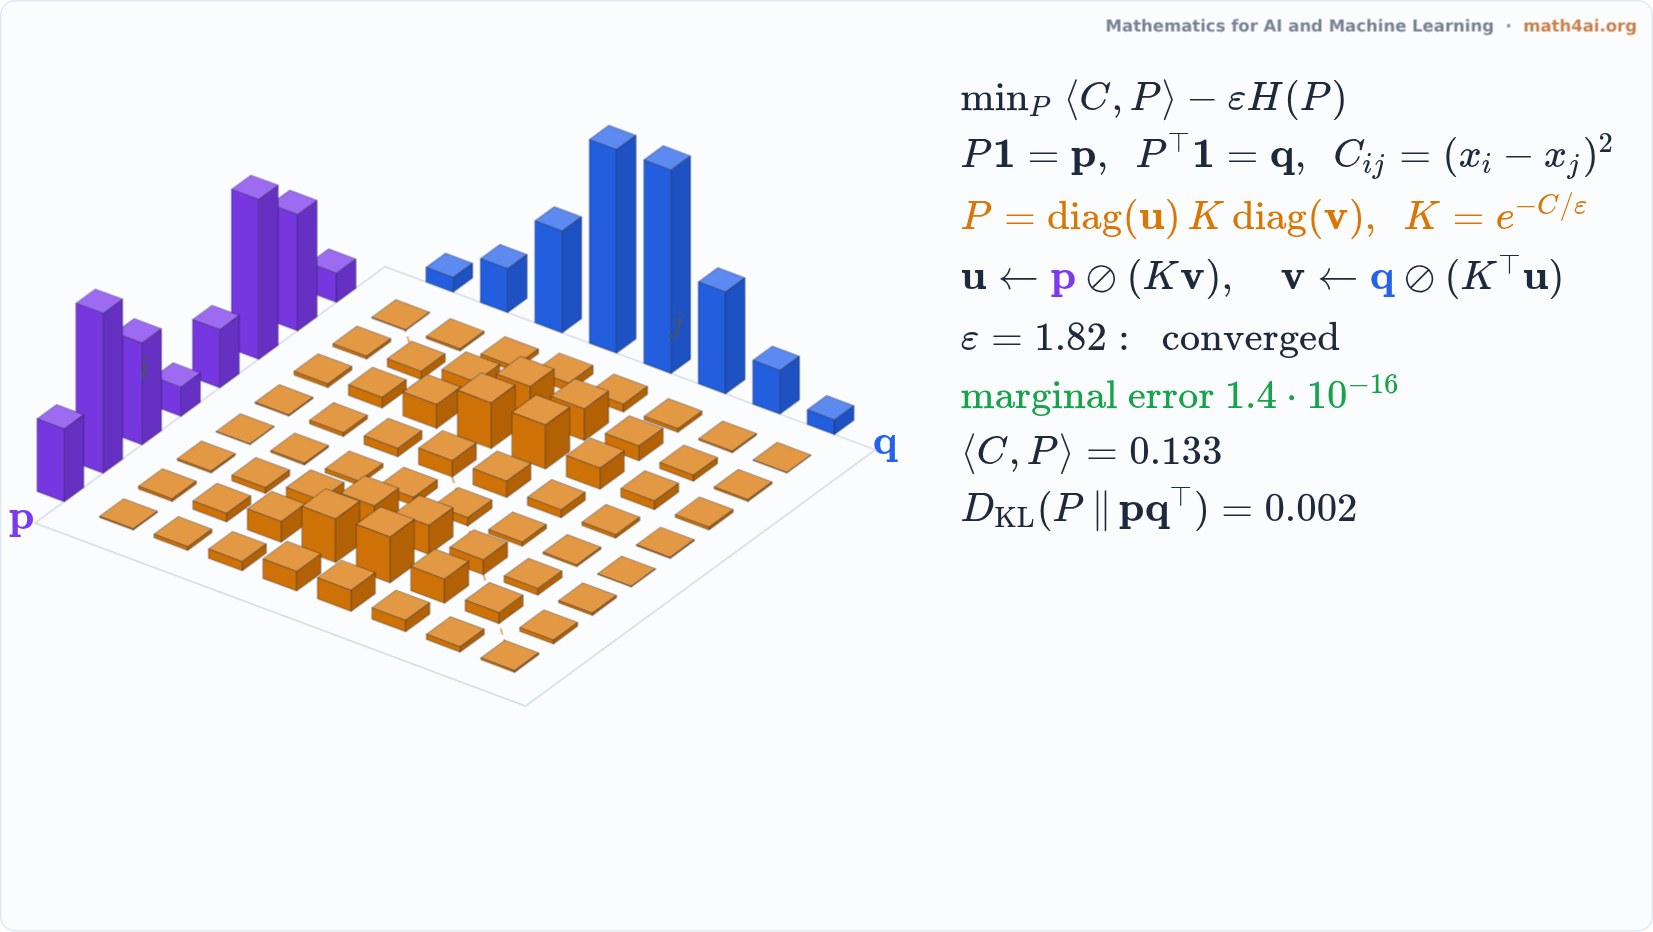 Preview1:38Entropic Optimal Transport and SinkhornChapter 14
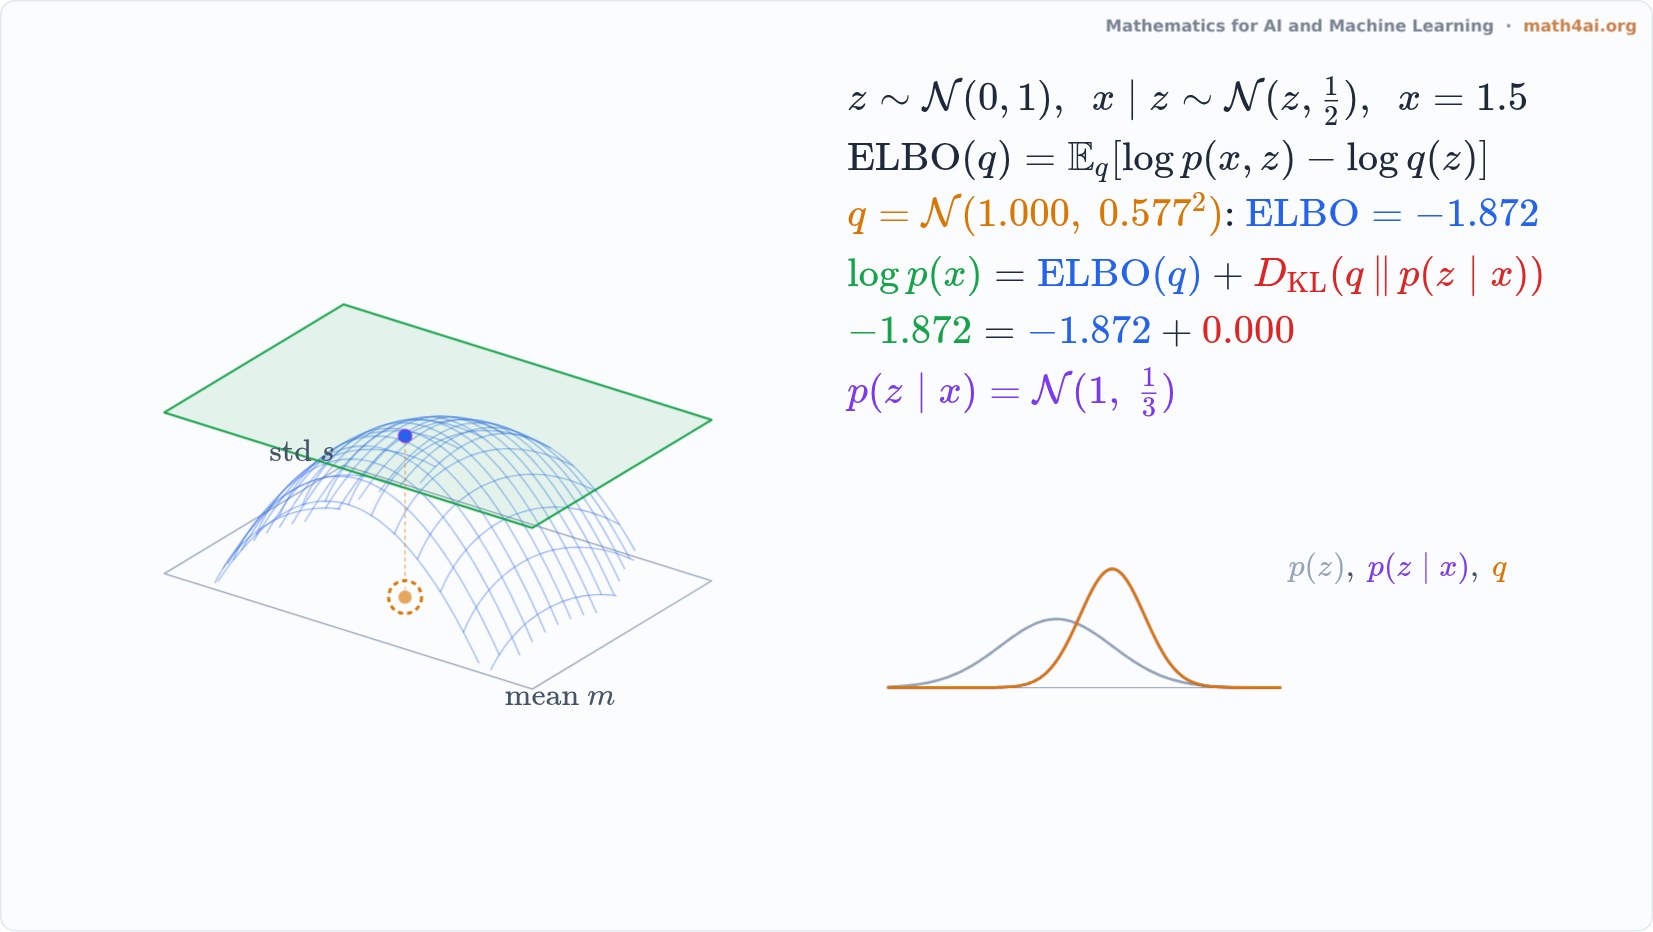 Preview1:58The ELBO: a Hill under the EvidenceChapter 14
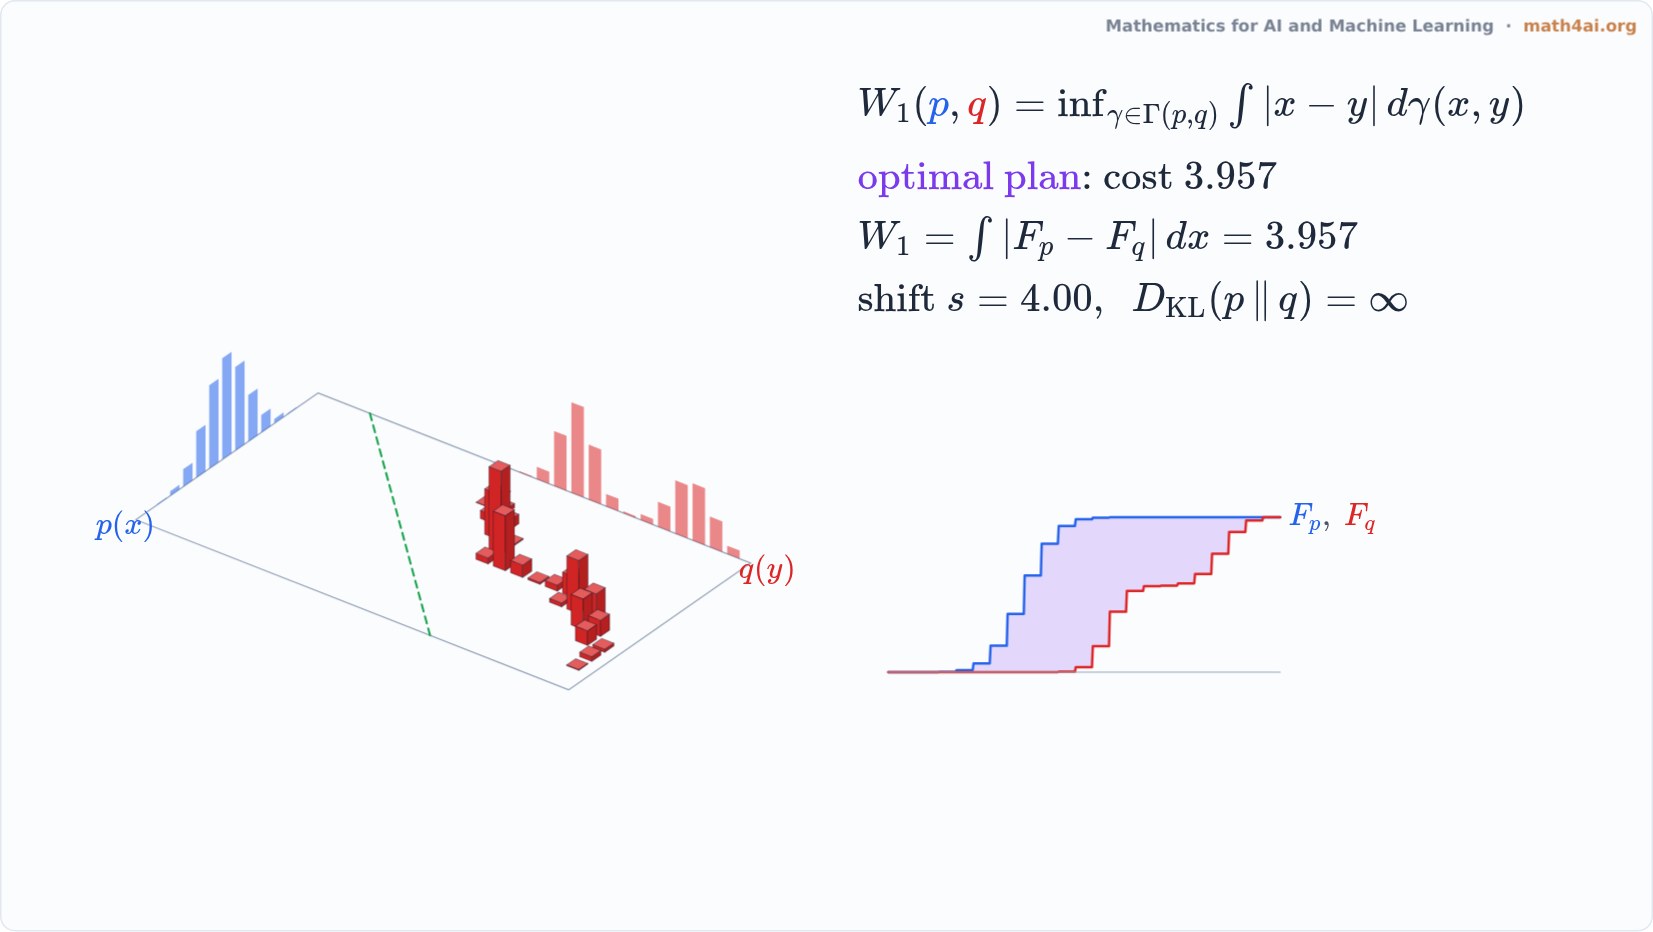 Preview1:45Wasserstein Distance: the Cheapest Way to Move the EarthChapter 14
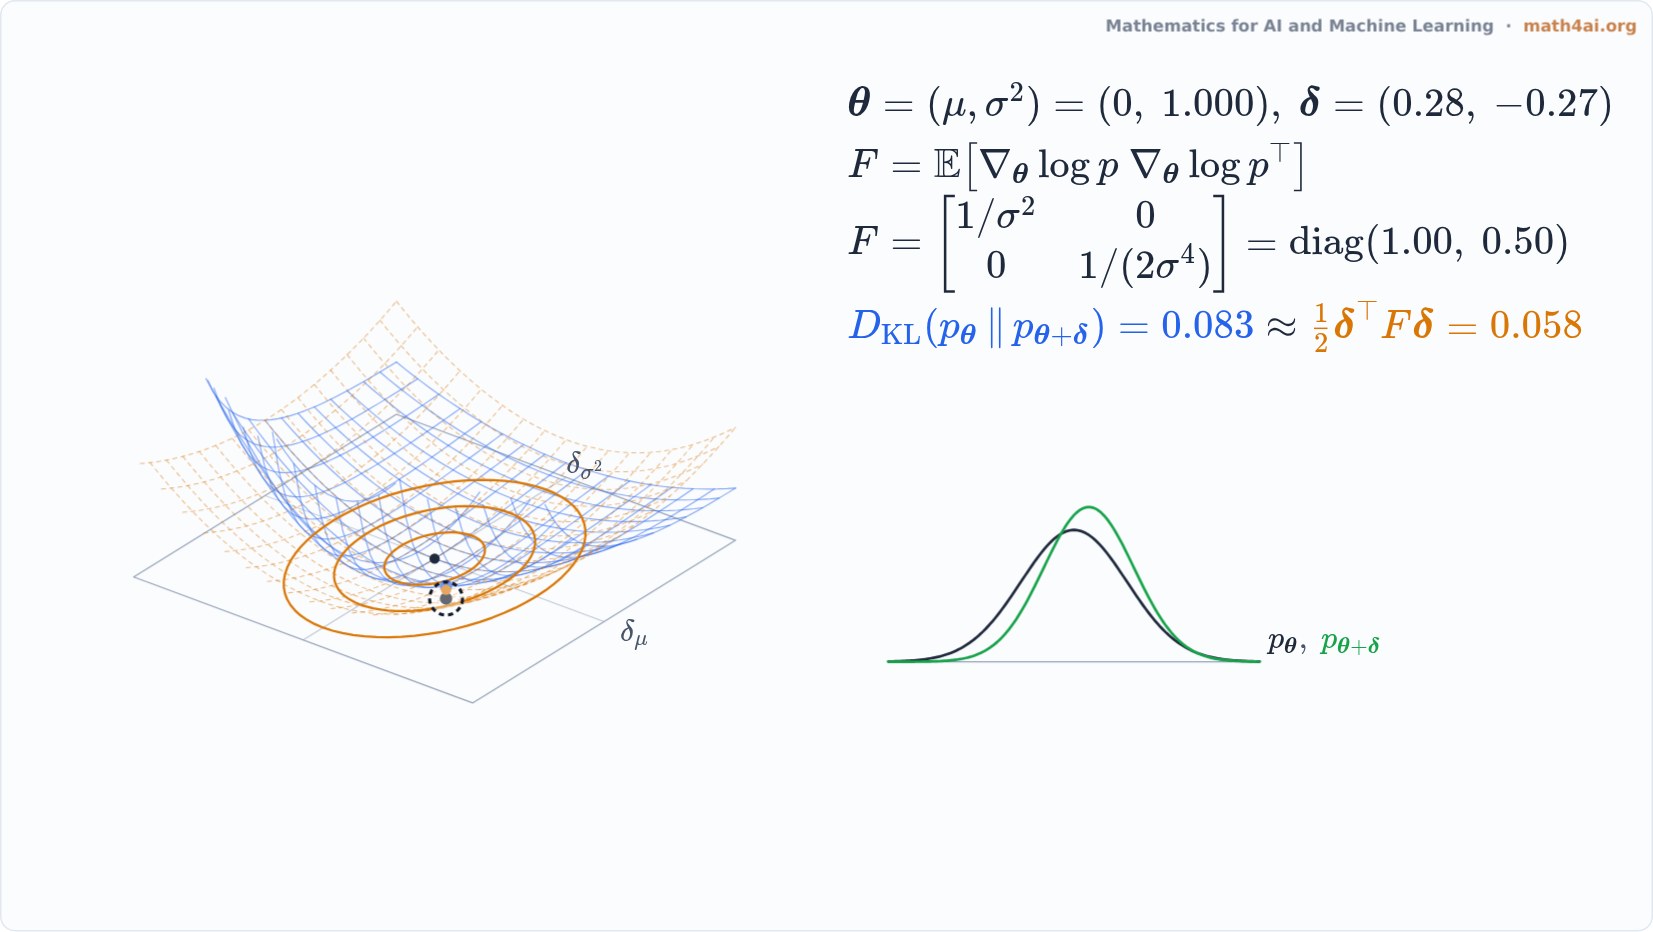 Preview2:04Fisher Information: the Curvature of KLChapter 14
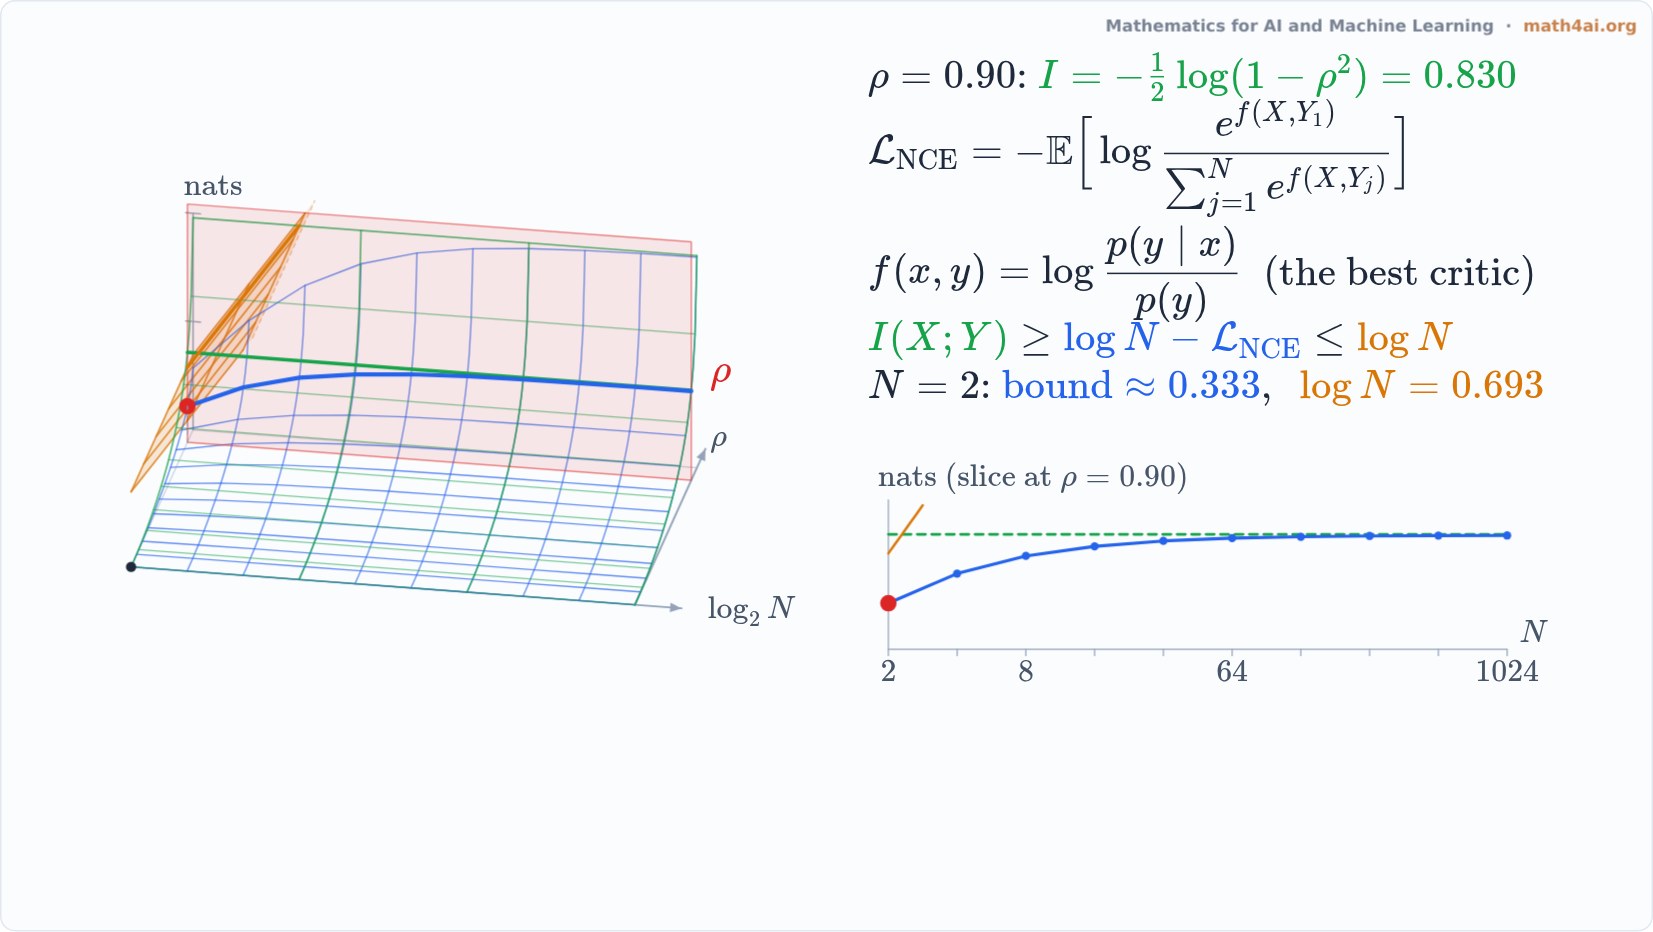 Preview1:53The InfoNCE BoundChapter 14
Chapter 15 Bellman Equations and Operators
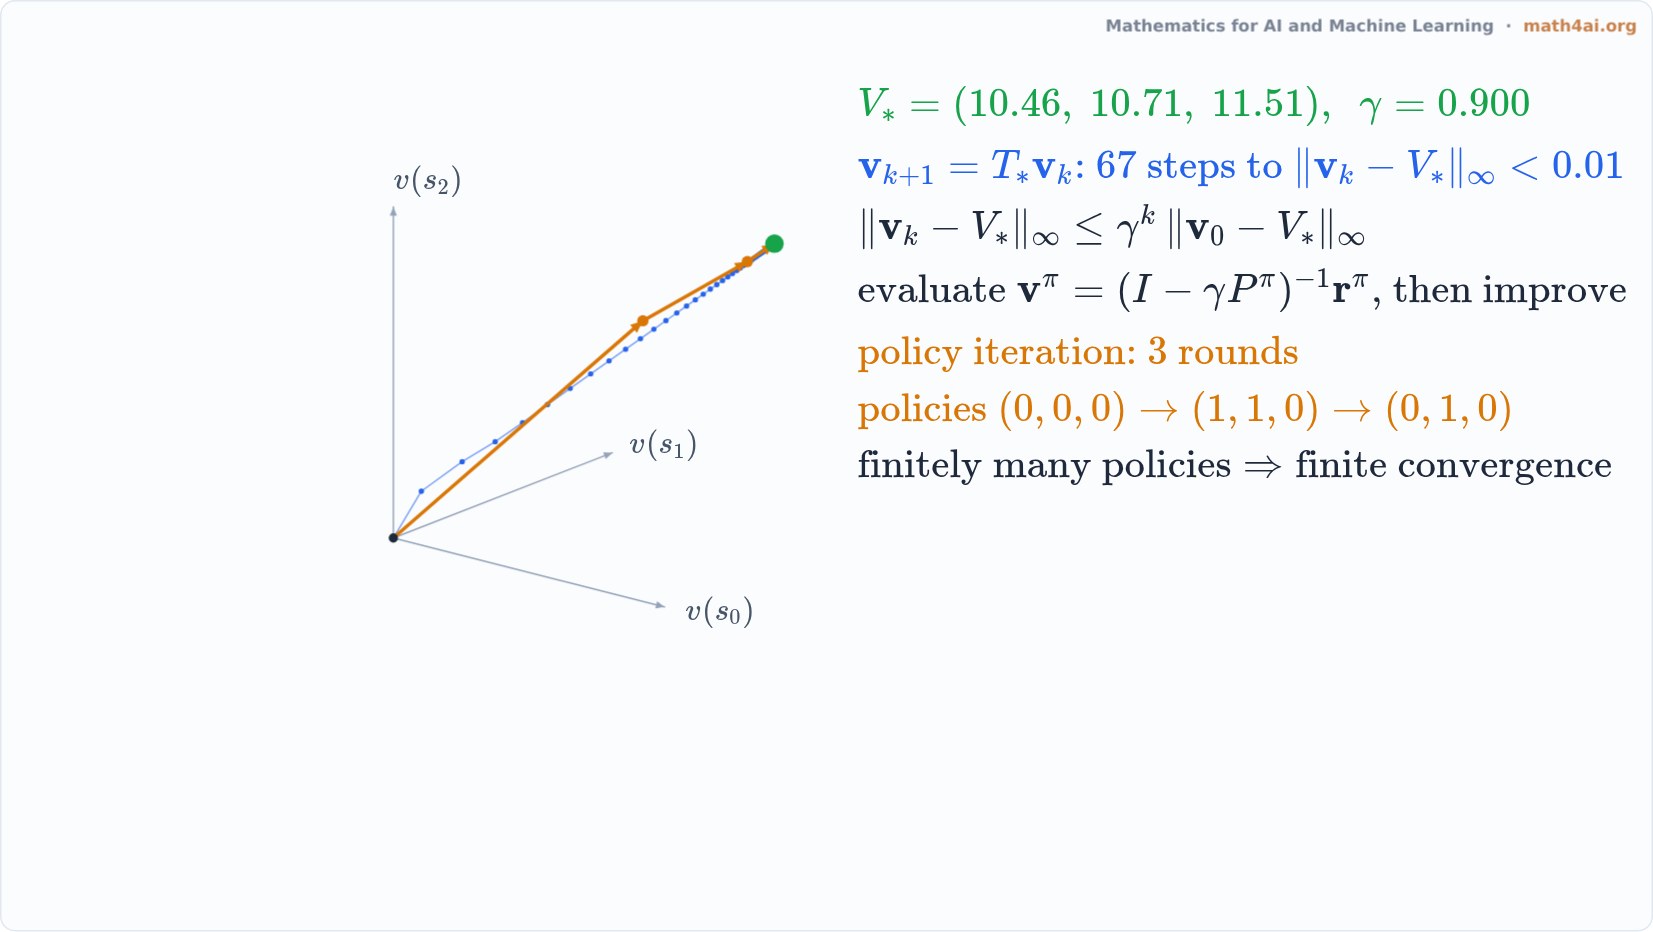 Interactive1:41Value Iteration and Policy Iteration: Many Small Steps or a Few Big JumpsChapter 15
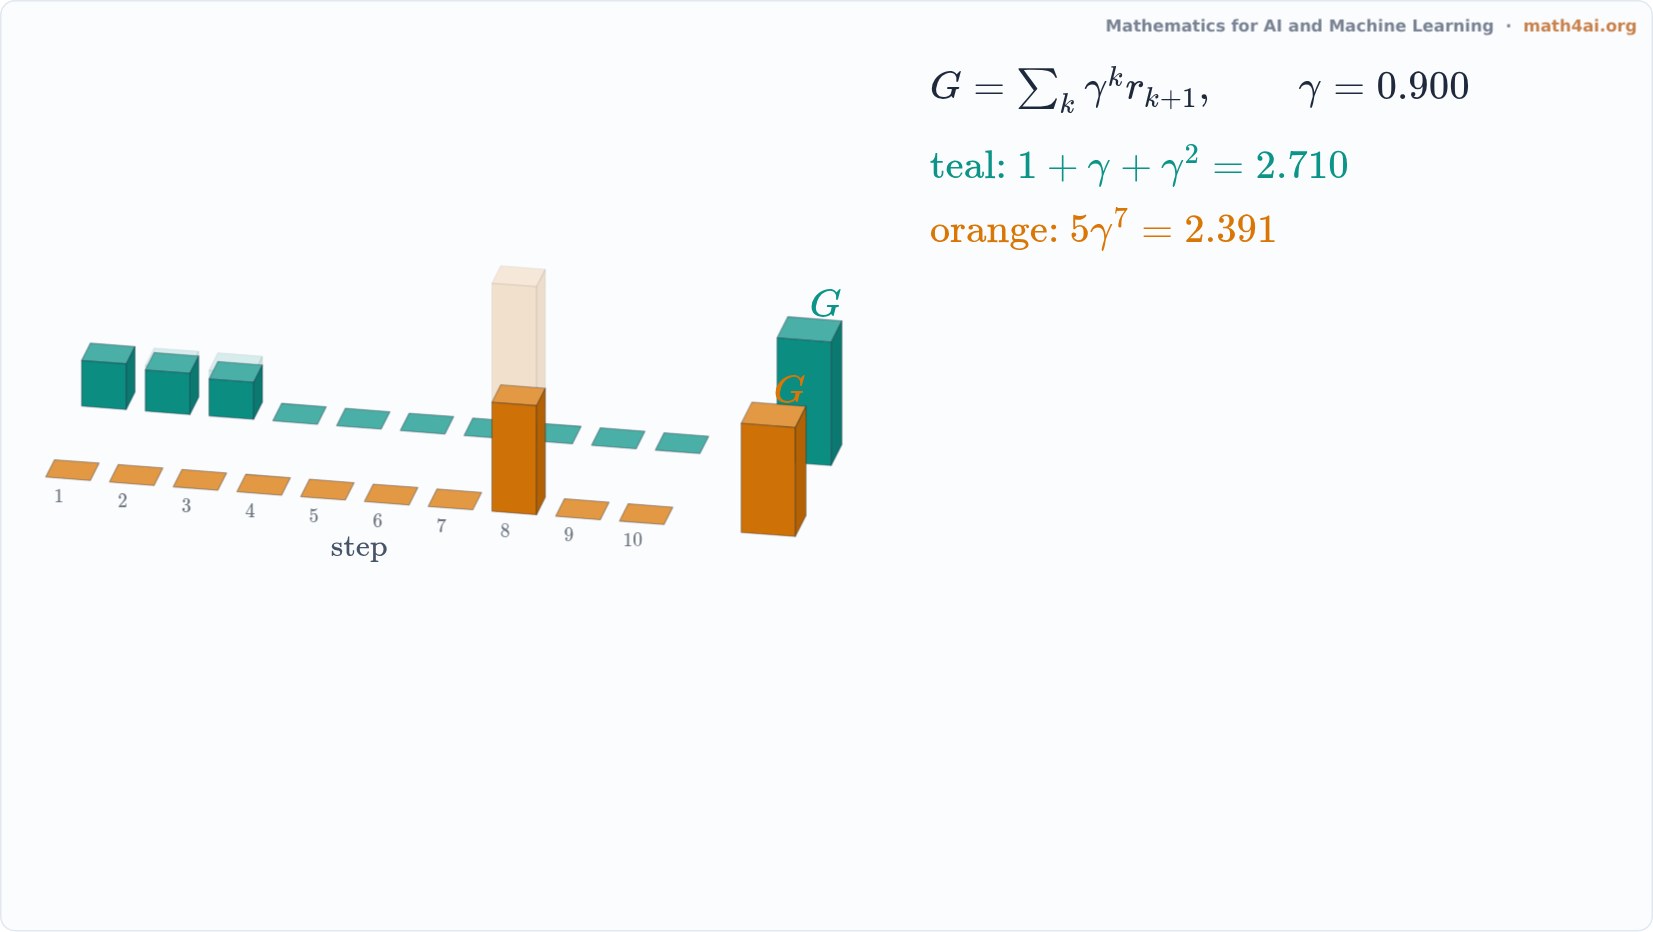 Preview1:32The Discounted Return: Now or LaterChapter 15
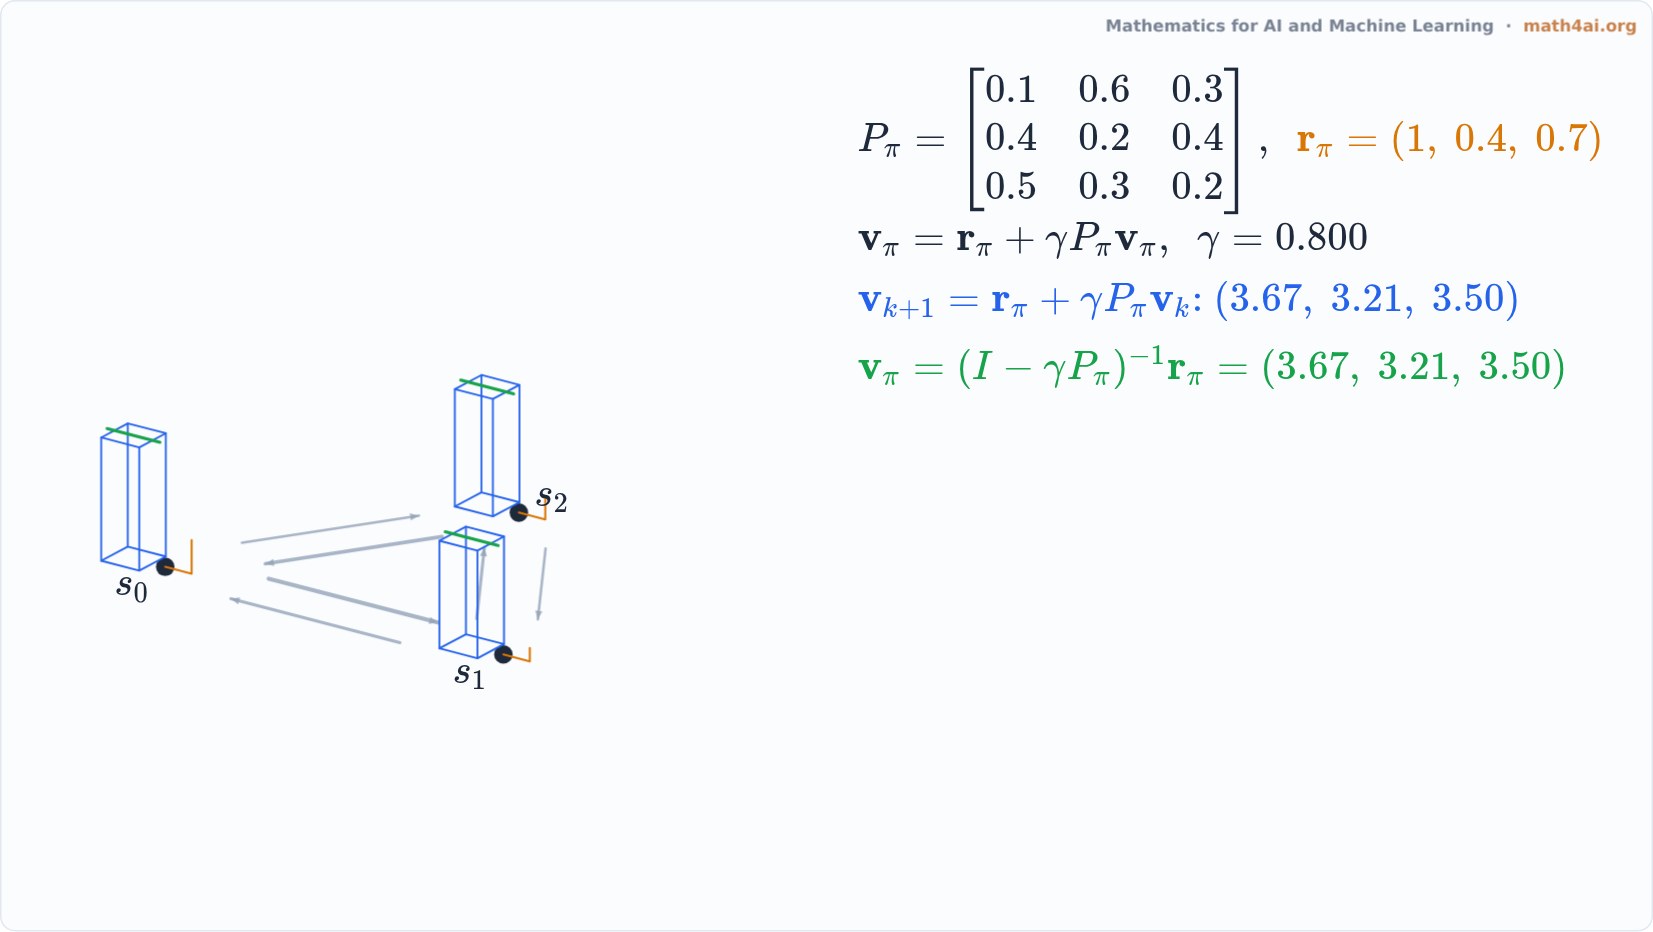 Preview1:39The Bellman Equation as a Linear SystemChapter 15
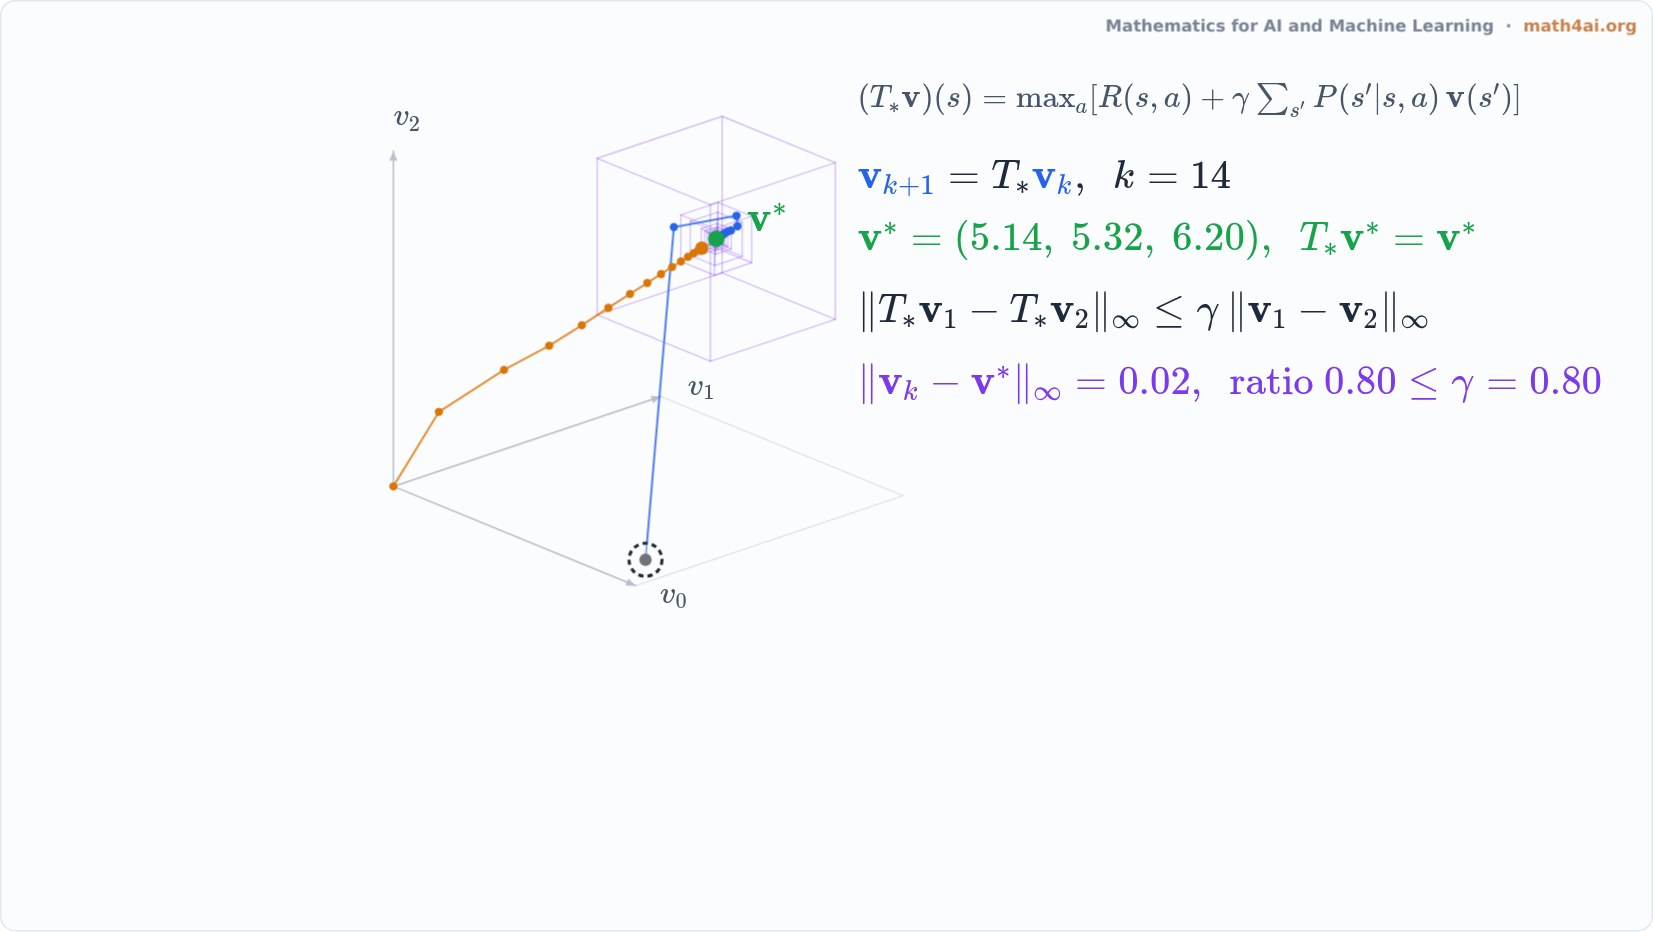 Preview1:49Bellman Operator: A Contraction With One Fixed PointChapter 15
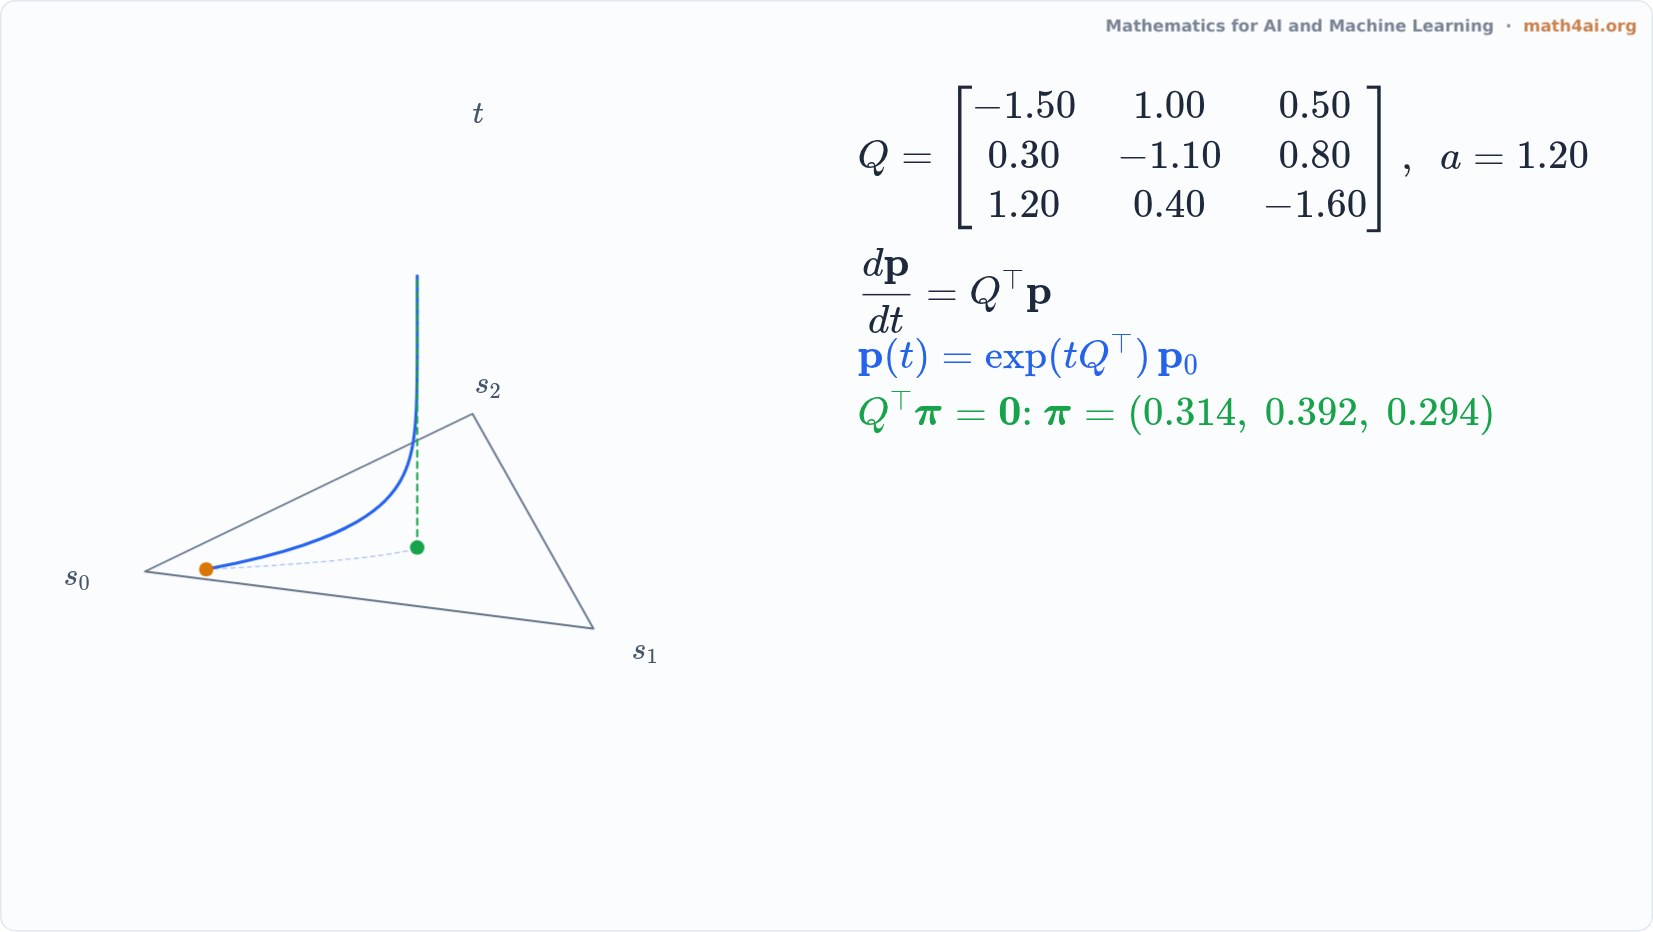 Preview1:34Continuous-Time Markov Chains: Probability Flowing on a TriangleChapter 15
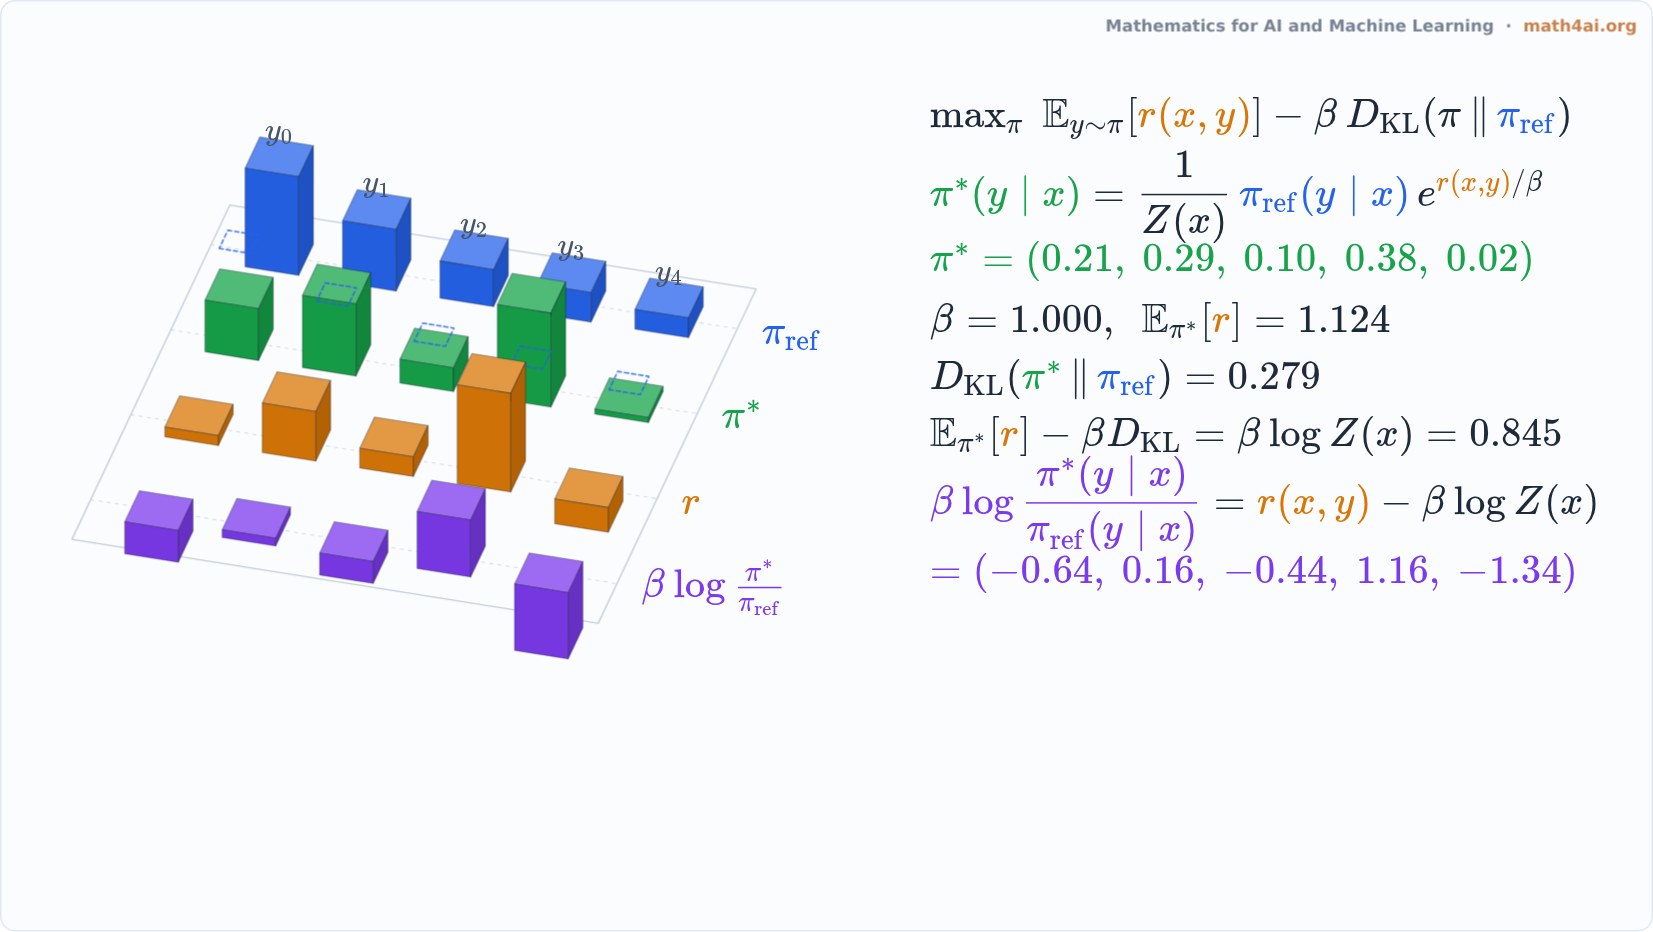 Preview1:58The KL-Regularized Optimal PolicyChapter 15
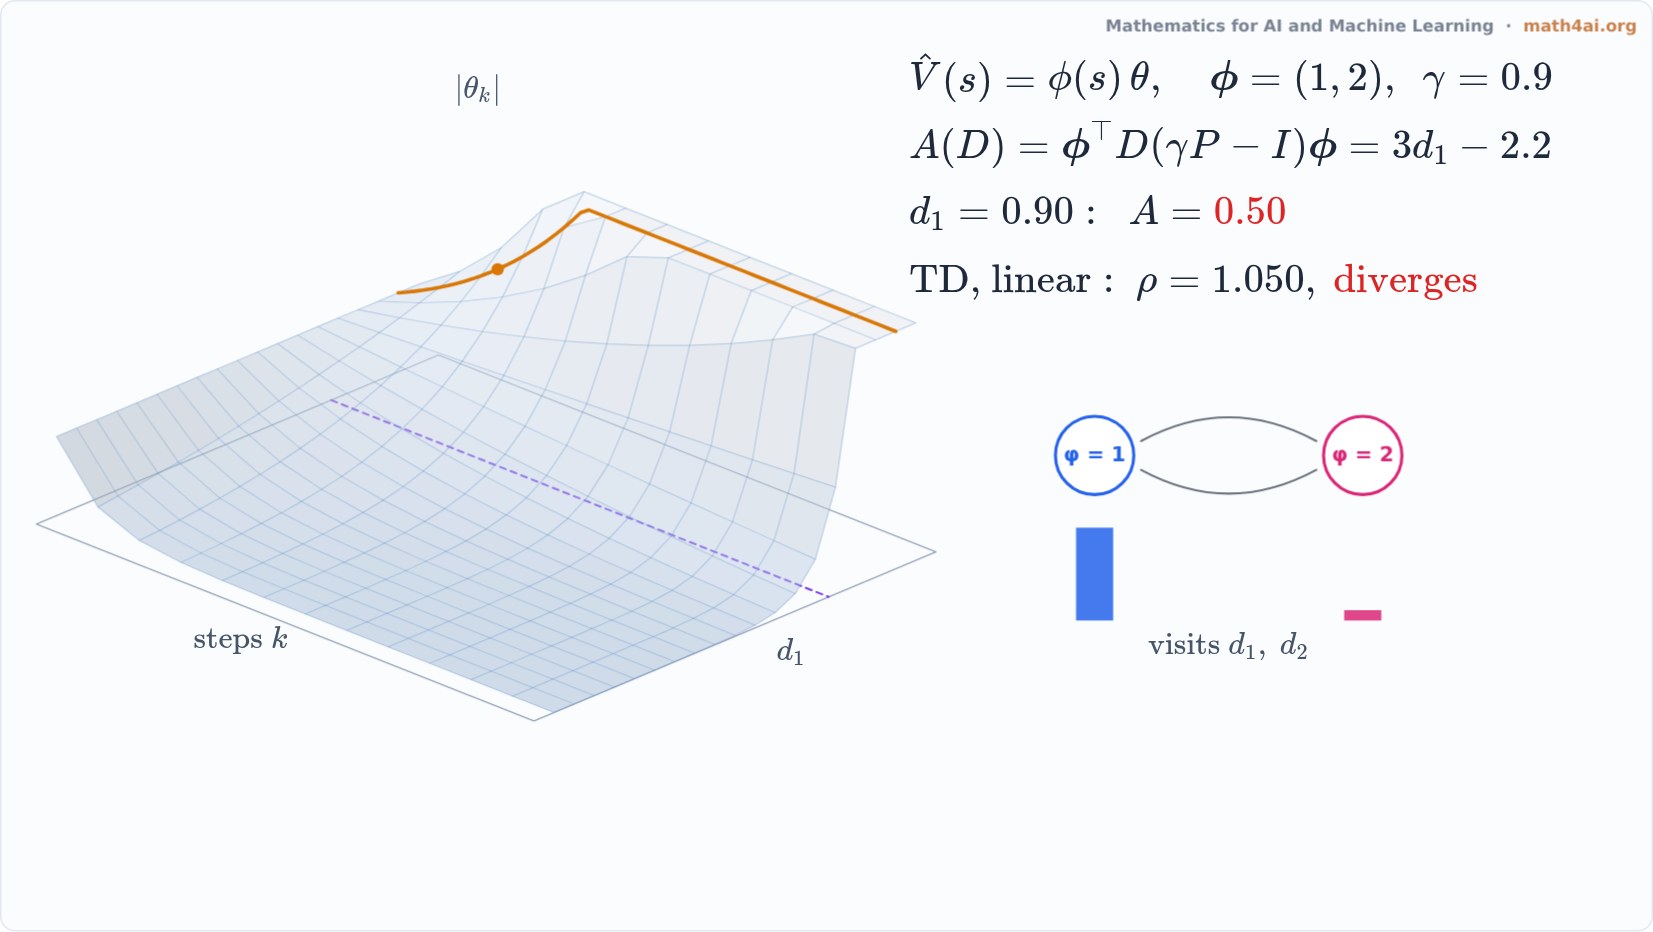 Preview1:51The Deadly Triad: When TD Learning ExplodesChapter 15
Chapter 16 Variational Inference and Latent Variables
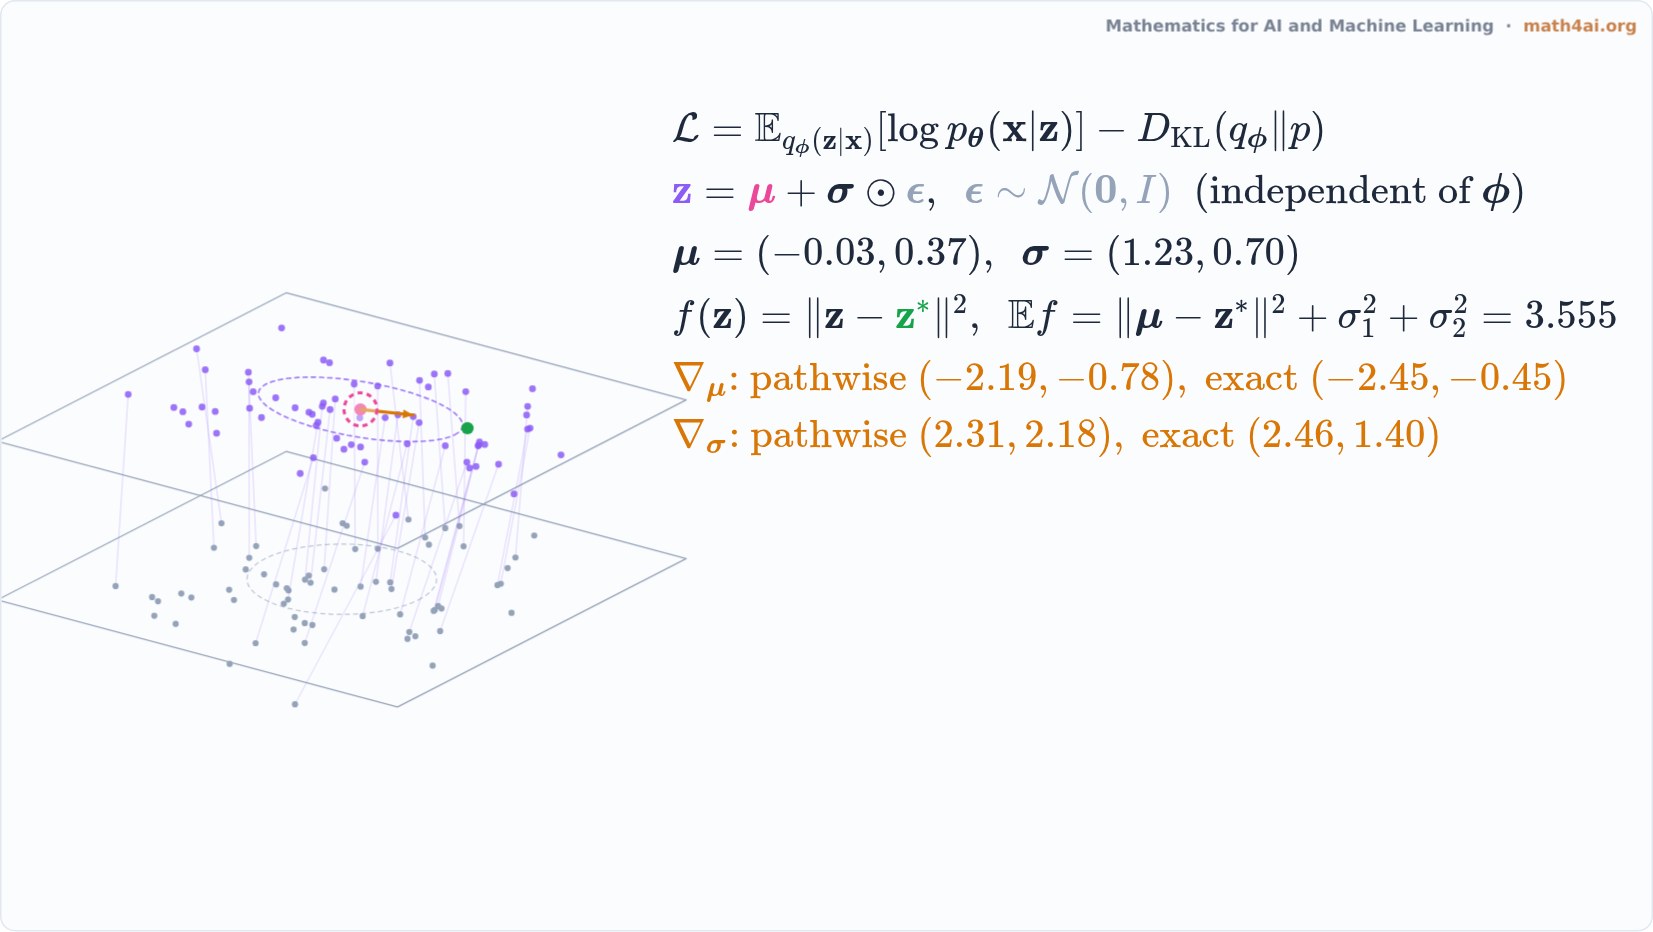 Interactive1:46The Reparameterization Trick: Differentiable SamplingChapter 16
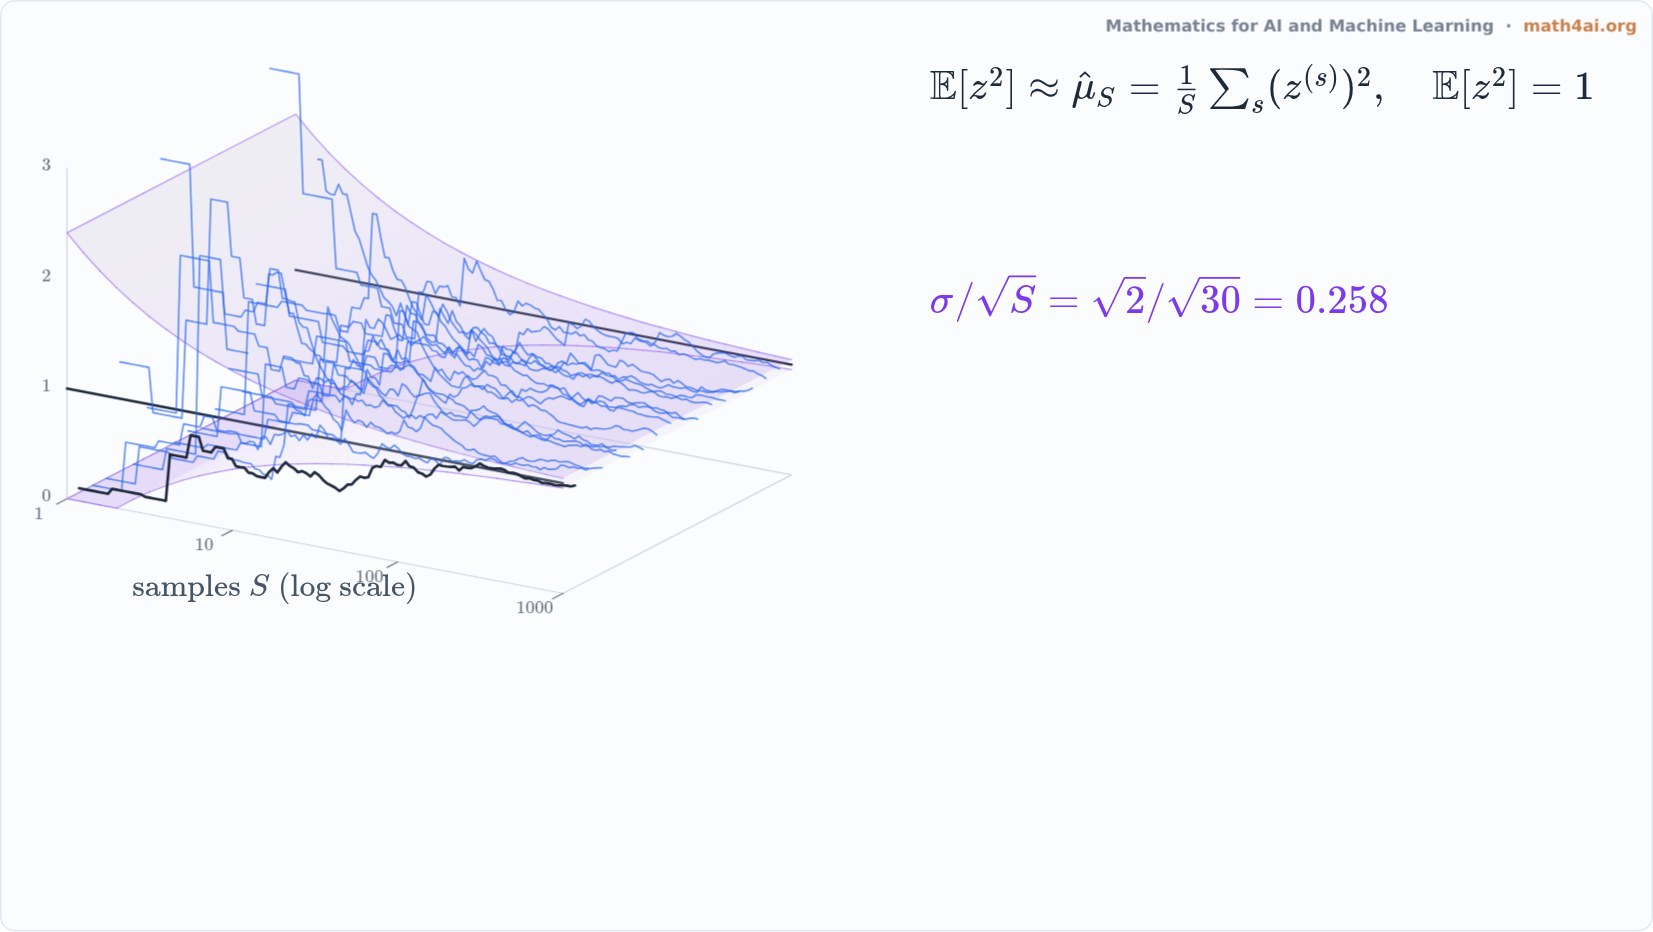 Preview1:27Monte Carlo: Averages That Close In Like a FunnelChapter 16
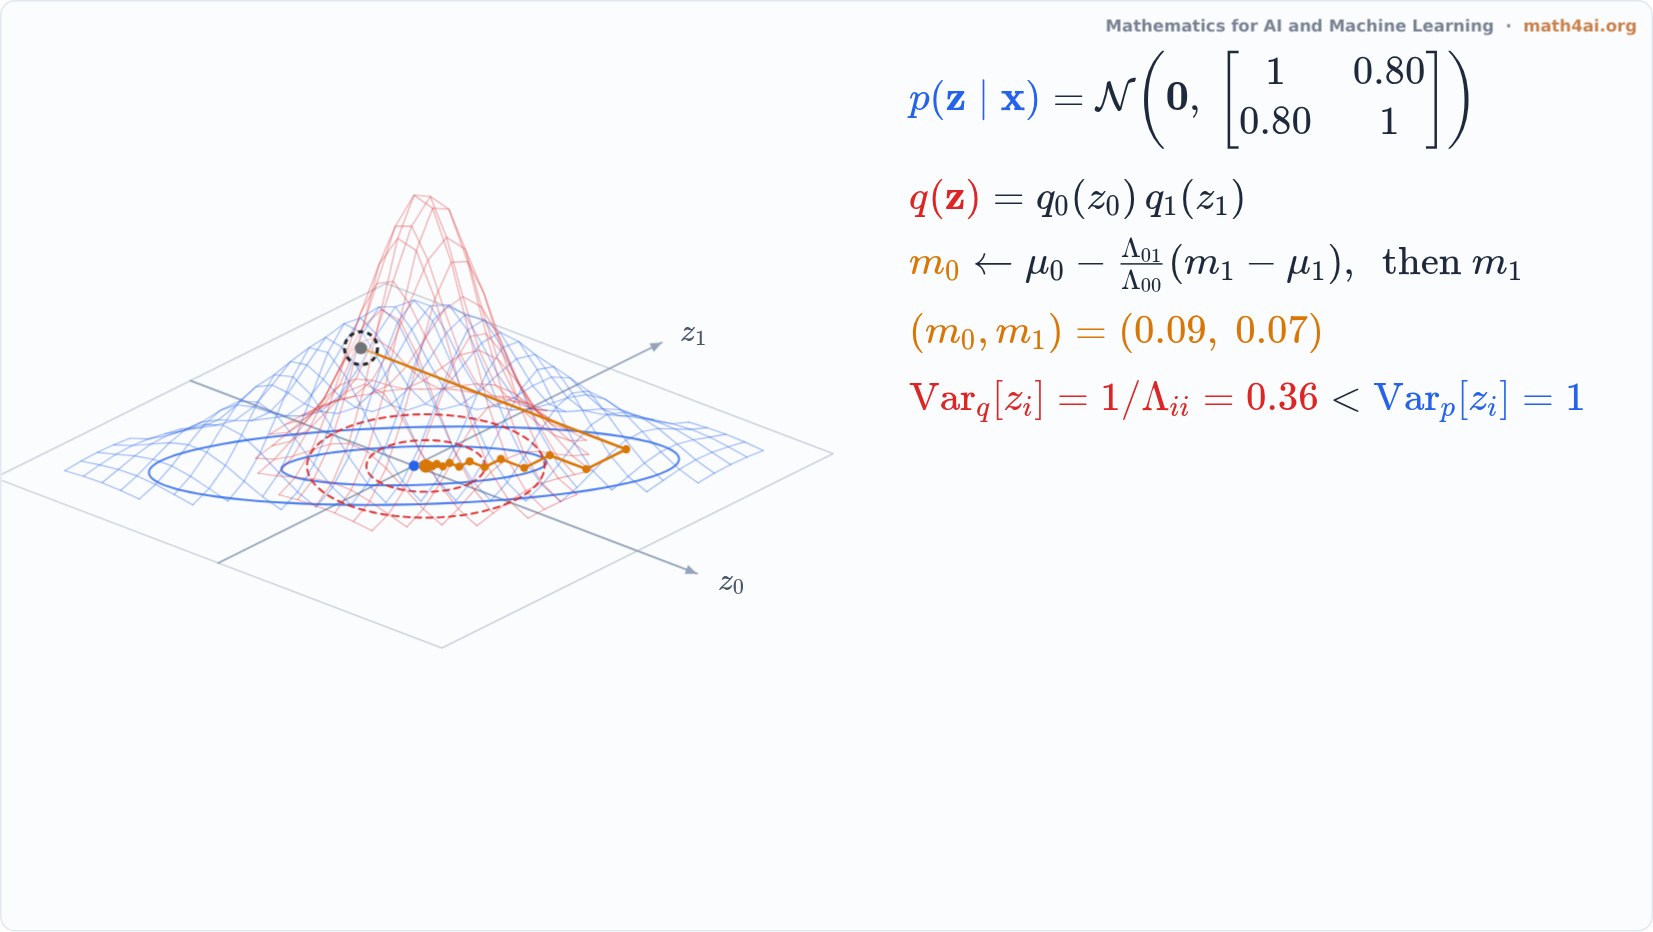 Preview1:42Mean Field: Independent Factors for a Correlated PosteriorChapter 16
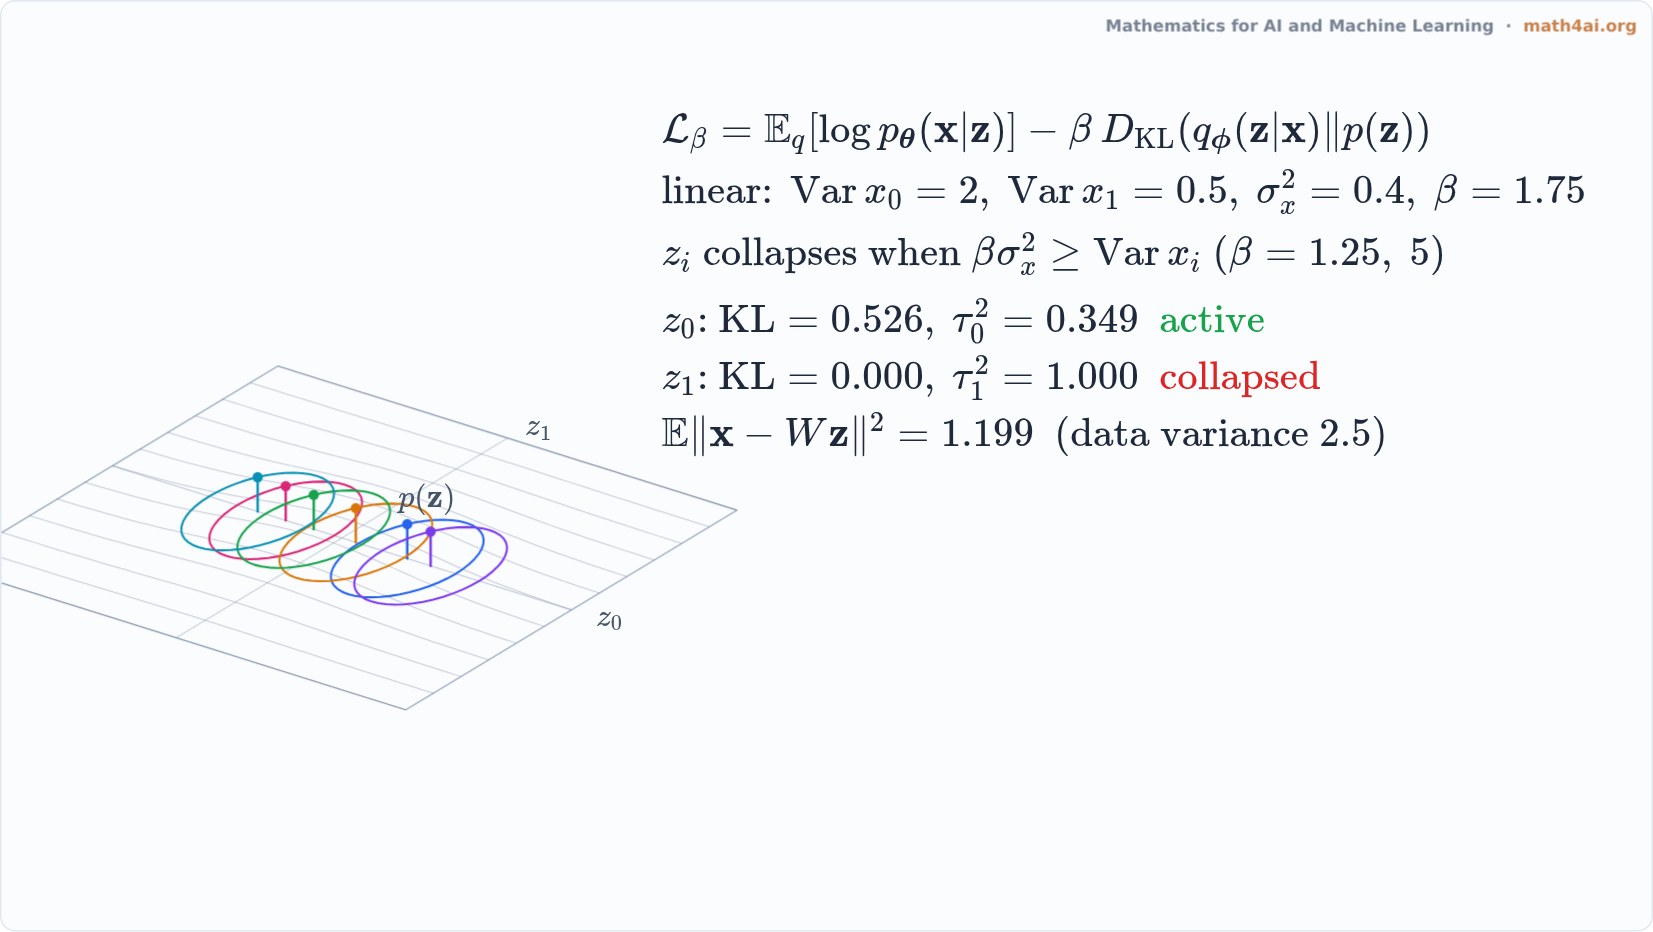 Preview1:45Posterior Collapse: When Latents Vanish into the PriorChapter 16
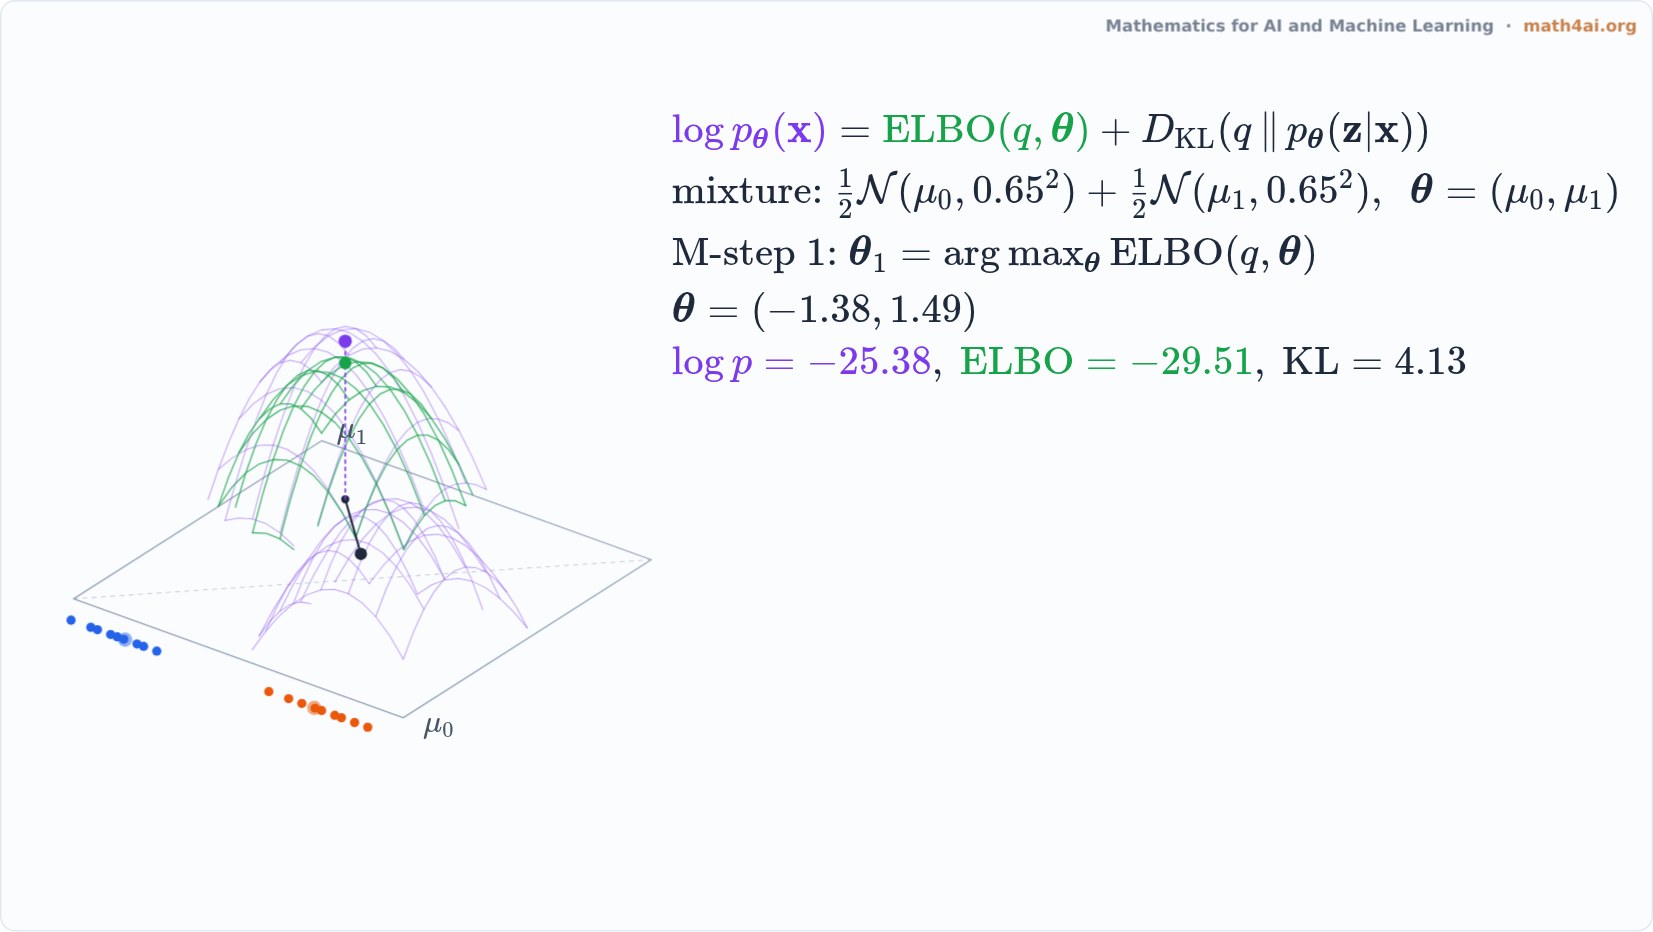 Preview1:36Expectation Maximization: Coordinate Ascent on the Lower BoundChapter 16
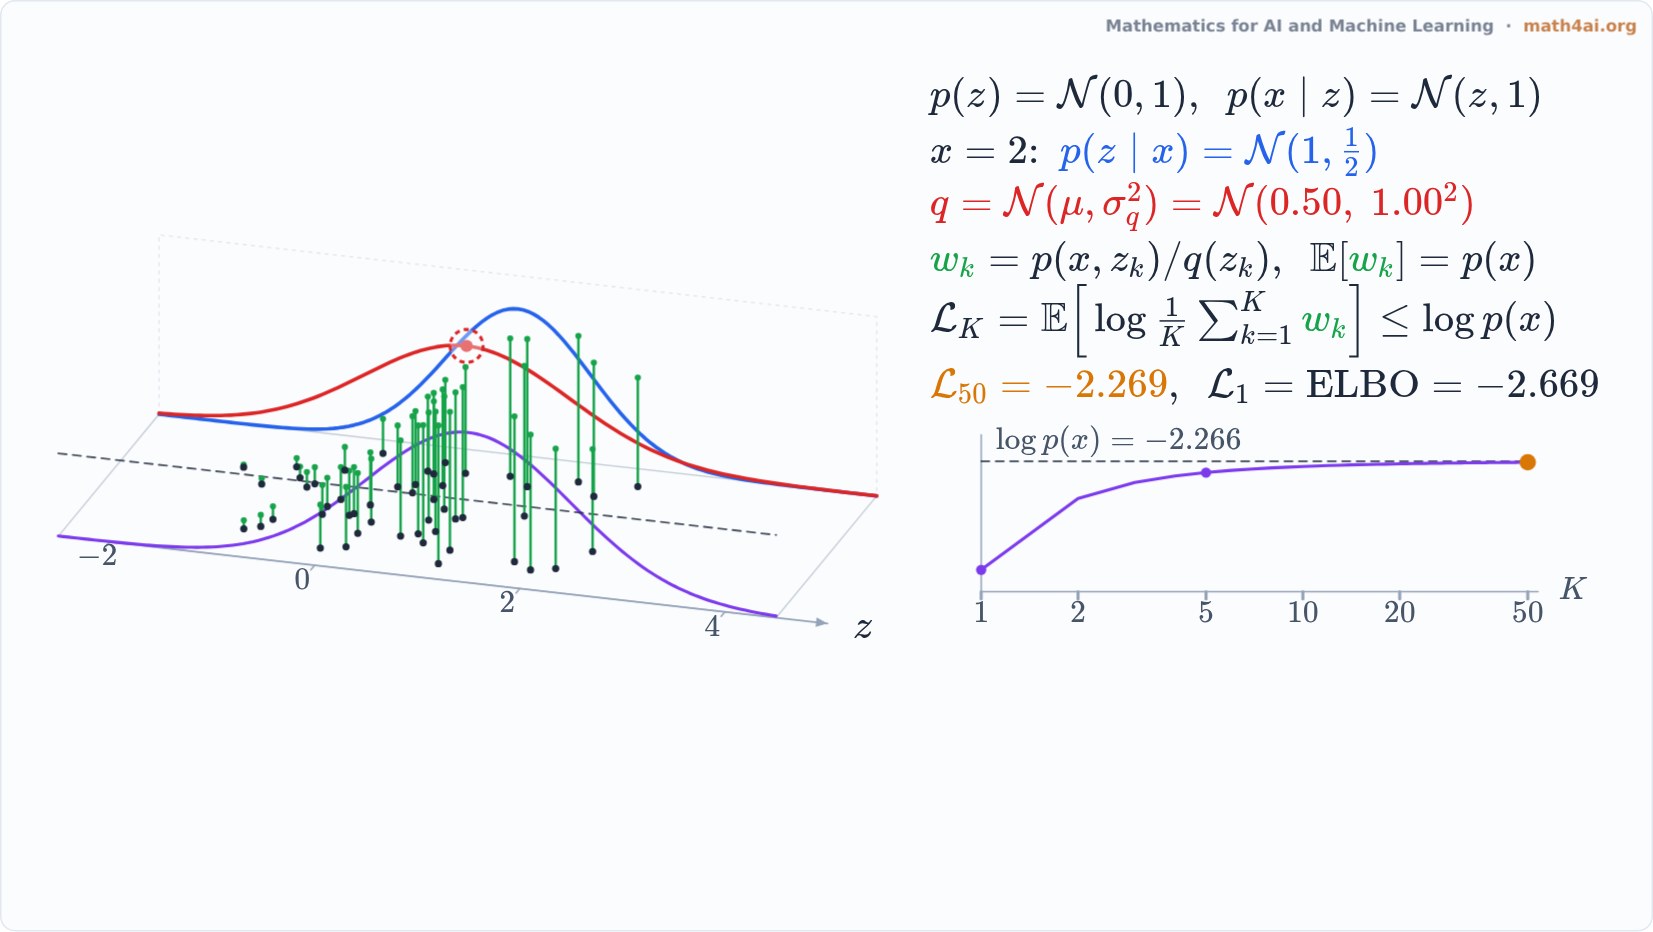 Preview1:55Importance-Weighted BoundsChapter 16
Chapter 17 Score Function and Energy-Based Models
Chapter 18 Langevin Dynamics and Sampling
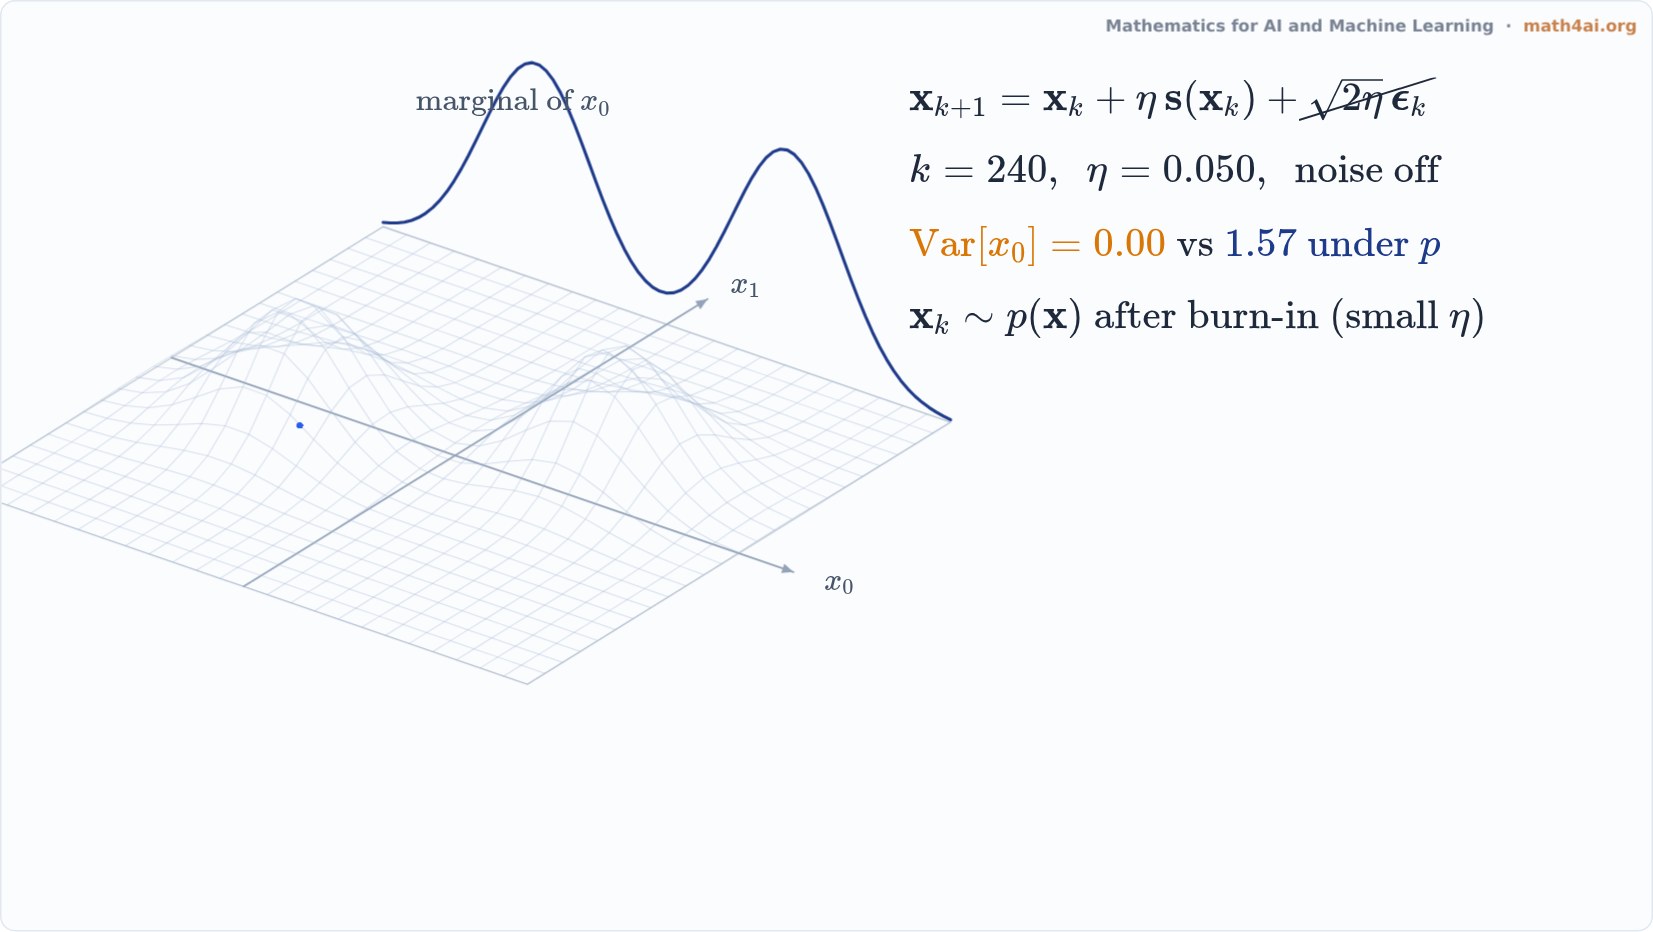 Interactive1:22Langevin Sampling: Drift Uphill, Kick at RandomChapter 18
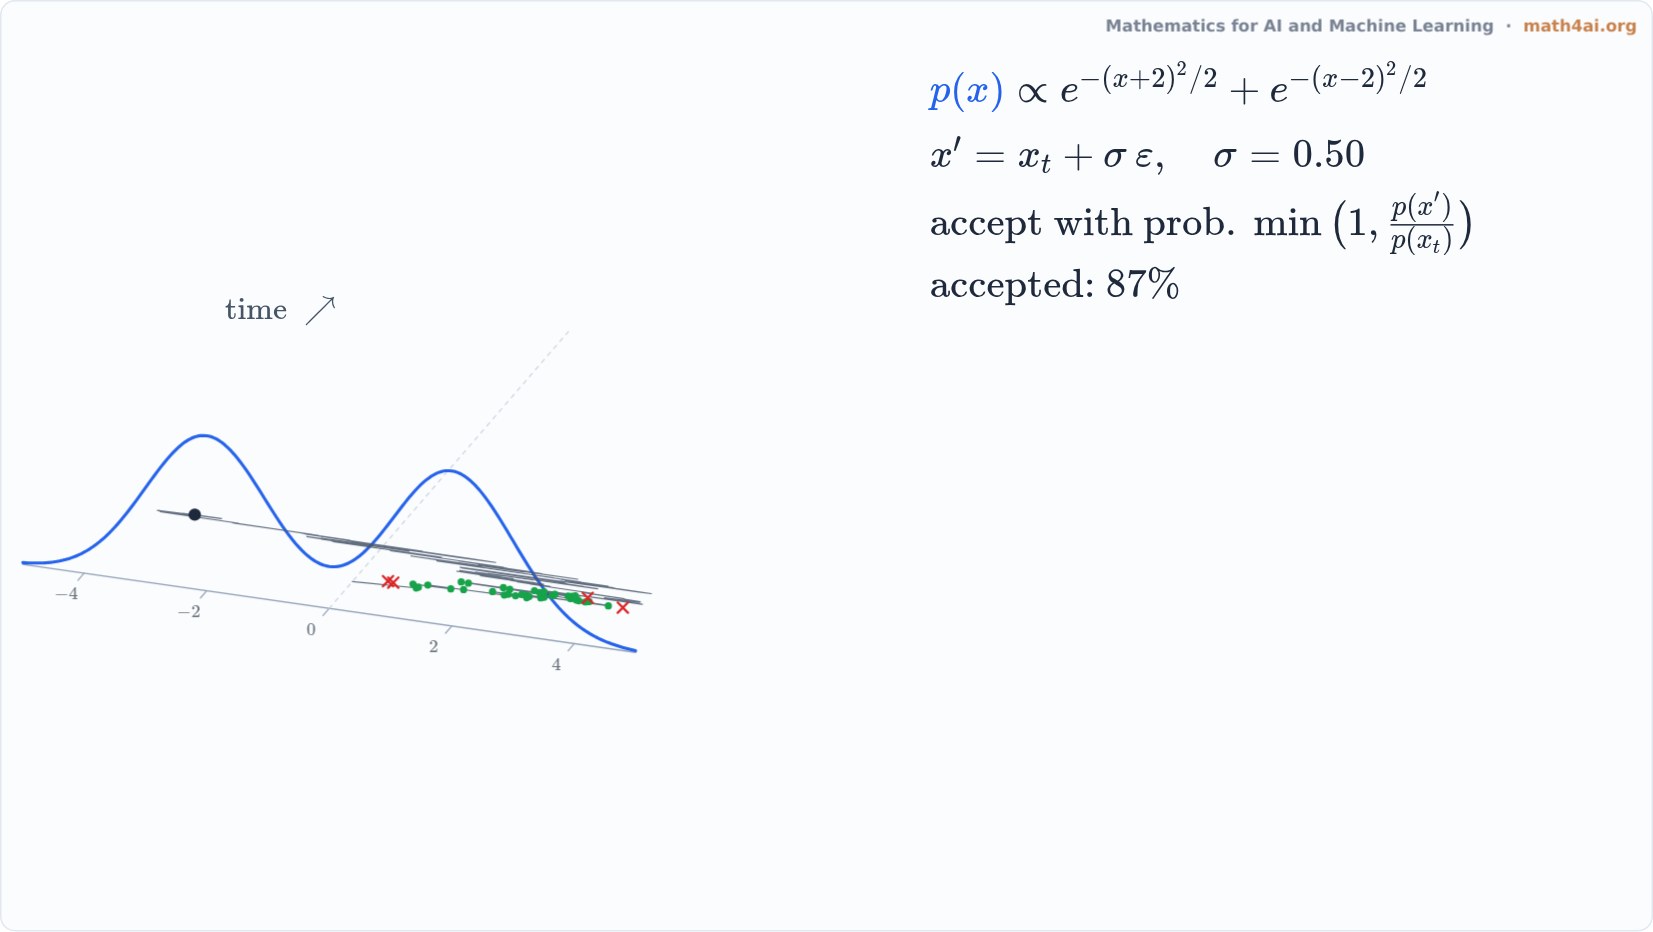 Preview1:24Metropolis-Hastings: A Random Walk That SamplesChapter 18
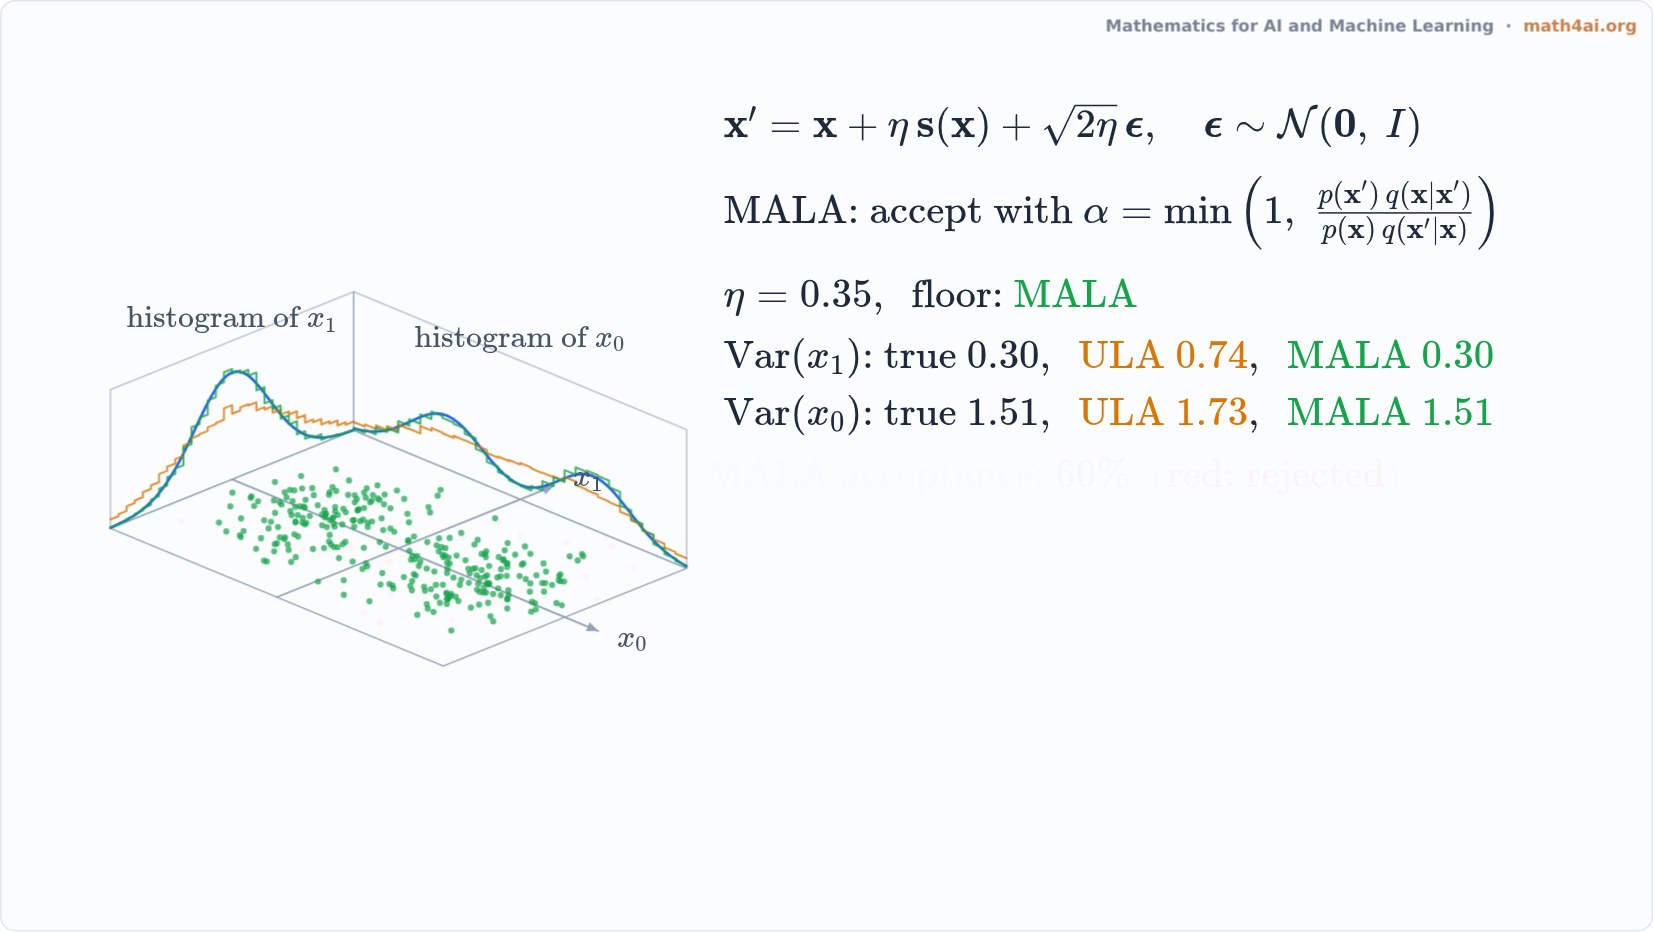 Preview1:42MALA: Removing Discretization Bias with Accept-RejectChapter 18
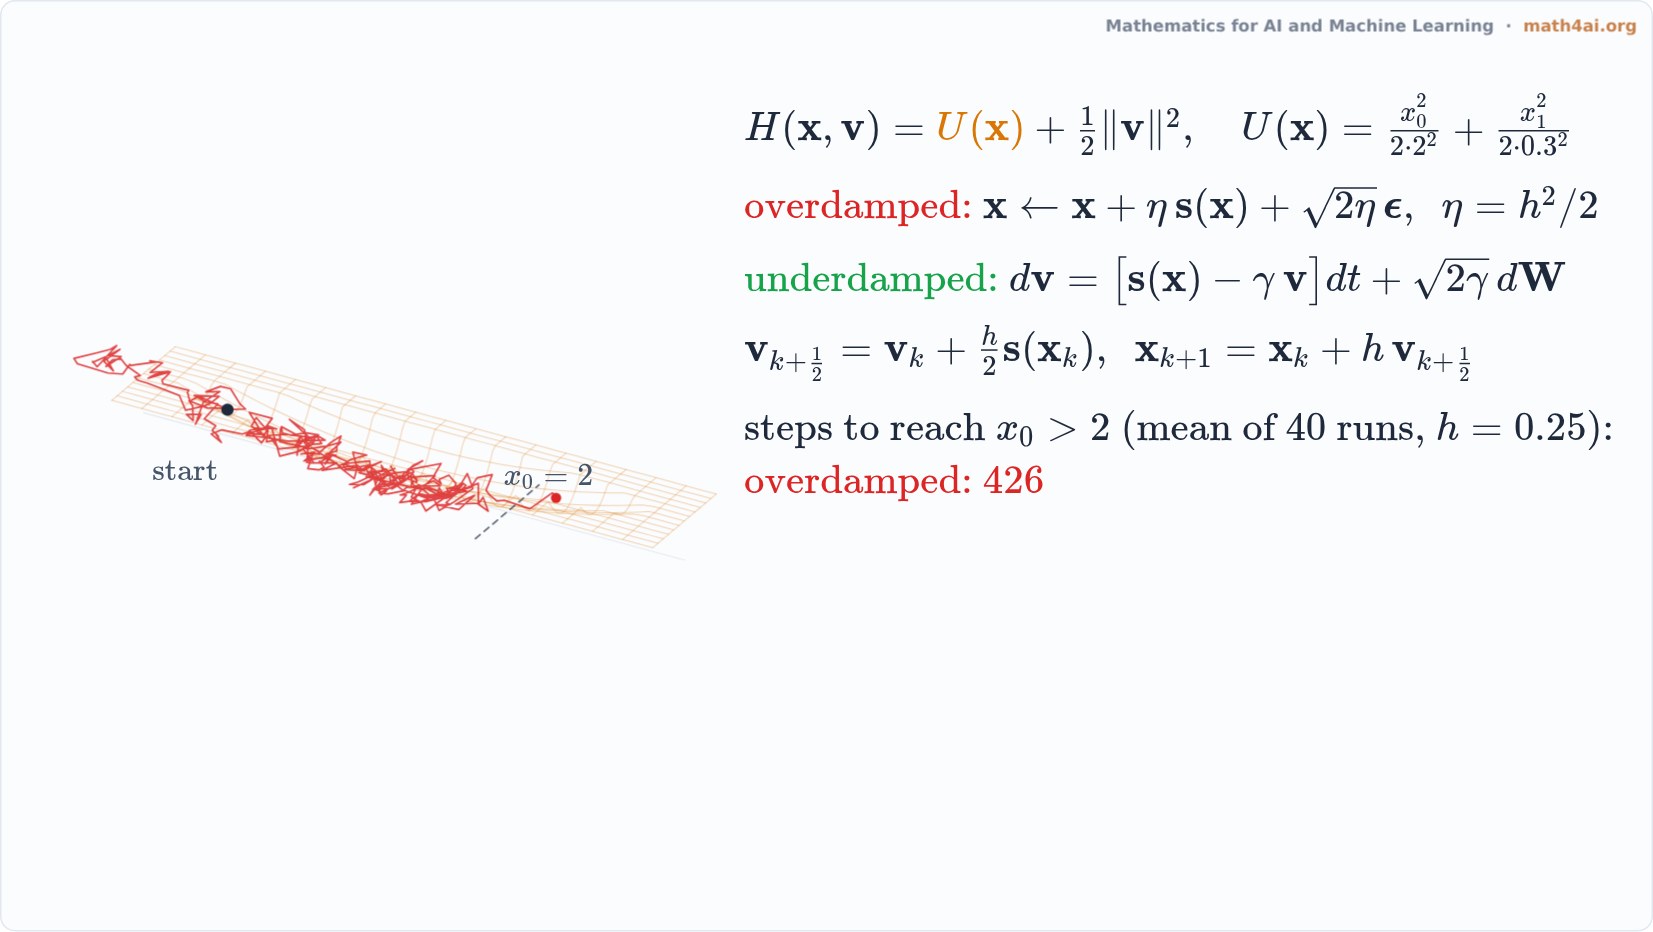 Preview1:40Underdamped Langevin and HMC: Momentum-Driven ExplorationChapter 18
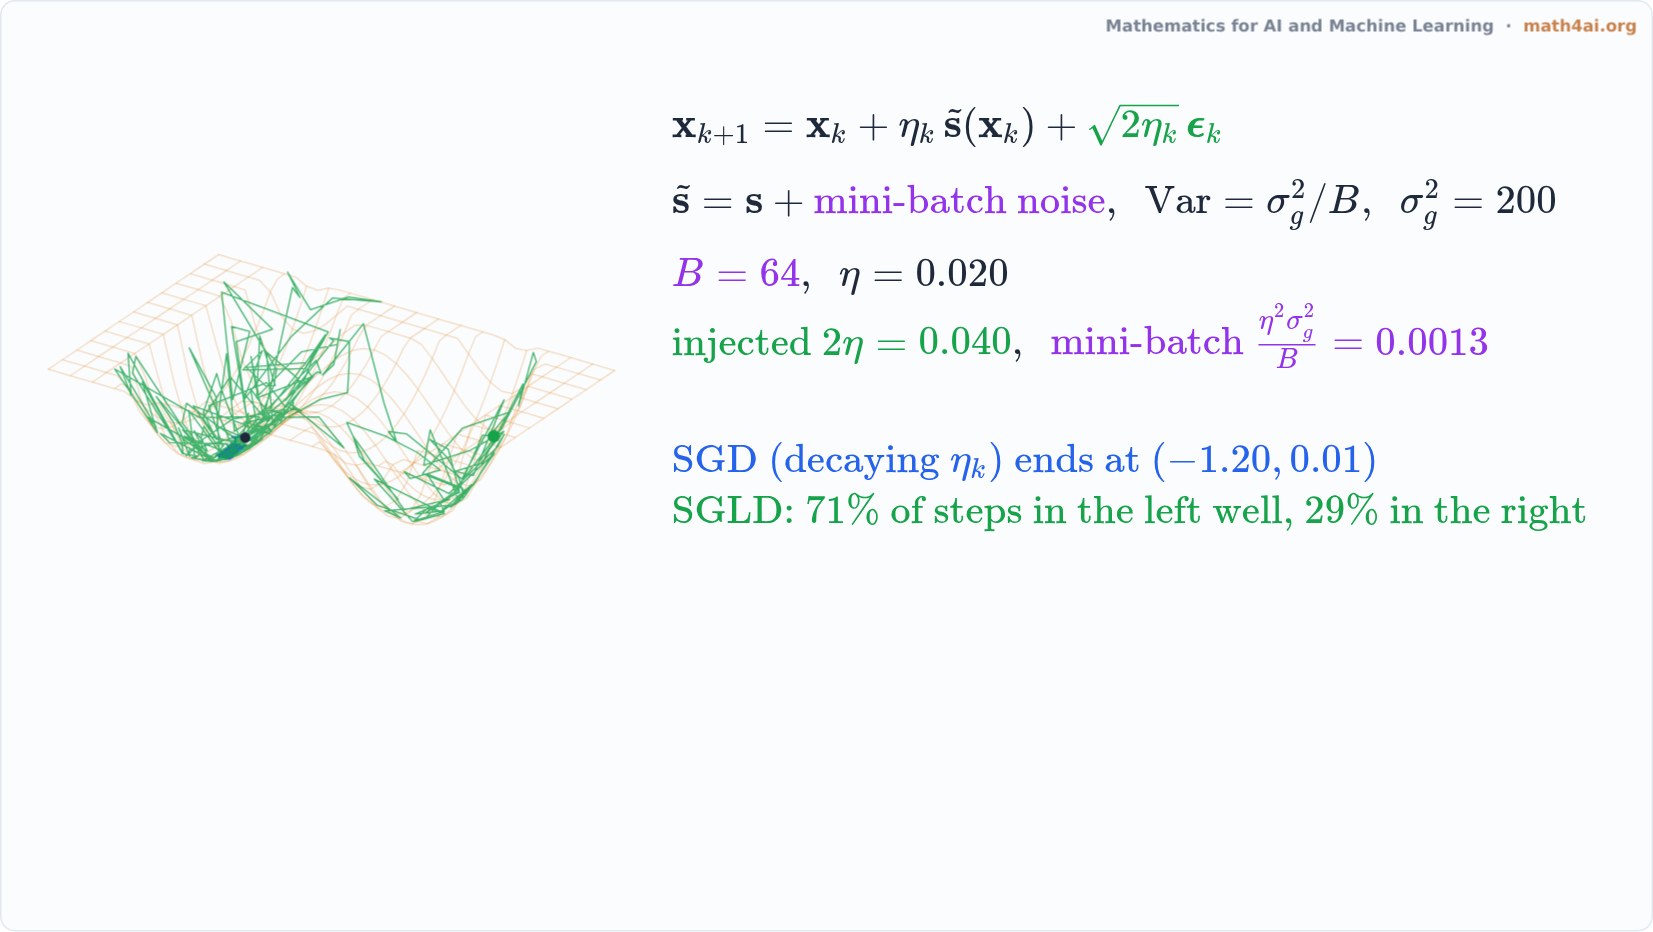 Preview1:29Langevin Dynamics and SGLD: Sampling vs OptimizationChapter 18
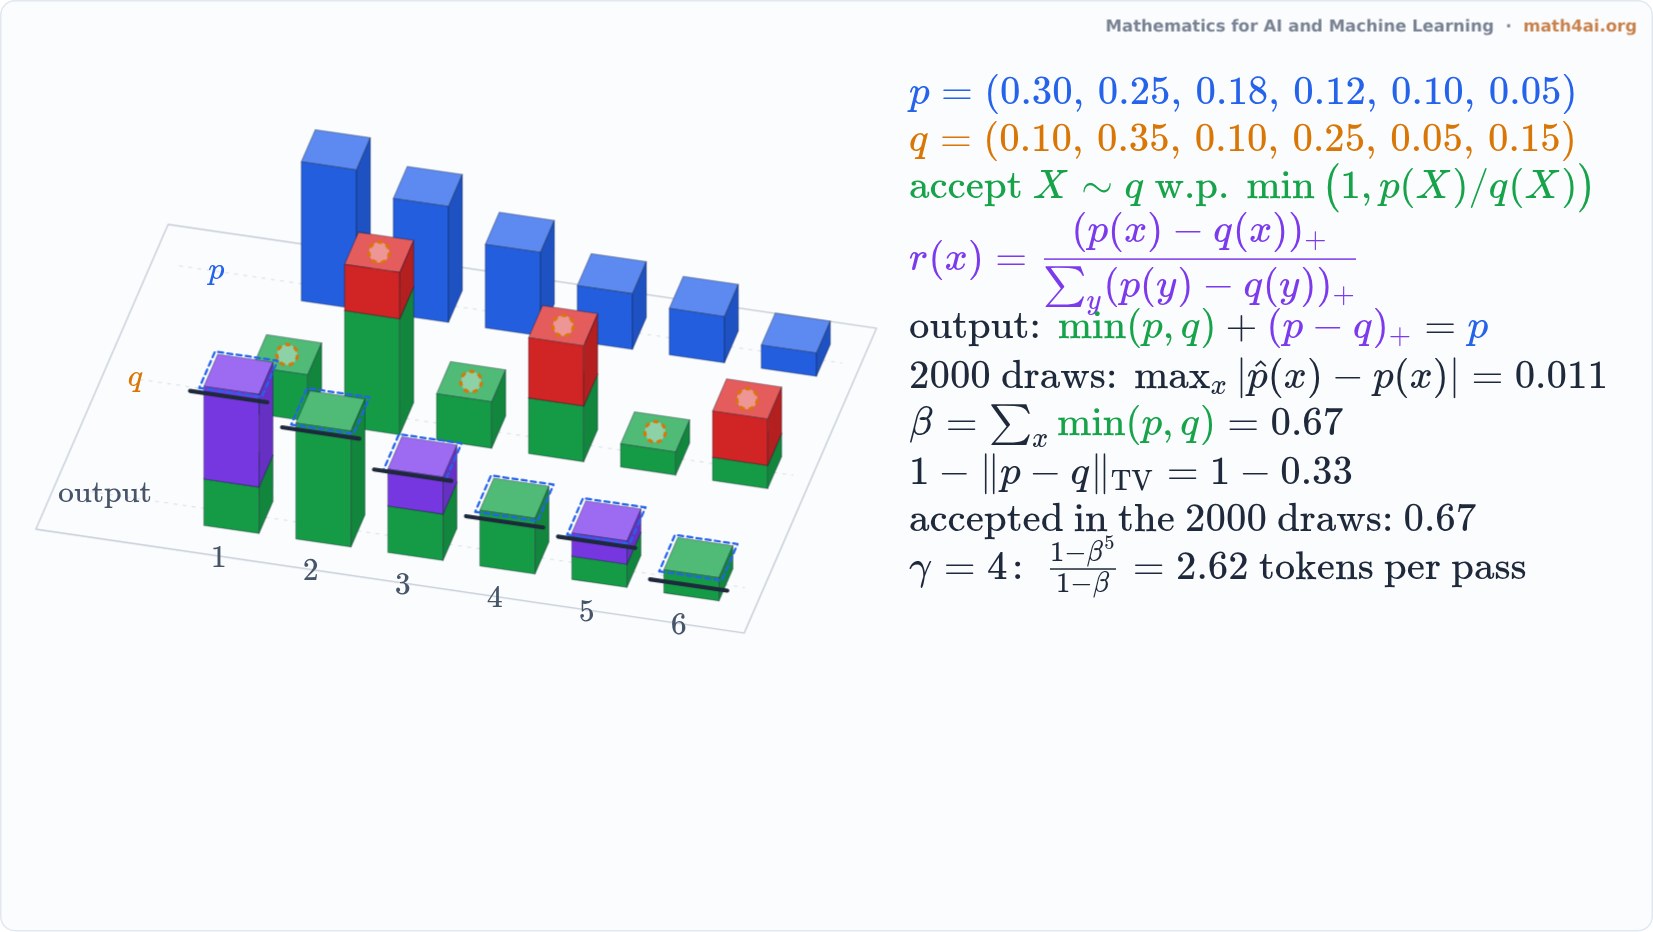 Preview1:46Speculative Decoding: Exact Sampling With a Draft ModelChapter 18
Chapter 19 Stochastic Differential Equations
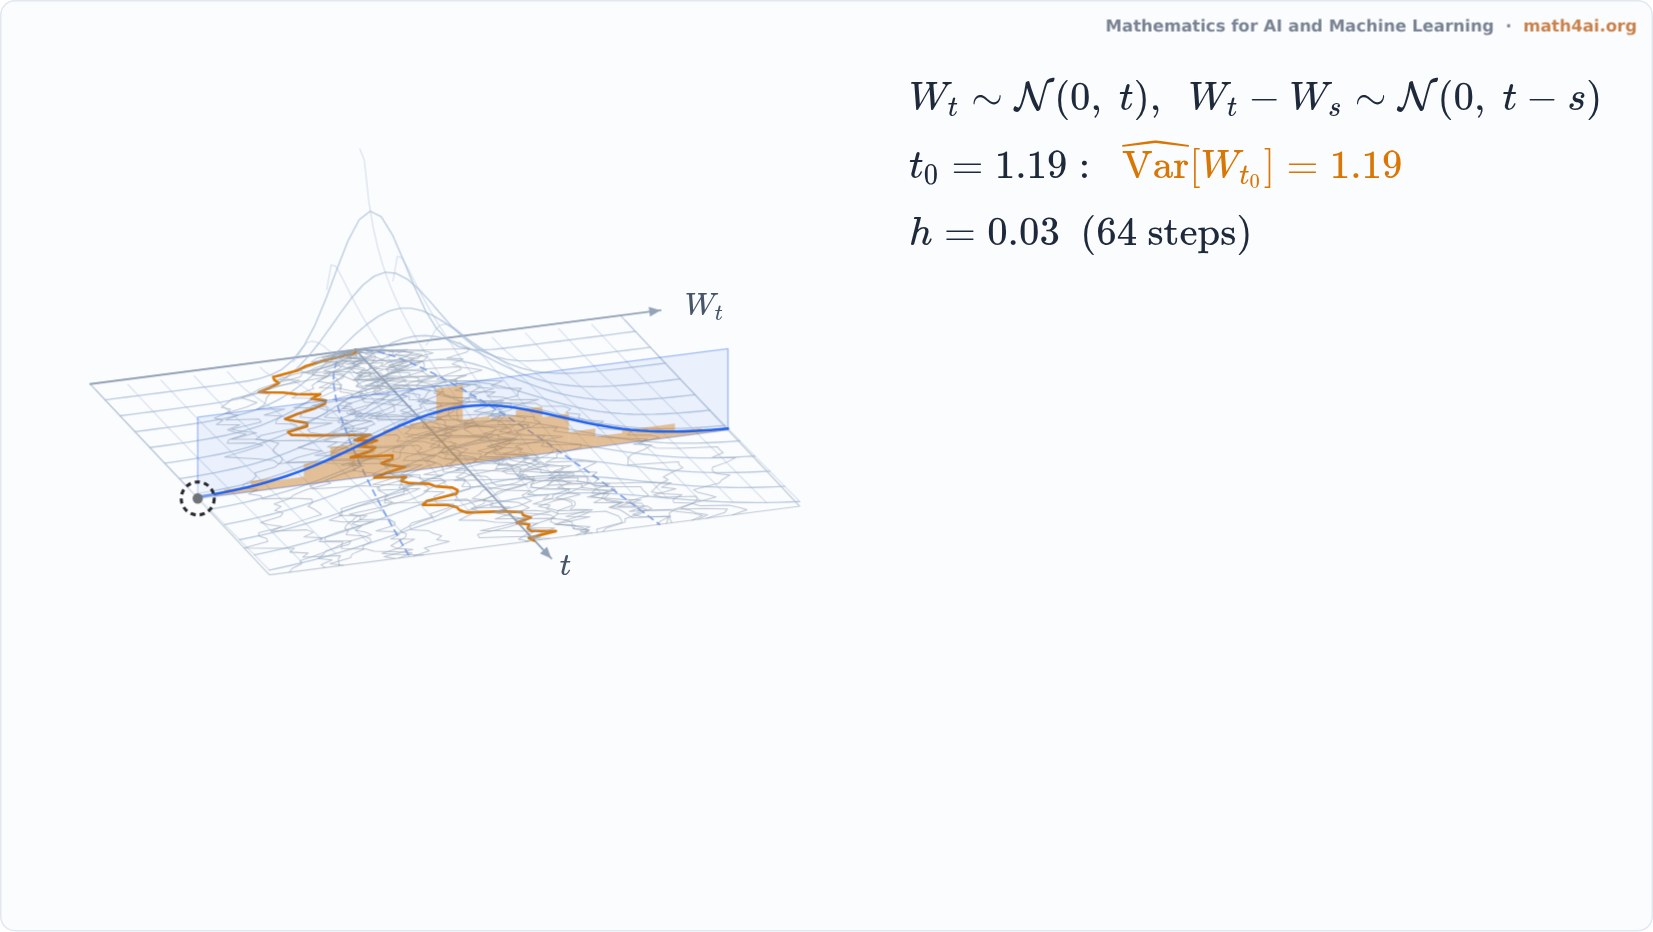 Interactive1:37Brownian Motion: Rough Paths, a Spreading Bell, and dW Squared Equals dtChapter 19
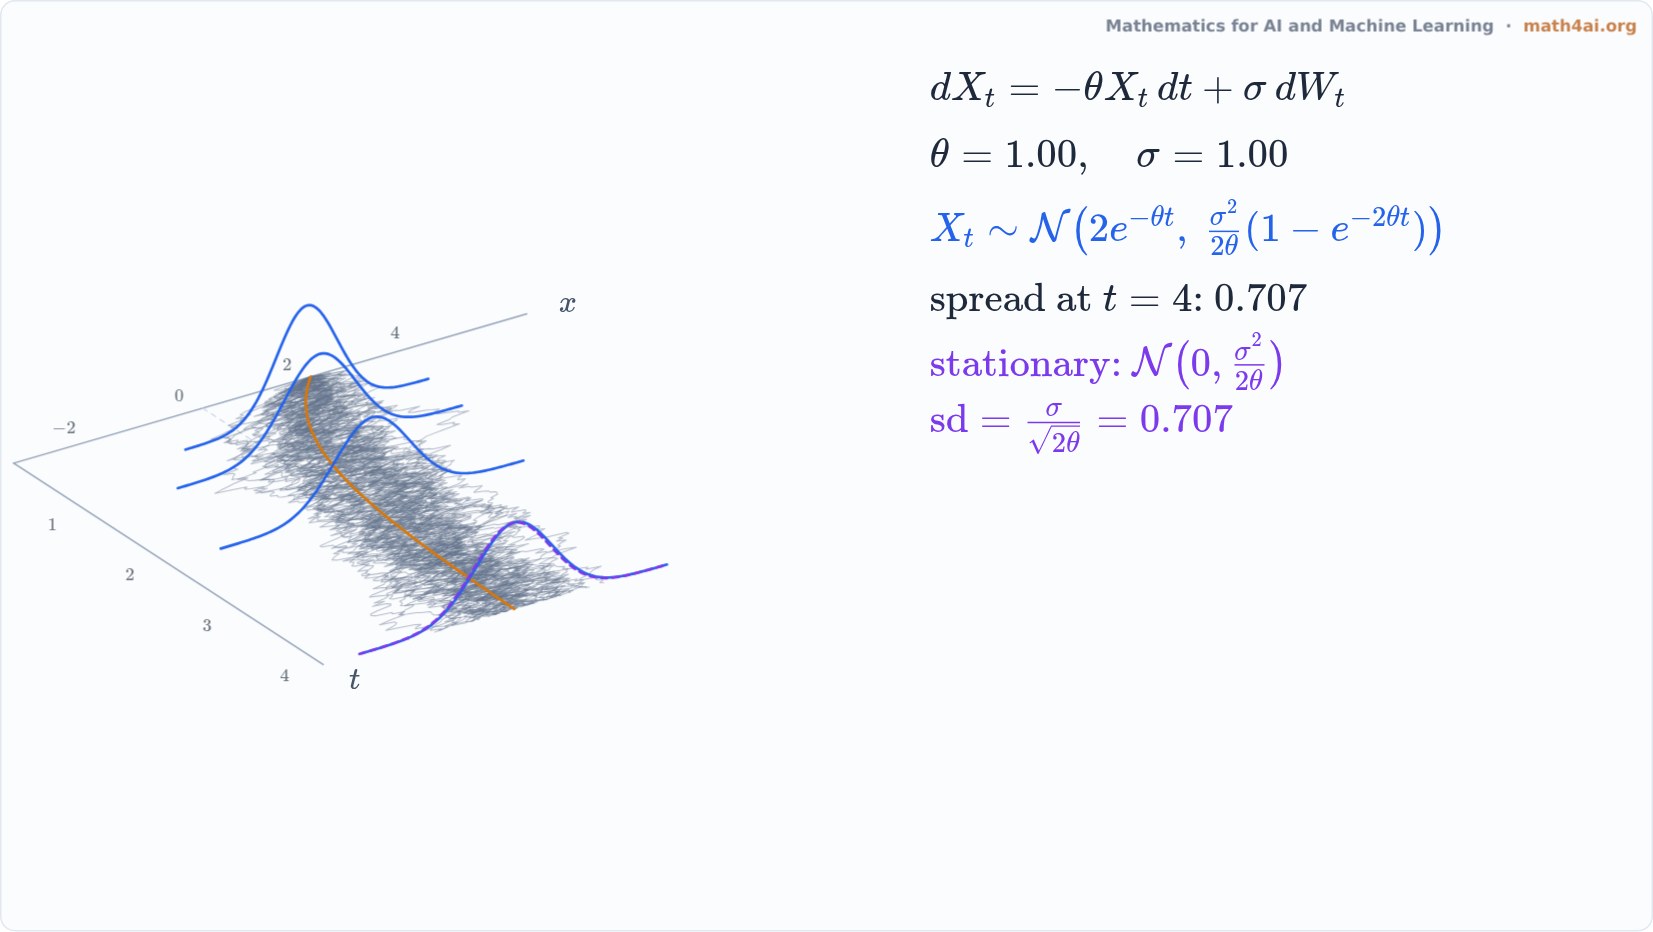 Preview1:17The Ornstein-Uhlenbeck Process: Brownian Motion on a SpringChapter 19
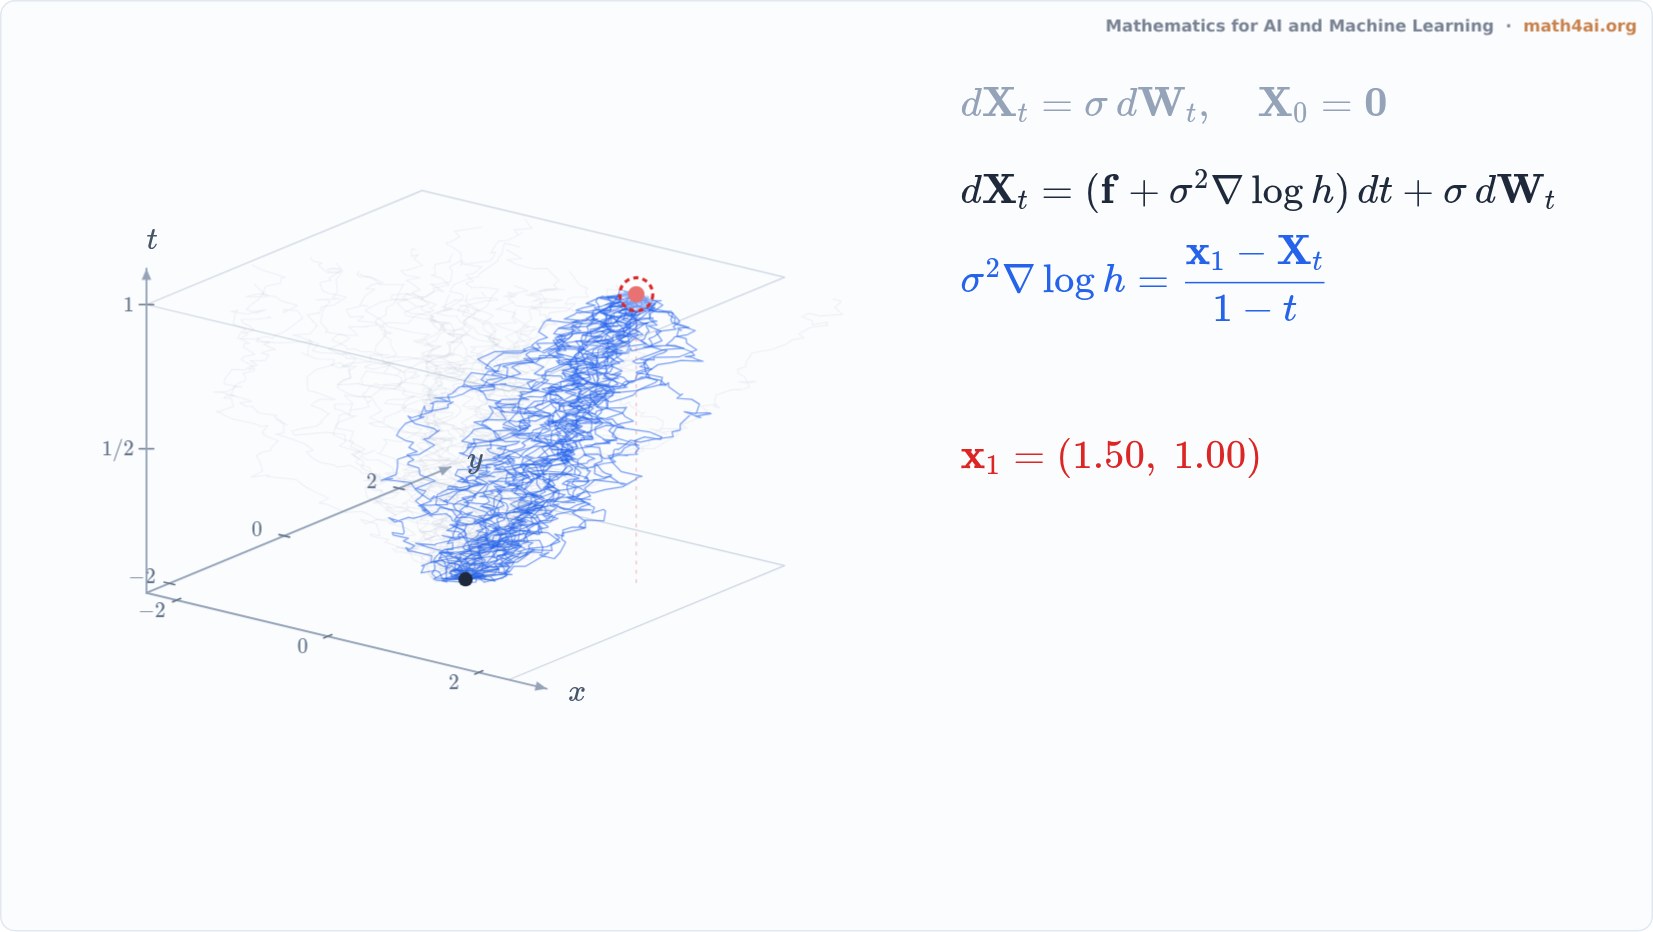 Preview1:29Conditioning a Diffusion on Its EndpointChapter 19
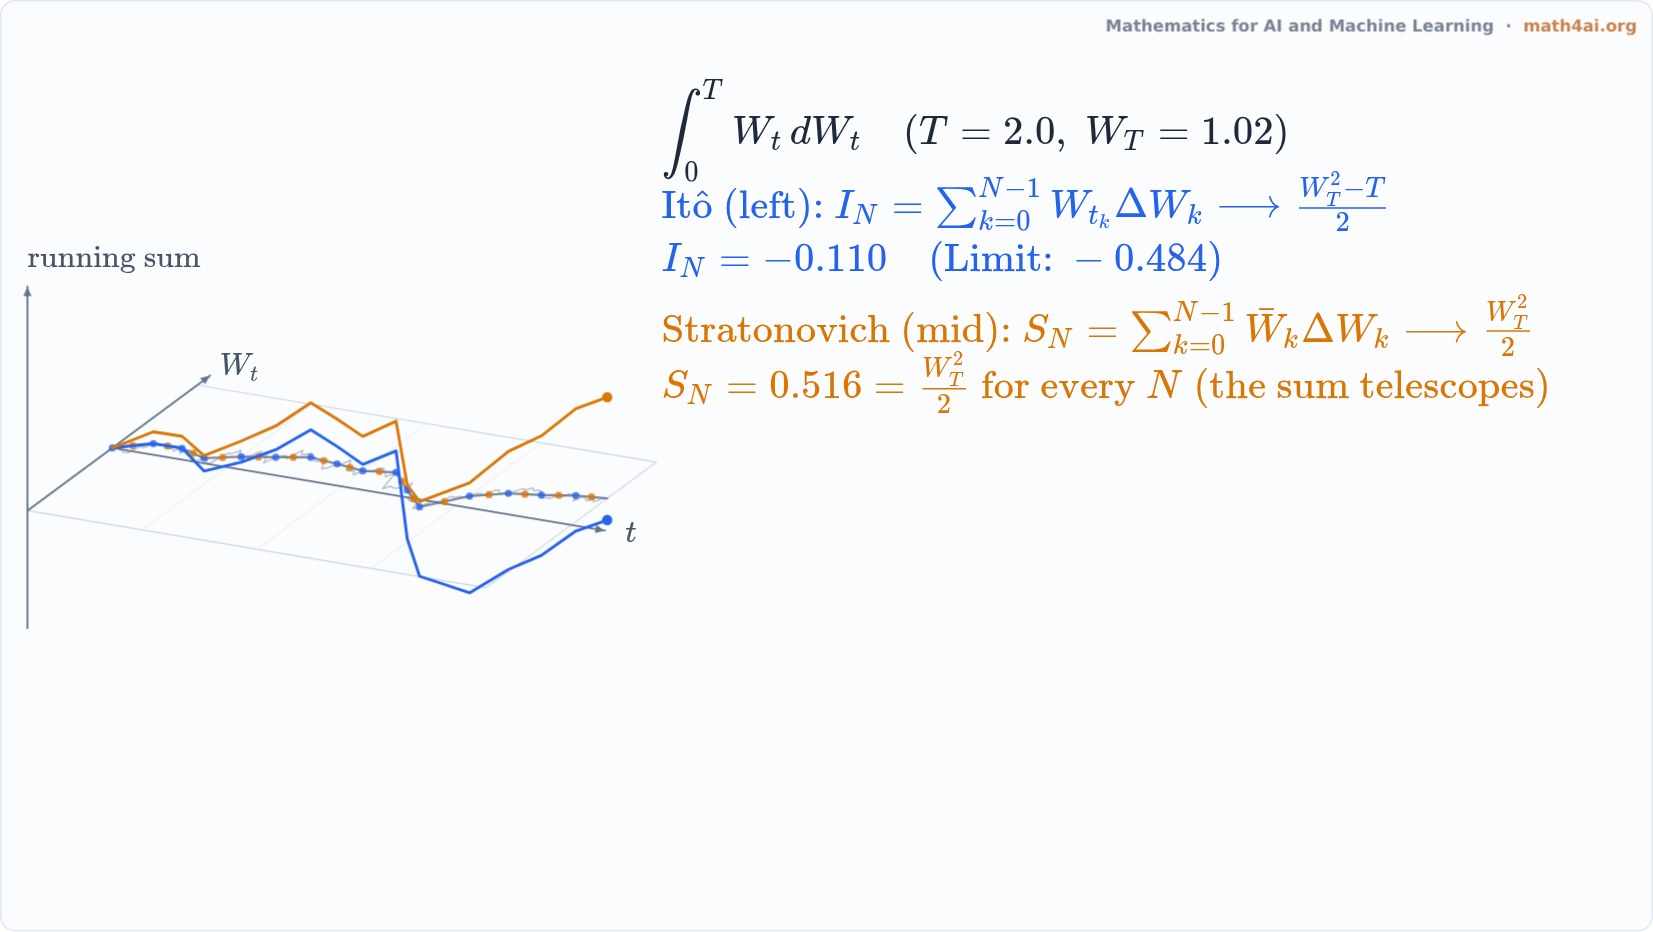 Preview1:46Itô vs Stratonovich: Left Endpoint or MidpointChapter 19
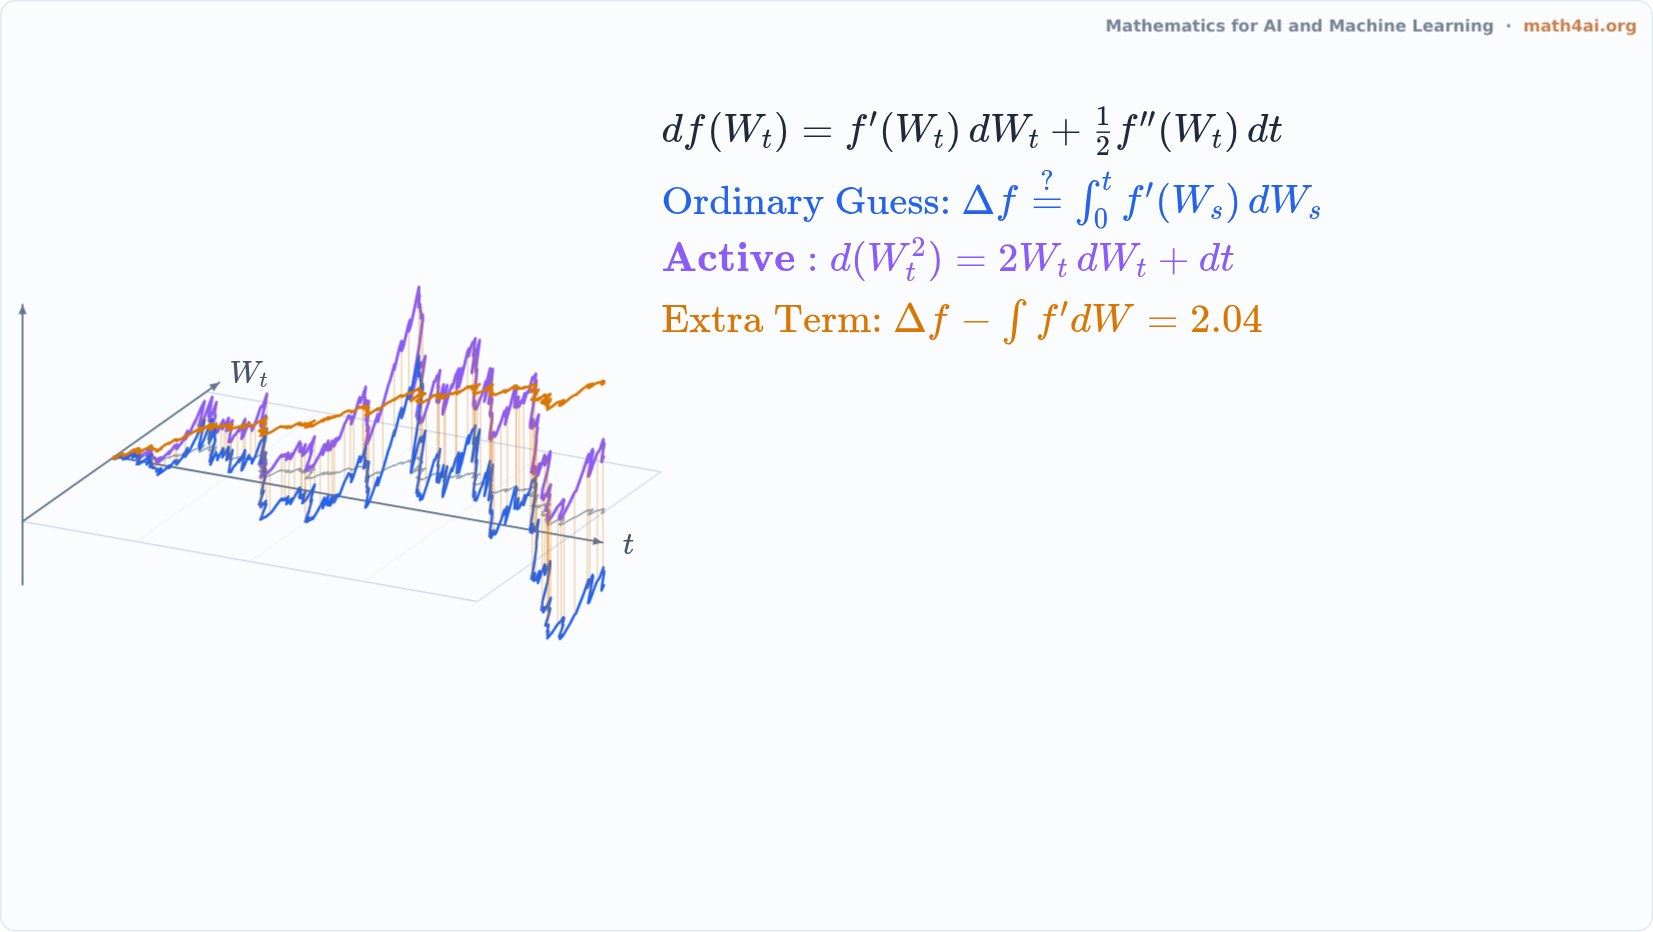 Preview2:01Itô's Lemma: The Extra Second-Order DriftChapter 19
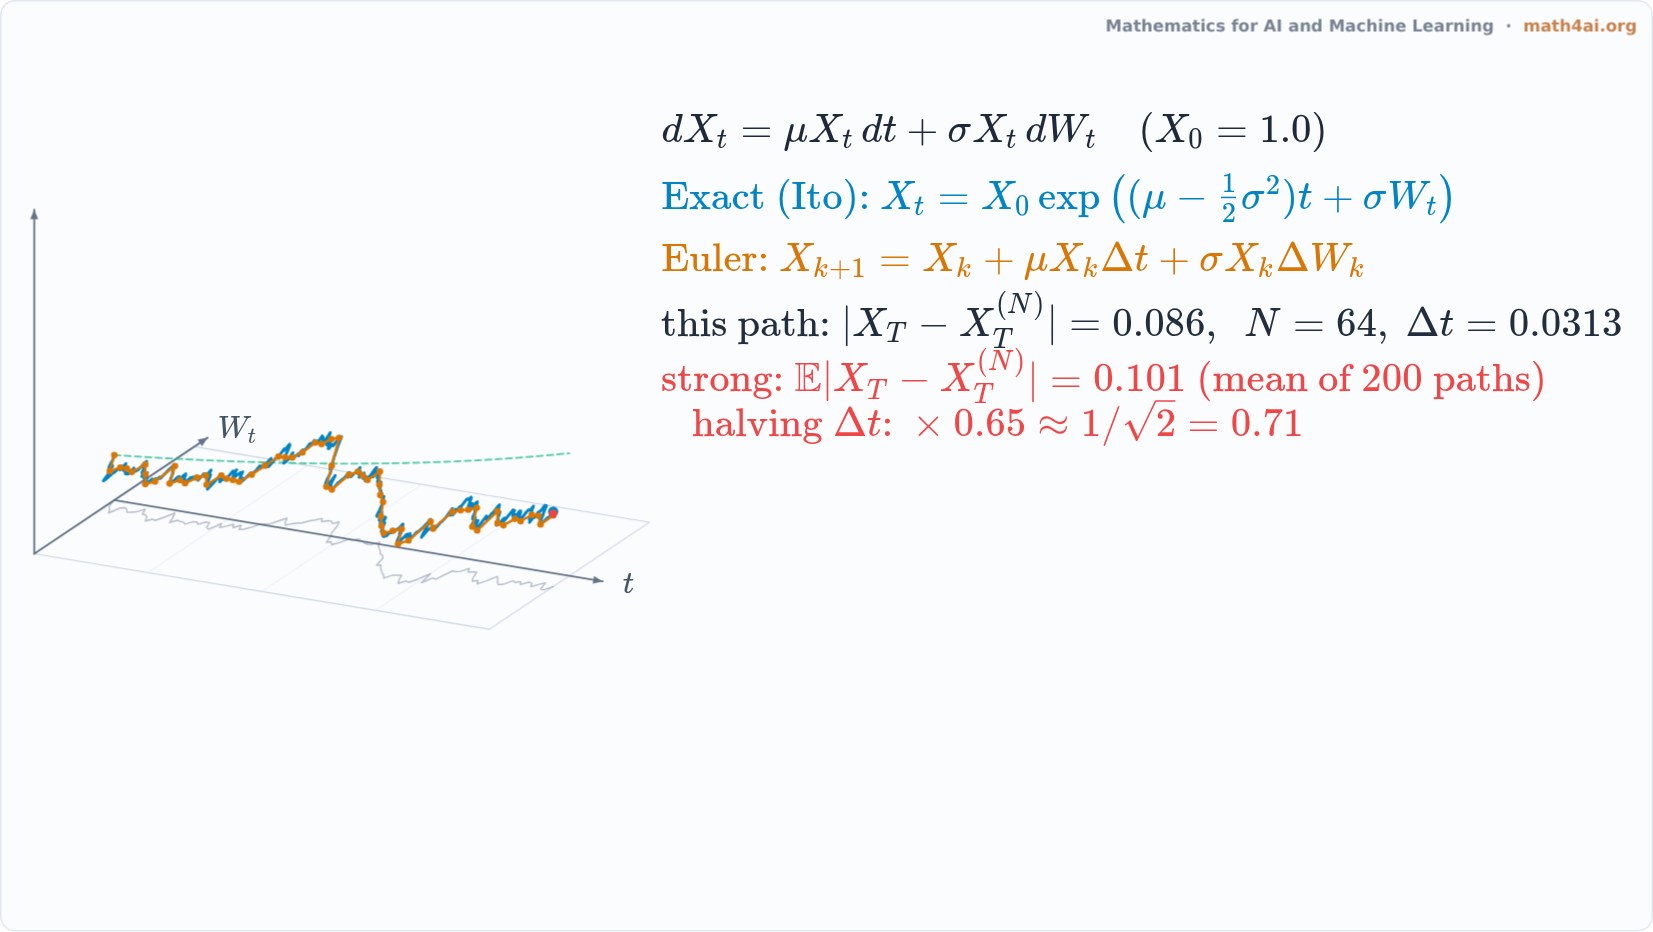 Preview1:56Euler–Maruyama: SDEs as Limits of AlgorithmsChapter 19
Chapter 20 ODE, SDE, and Continuous Limits of Algorithms
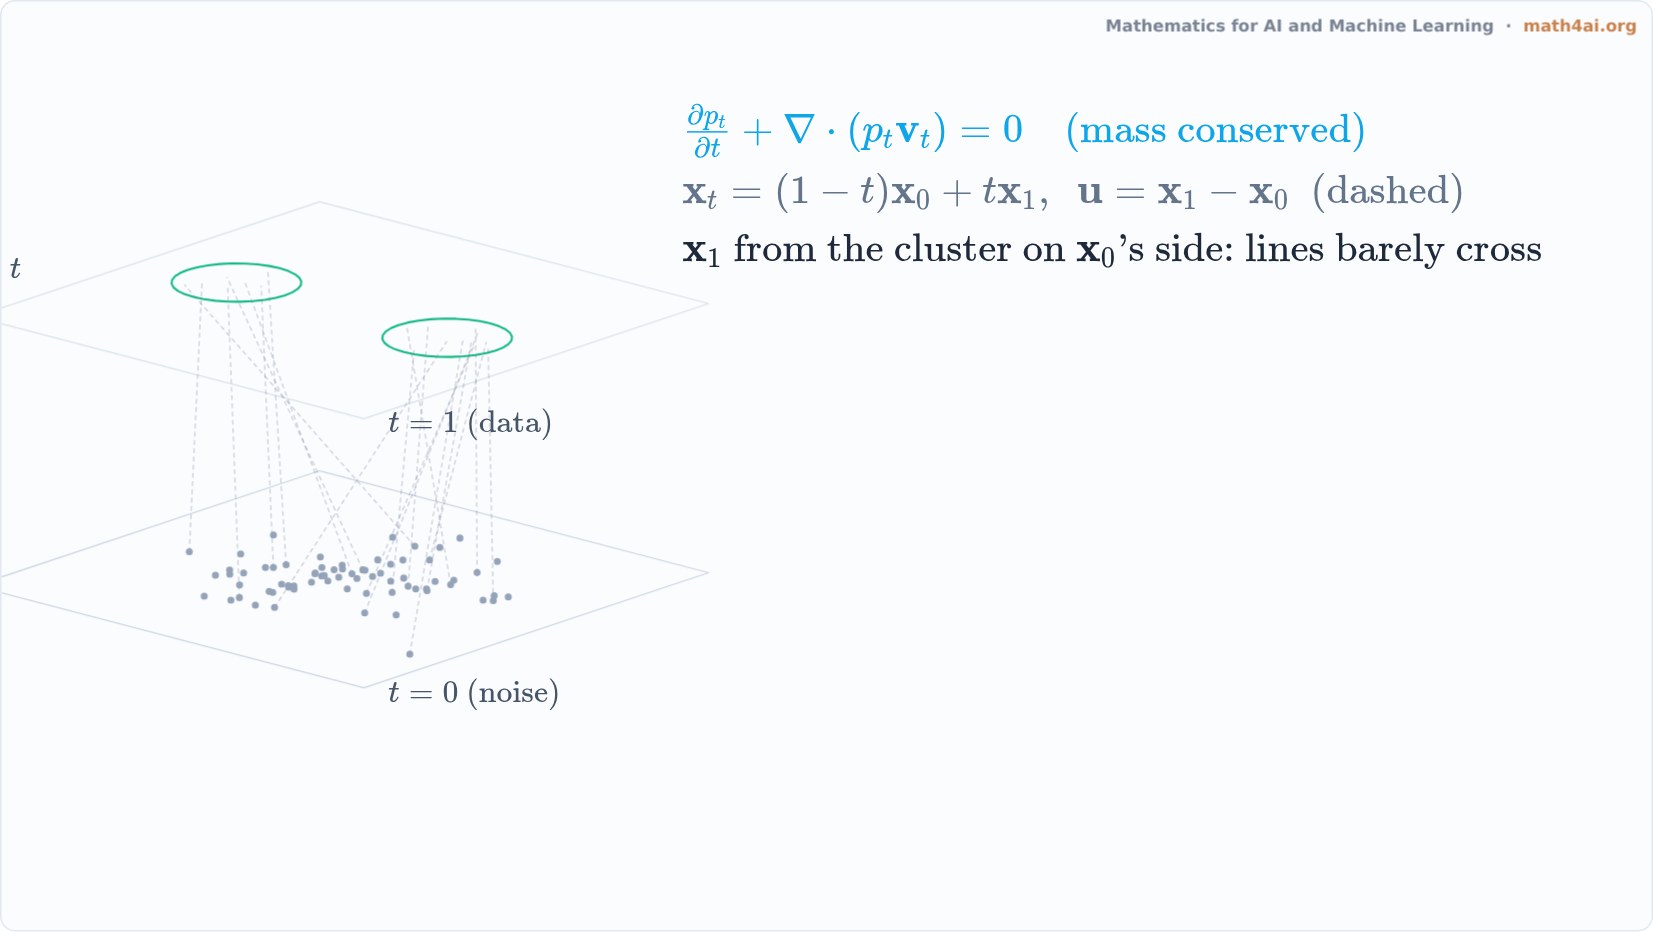 Interactive1:45Flow Matching: Velocity Fields and the Continuity EquationChapter 20
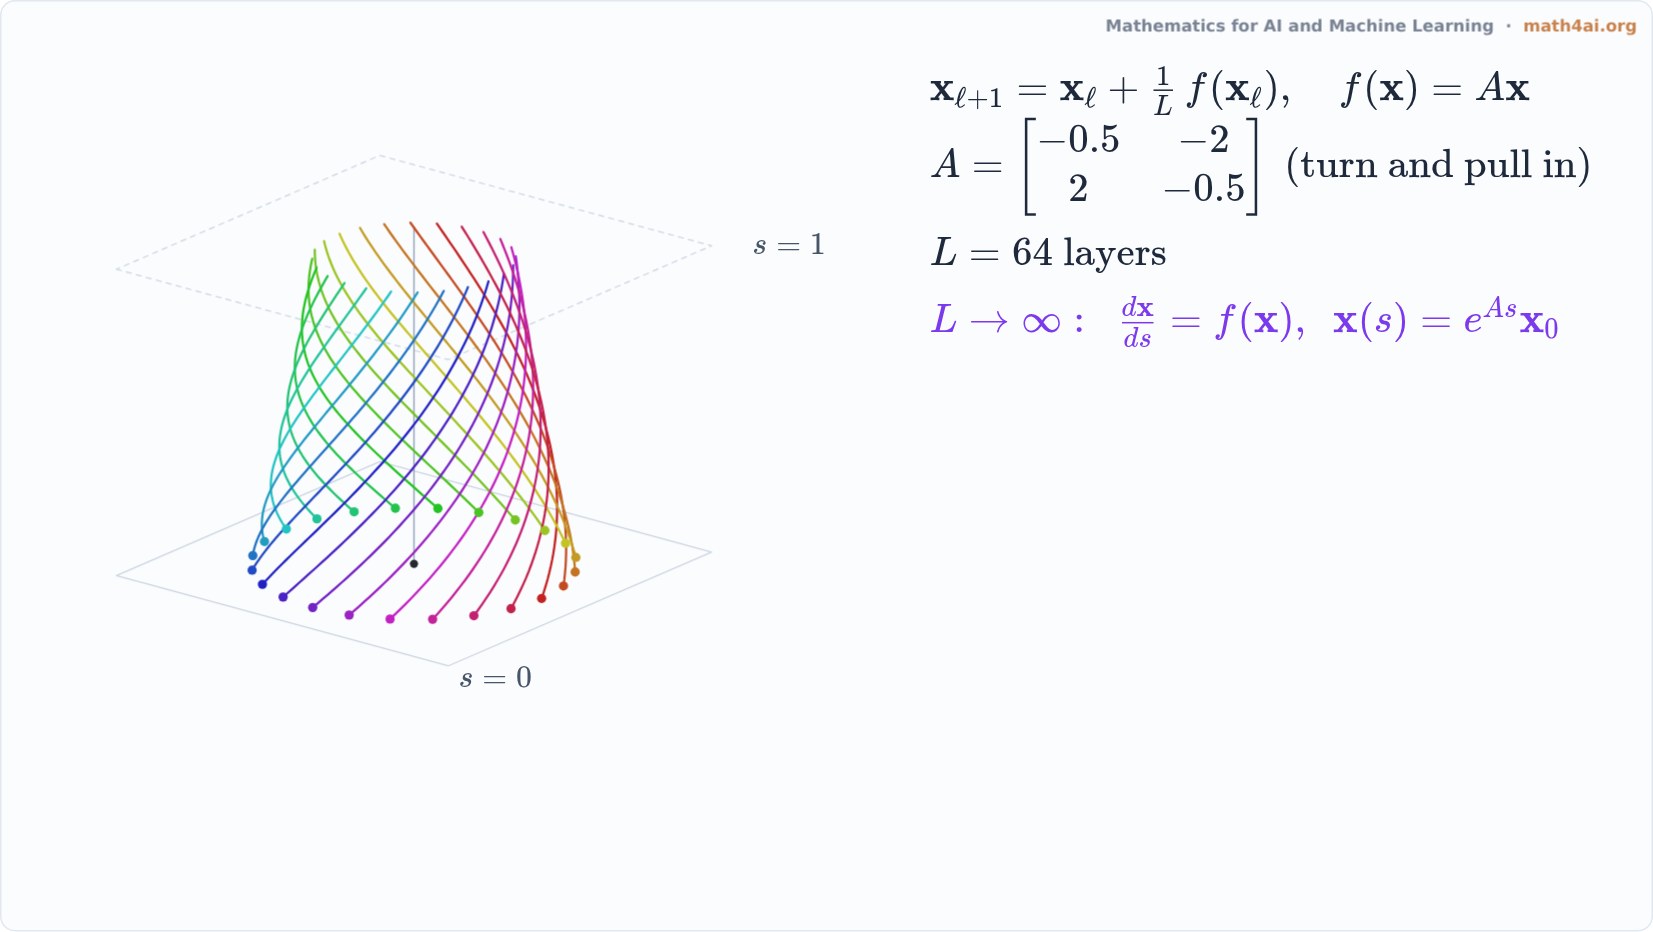 Preview1:28From a Residual Network to a Neural ODEChapter 20
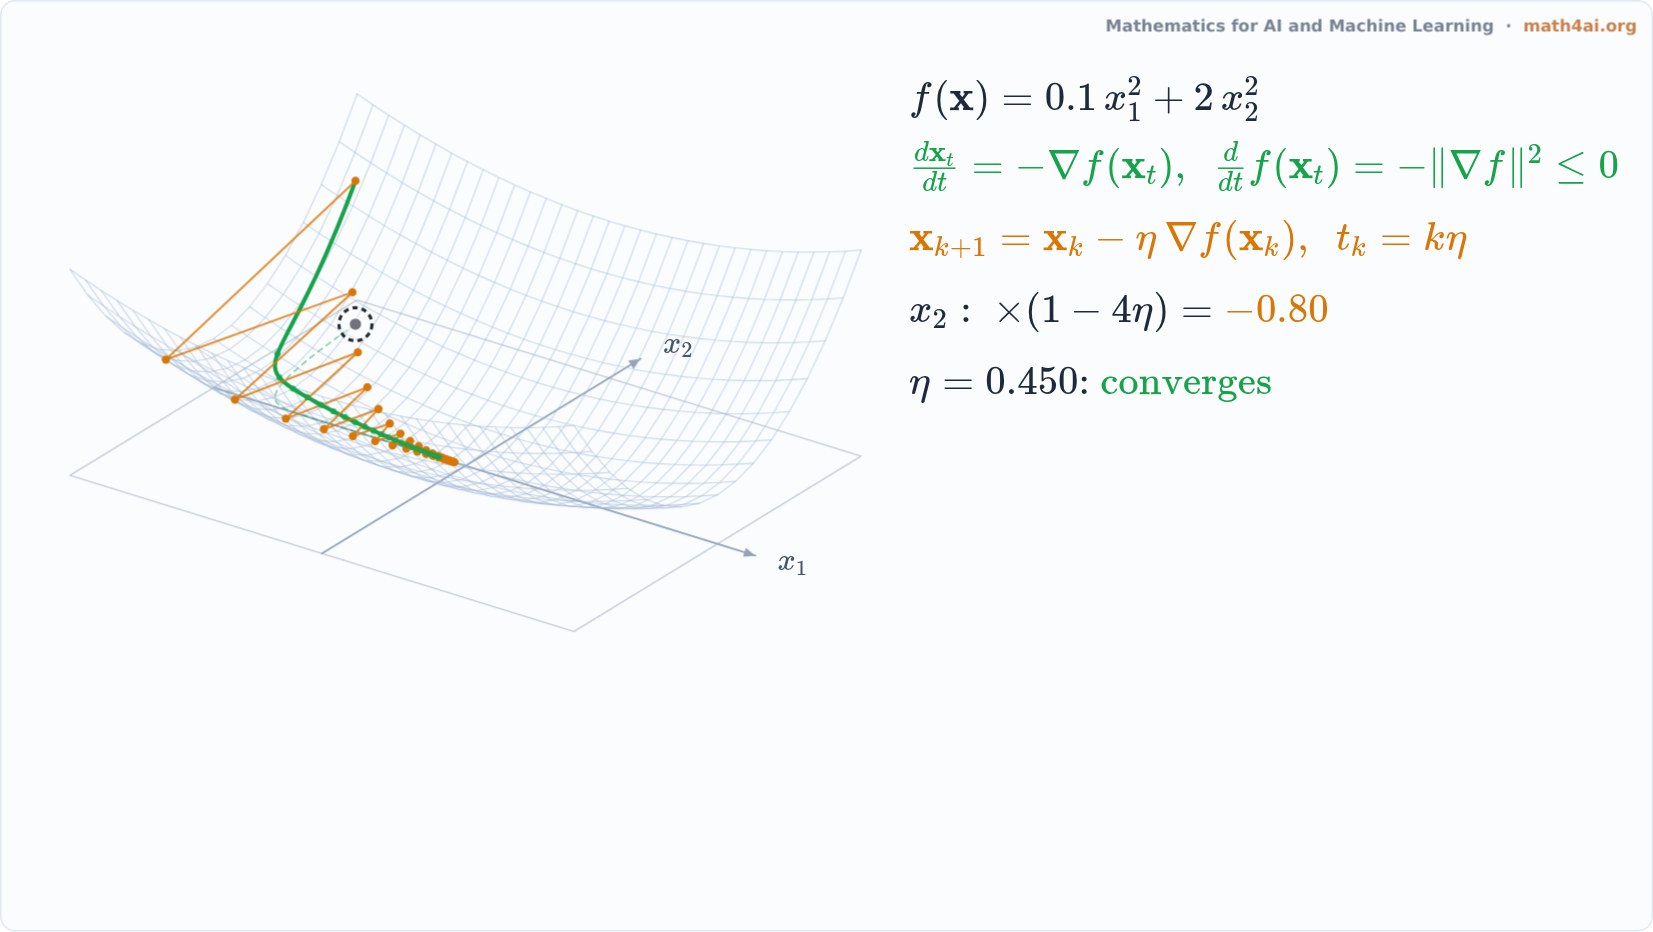 Preview1:27Gradient Flow: Gradient Descent With Infinitely Small StepsChapter 20
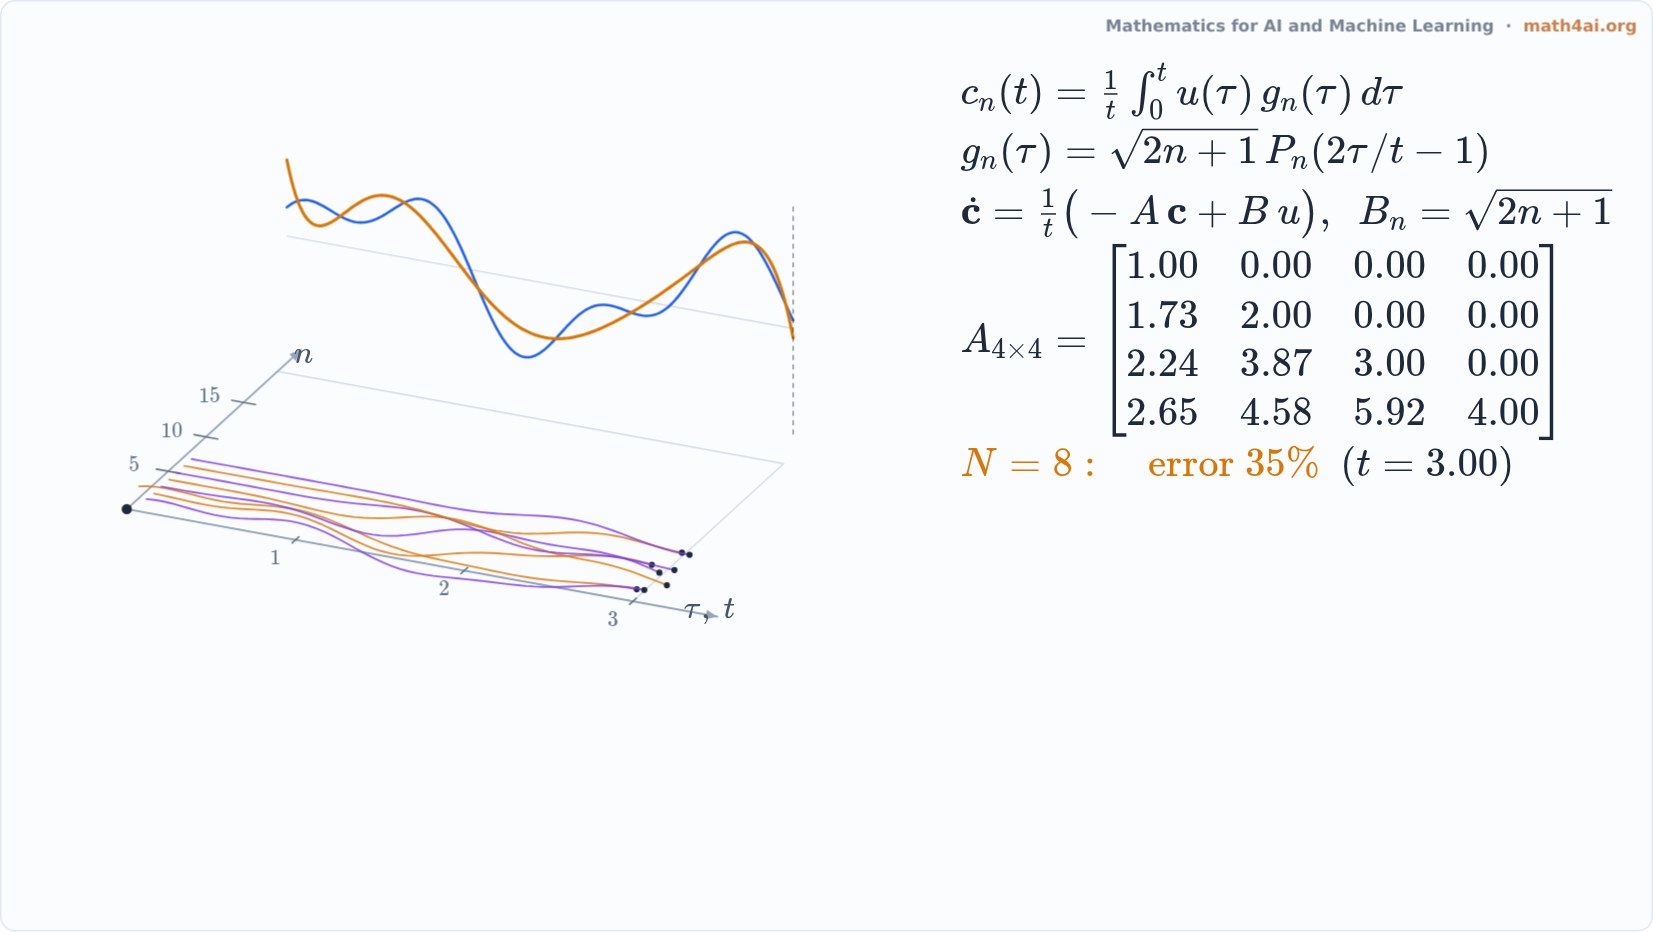 Preview1:26Memory by Orthogonal Projection (HiPPO)Chapter 20
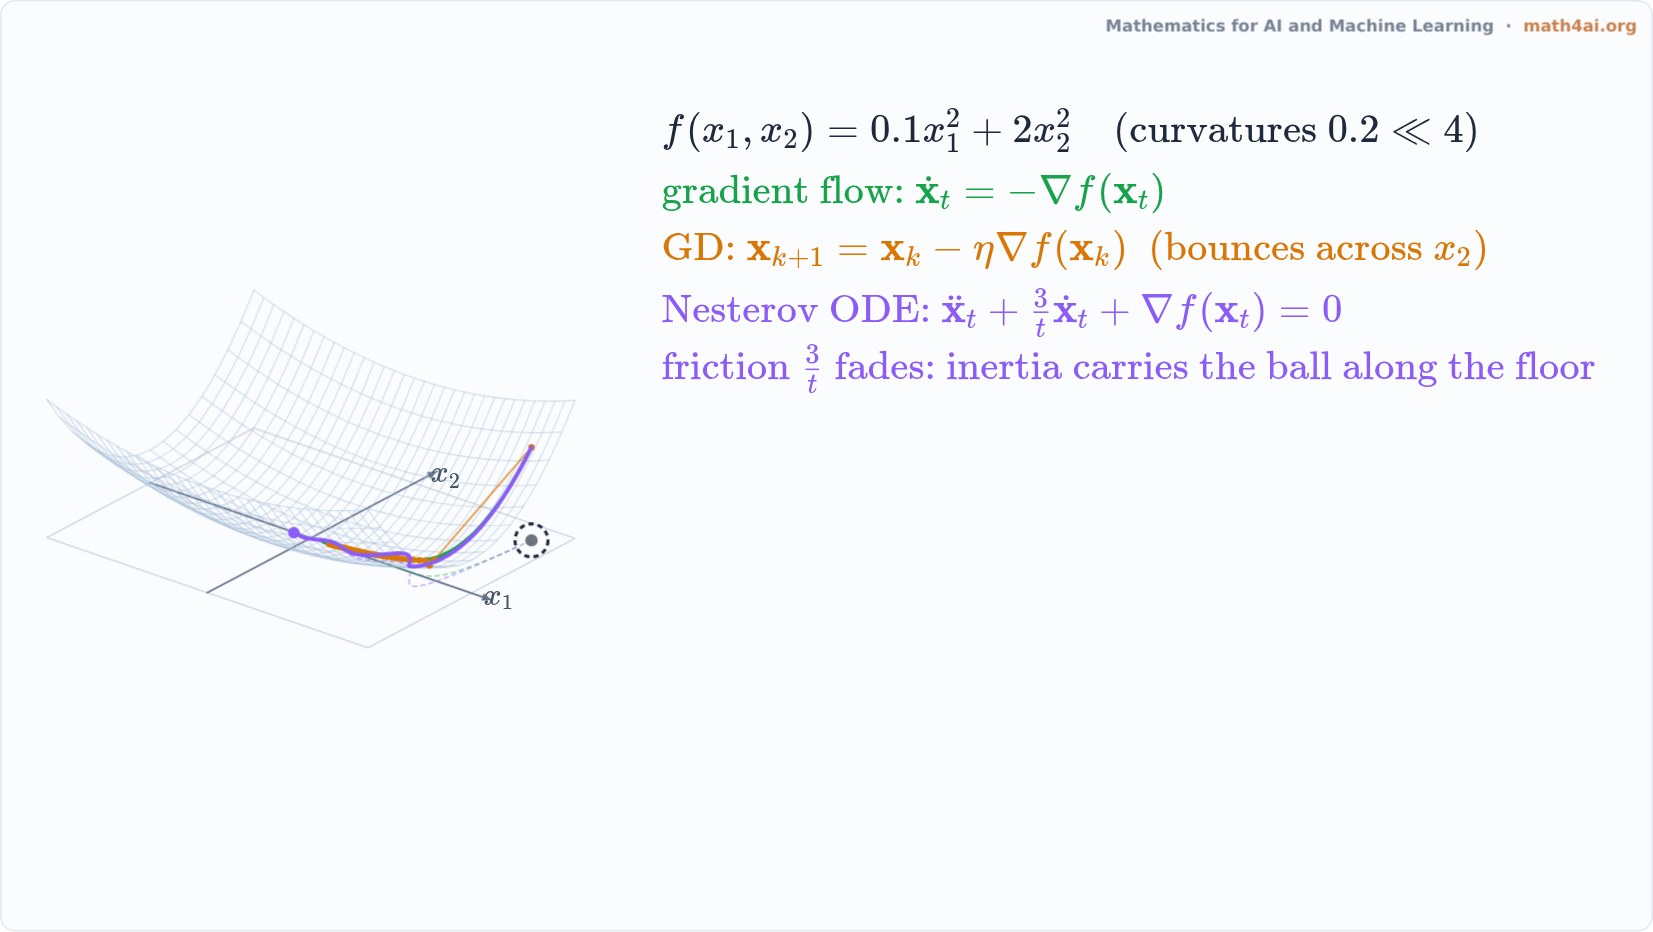 Preview1:36Momentum Methods: Second-Order ODEChapter 20
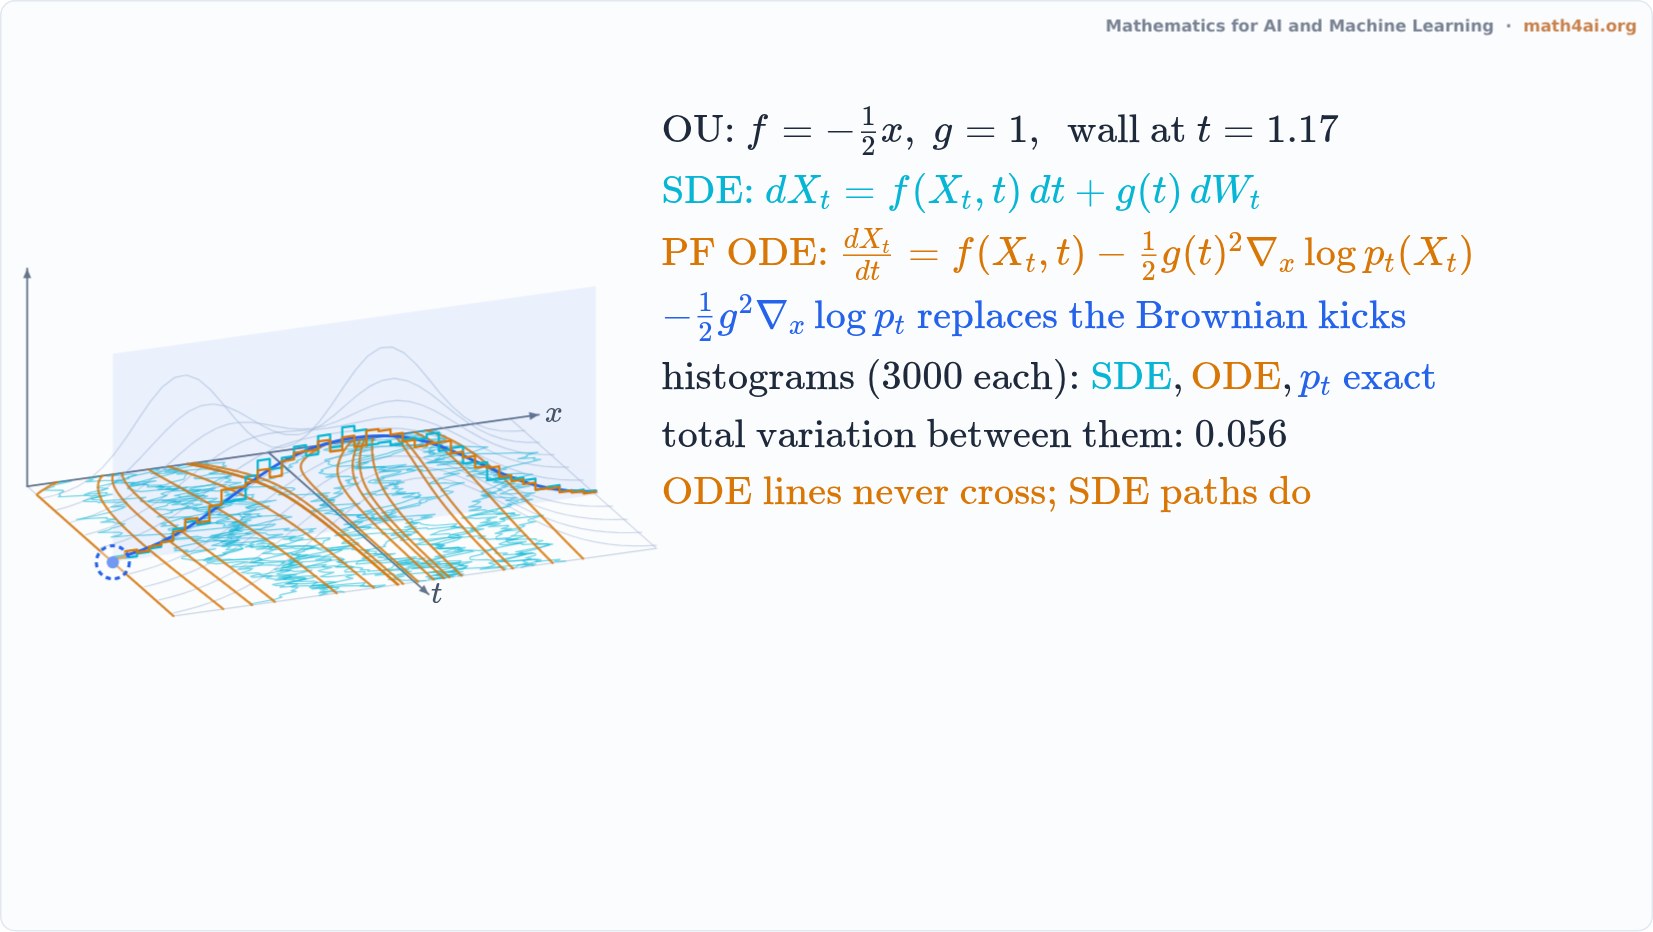 Preview1:34Probability Flow ODE: Deterministic Paths, Identical MarginalsChapter 20
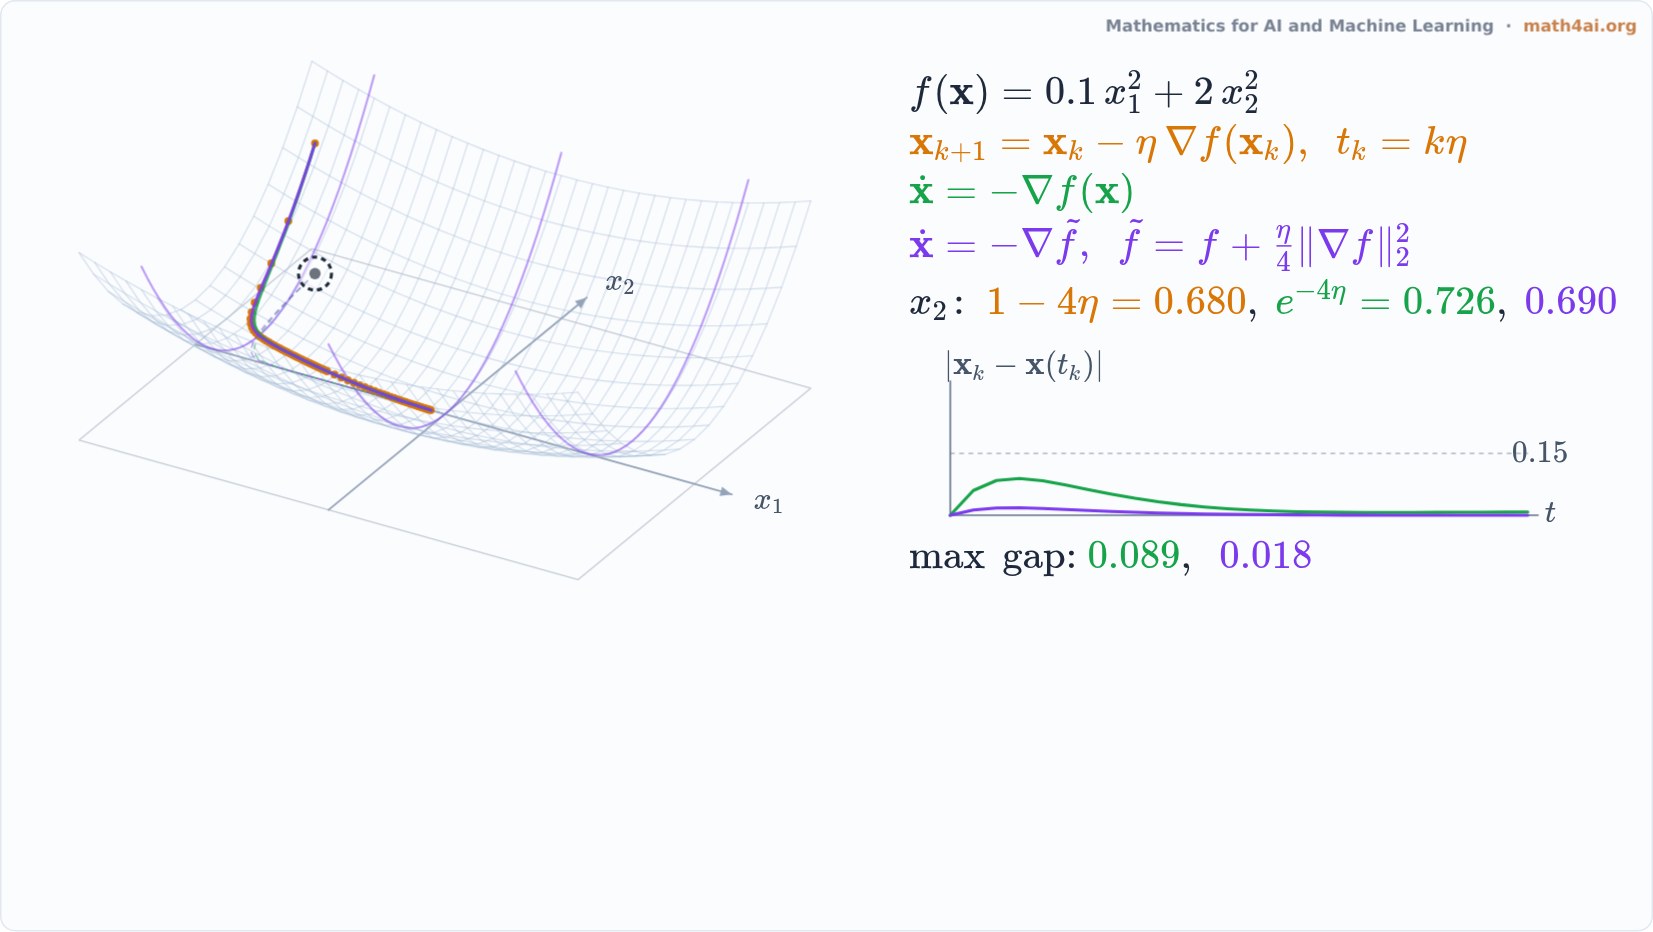 Preview1:40Backward Error Analysis: What Gradient Descent FollowsChapter 20
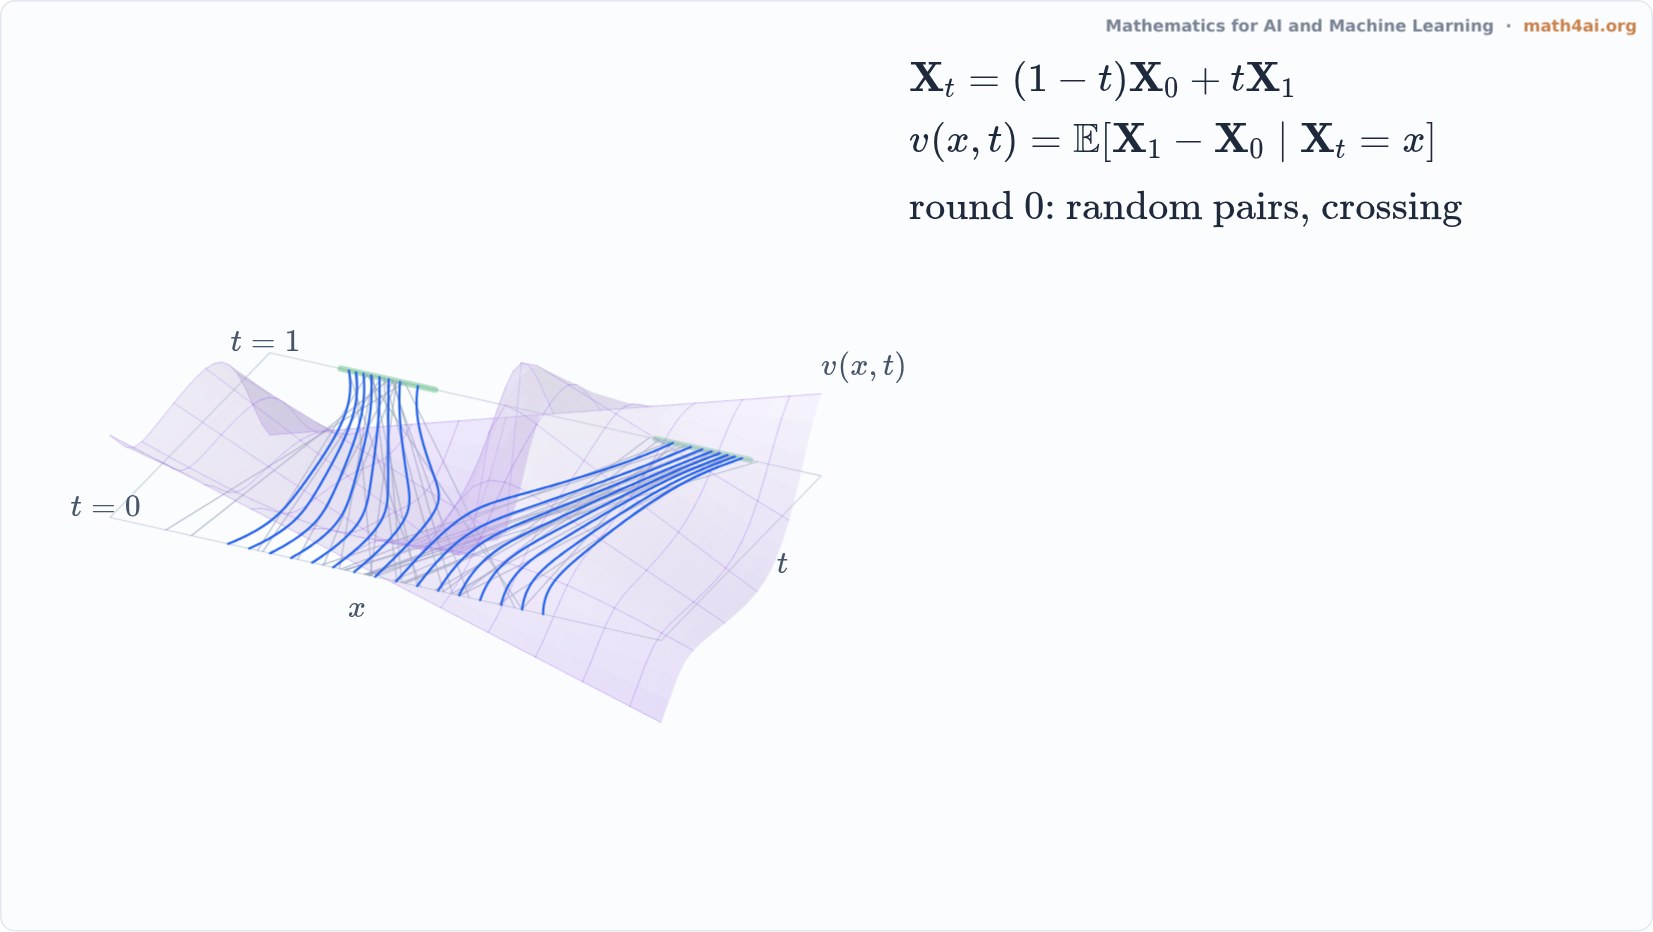 Preview1:46Rectified Flow: Straightening by RetrainingChapter 20
Chapter 21 Fokker-Planck and Distribution Dynamics
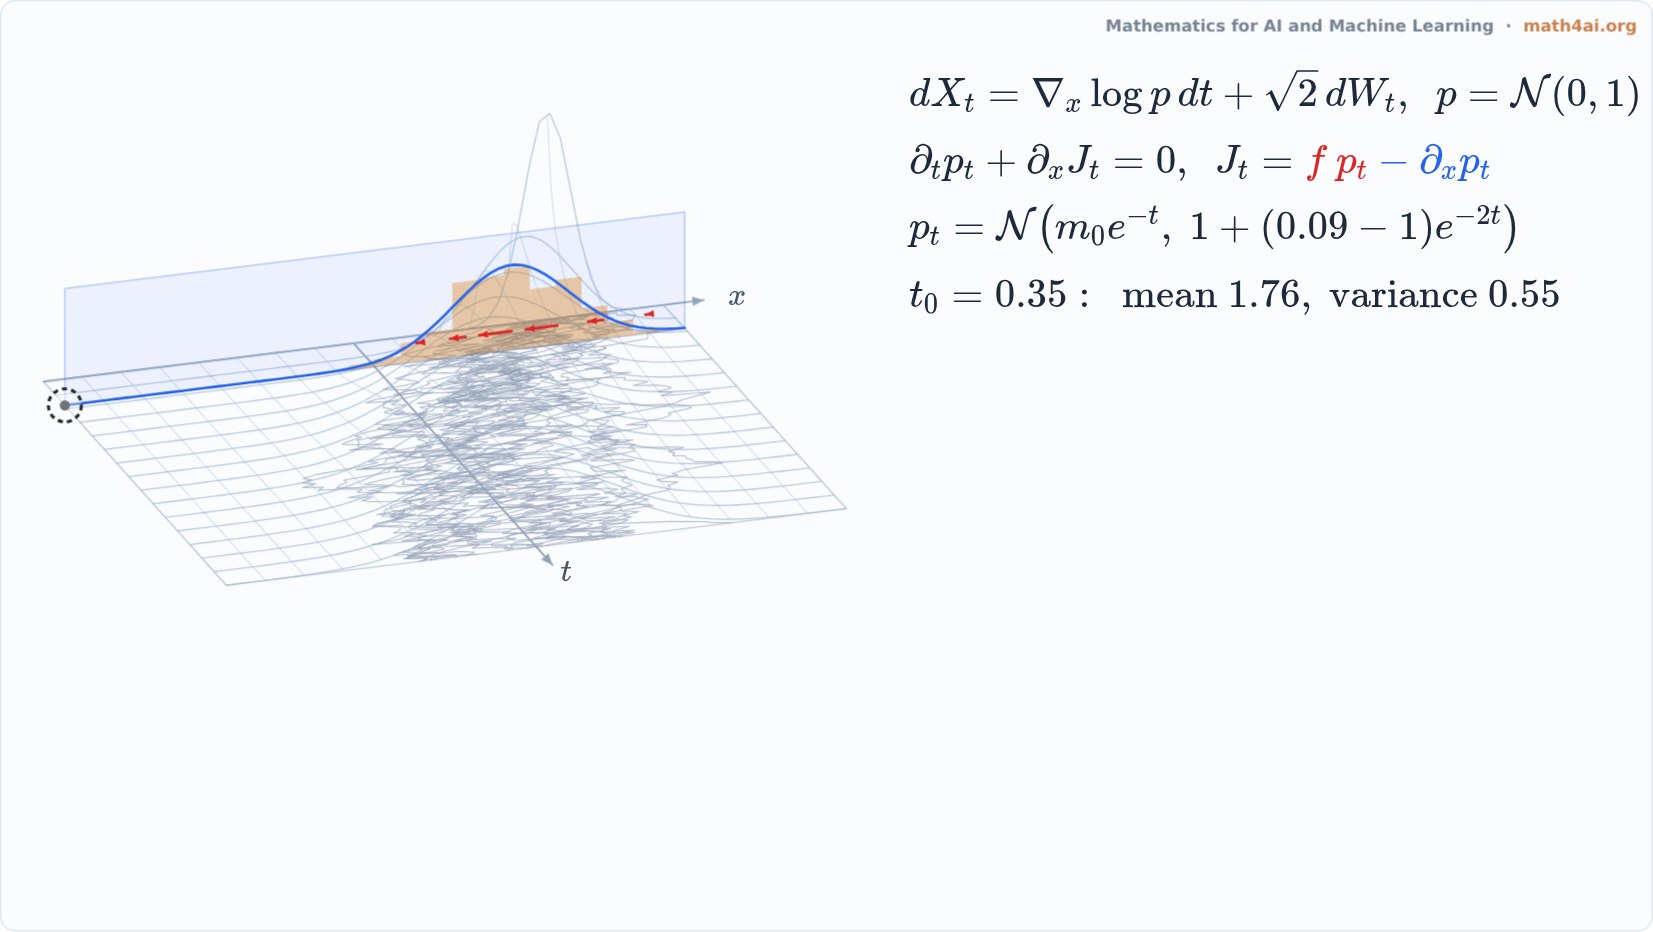 Interactive1:35Fokker-Planck: A Random Cloud, a Deterministic DensityChapter 21
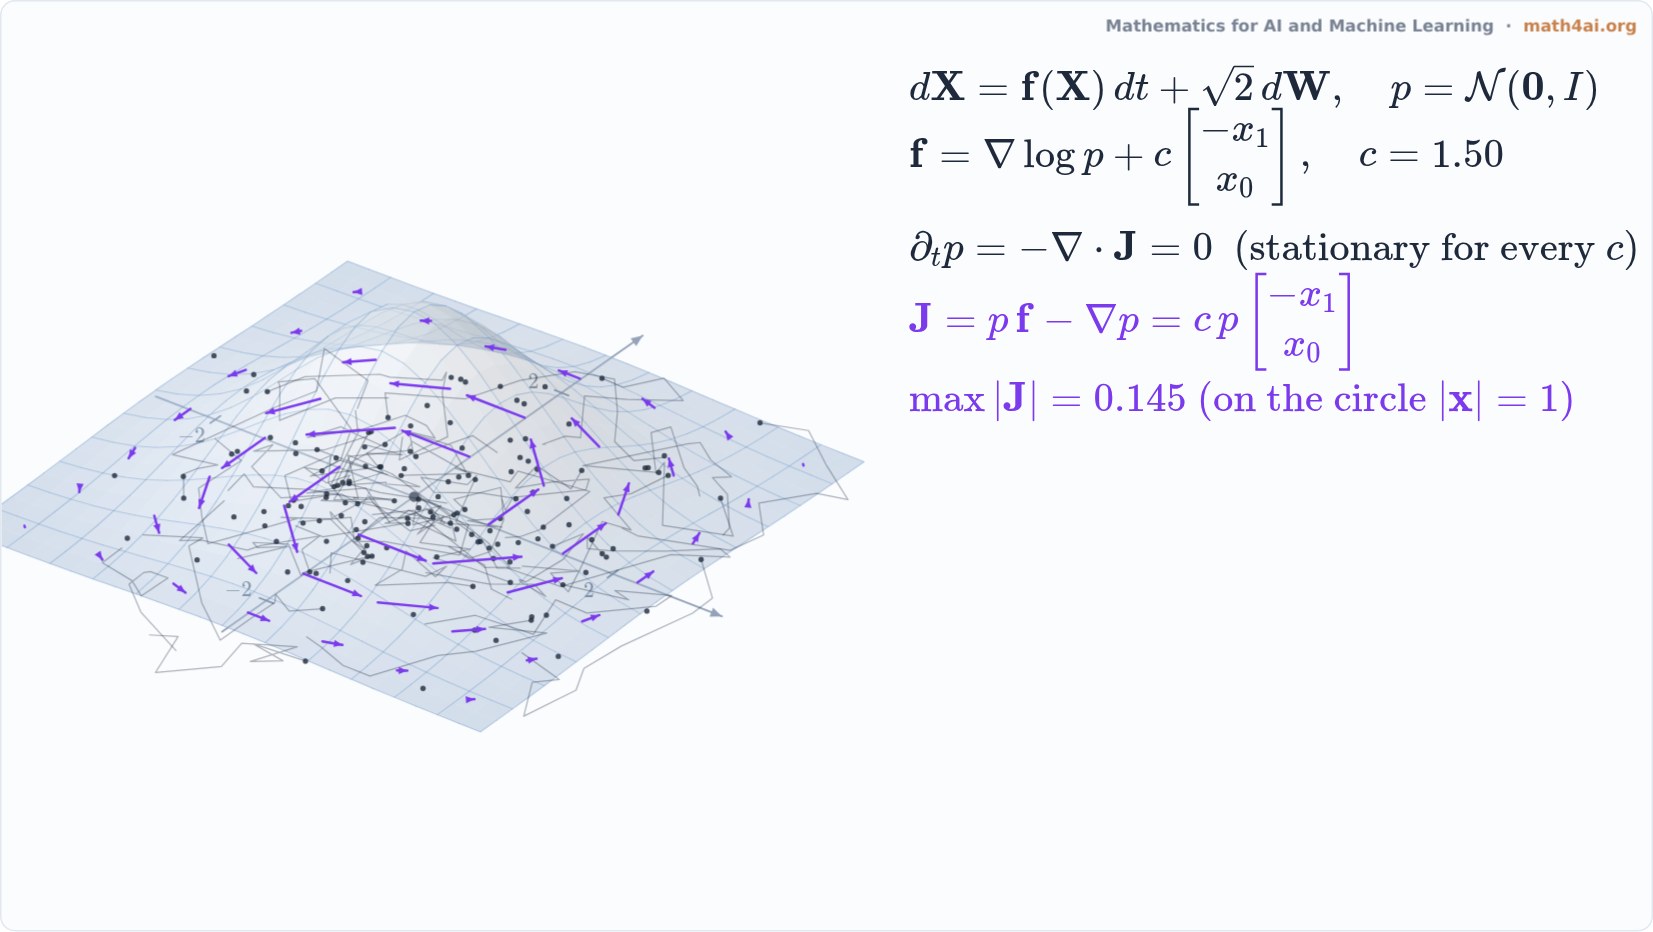 Preview1:29Detailed Balance: Stationary Is Not the Same as StillChapter 21
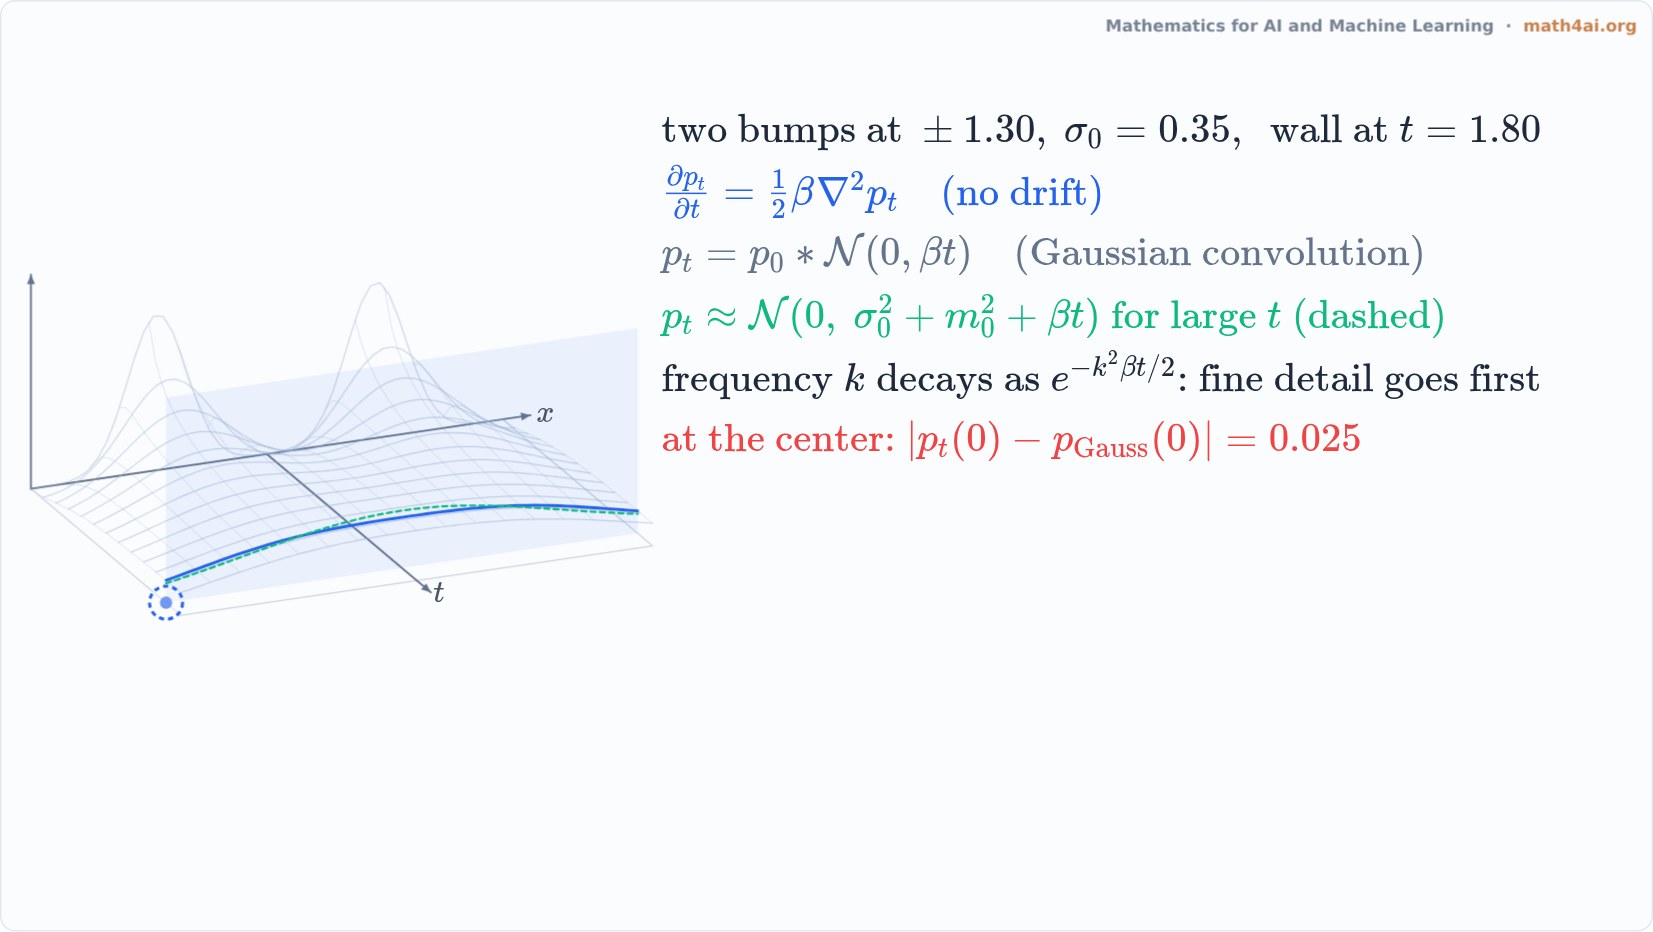 Preview1:28Forward Diffusion and the Heat Equation: All Distributions Become GaussianChapter 21
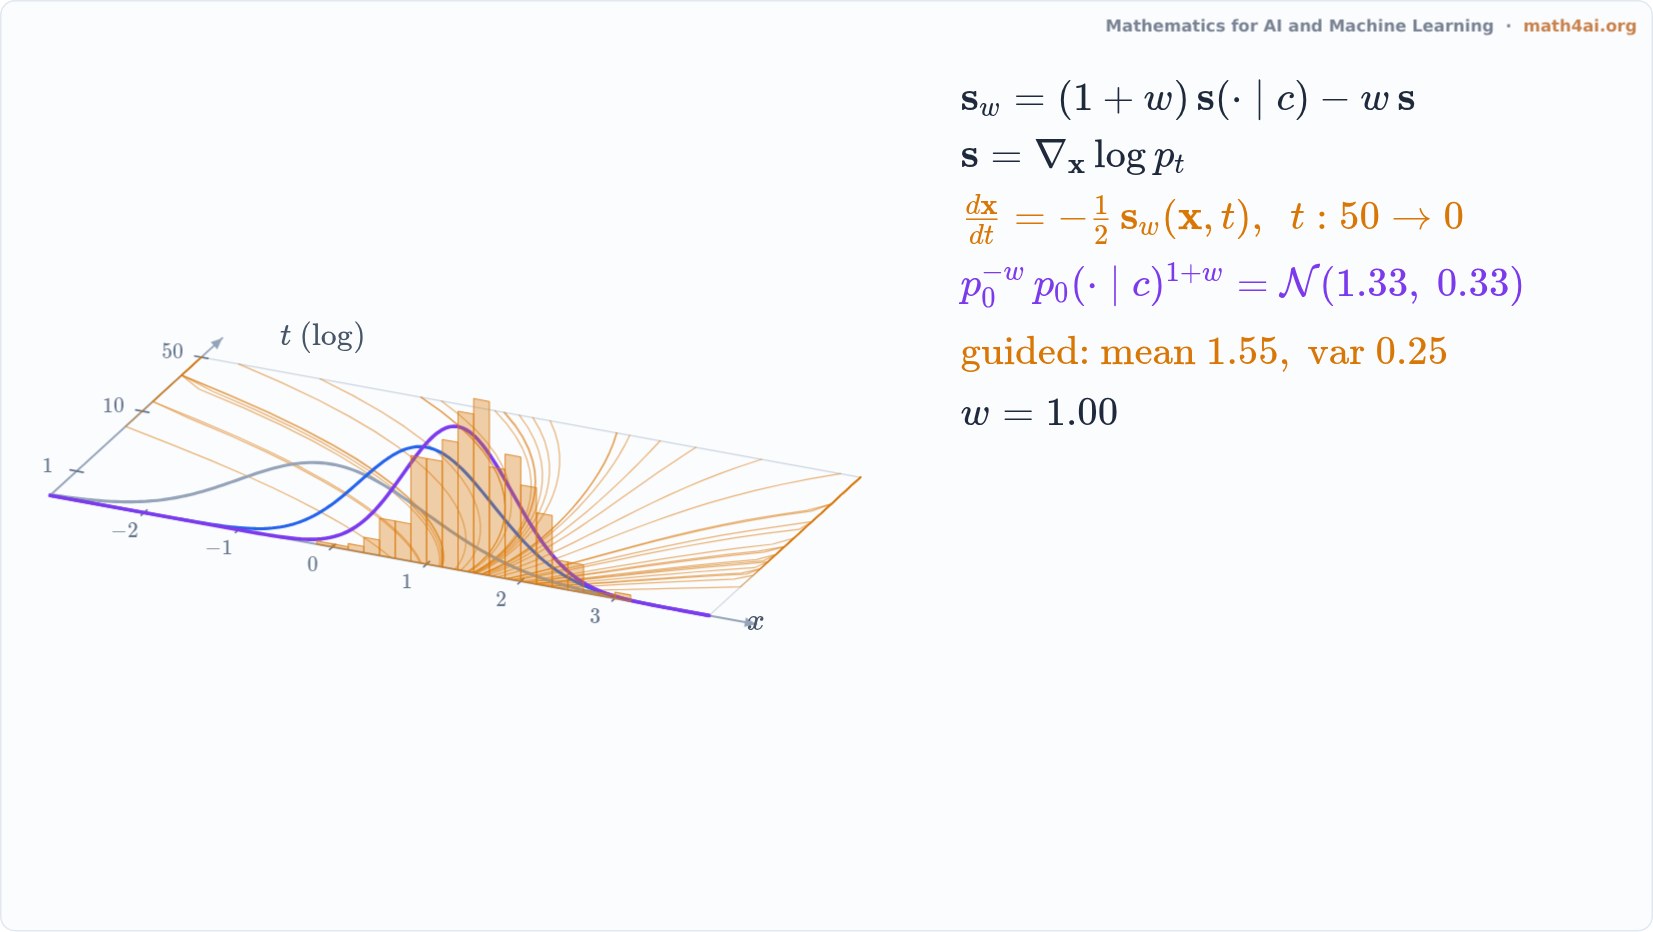 Preview1:27Guidance Does Not Sample the Sharpened DistributionChapter 21
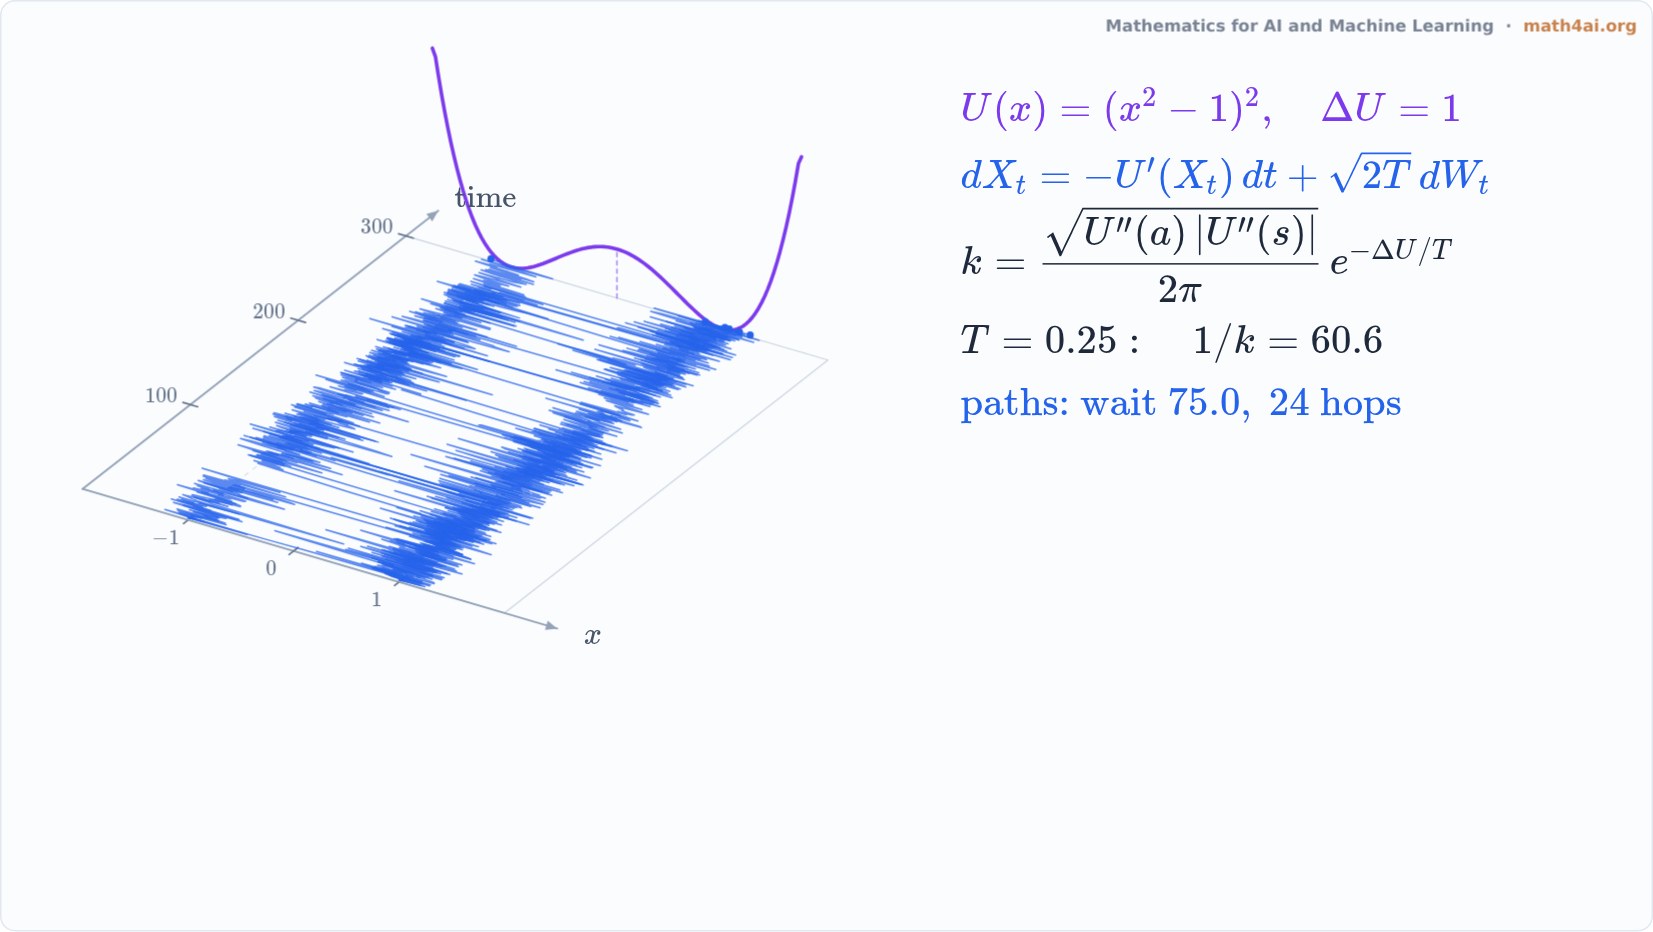 Preview1:50Metastability and the Kramers Escape RateChapter 21
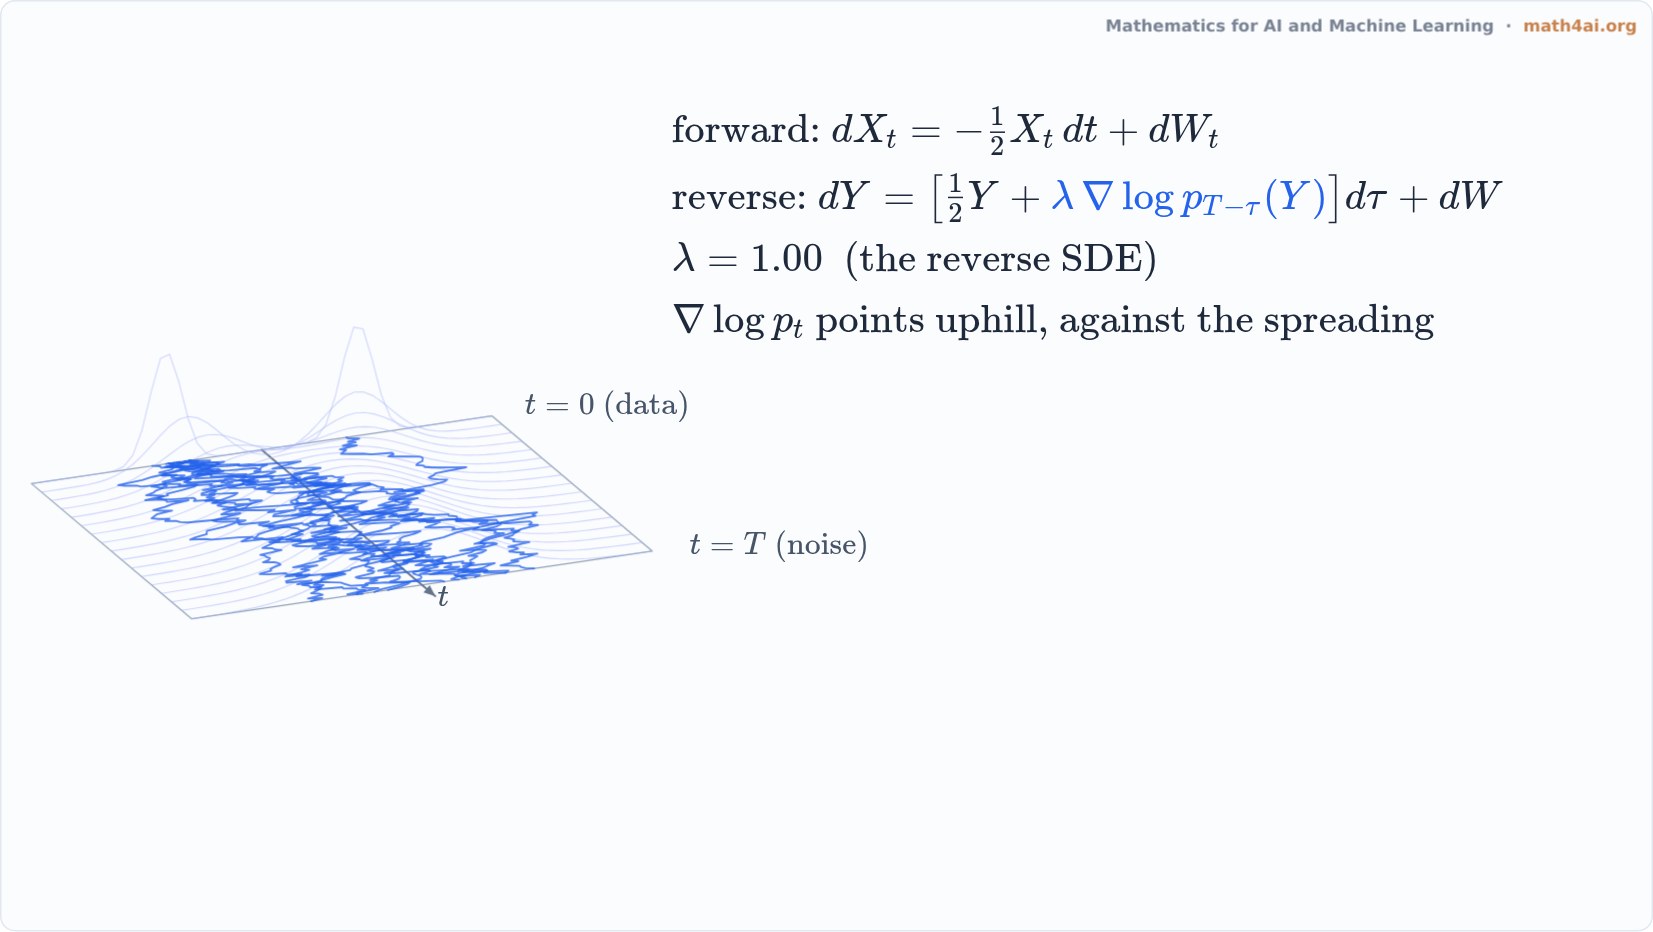 Preview1:26Reverse Time: Why We Must Learn the ScoreChapter 21
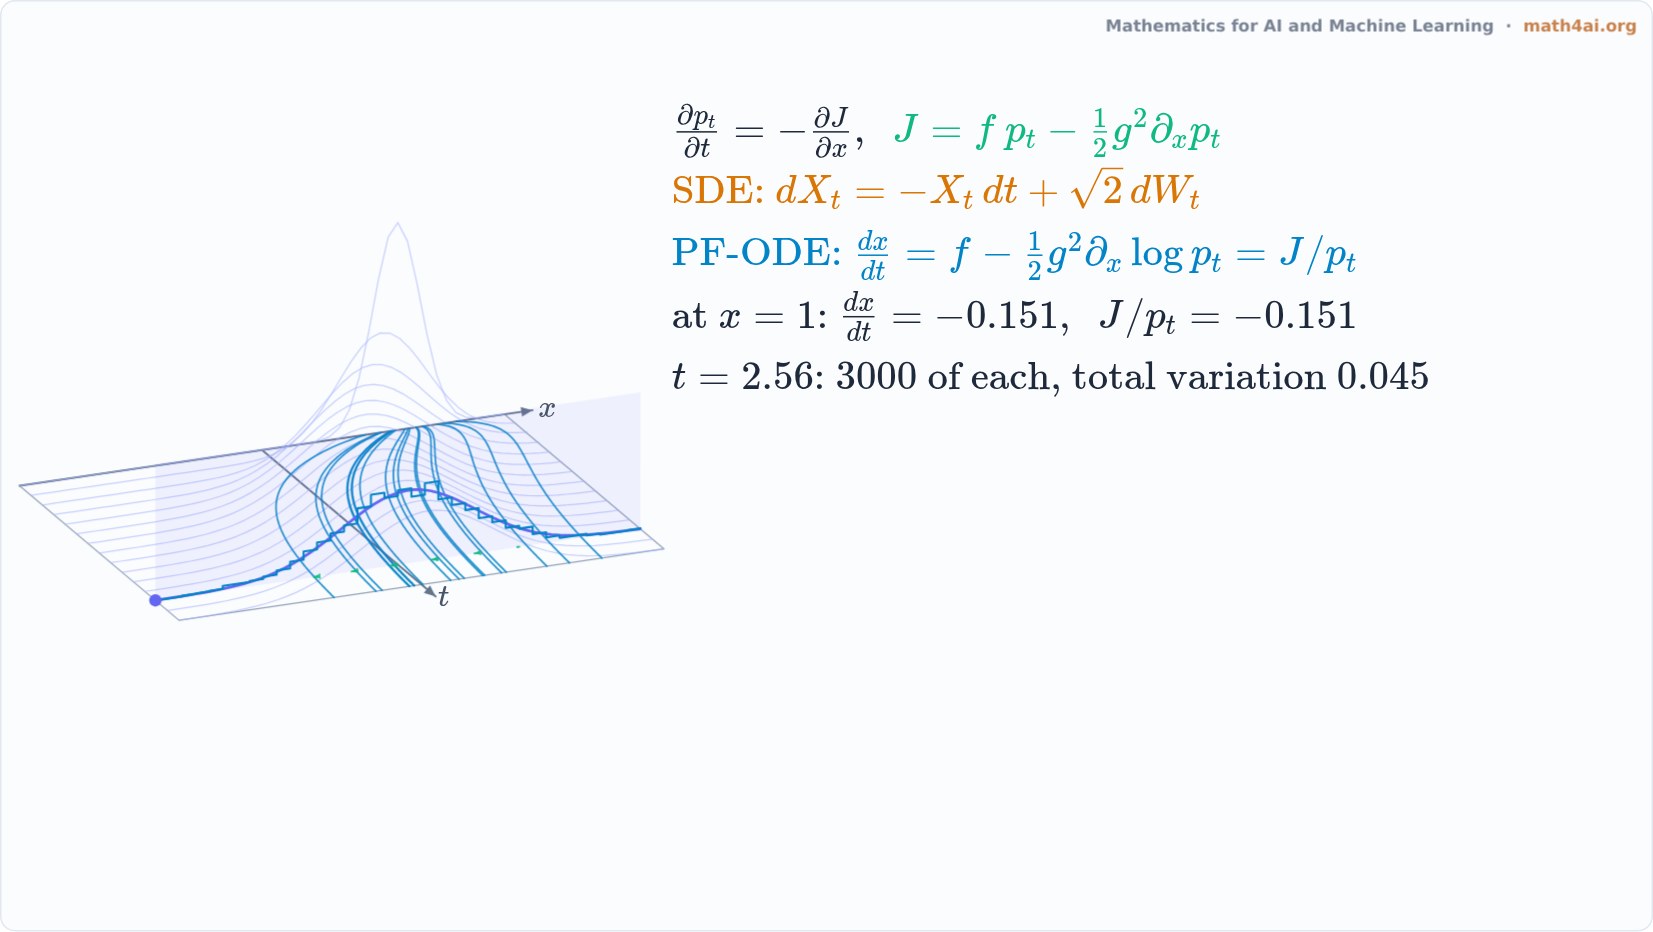 Preview1:34Unification: SDEs, Probability Flow ODEs, and Fokker-Planck DynamicsChapter 21
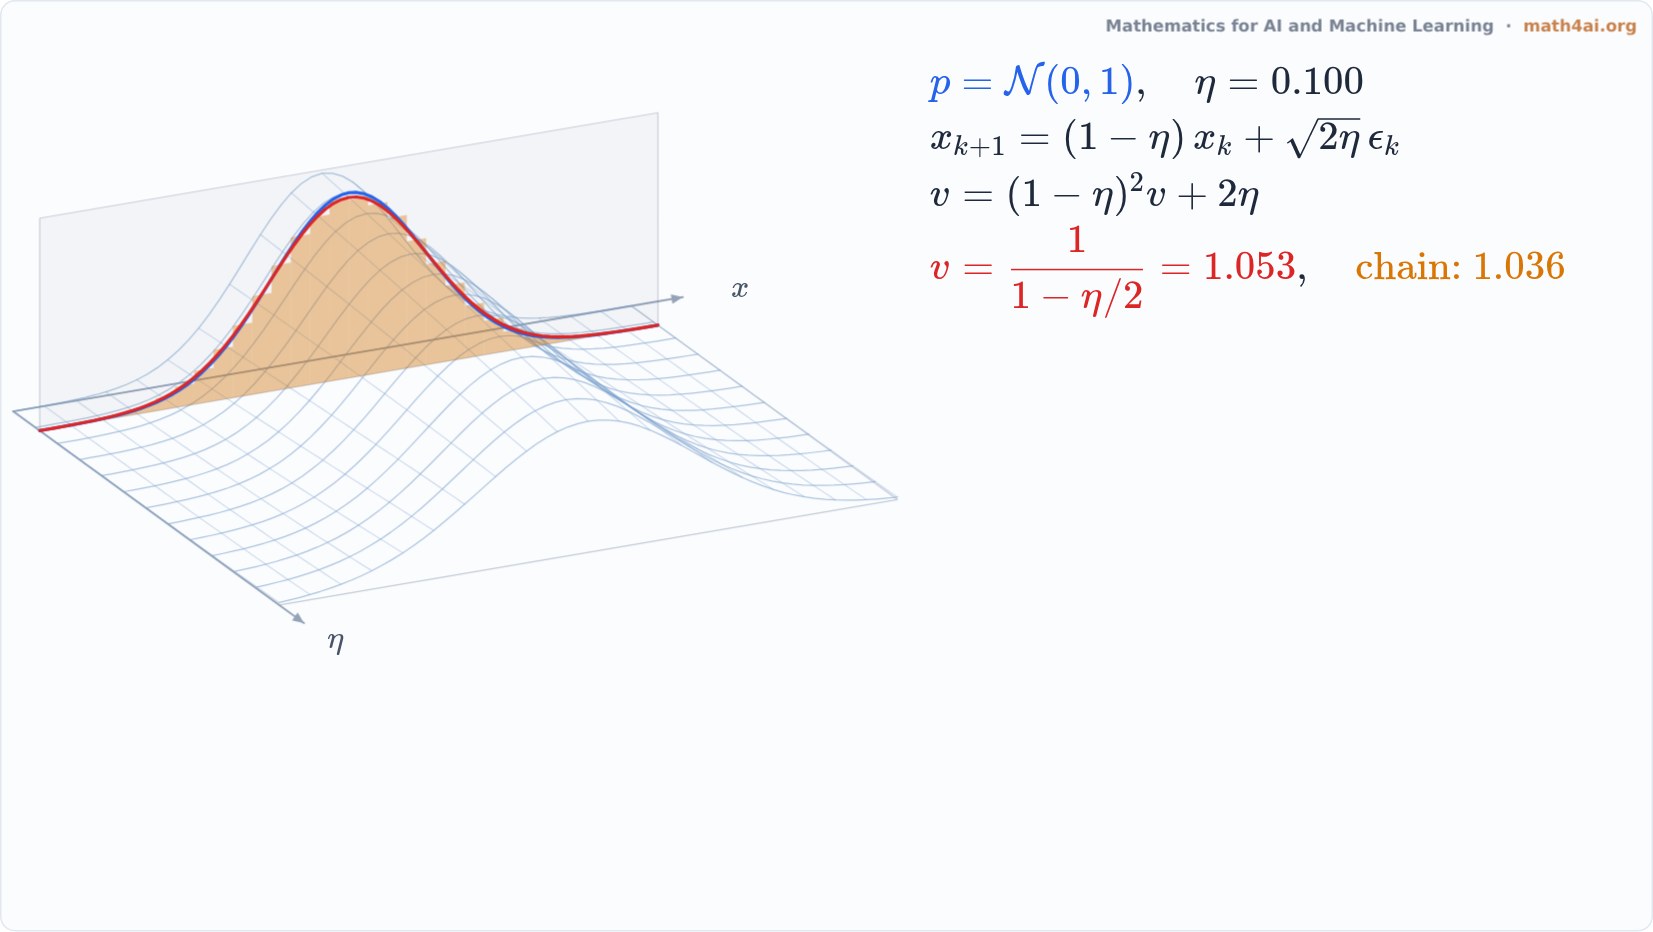 Preview1:52Discretization Changes the Stationary DistributionChapter 21
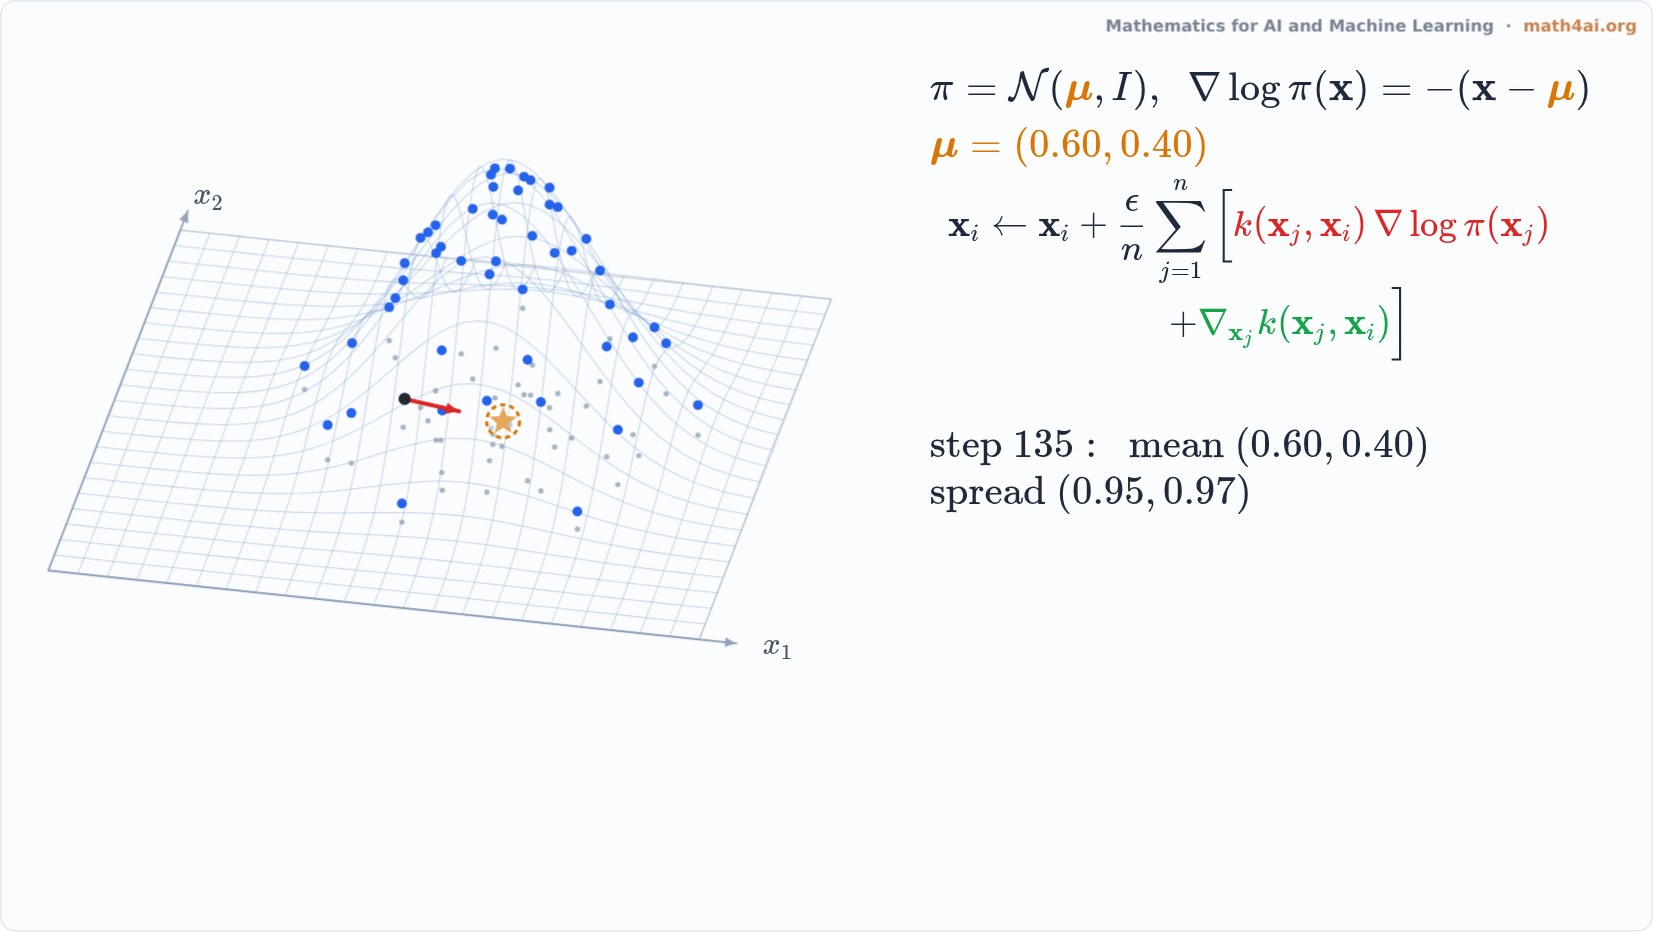 Preview1:29Stein Variational Gradient Descent: Pull and PushChapter 21