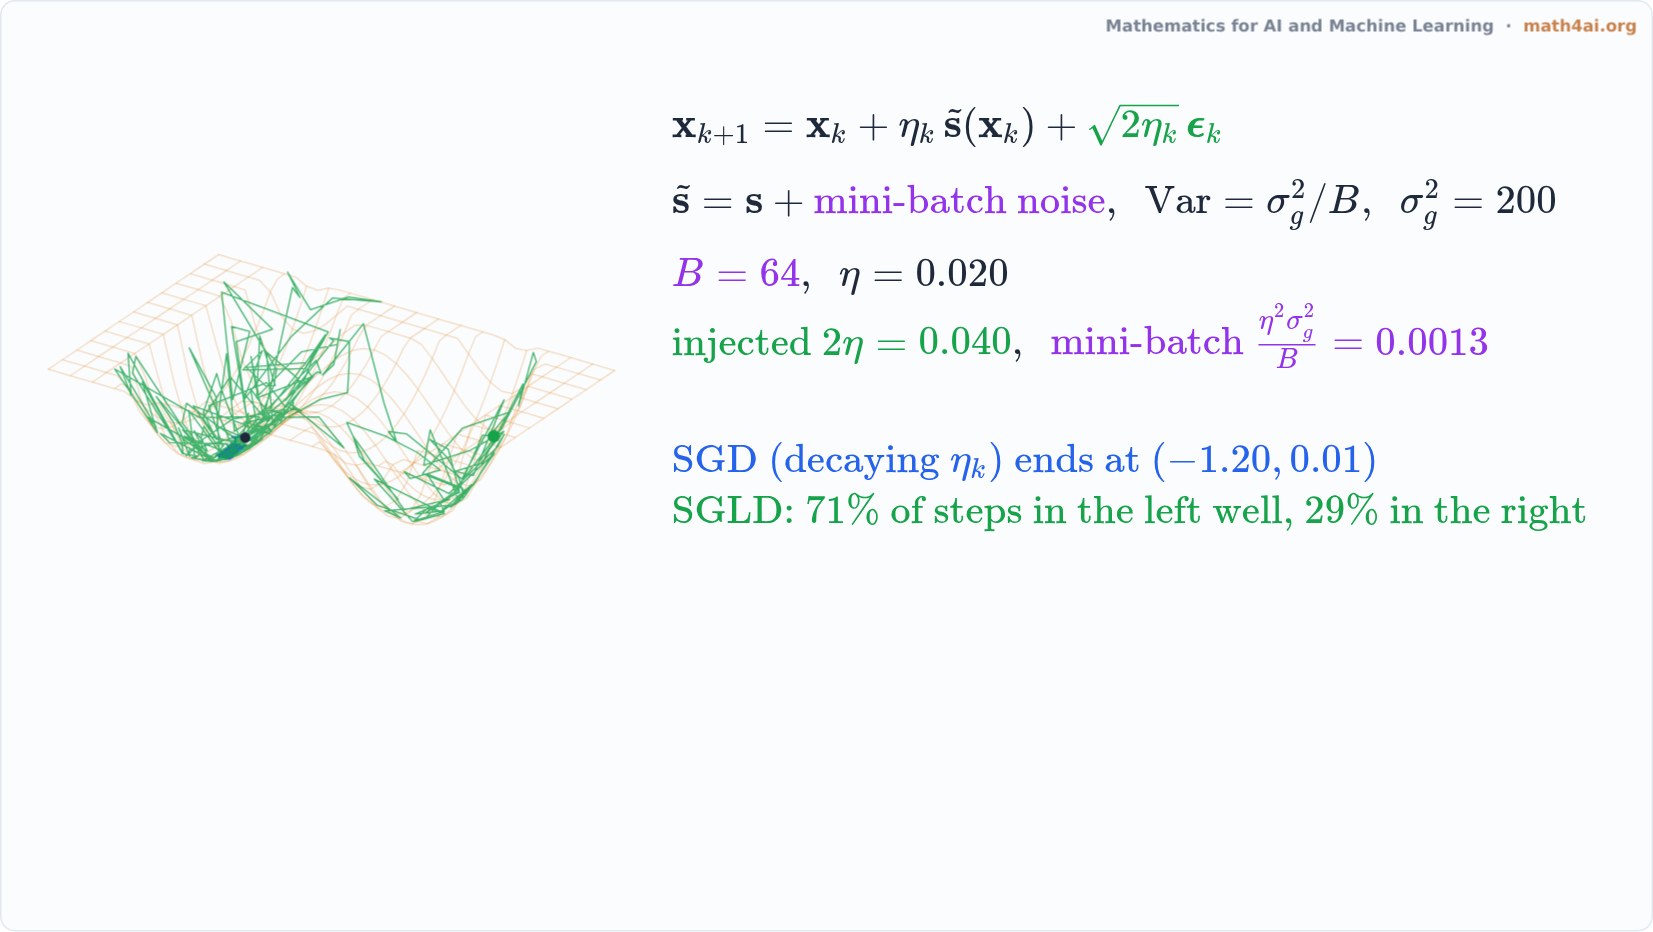
Langevin Dynamics and SGLD: Sampling vs Optimization
An interactive live film: mini-batch stochastic gradients vs injected Langevin thermal noise; SGD freezes in local minima, while SGLD explores the full posterior as injected noise dominates mini-batch variance.
Narration
Langevin sampling and stochastic gradient descent look remarkably alike. Both take gradient steps on an energy function, but they serve fundamentally different goals.
Stochastic gradient descent is an optimizer. It decays its learning rate to freeze at the nearest local minimum, seeking a single point estimate.
The rest of the narration is in the book's Companion.
More from Chapter 18
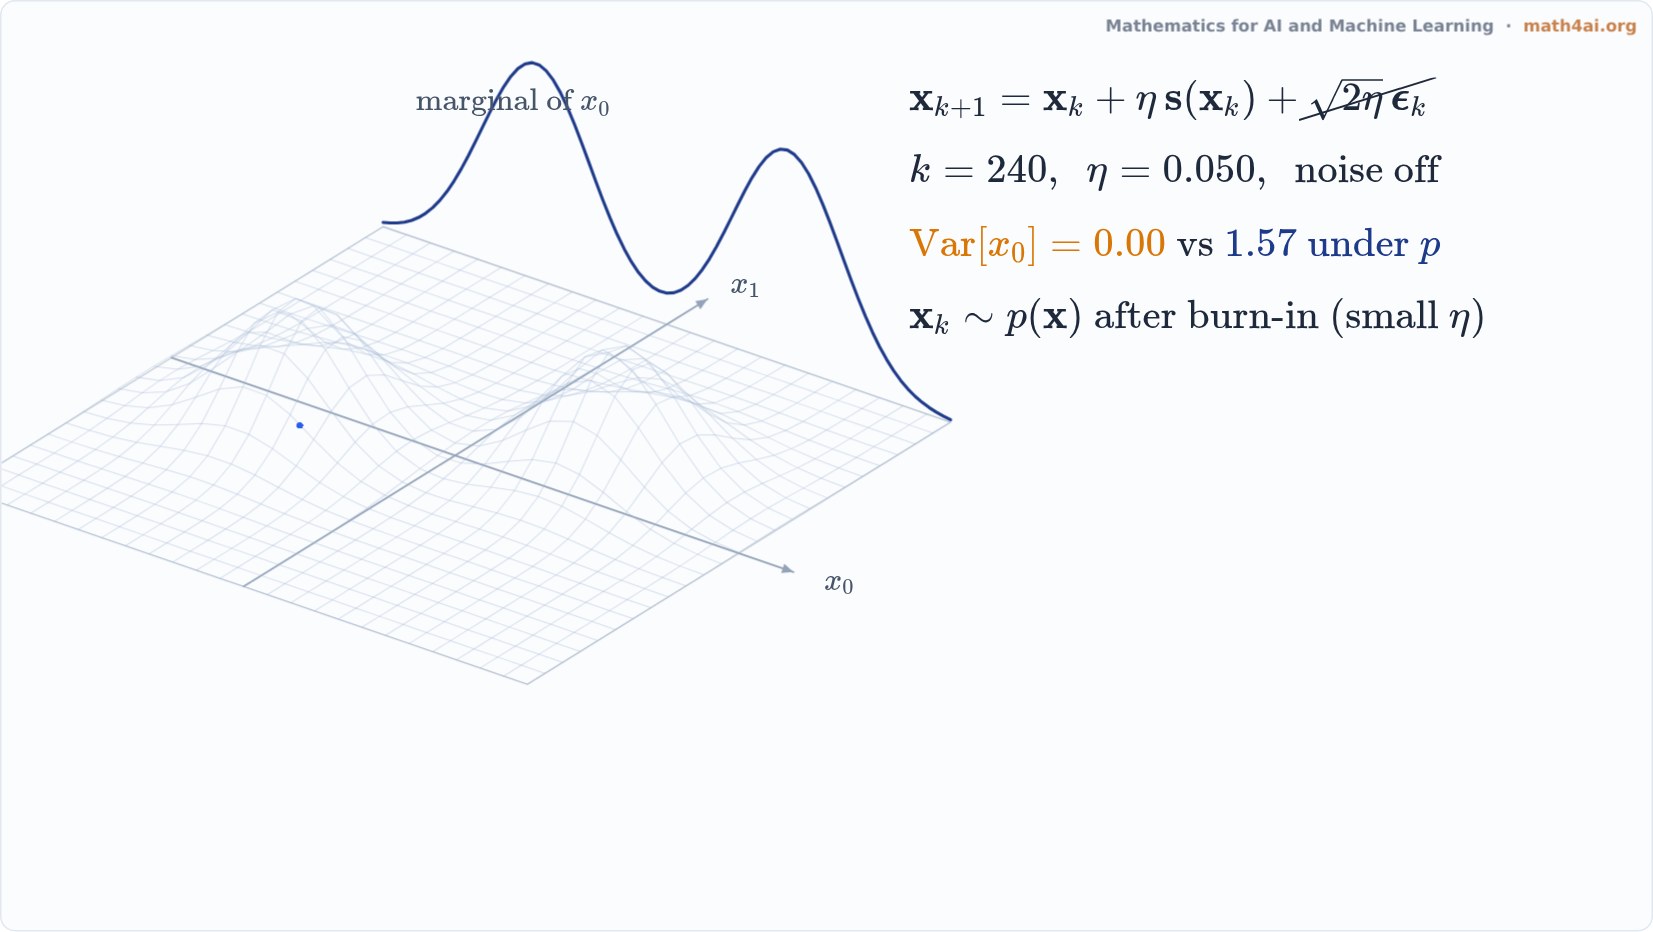 Interactive1:22Langevin Sampling: Drift Uphill, Kick at RandomChapter 18
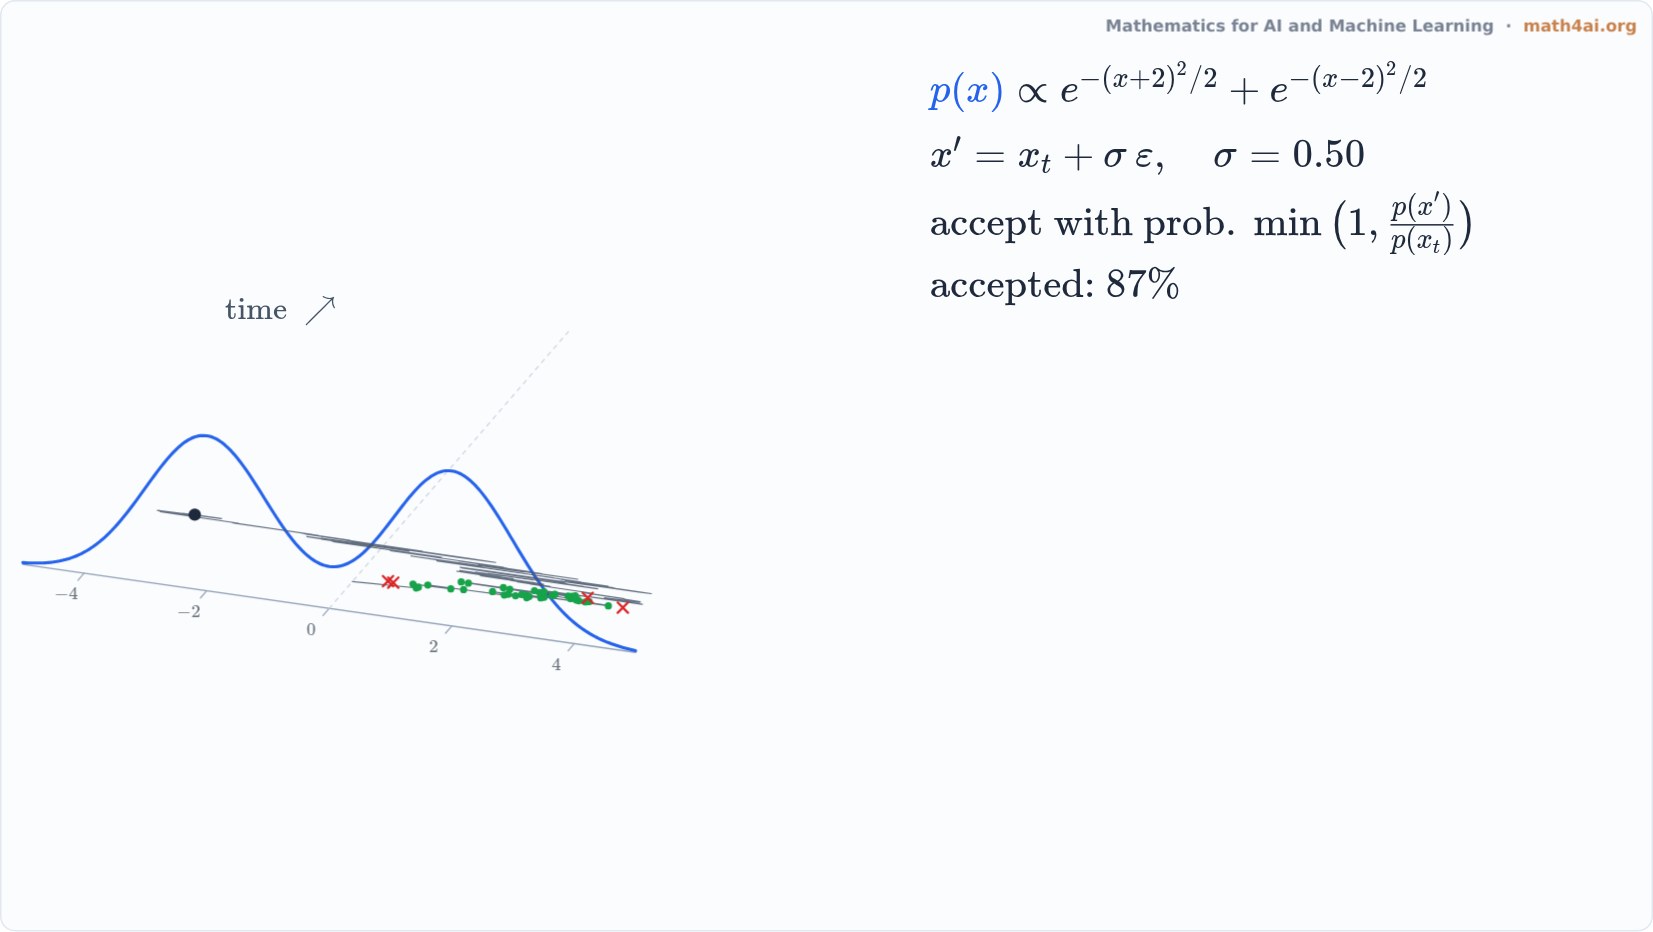 Preview1:24Metropolis-Hastings: A Random Walk That SamplesChapter 18
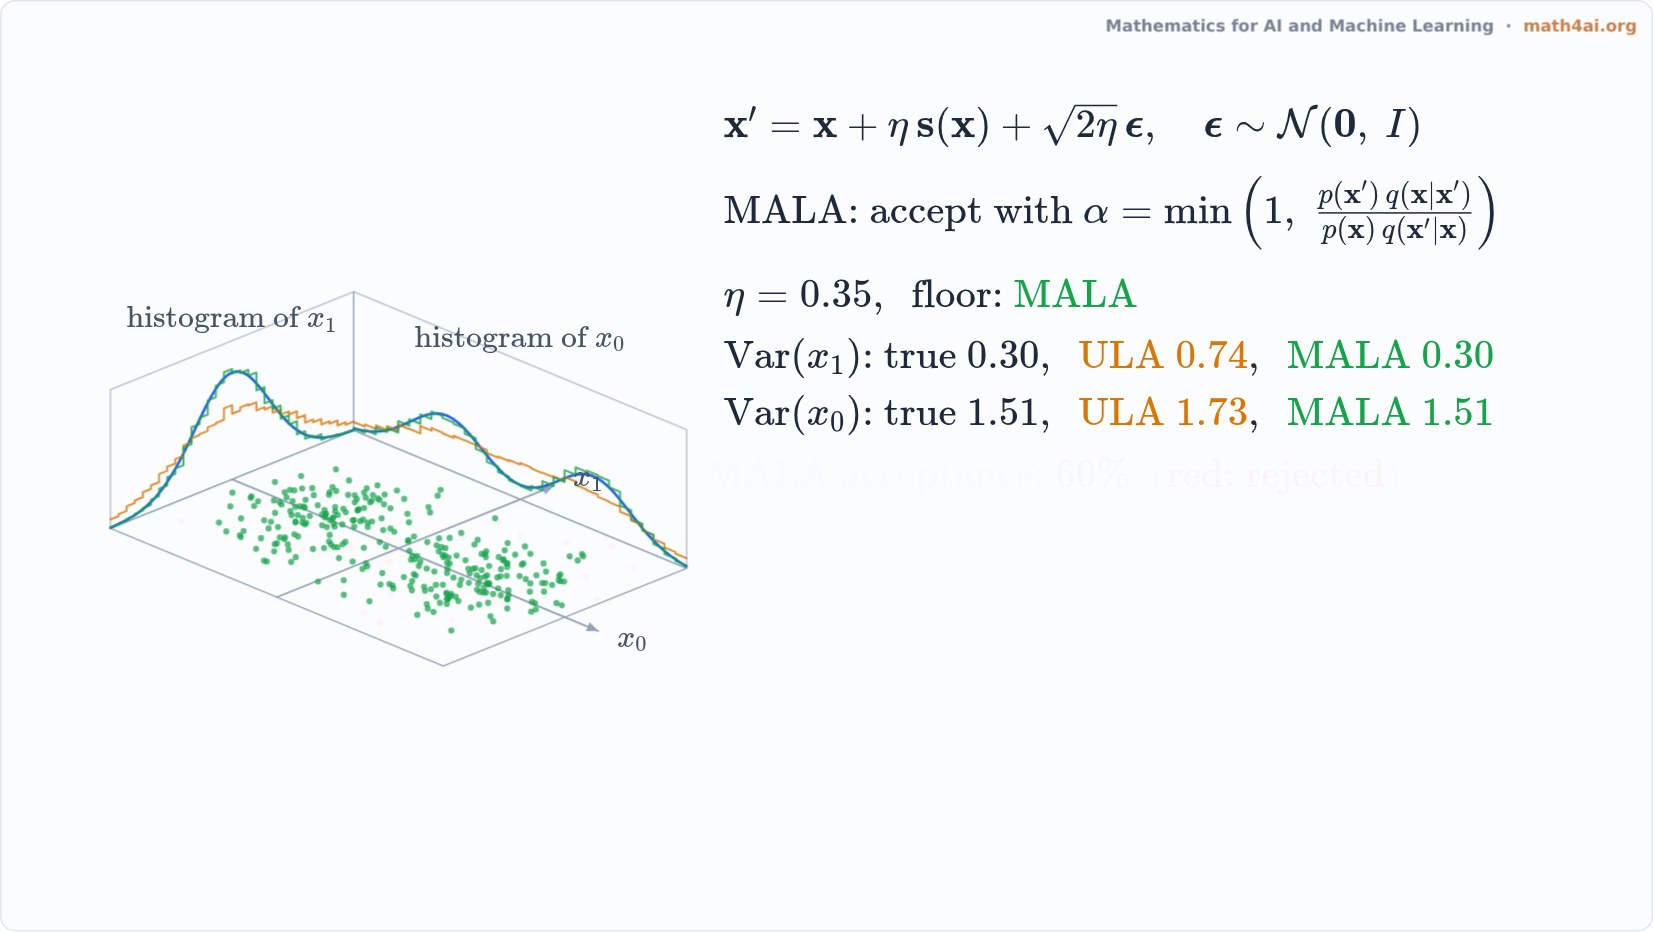 Preview1:42MALA: Removing Discretization Bias with Accept-RejectChapter 18
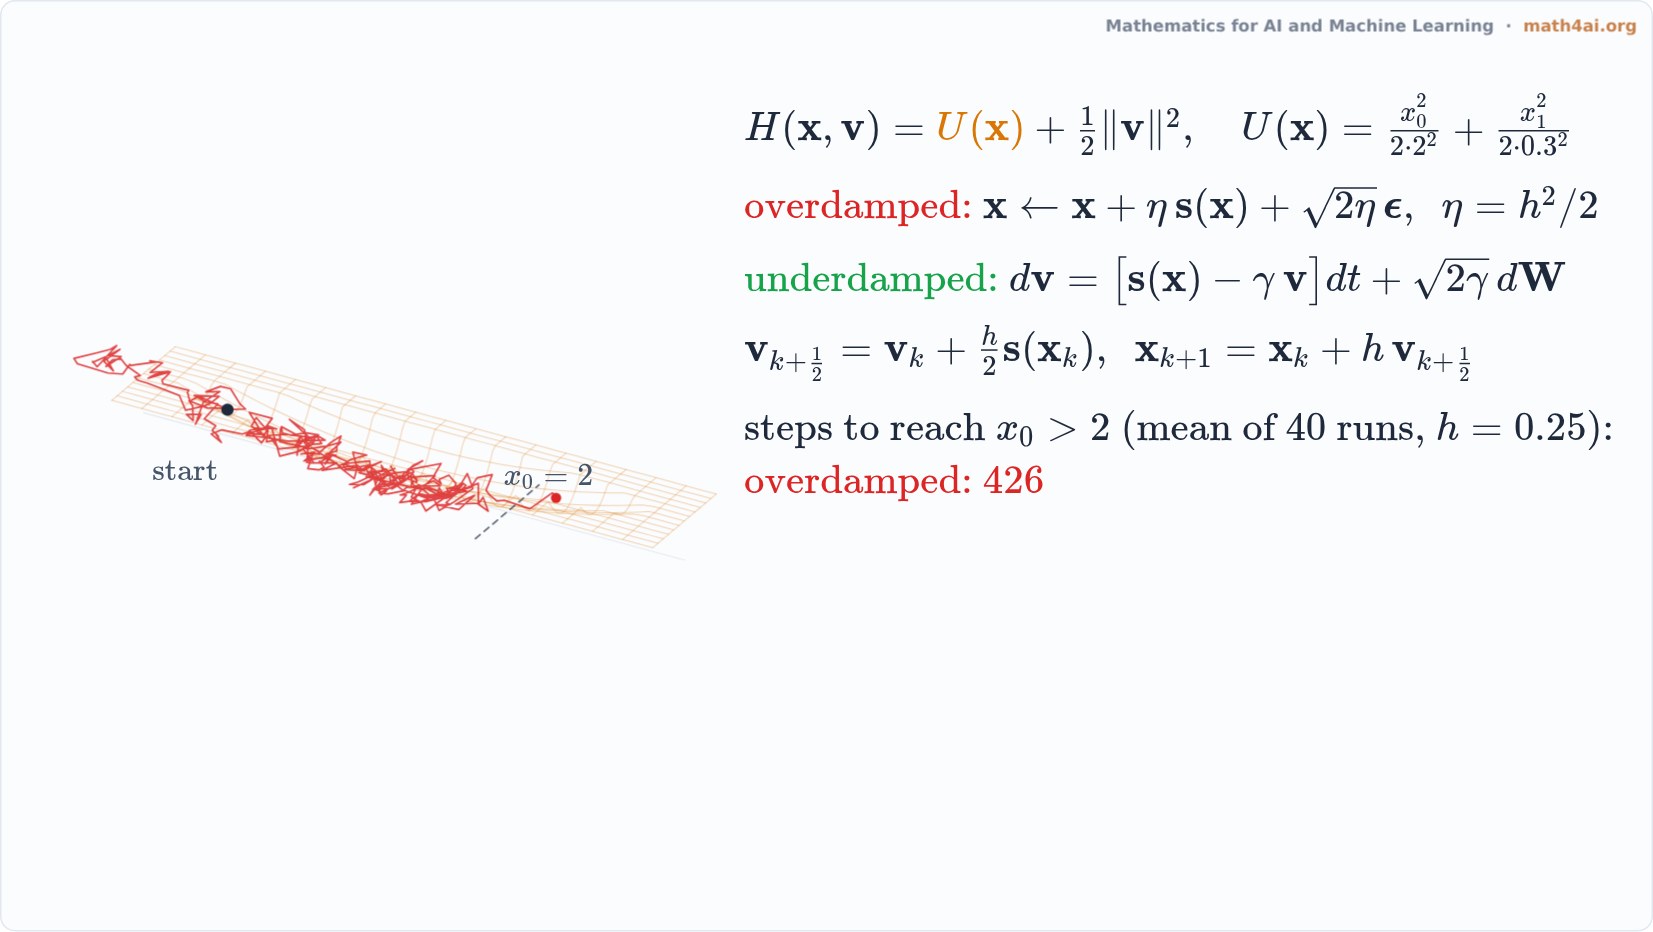 Preview1:40Underdamped Langevin and HMC: Momentum-Driven ExplorationChapter 18
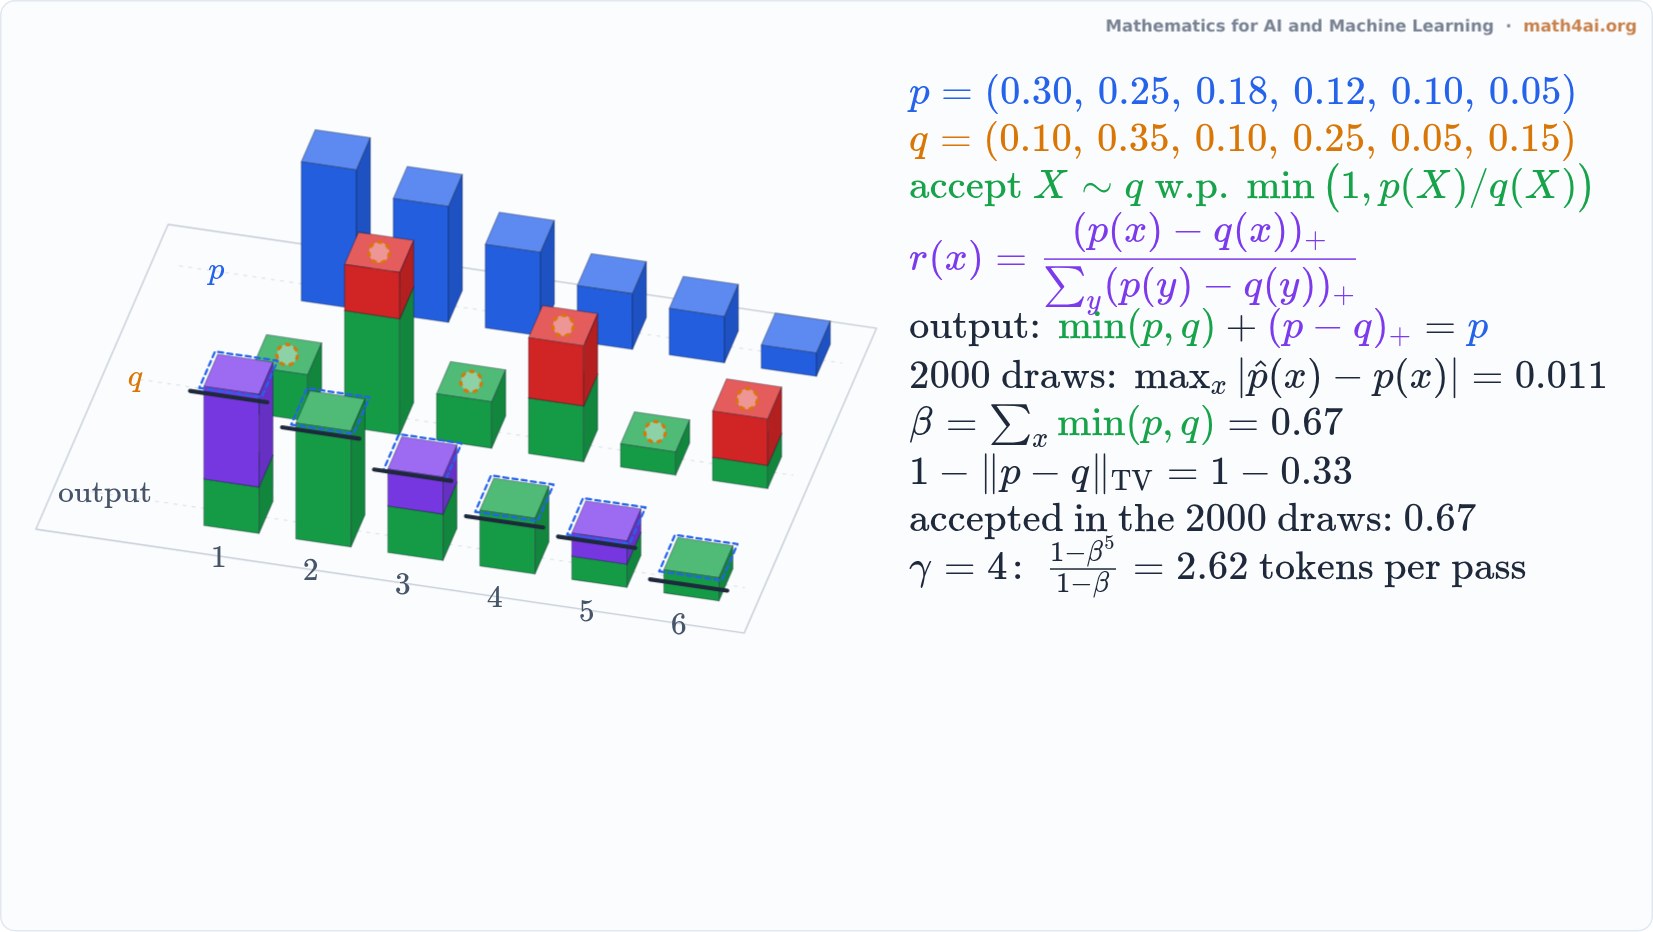 Preview1:46Speculative Decoding: Exact Sampling With a Draft ModelChapter 18