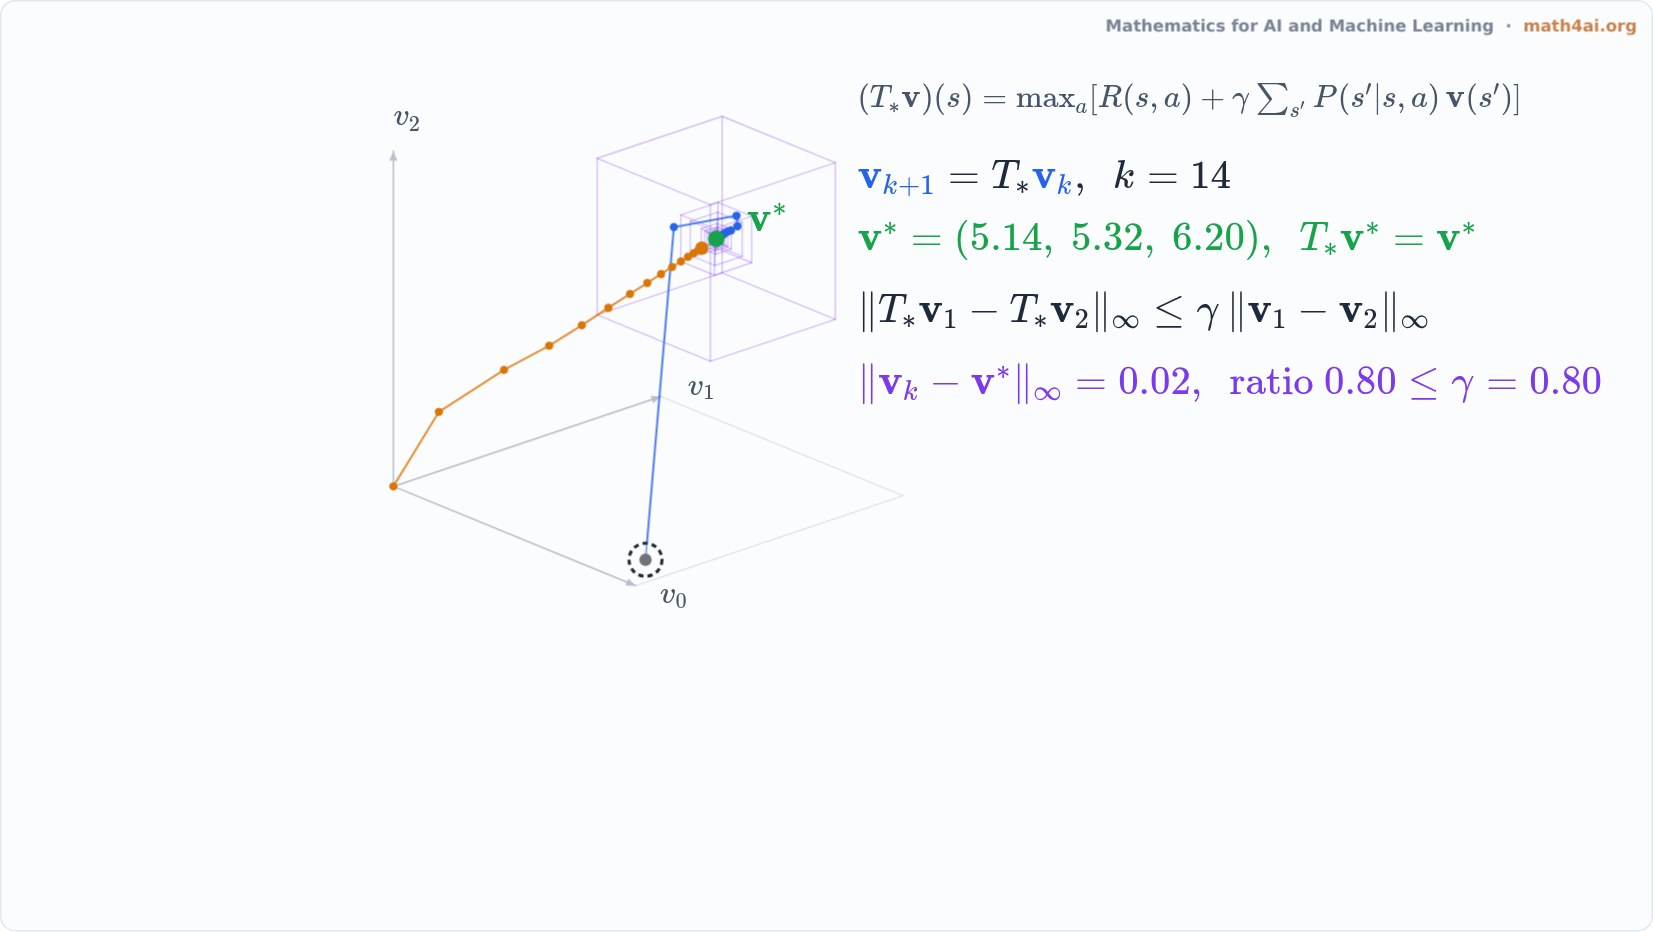
Bellman Operator: A Contraction With One Fixed Point
An interactive live film: value functions of a three-state problem are points in 3D; value iteration from any start walks to v*, inside sup-norm cubes that shrink by gamma every step.
Narration
A small decision problem has three states, so a value function is just a vector with three entries: a point in three dimensional space.
The Bellman optimality operator takes a value vector and returns a new one. For each state, it takes the best action: its reward, plus gamma times the expected value of the next state.
The rest of the narration is in the book's Companion.
More from Chapter 15
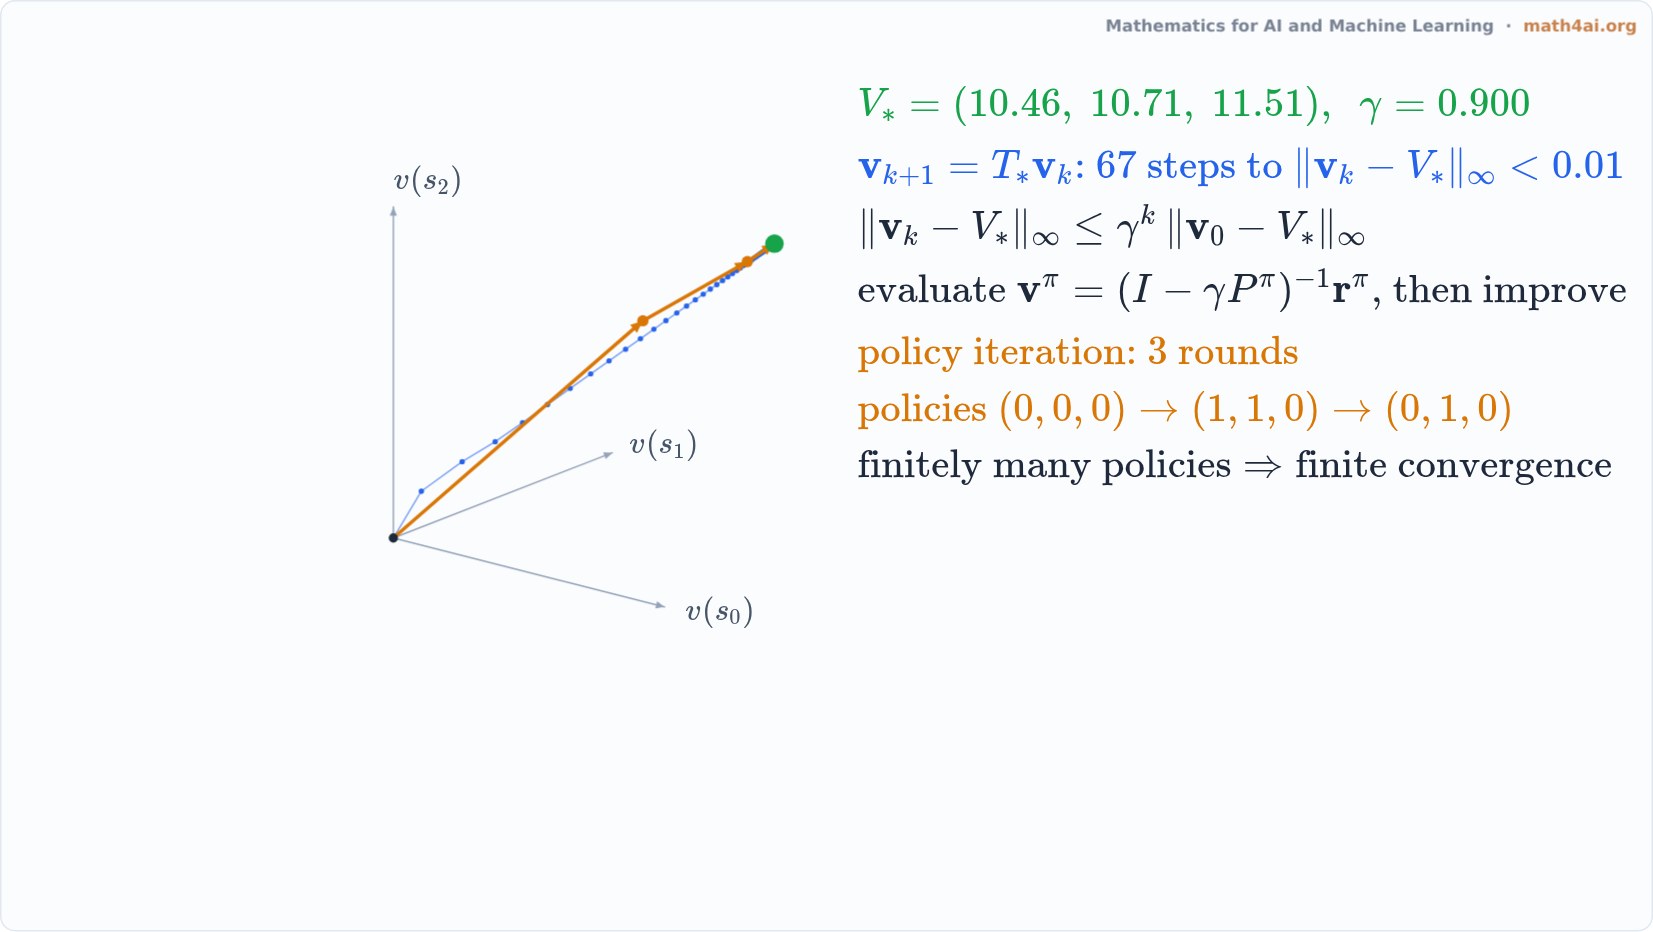 Interactive1:41Value Iteration and Policy Iteration: Many Small Steps or a Few Big JumpsChapter 15
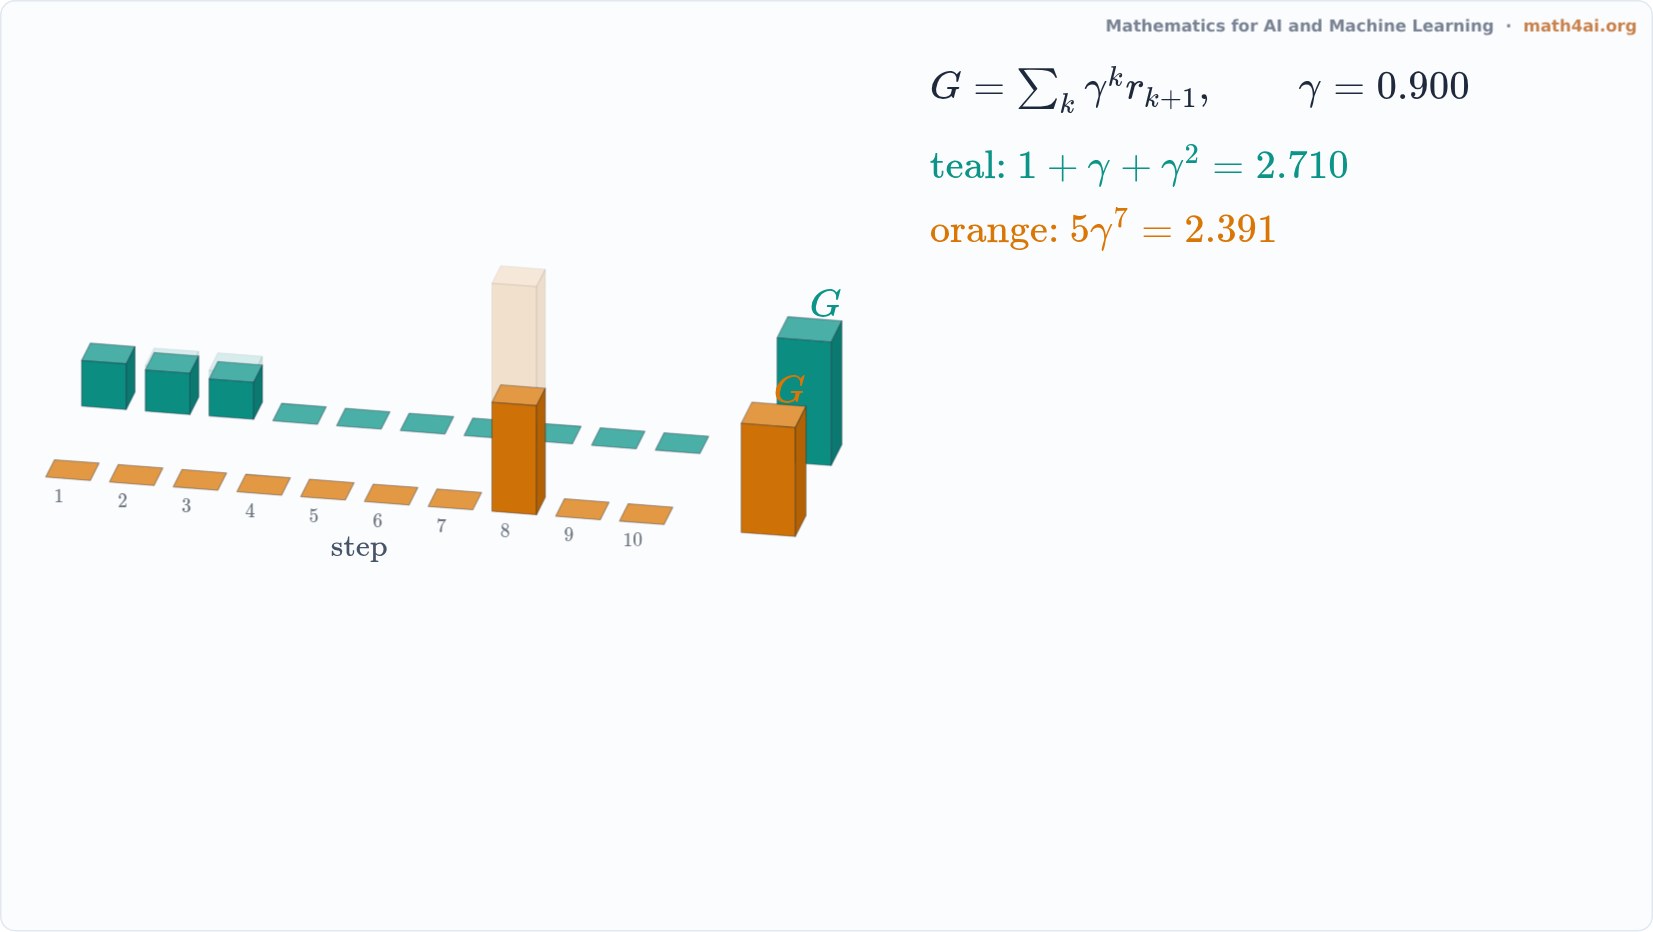 Preview1:32The Discounted Return: Now or LaterChapter 15
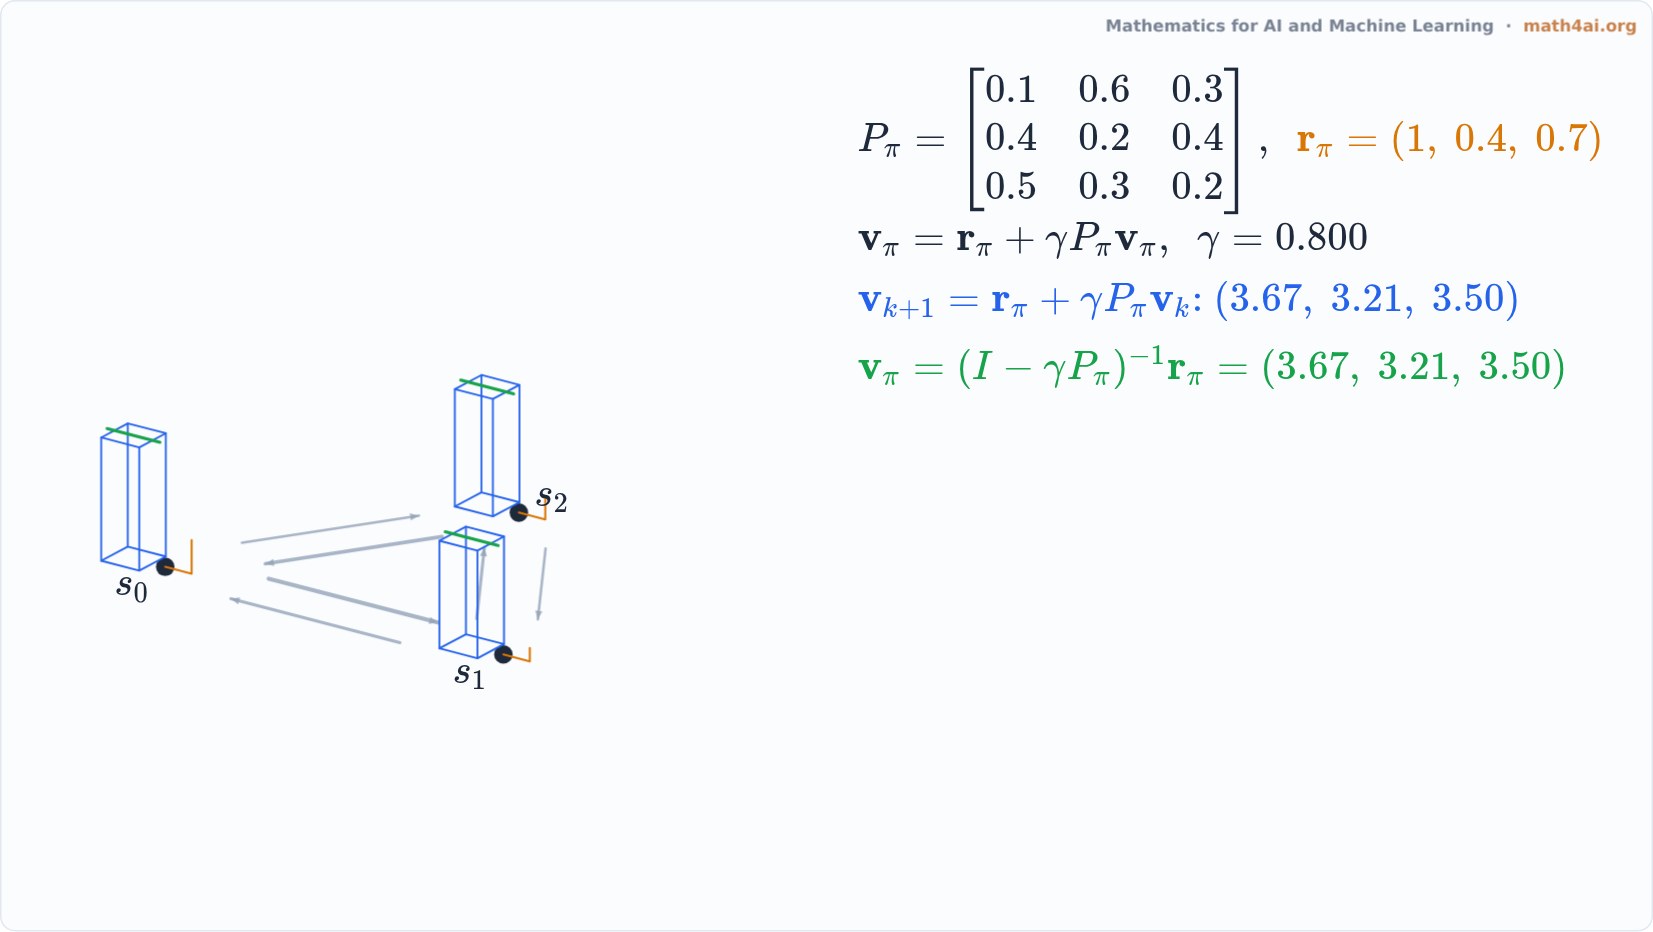 Preview1:39The Bellman Equation as a Linear SystemChapter 15
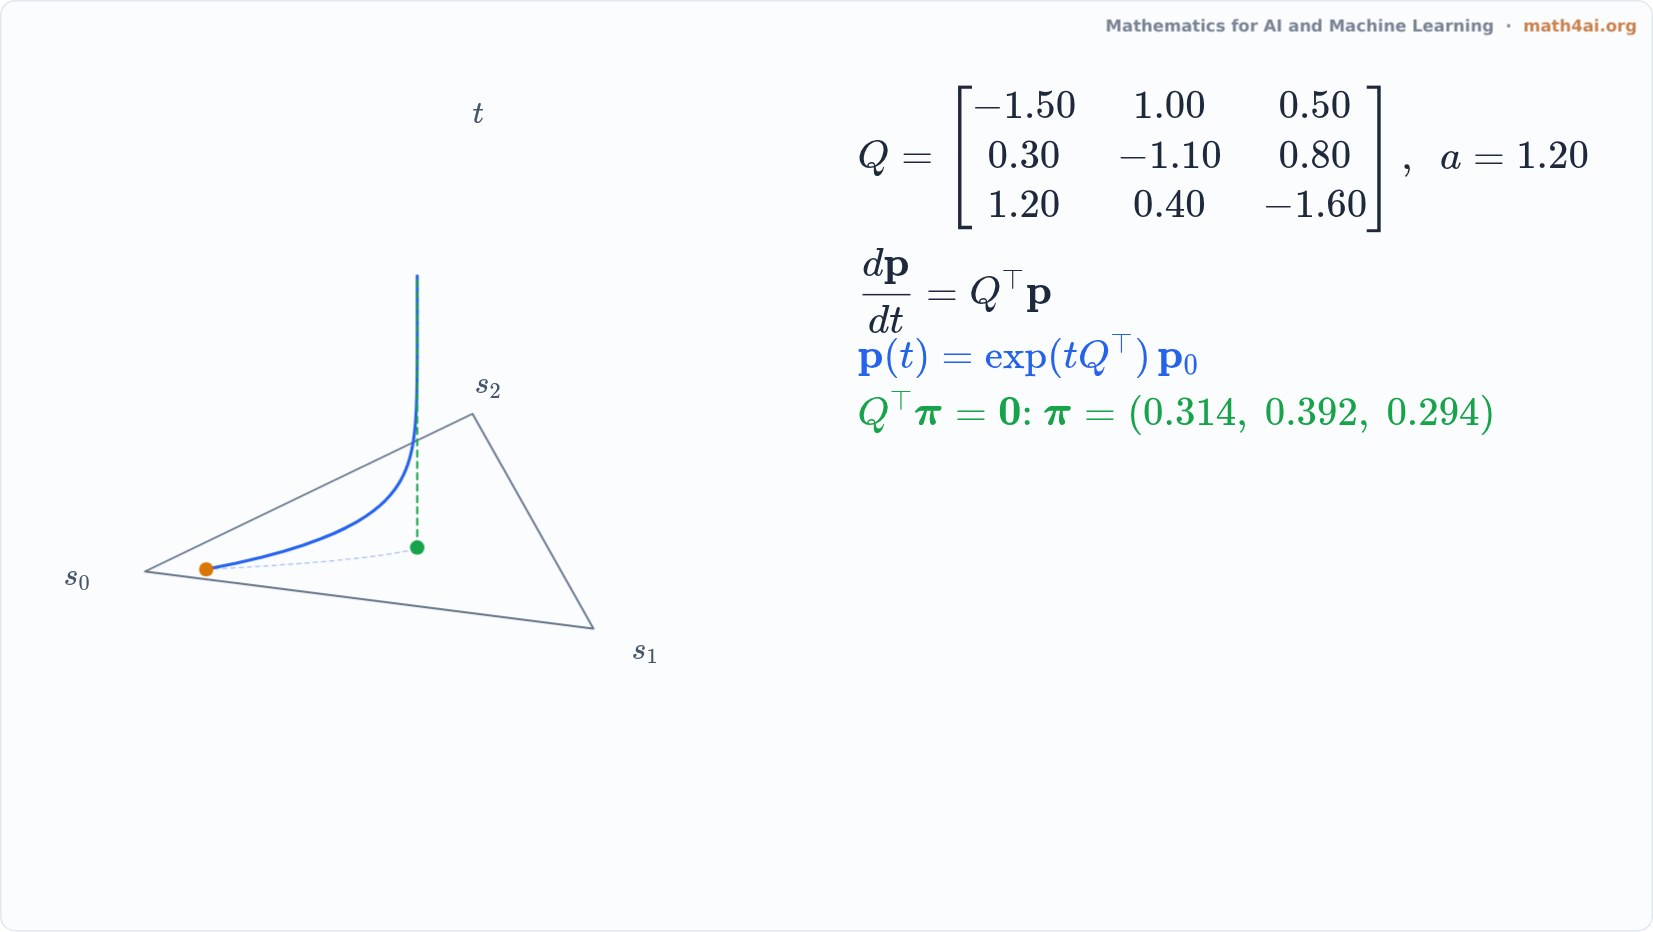 Preview1:34Continuous-Time Markov Chains: Probability Flowing on a TriangleChapter 15
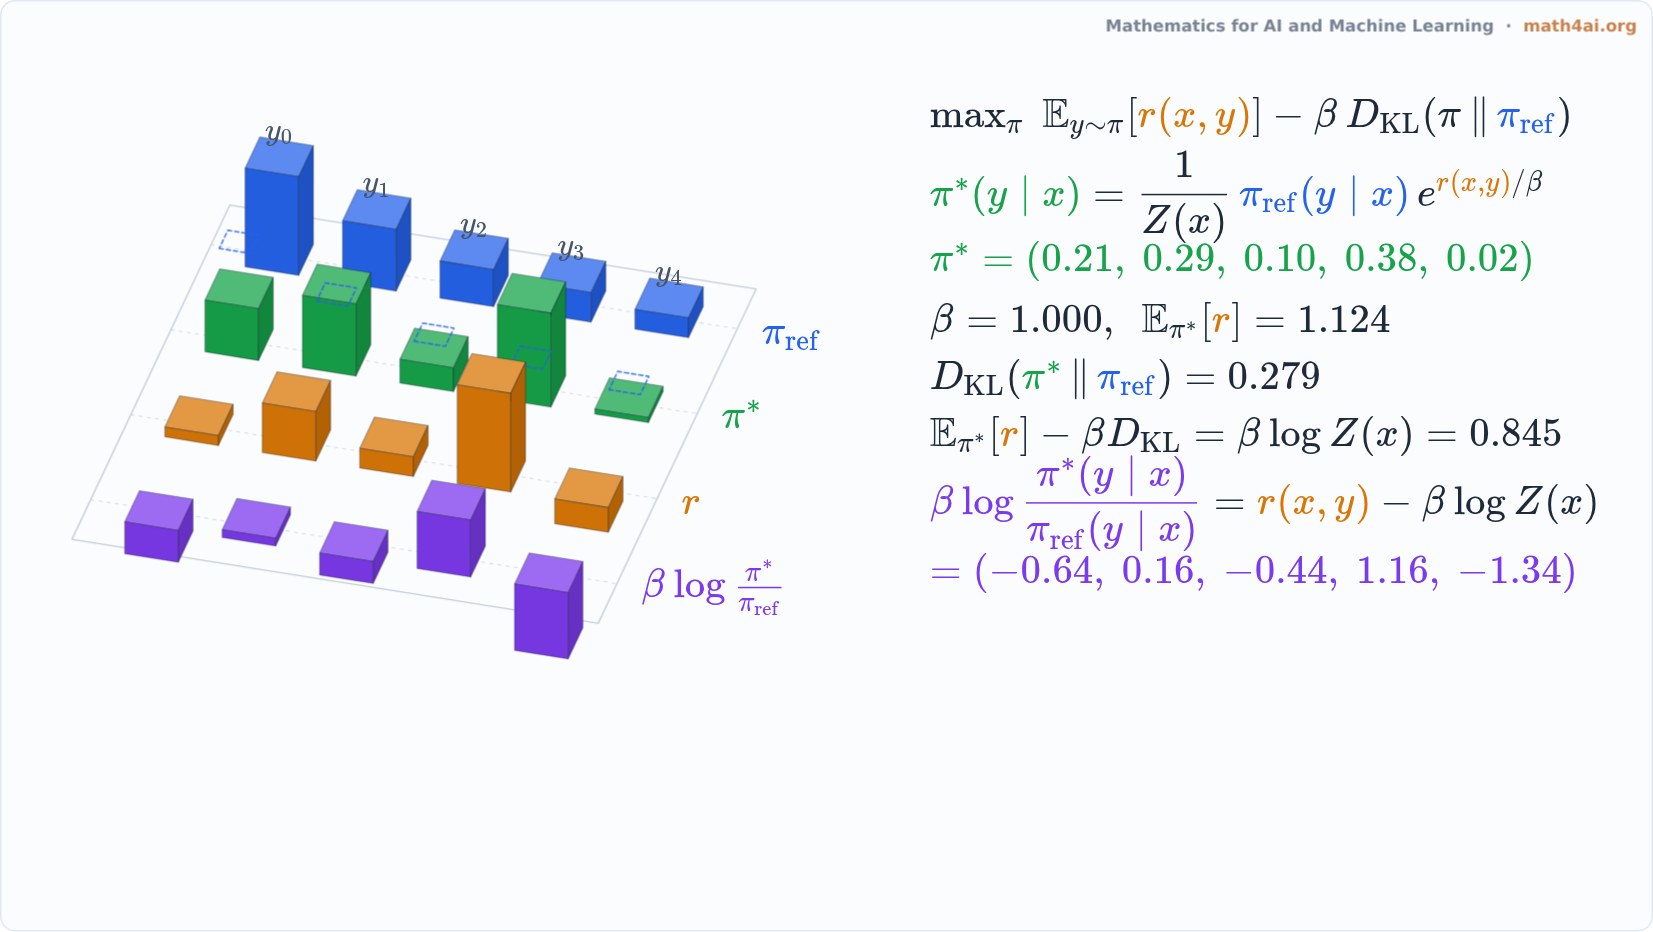 Preview1:58The KL-Regularized Optimal PolicyChapter 15
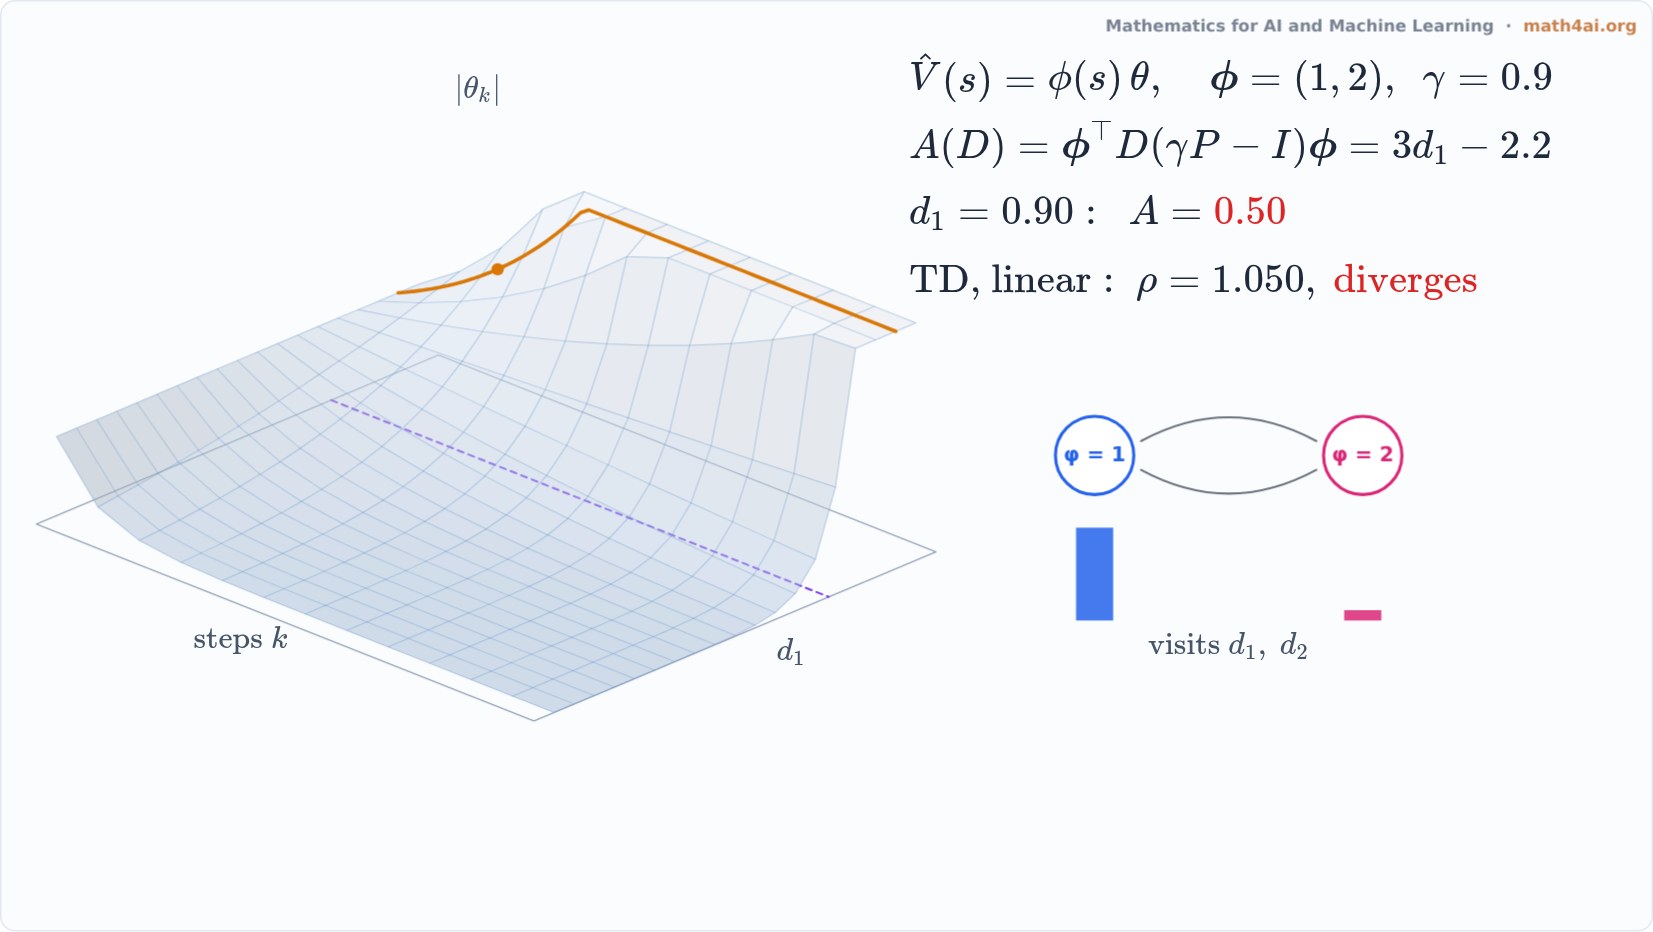 Preview1:51The Deadly Triad: When TD Learning ExplodesChapter 15