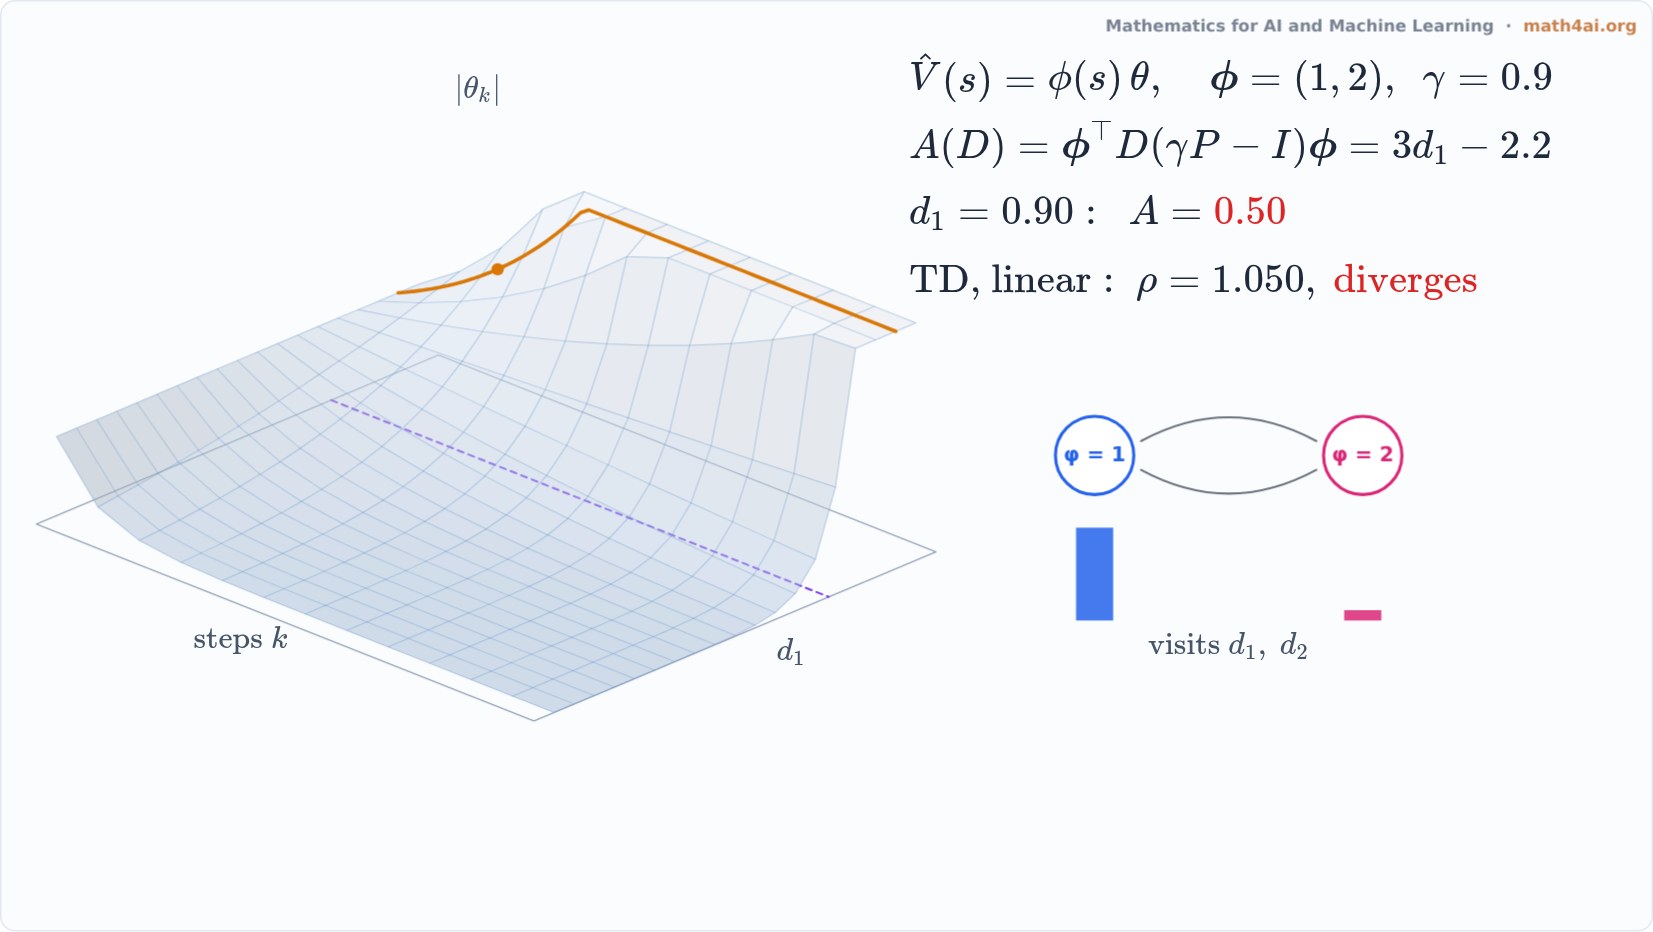
The Deadly Triad: When TD Learning Explodes
An interactive live film on the book's two-state example: the size of the TD estimate as a surface over steps and sampling share. Past d₁ ≈ 0.73 it explodes; tabular values or Monte Carlo targets tame it.
Narration
A tiny problem: two states that take turns, and no reward at all, so every true value is zero. We learn it with a single weight theta. The estimate for a state is its feature times theta: one for the first state, two for the second.
Temporal difference learning moves theta towards a bootstrapped target: the discount times the estimate at the next state. Averaged over the states we sample, each step multiplies theta by one plus alpha times a number A.
The rest of the narration is in the book's Companion.
More from Chapter 15
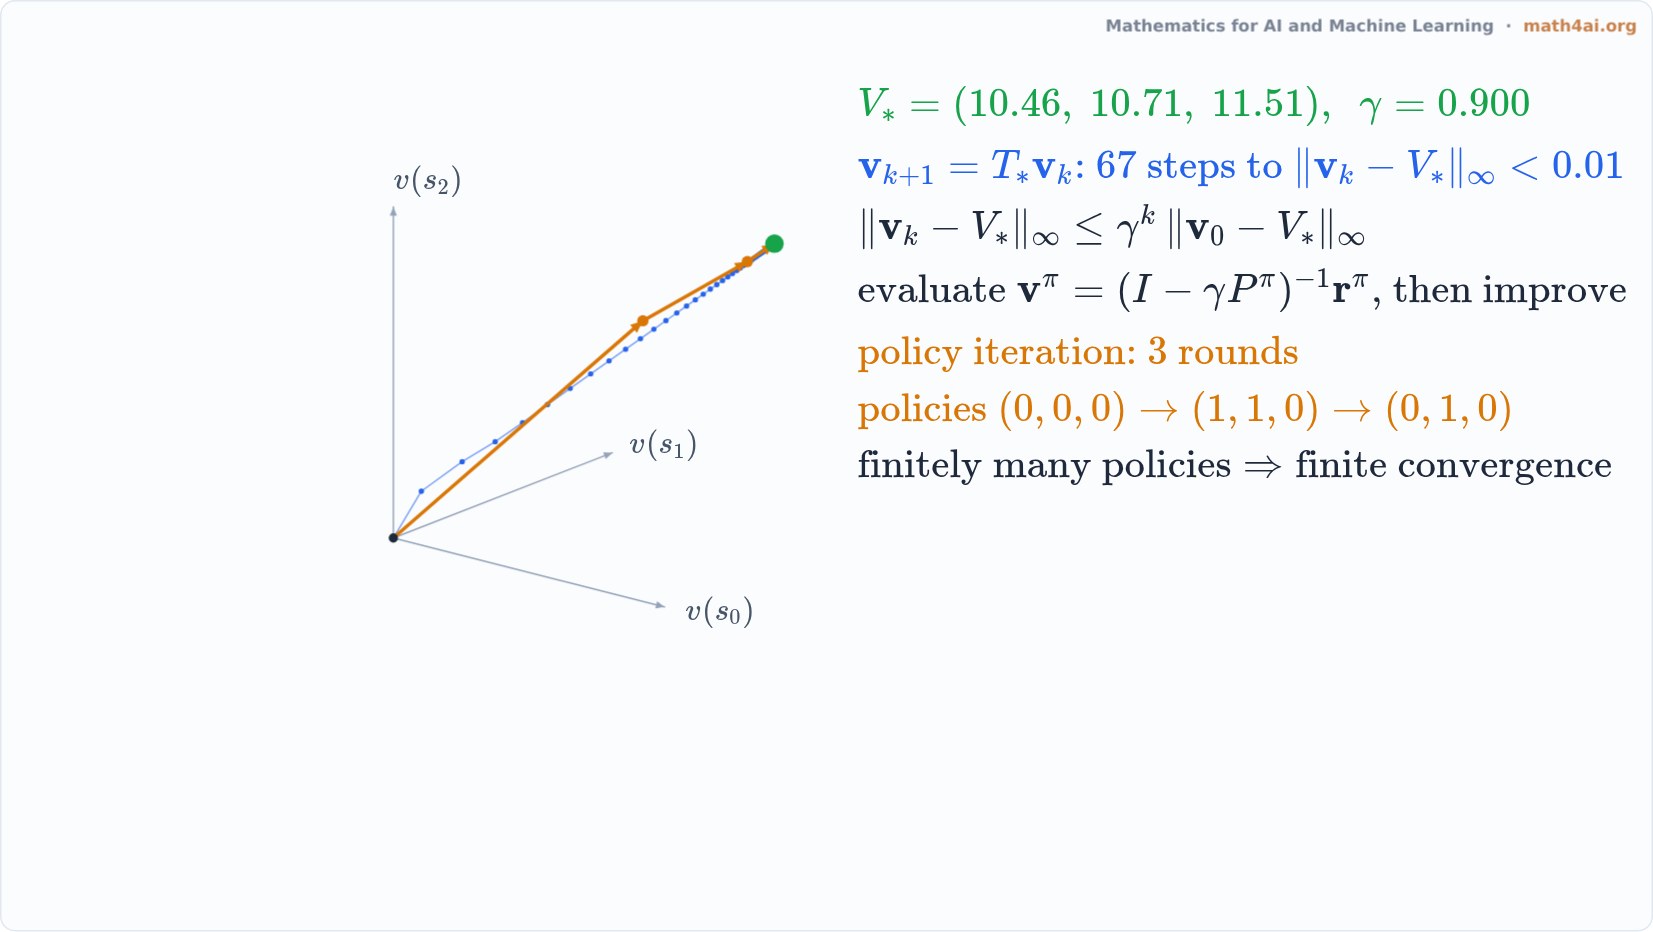 Interactive1:41Value Iteration and Policy Iteration: Many Small Steps or a Few Big JumpsChapter 15
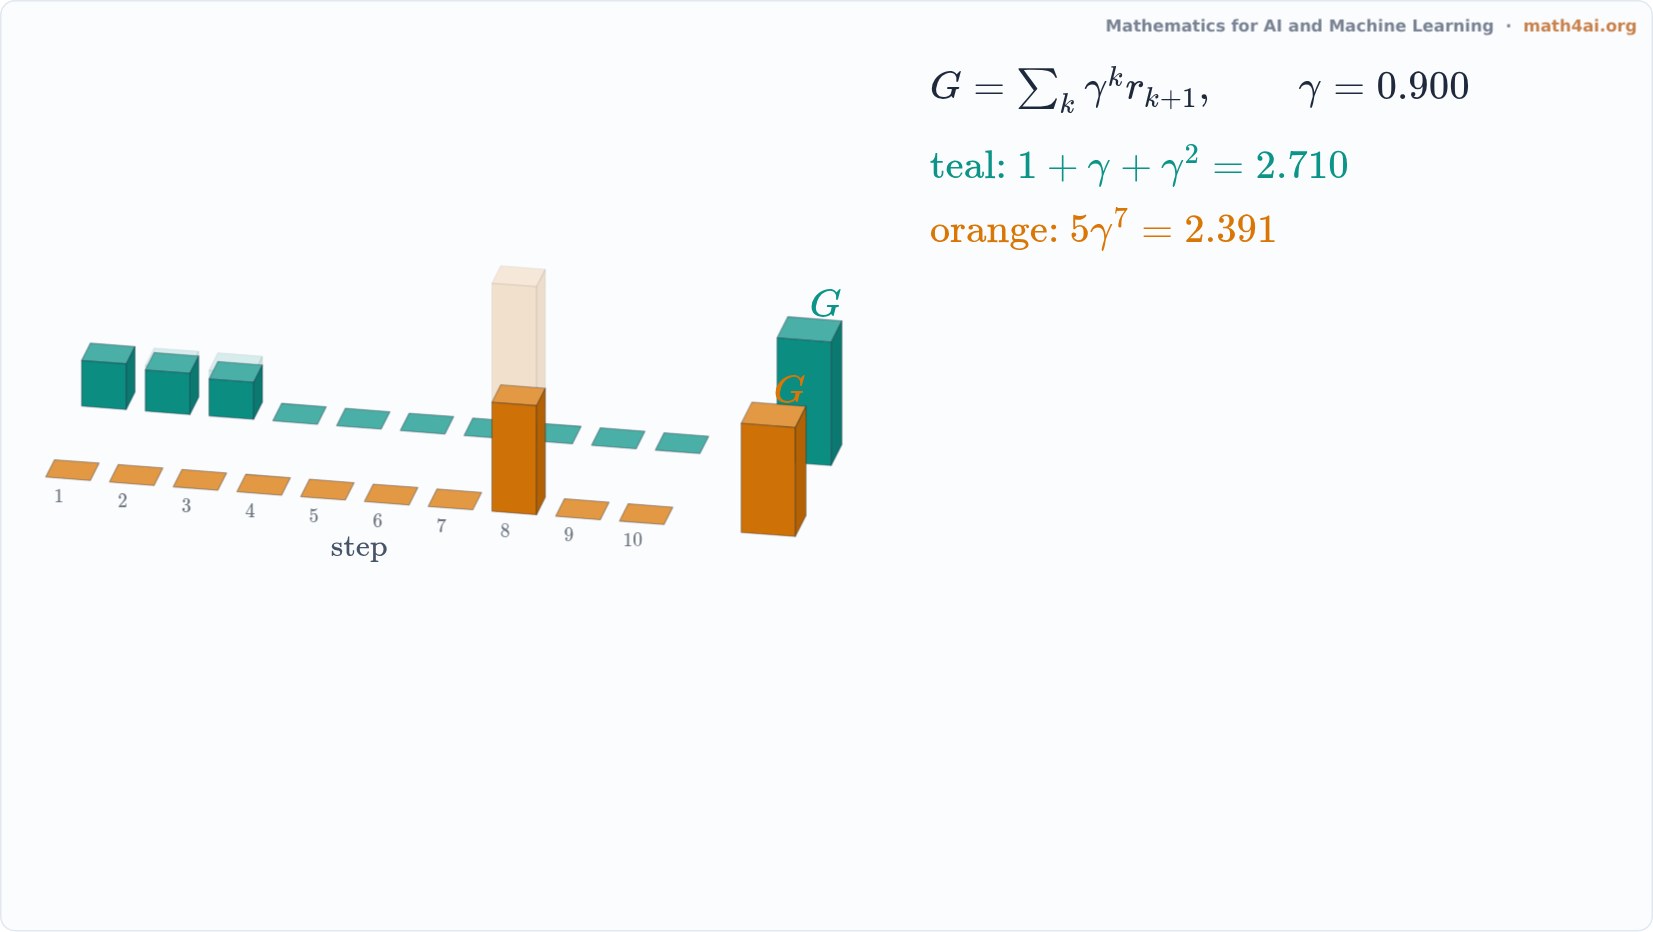 Preview1:32The Discounted Return: Now or LaterChapter 15
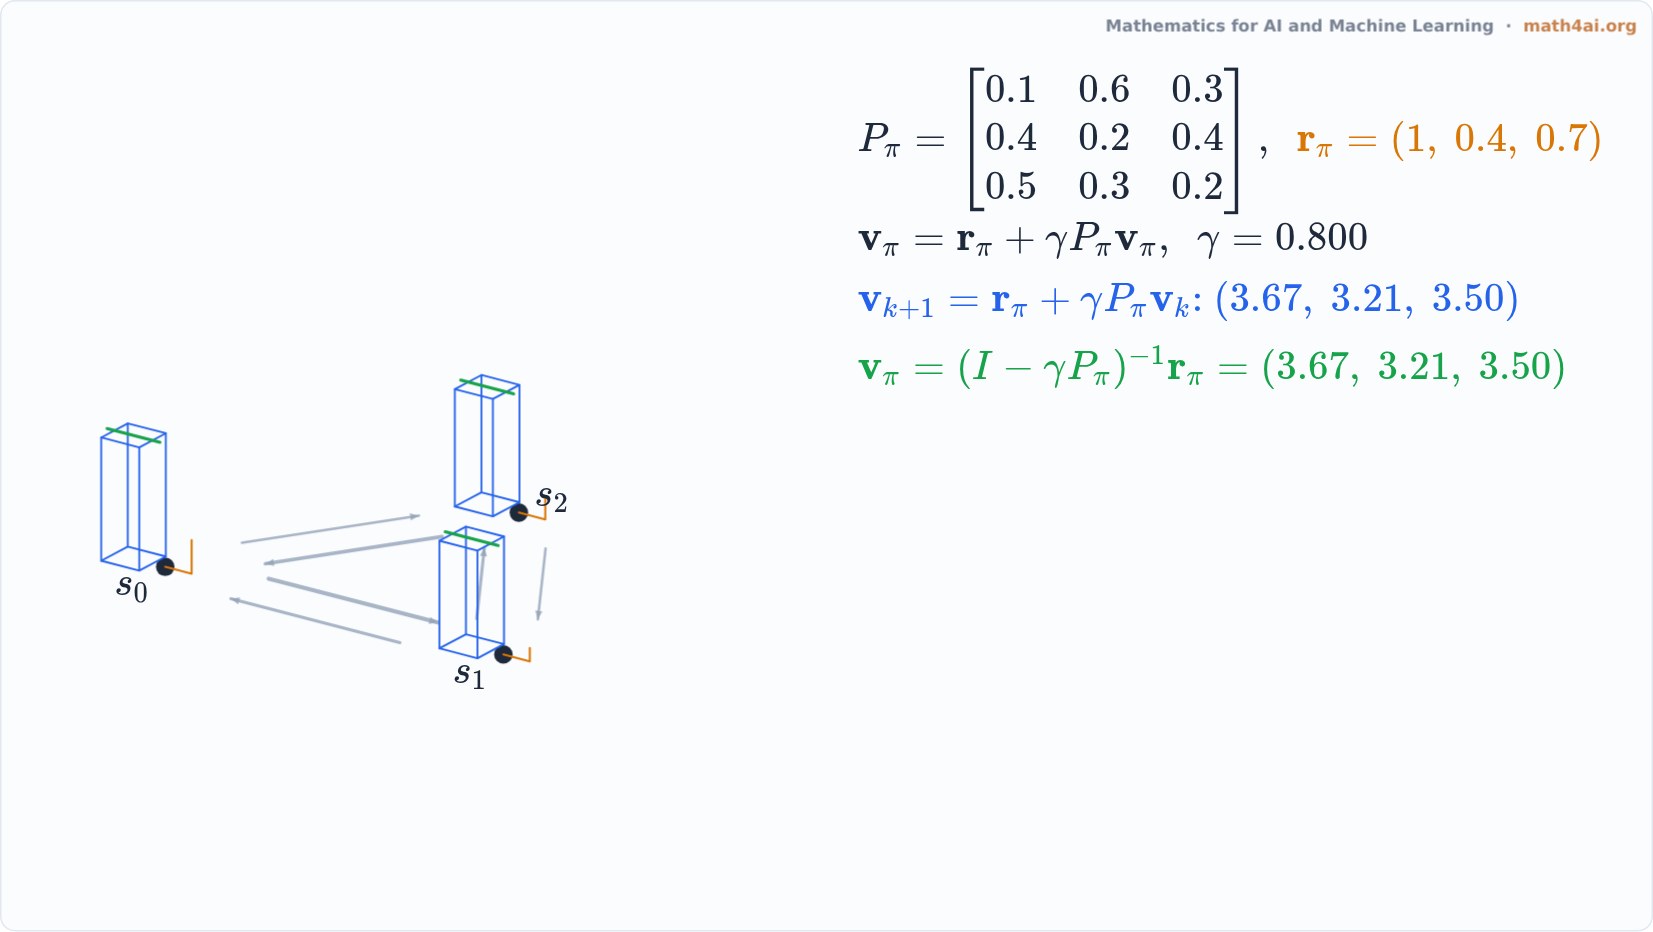 Preview1:39The Bellman Equation as a Linear SystemChapter 15
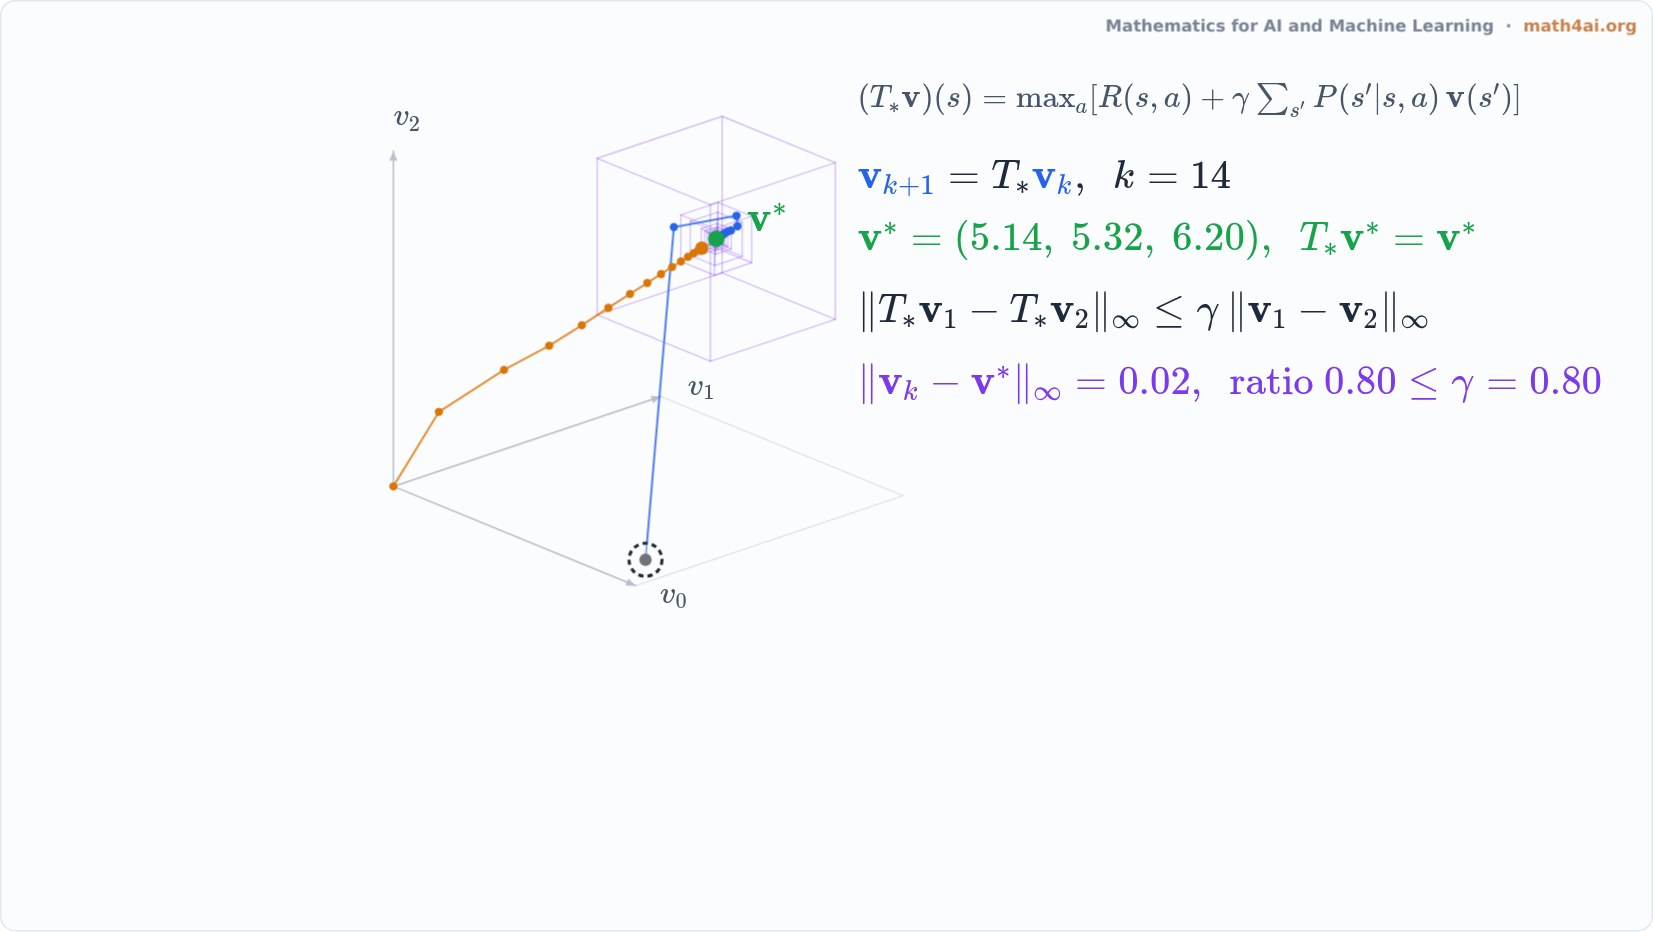 Preview1:49Bellman Operator: A Contraction With One Fixed PointChapter 15
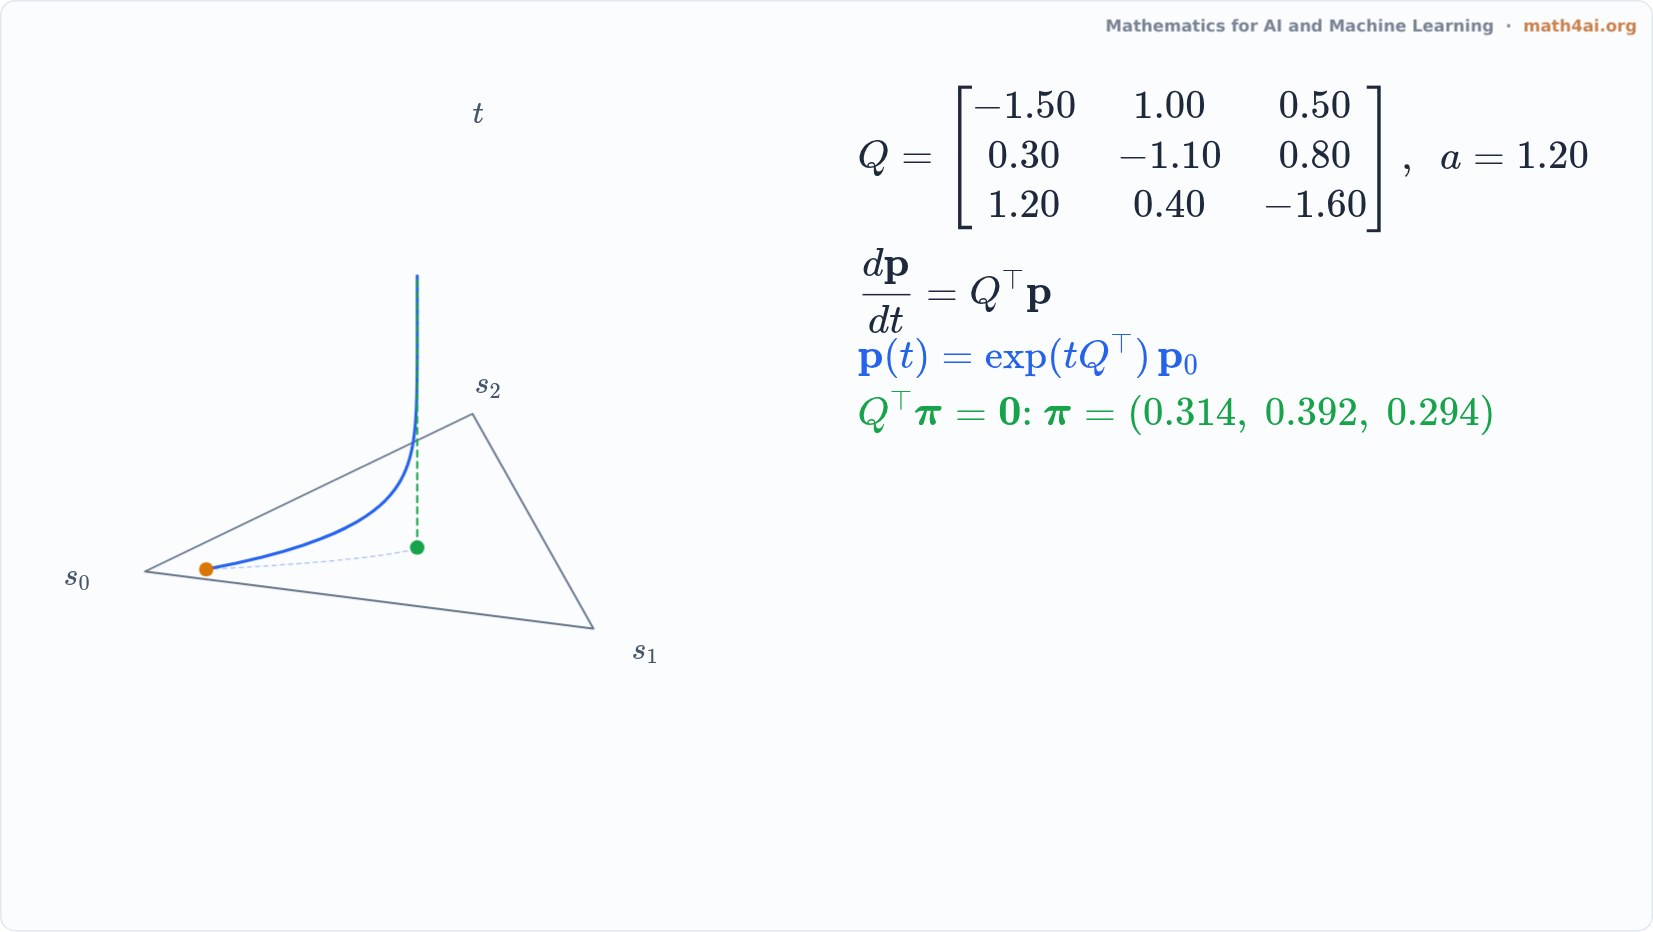 Preview1:34Continuous-Time Markov Chains: Probability Flowing on a TriangleChapter 15
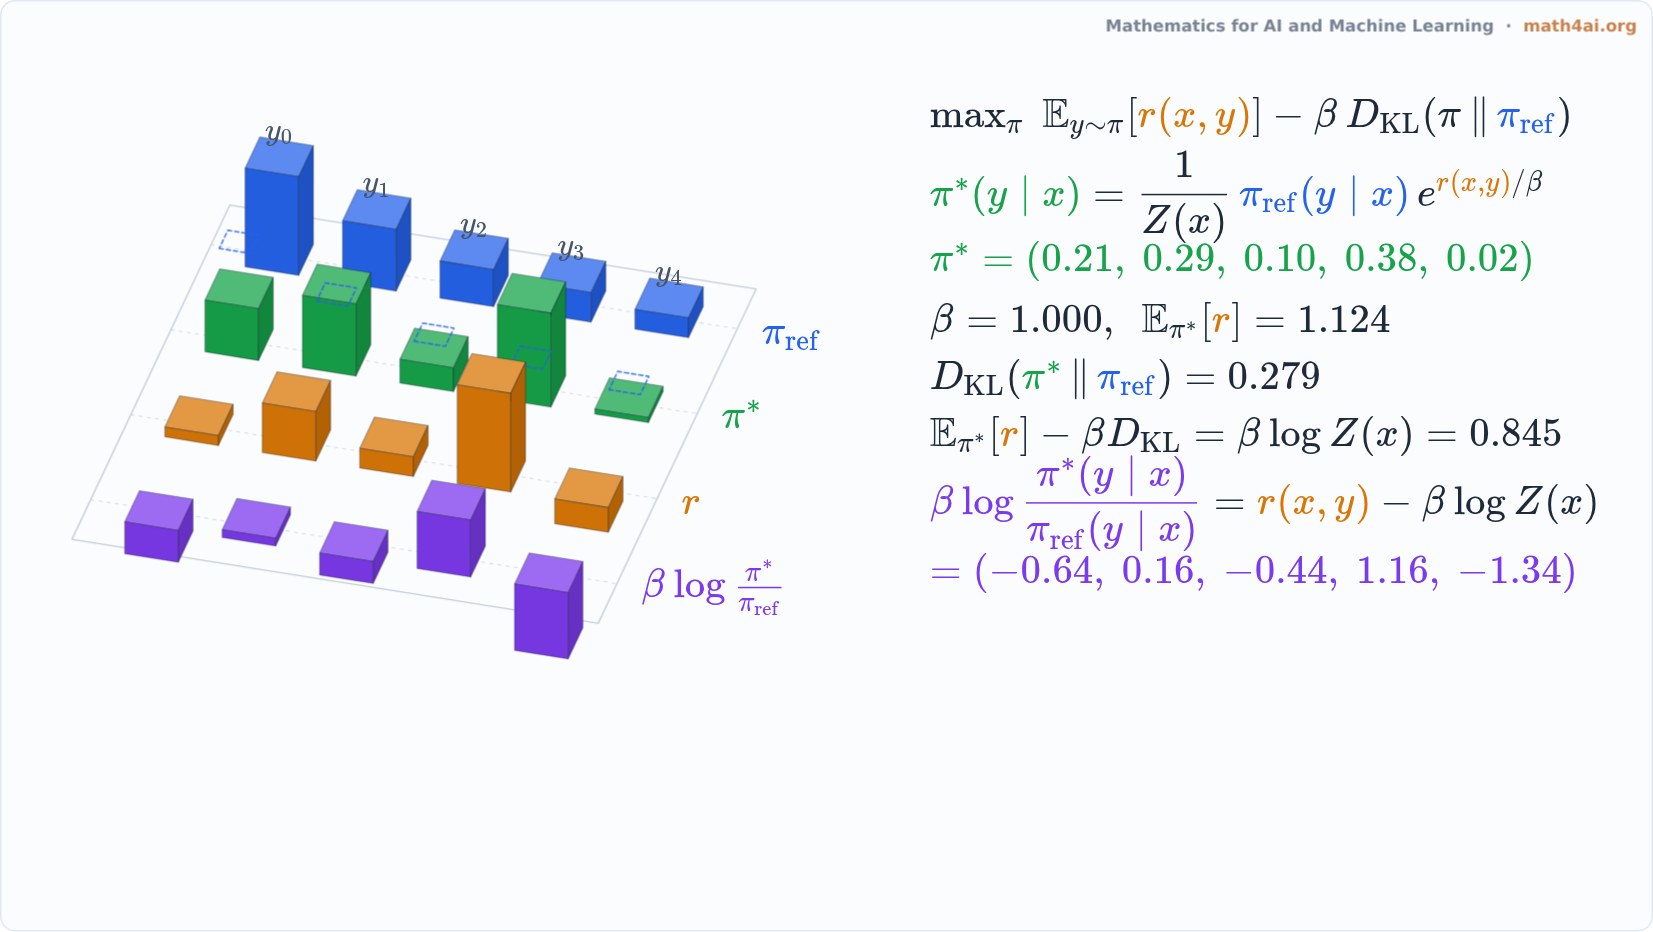 Preview1:58The KL-Regularized Optimal PolicyChapter 15