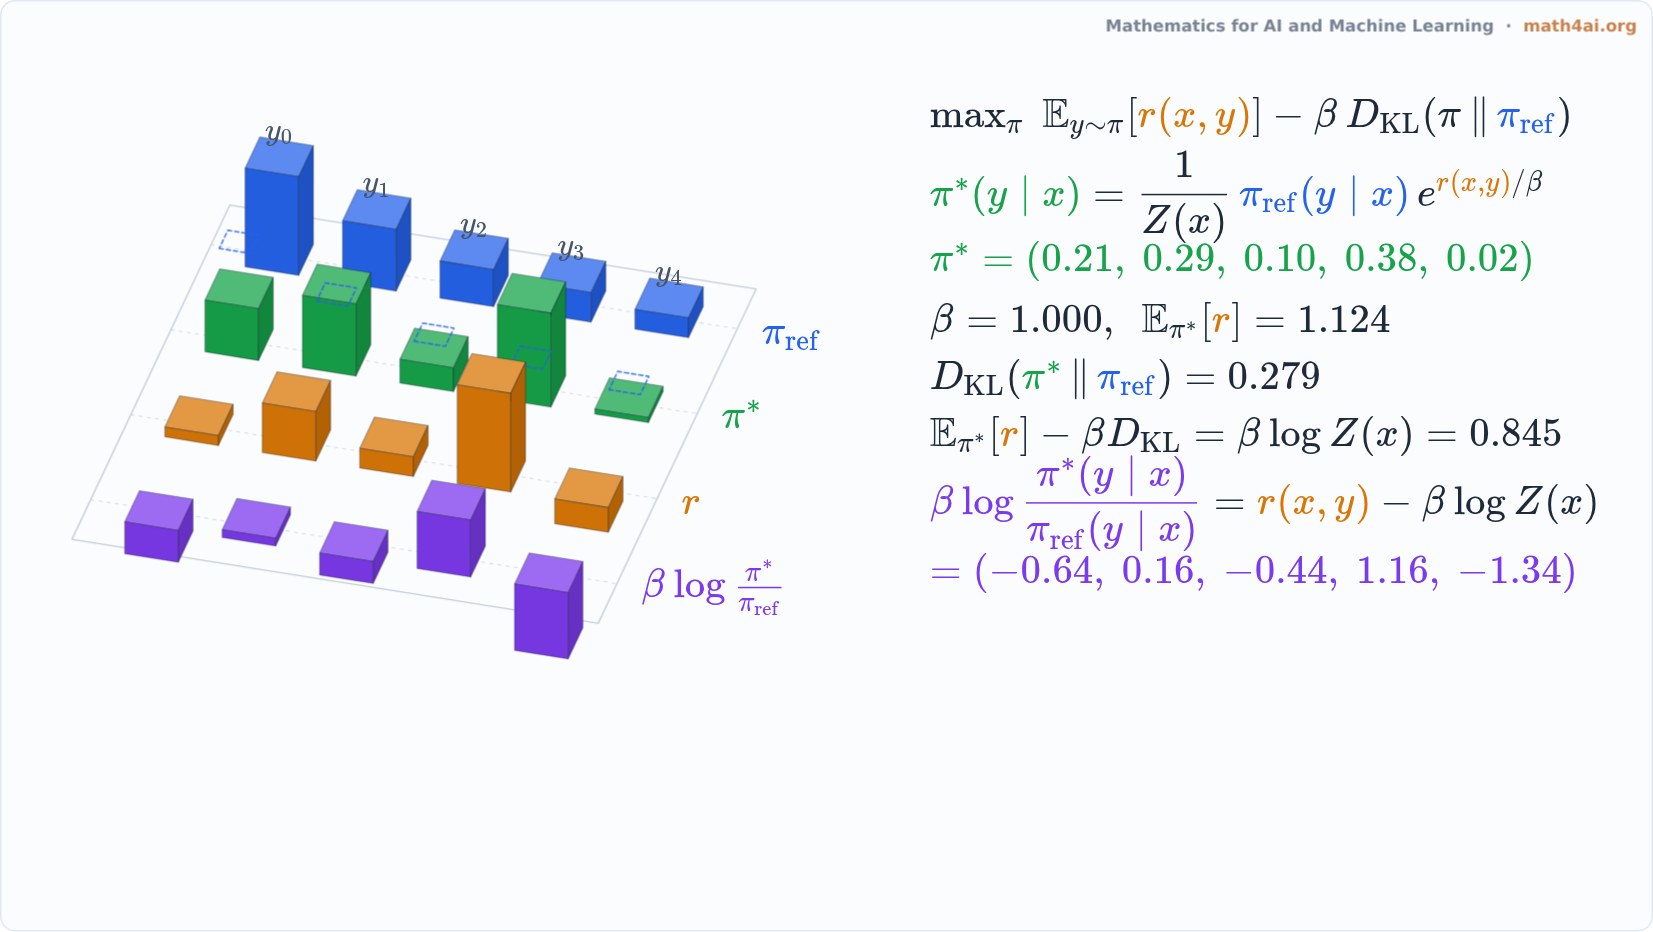
The KL-Regularized Optimal Policy
An interactive live film: the optimal policy of KL-regularized reward maximization is pi_ref times exp(r / beta), normalized; set beta and drag the rewards to see the expected reward, the KL divergence and the DPO implicit reward r - beta log Z update live.
Narration
One prompt x, and five possible responses, y zero to y four. The blue bars at the back are the reference policy, pi ref. The orange bars are the rewards r.
We want a policy that earns a high reward but stays close to pi ref. So we maximize the expected reward, minus beta times the KL divergence from pi ref.
The rest of the narration is in the book's Companion.
More from Chapter 15
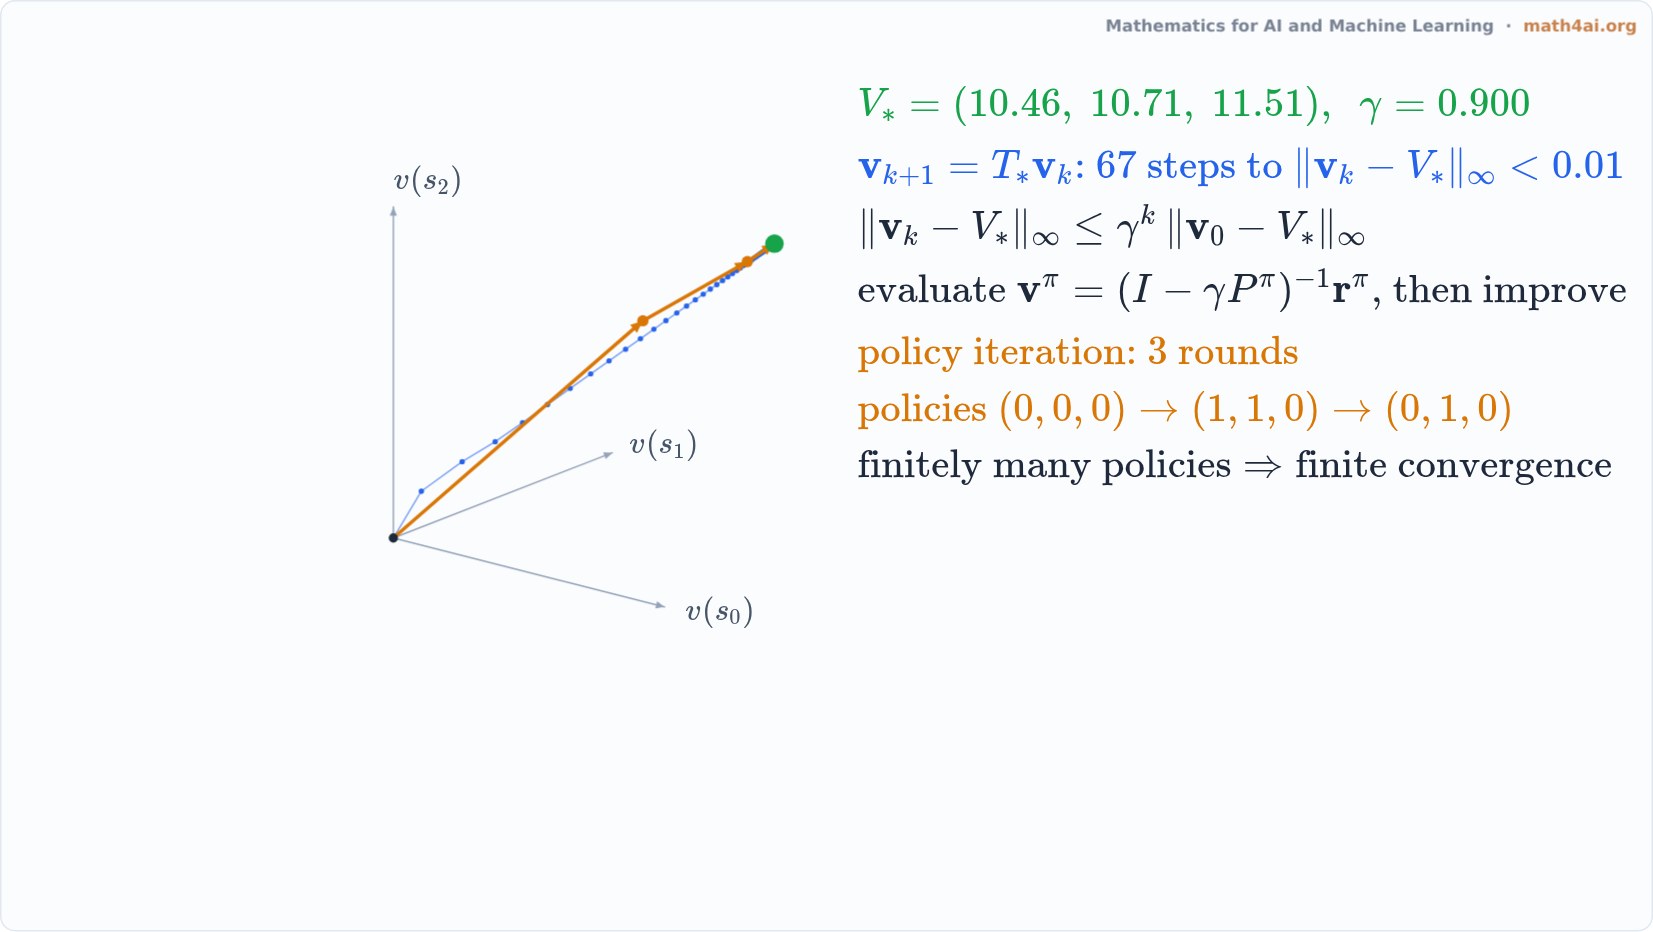 Interactive1:41Value Iteration and Policy Iteration: Many Small Steps or a Few Big JumpsChapter 15
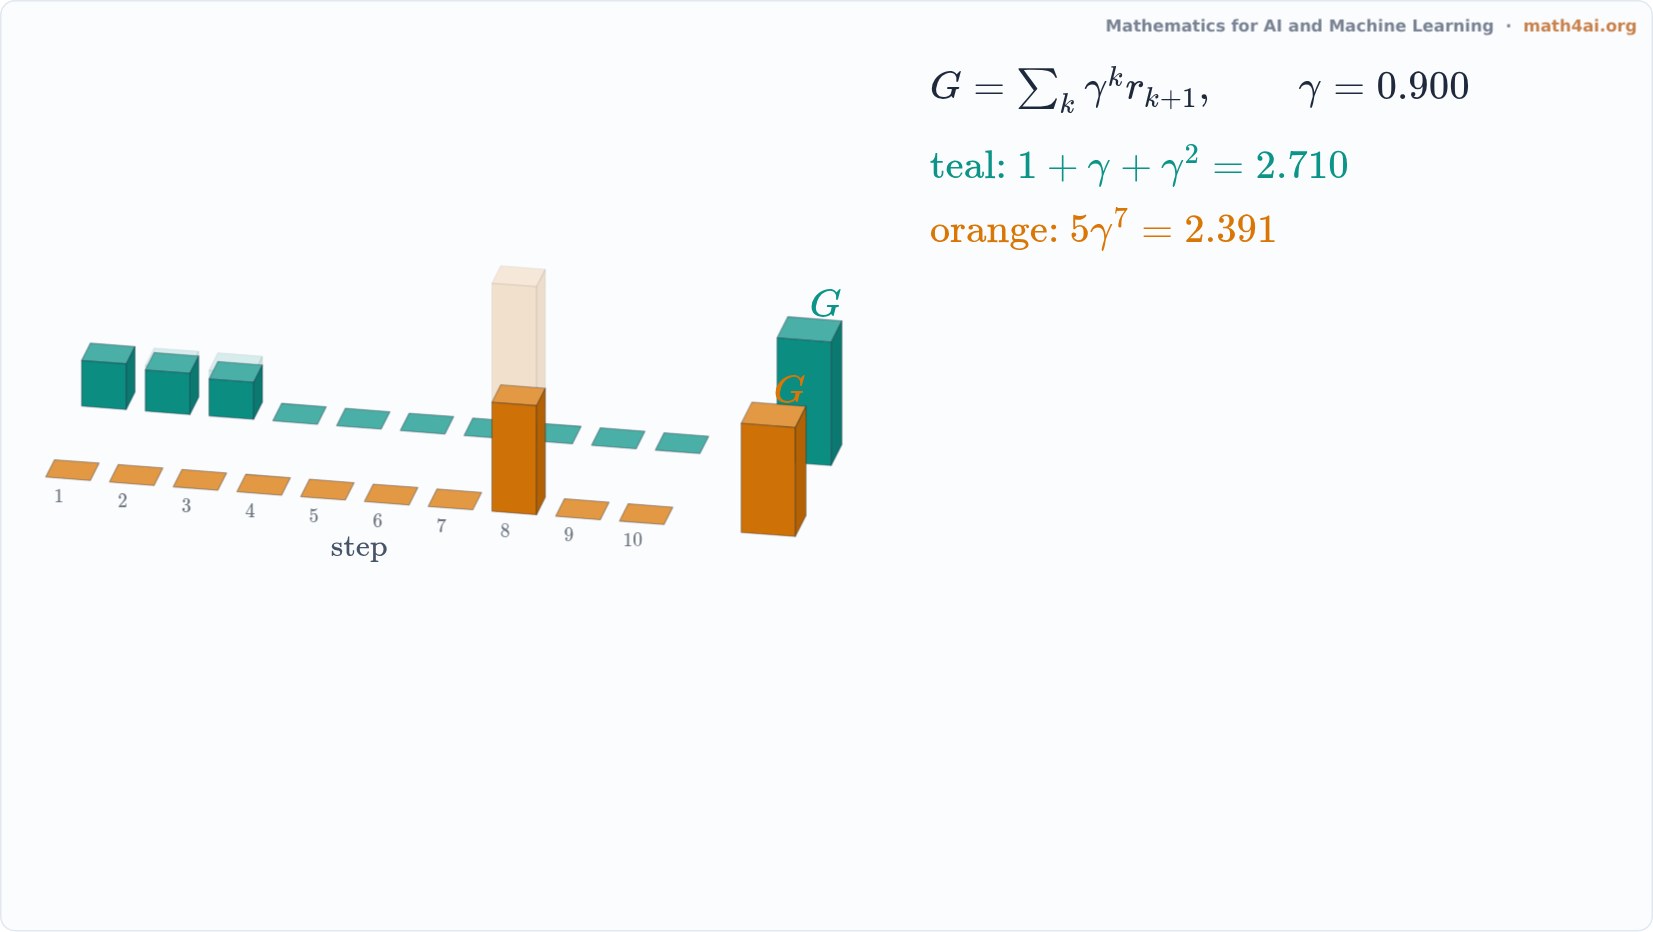 Preview1:32The Discounted Return: Now or LaterChapter 15
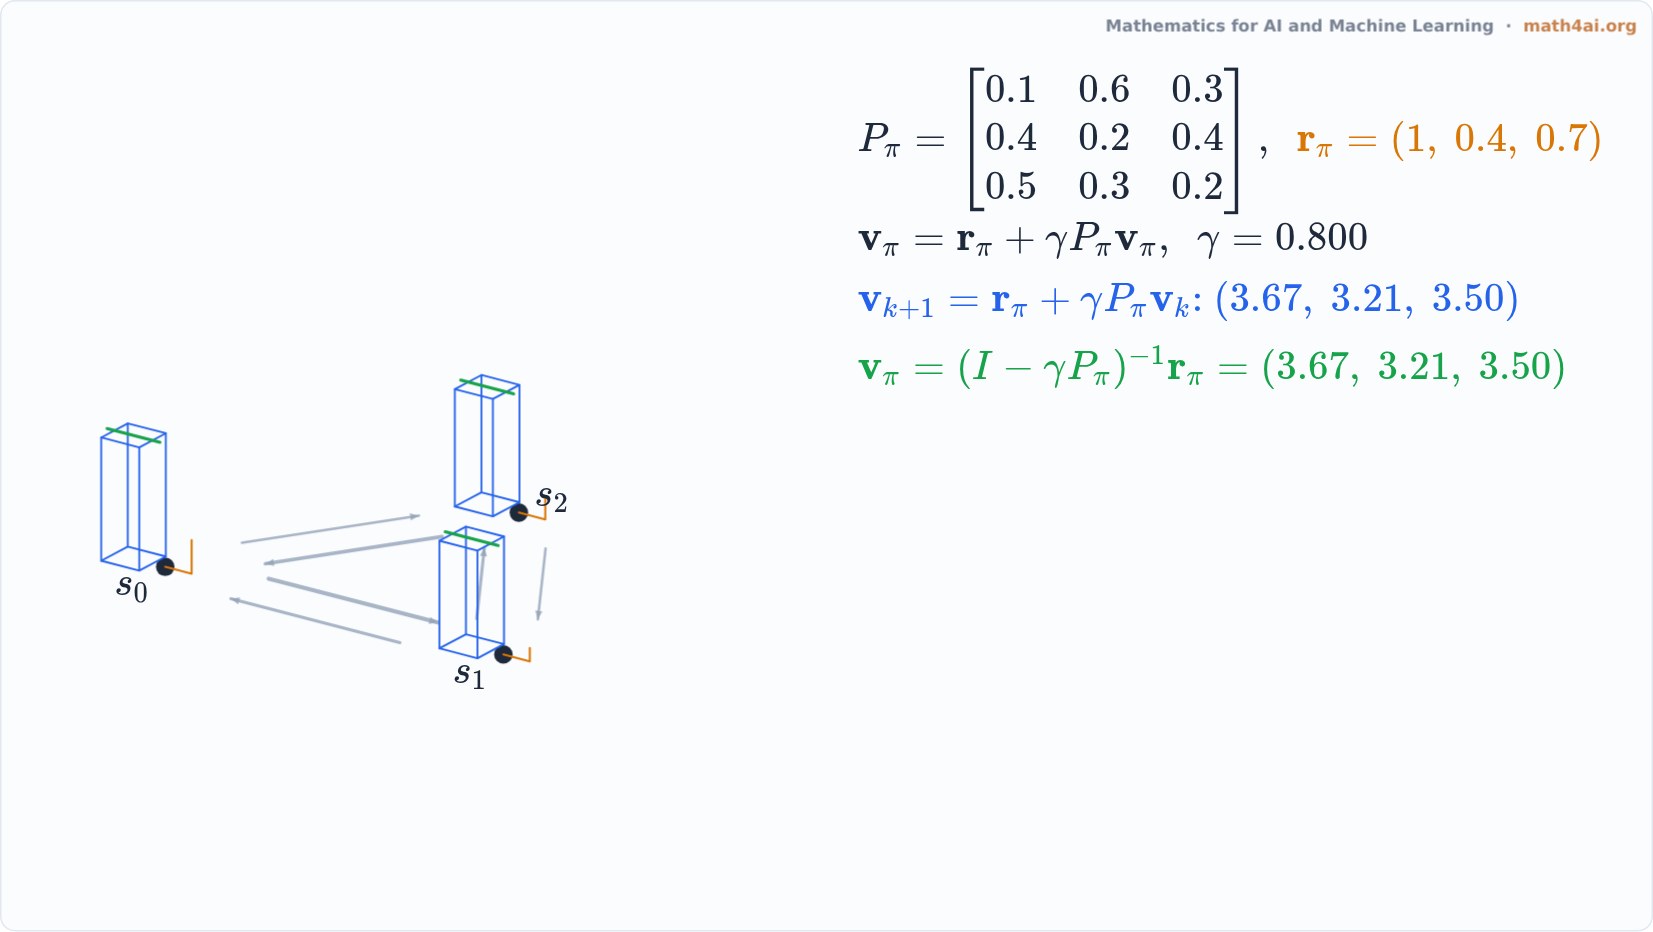 Preview1:39The Bellman Equation as a Linear SystemChapter 15
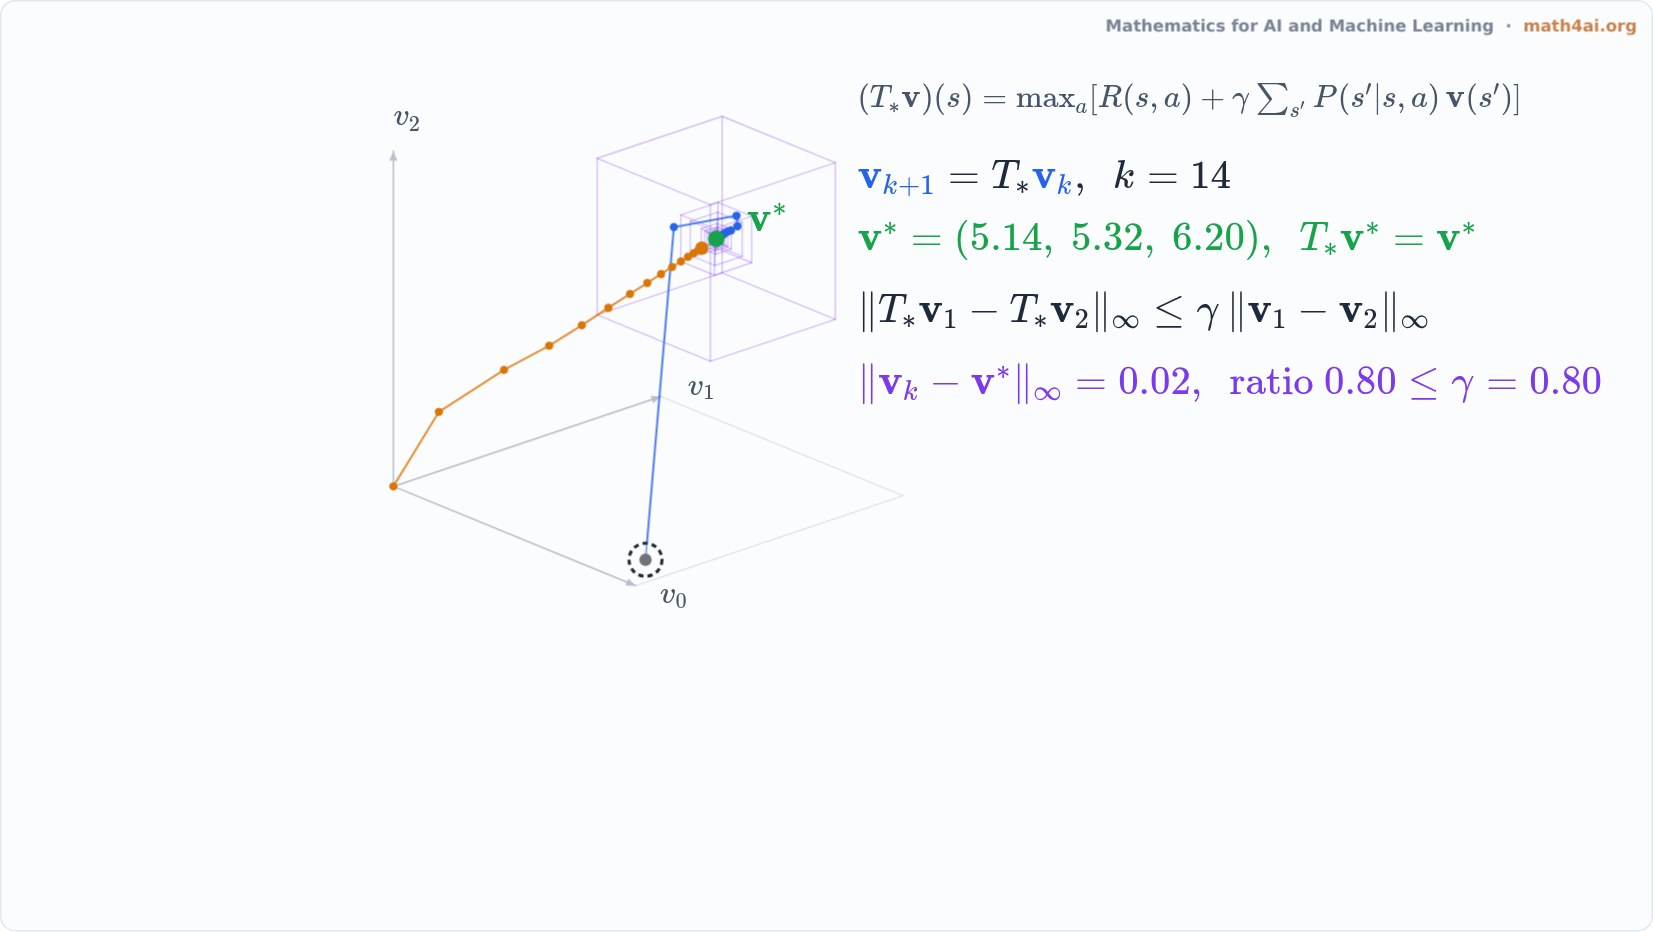 Preview1:49Bellman Operator: A Contraction With One Fixed PointChapter 15
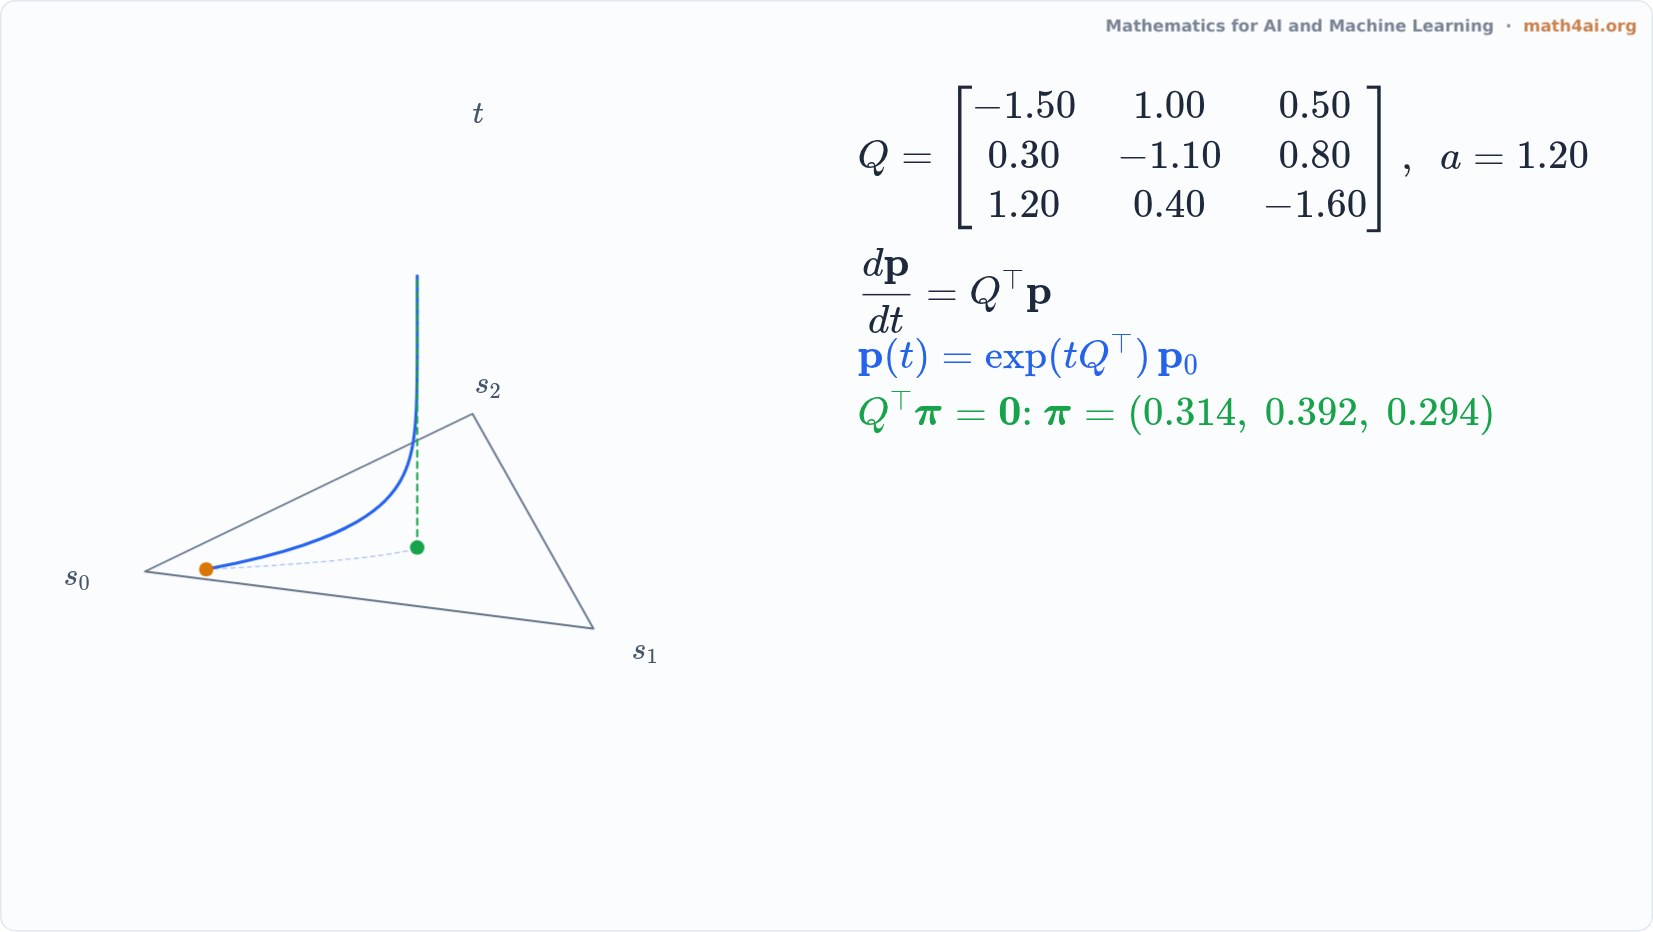 Preview1:34Continuous-Time Markov Chains: Probability Flowing on a TriangleChapter 15
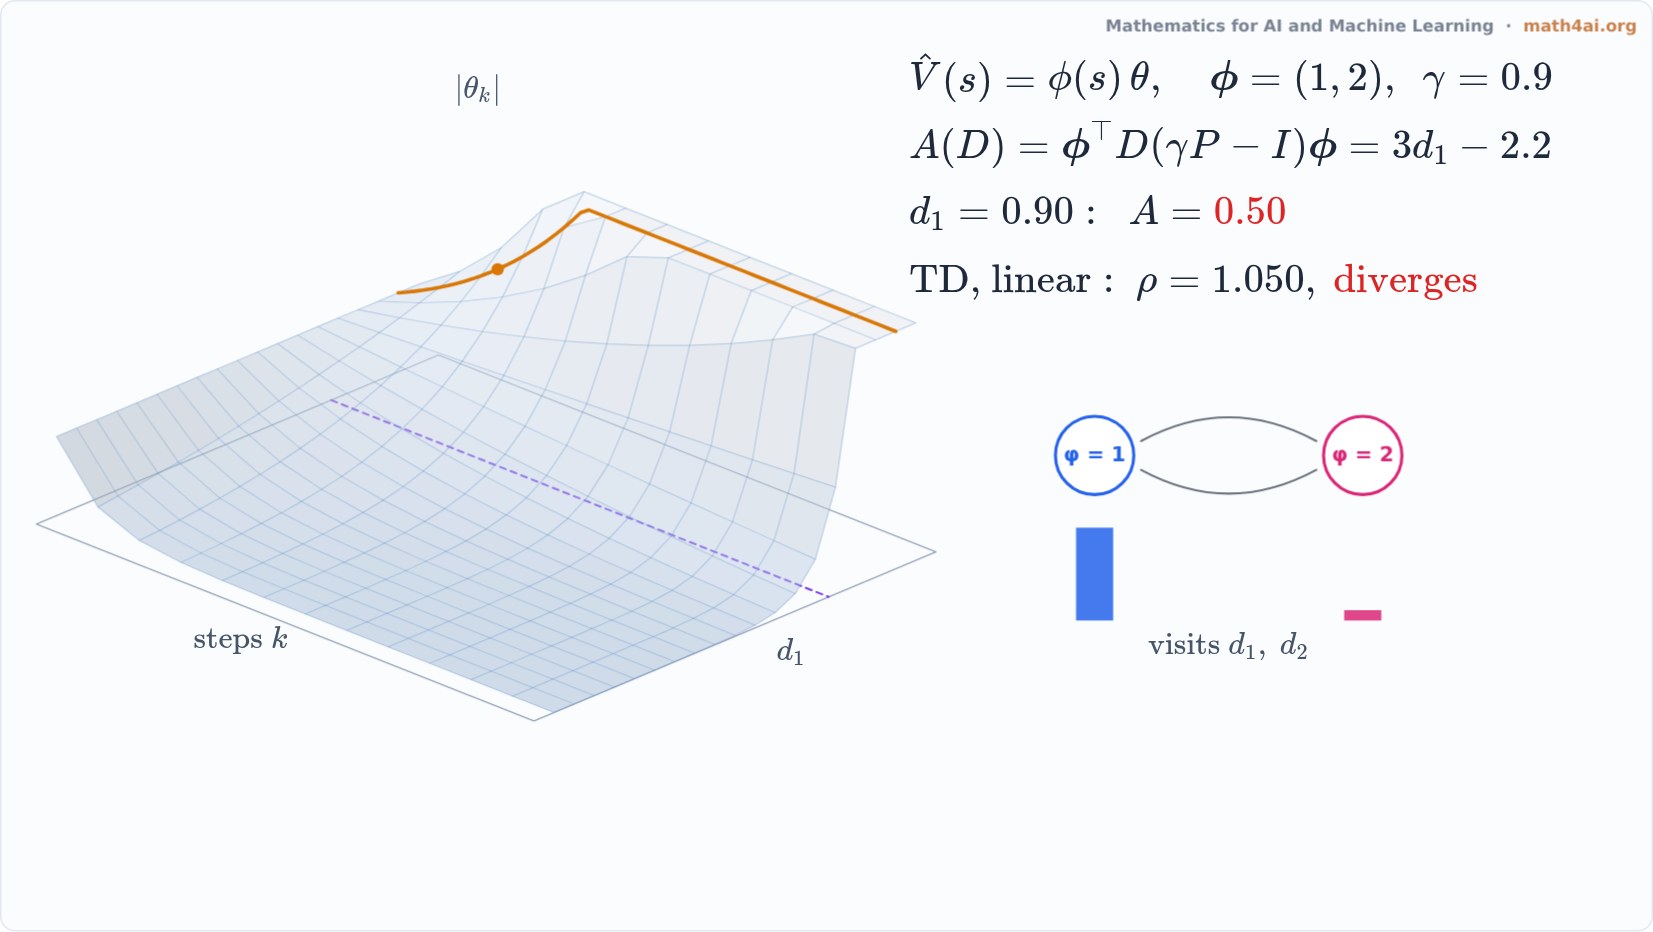 Preview1:51The Deadly Triad: When TD Learning ExplodesChapter 15