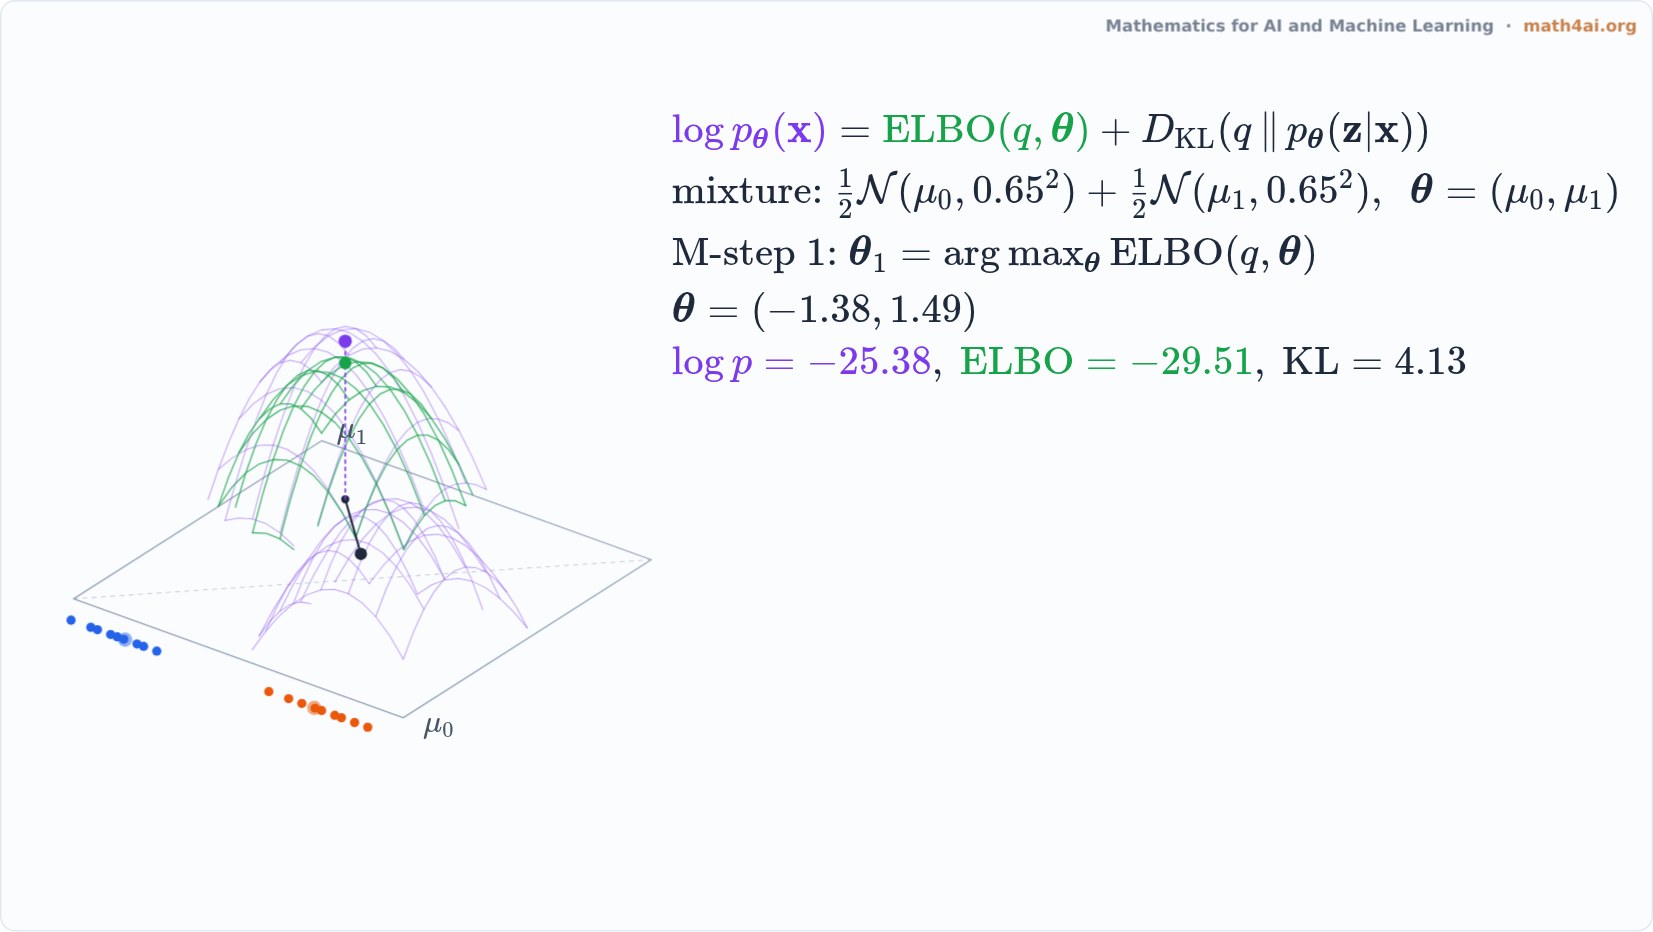
Expectation Maximization: Coordinate Ascent on the Lower Bound
An interactive live film: the expectation step eliminates the KL gap so the ELBO touches the true log-likelihood tangentially, while the maximization step lifts both to higher ground.
Narration
The expectation-maximization algorithm is a classical foundation for learning latent variable models, famously used to fit Gaussian mixture models to clustered data.
This algorithm can be viewed as coordinate ascent on the evidence lower bound, a green surface that never rises above the purple surface of the marginal log-likelihood.
The rest of the narration is in the book's Companion.
More from Chapter 16
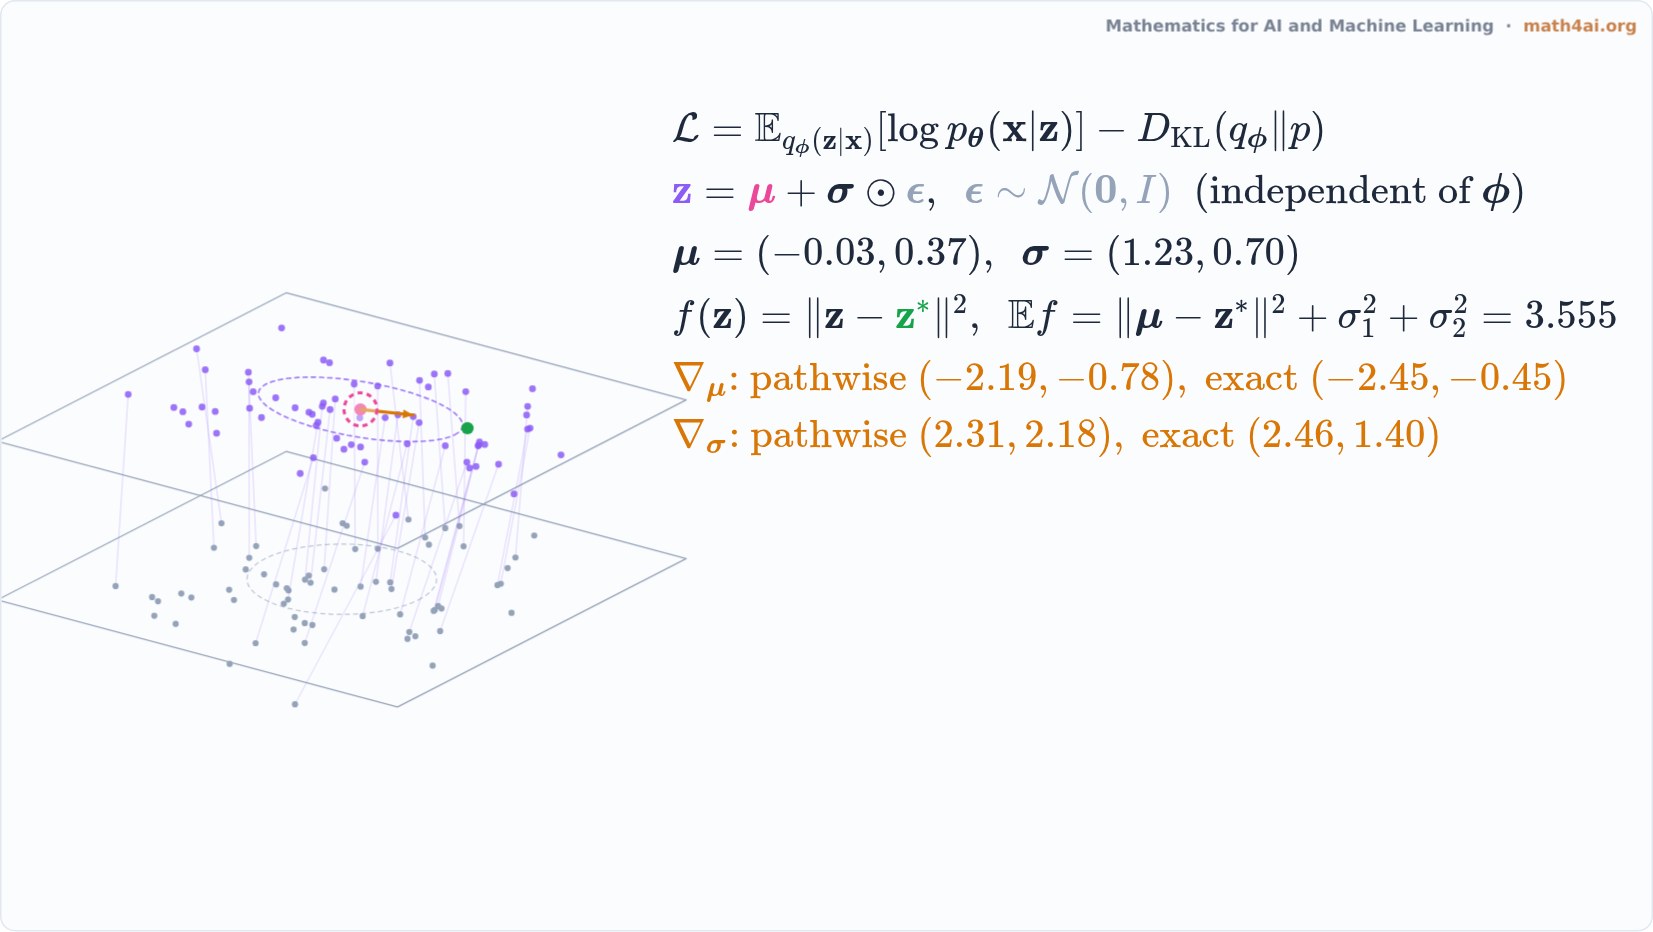 Interactive1:46The Reparameterization Trick: Differentiable SamplingChapter 16
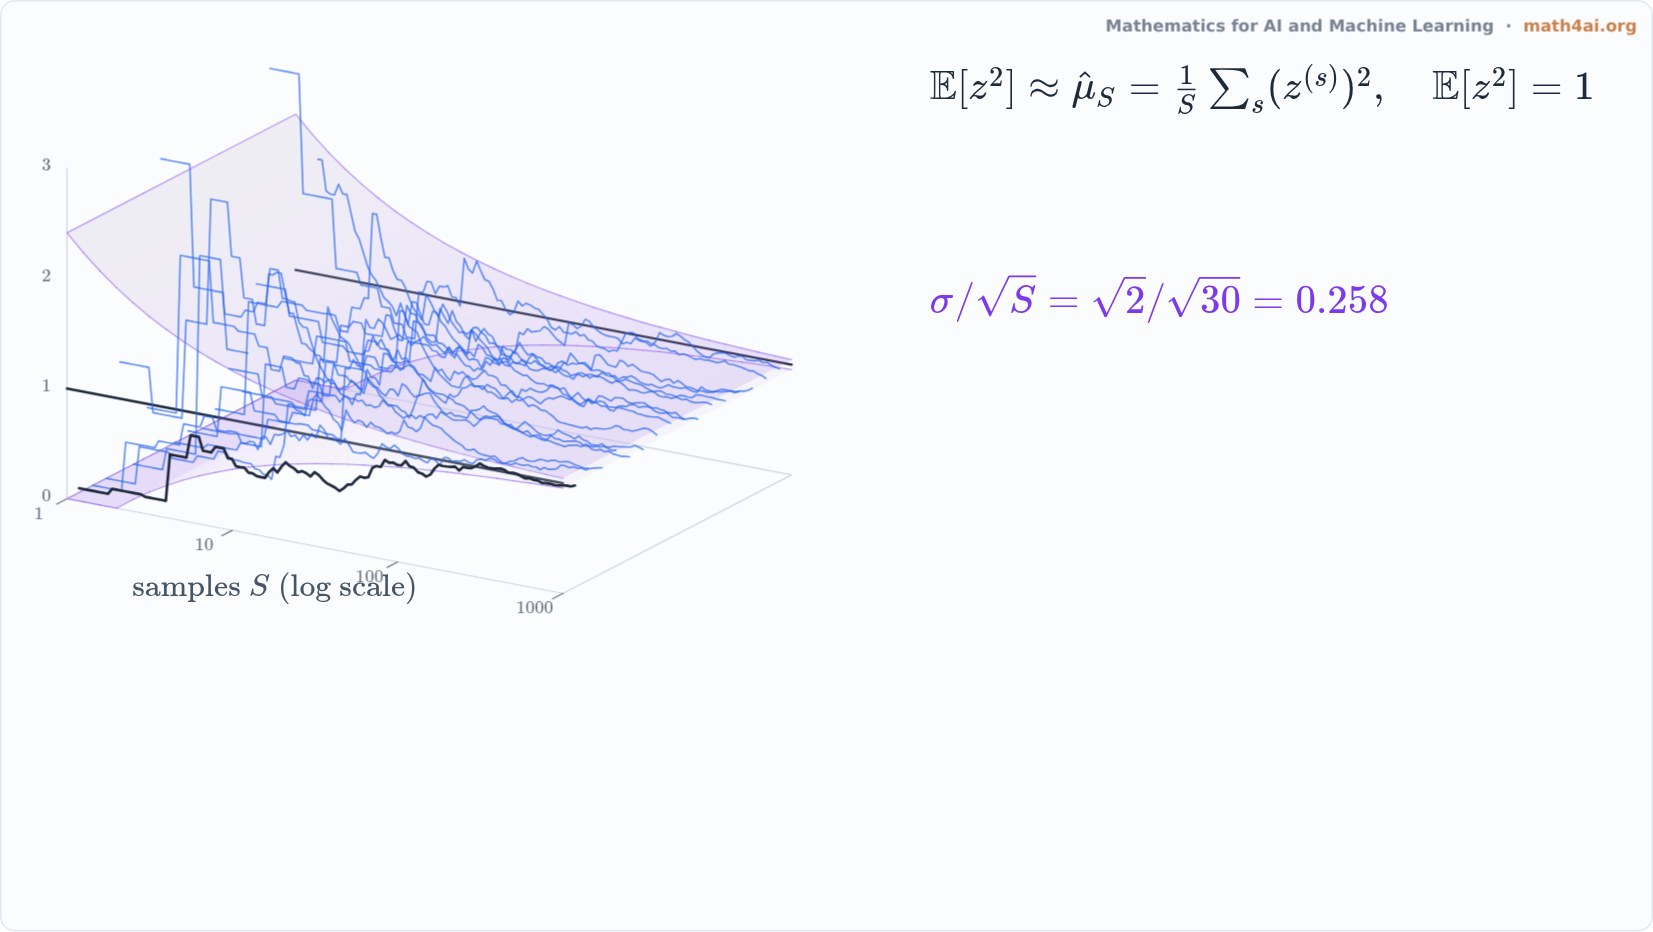 Preview1:27Monte Carlo: Averages That Close In Like a FunnelChapter 16
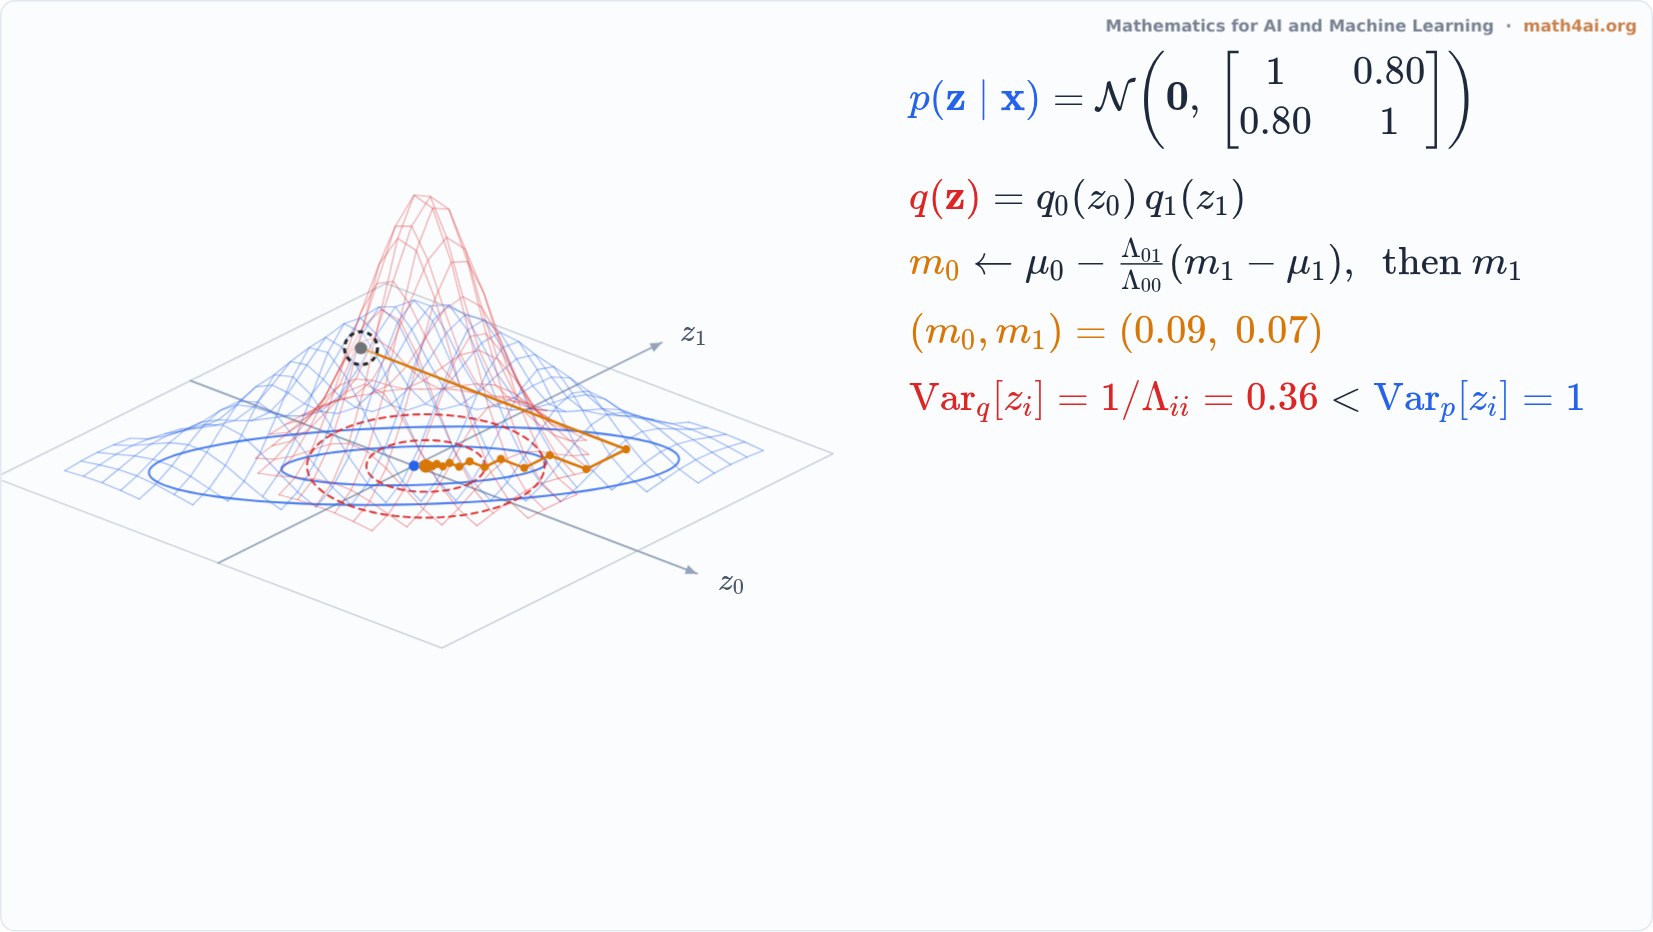 Preview1:42Mean Field: Independent Factors for a Correlated PosteriorChapter 16
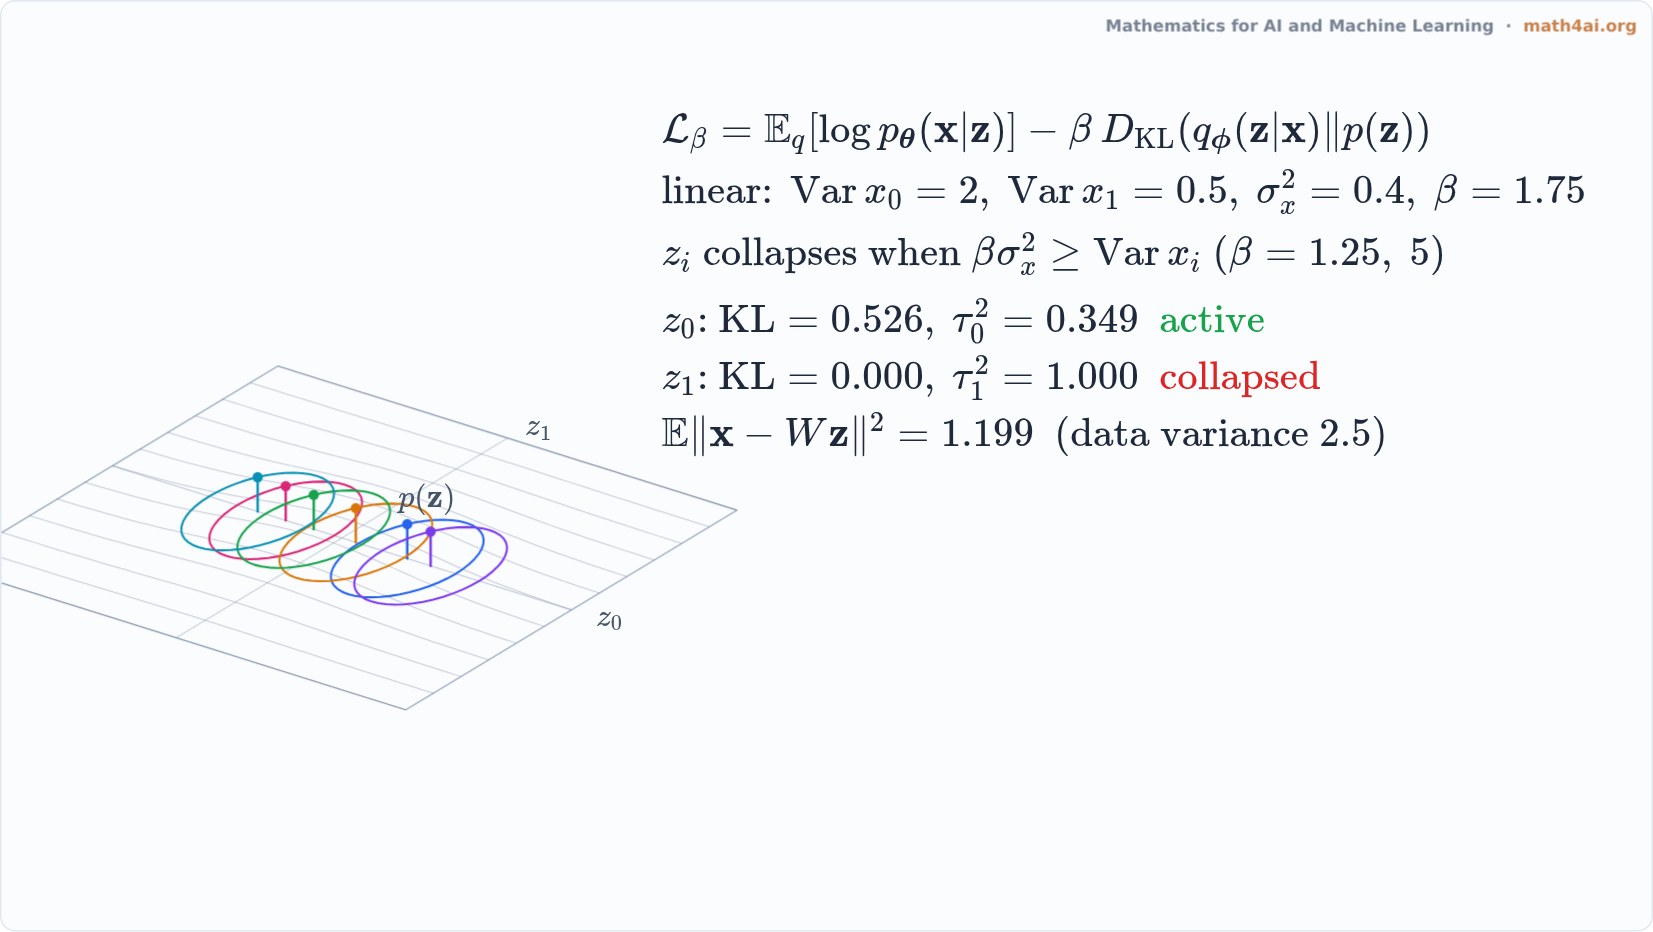 Preview1:45Posterior Collapse: When Latents Vanish into the PriorChapter 16
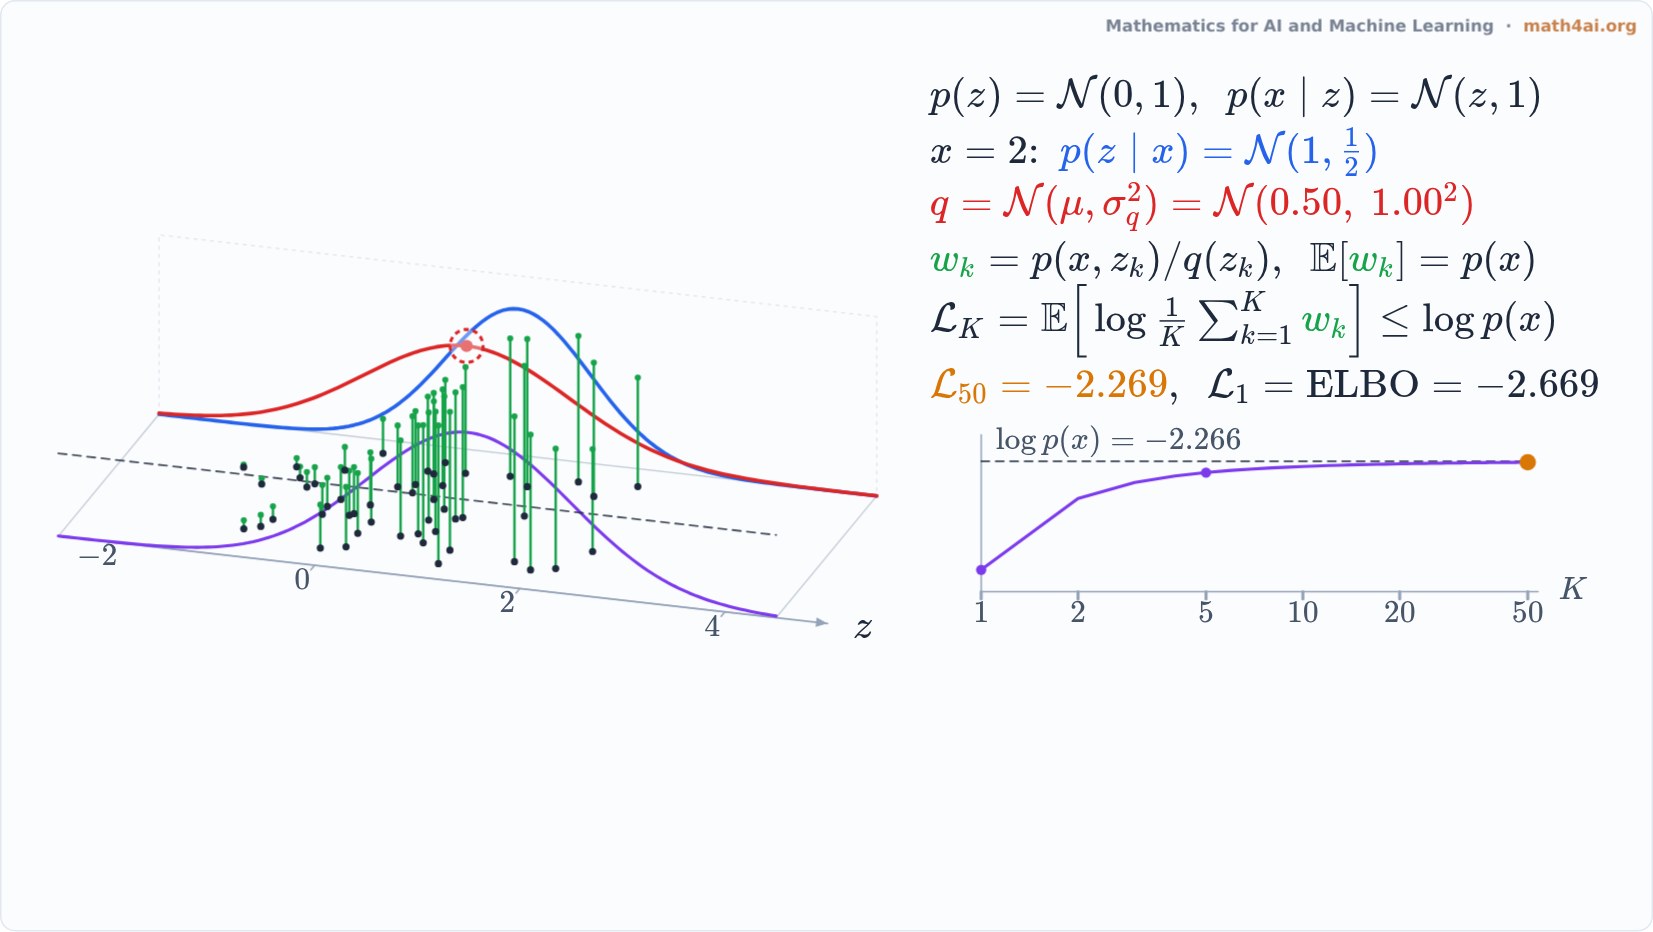 Preview1:55Importance-Weighted BoundsChapter 16