Adam and AdamW: A Step Size for Every Coordinate
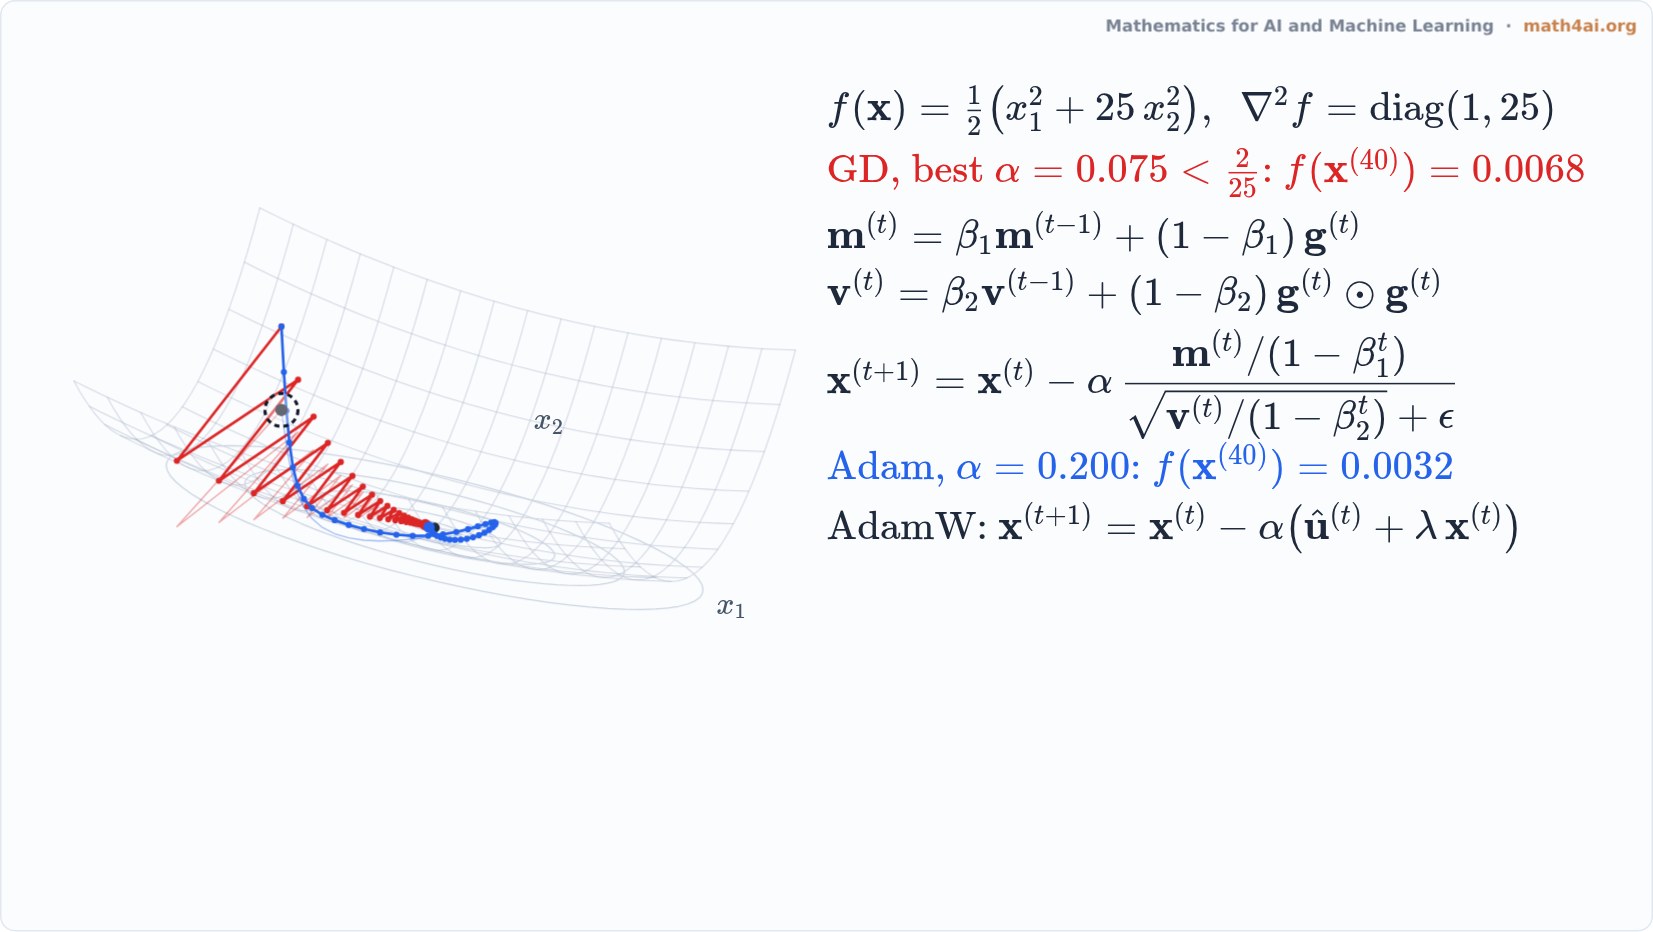
An interactive live film: on a narrow bowl, gradient descent is capped by the steep direction while Adam divides each coordinate by its own gradient scale. Set alpha and beta_1 and beat the best gradient descent in forty steps.
Narration
Here is a long, narrow bowl: the loss is one half of the sum of x one squared and twenty five times x two squared. Across the valley it curves twenty five times more than along it.
Gradient descent uses one step size for every coordinate, and the steep direction caps it: above two over twenty five, the steps across the valley grow and the iterates diverge. So the red path, at the best safe step, crosses the valley back and forth and creeps along the floor.
The rest of the narration is in the book's Companion.
More from Chapter 12
 Interactive1:08Gradient Descent in an Ill-Conditioned ValleyChapter 12
 Preview1:28The Descent Lemma: A Bowl That Bounds Every StepChapter 12
 Preview1:33Heavy-Ball Momentum: Zig-Zags Cancel, the Valley Floor Adds UpChapter 12
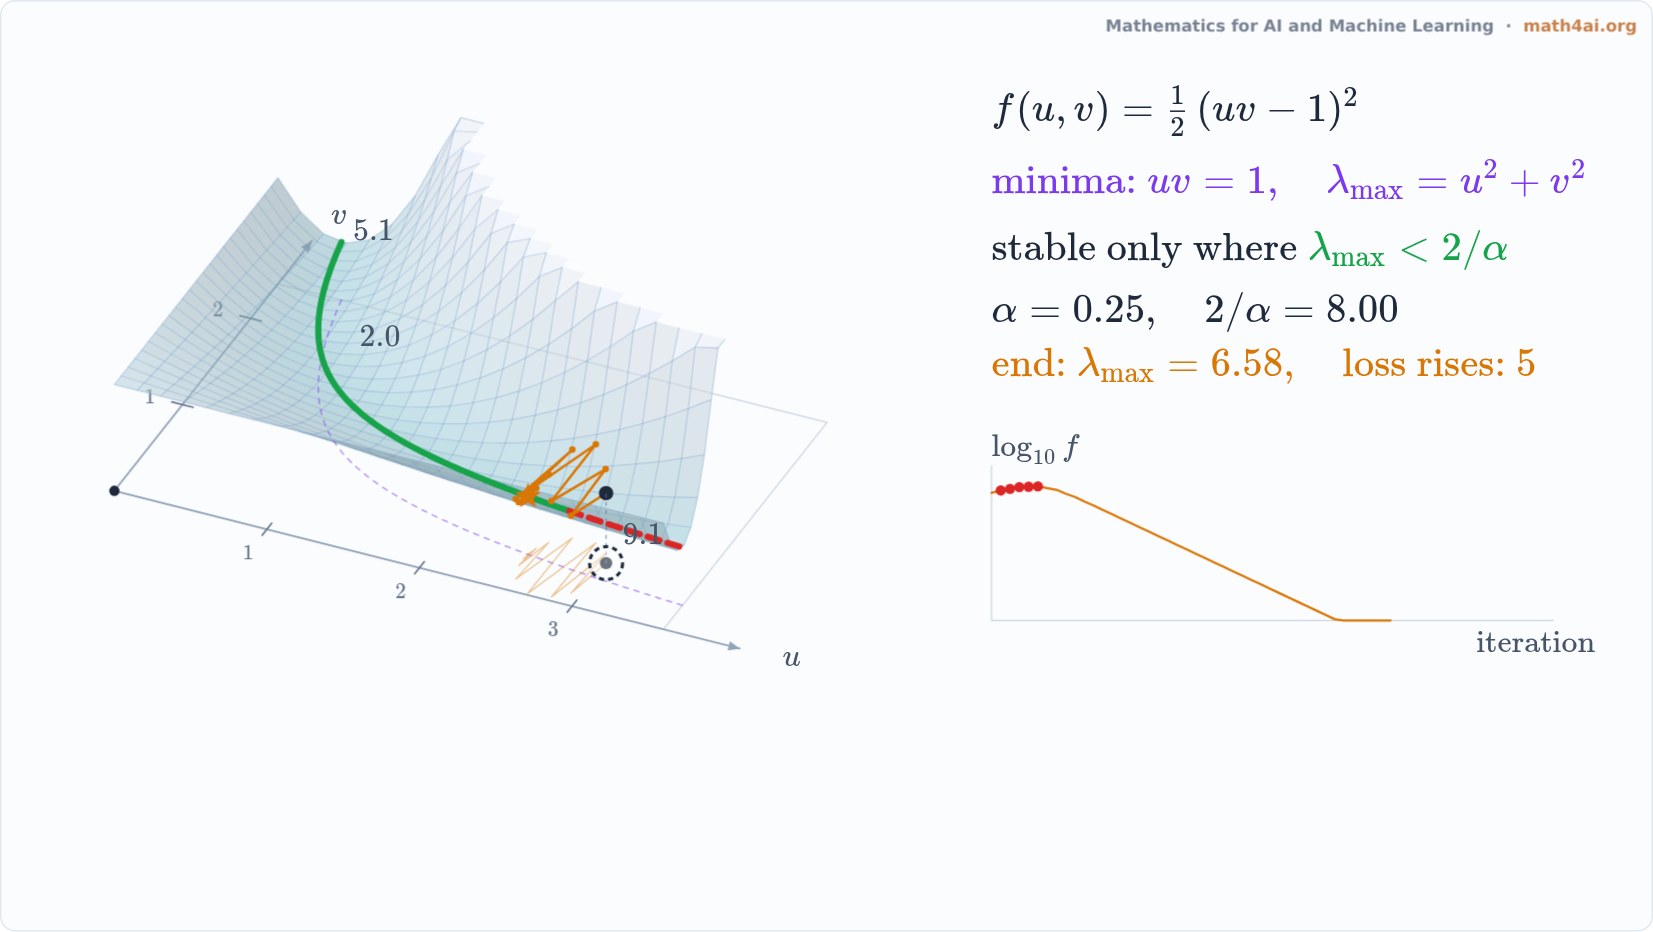 Preview1:43A Large Step Selects a Flatter MinimumChapter 12
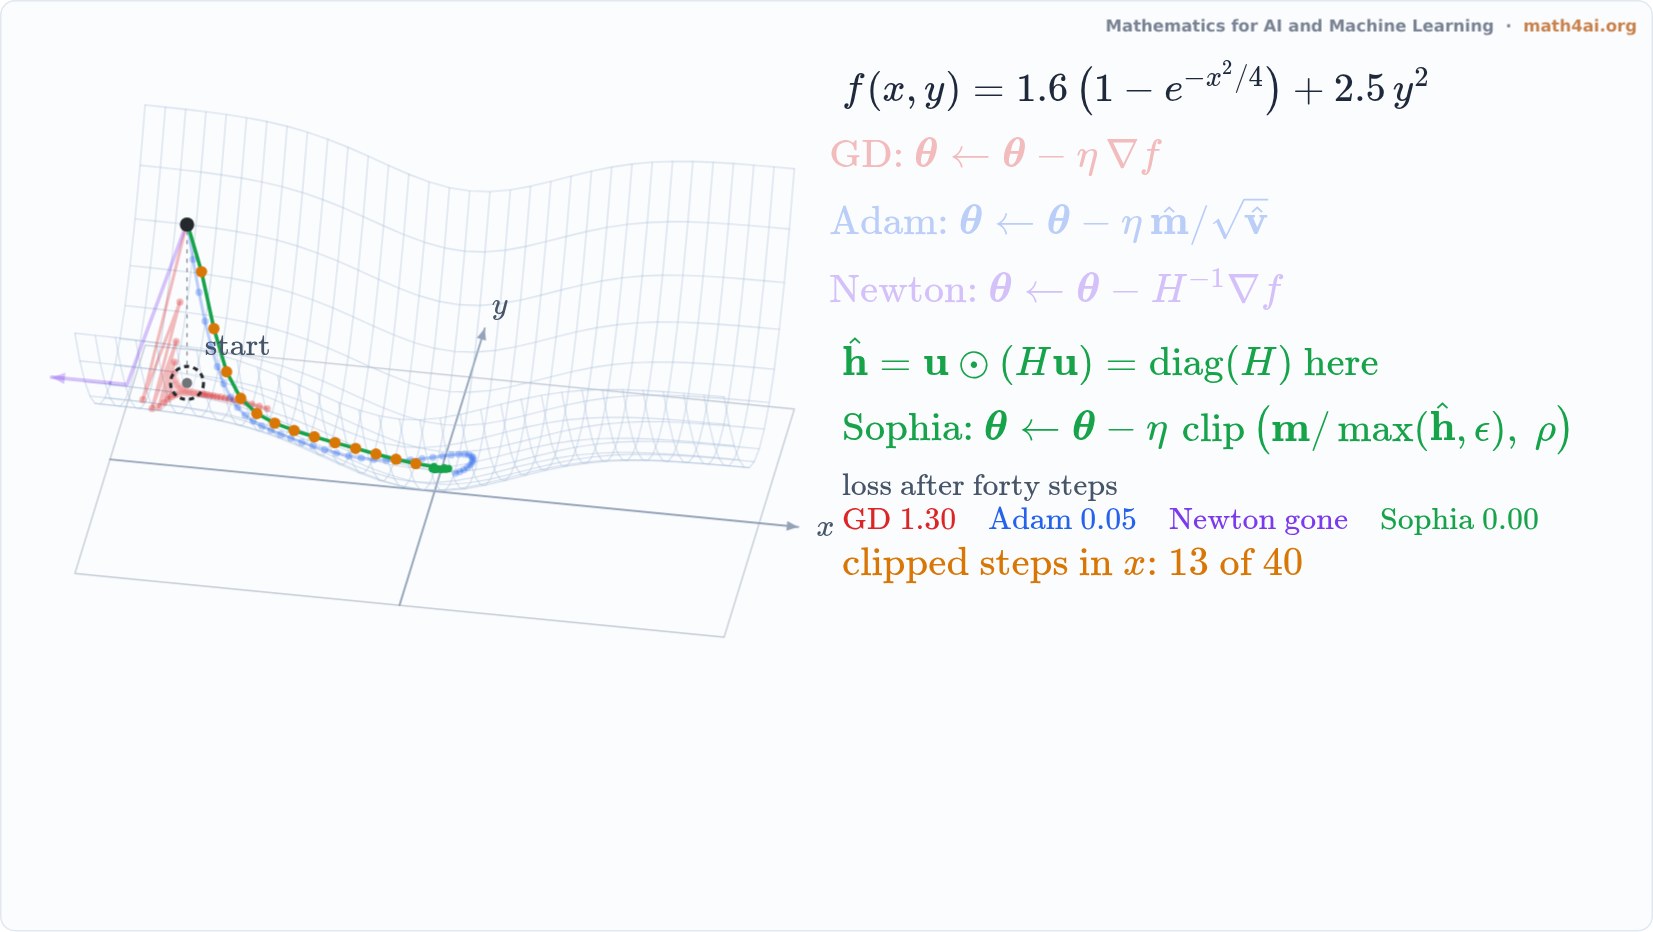 Preview2:12Sophia: Newton Steps with a ClipChapter 12
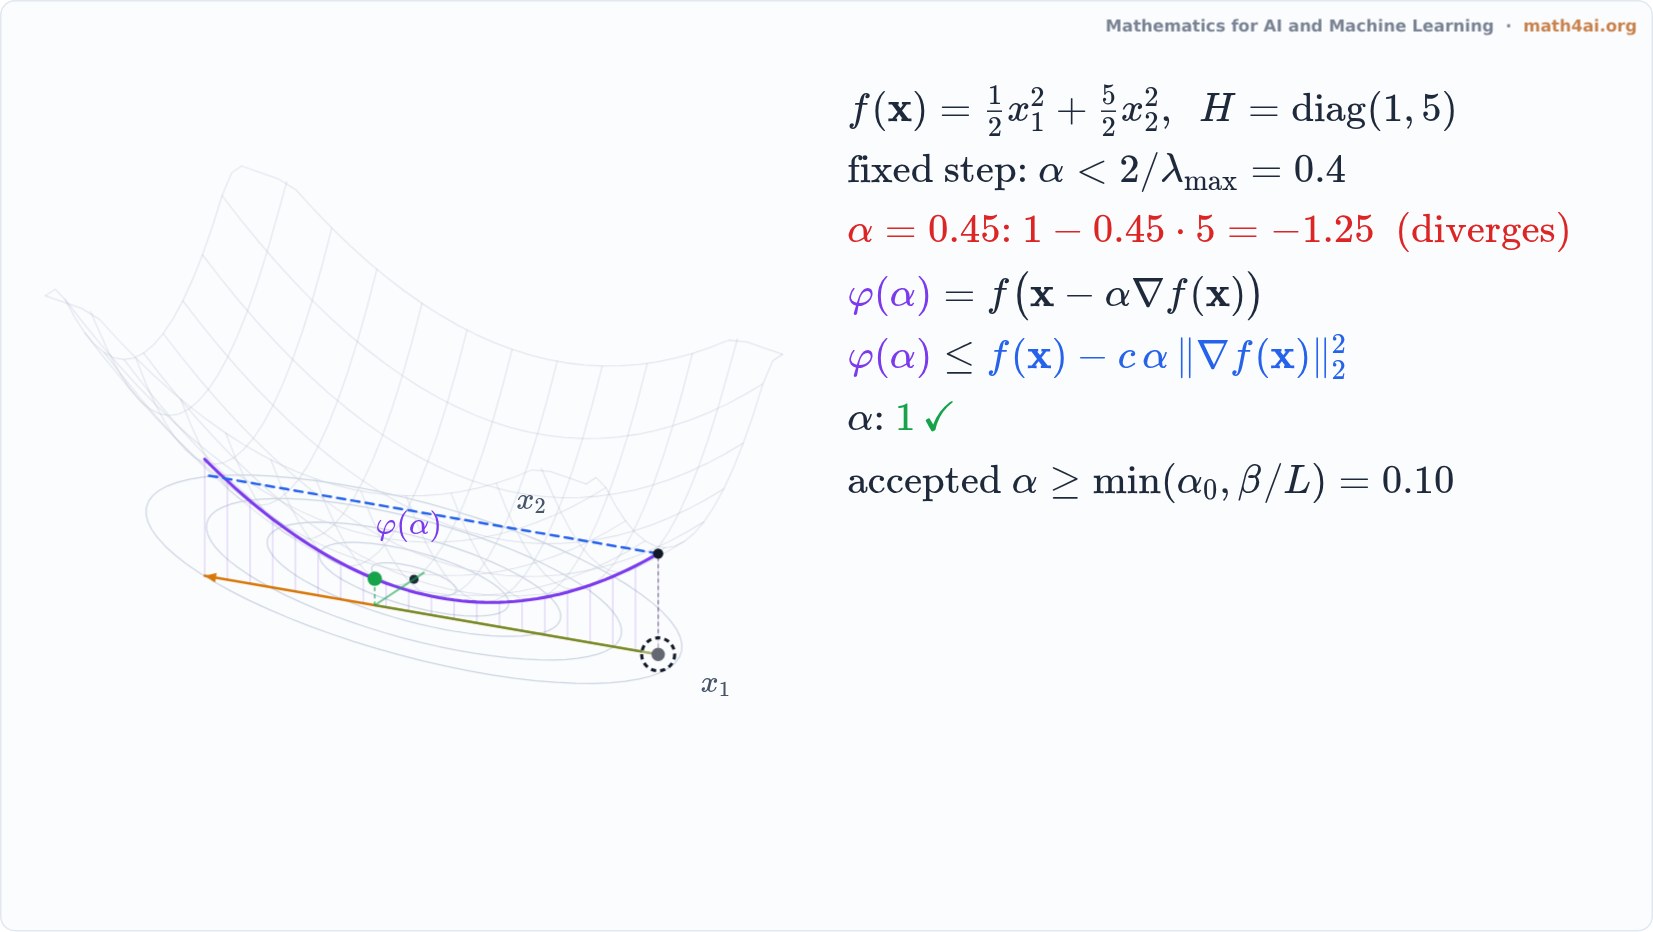 Preview1:55Backtracking Line Search and the Armijo ConditionChapter 12
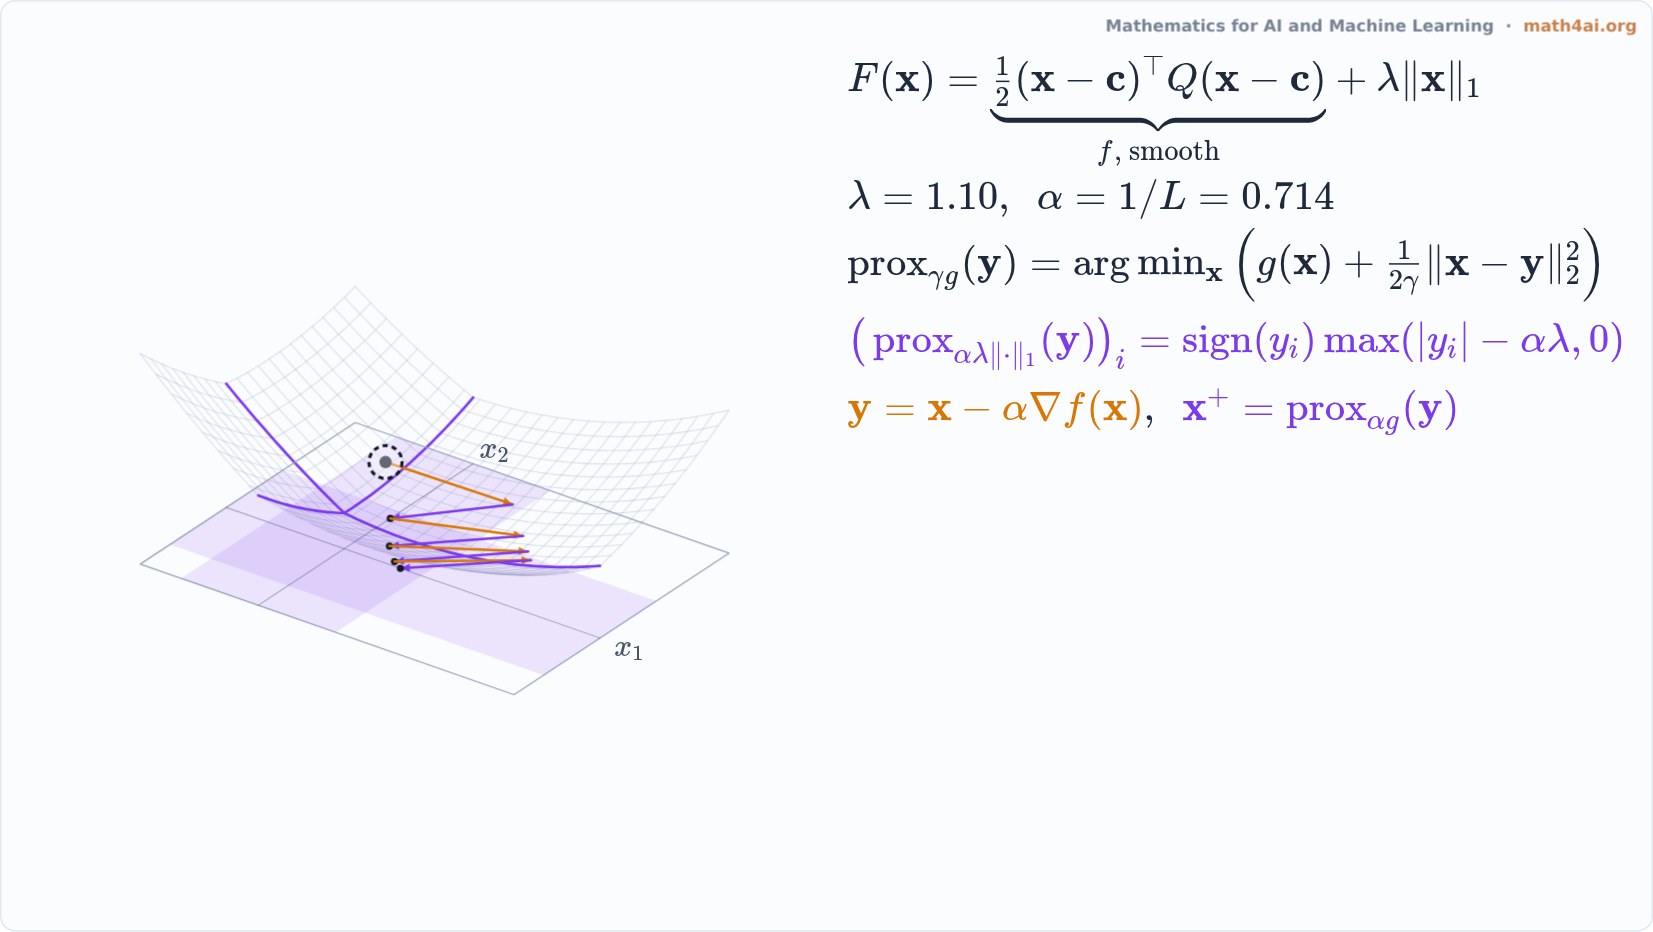 Preview1:50Proximal Gradient and Soft-Thresholding: Exact ZerosChapter 12
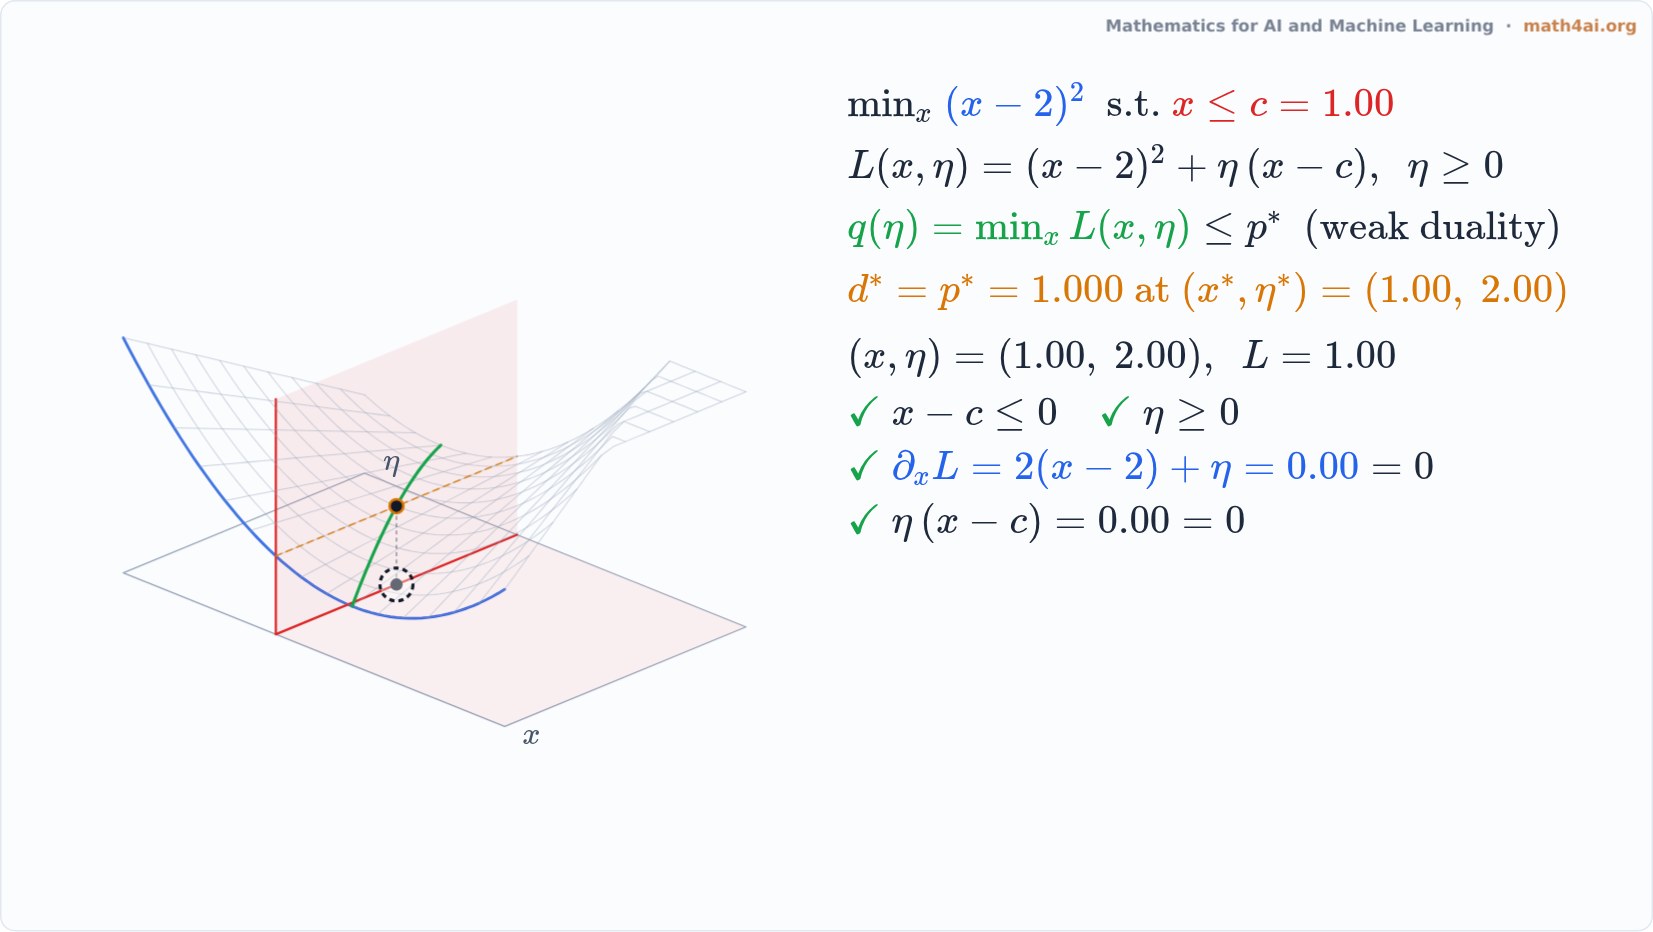 Preview1:53KKT Conditions: the Saddle Point of the LagrangianChapter 12
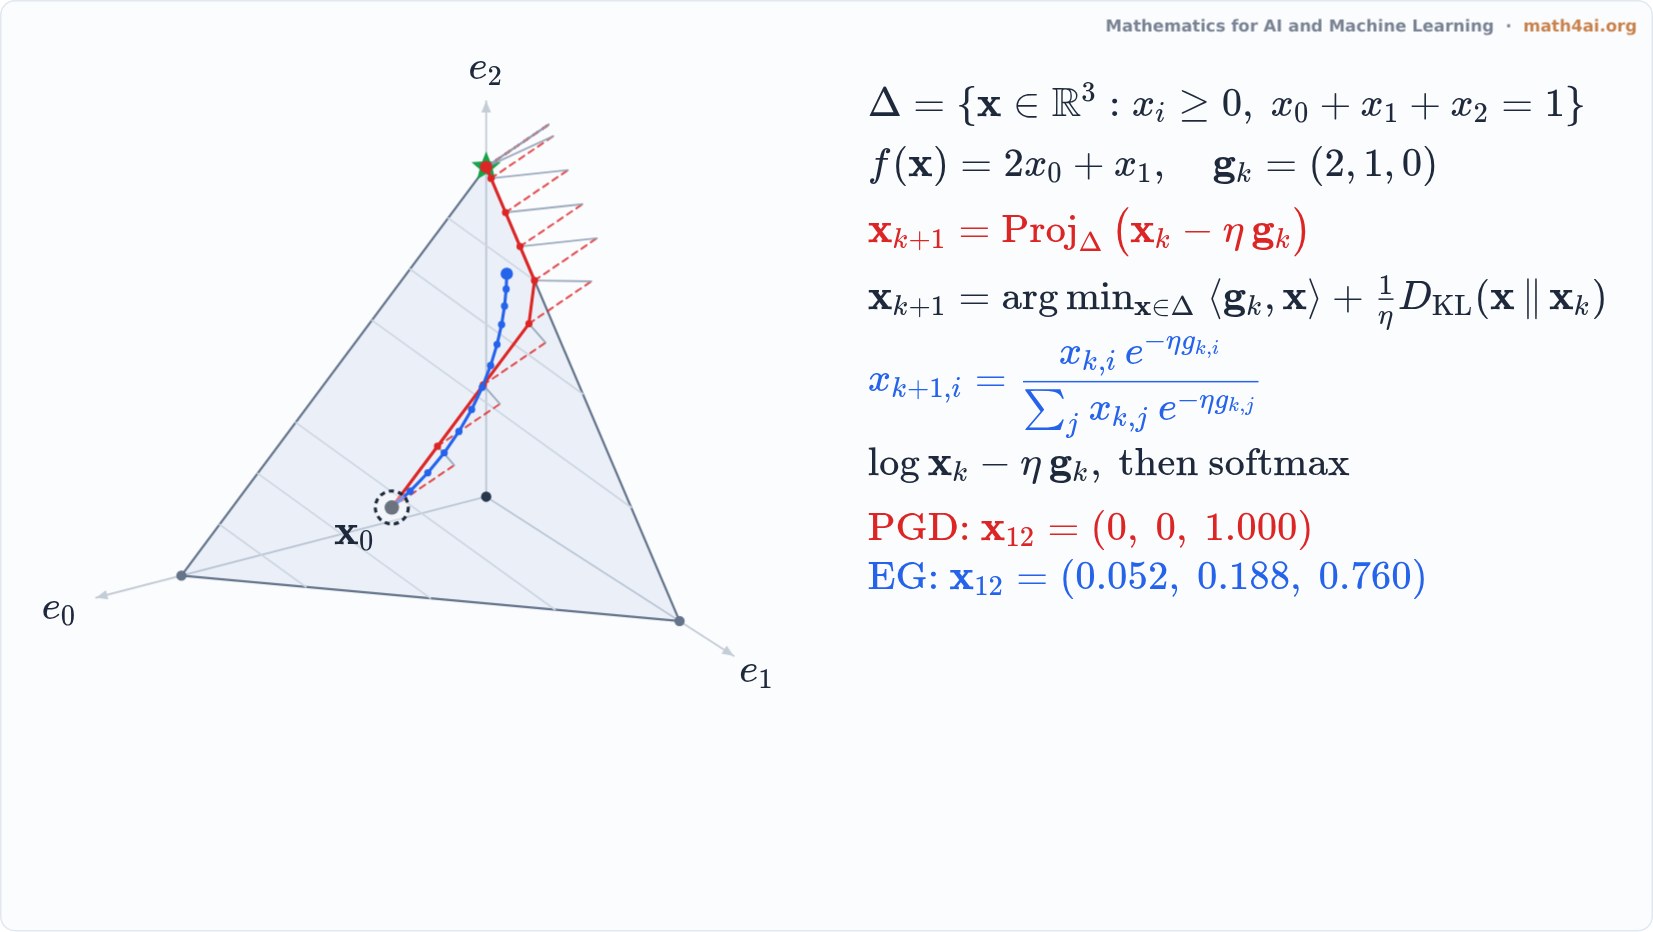 Preview1:52Mirror Descent Stays Inside the SimplexChapter 12
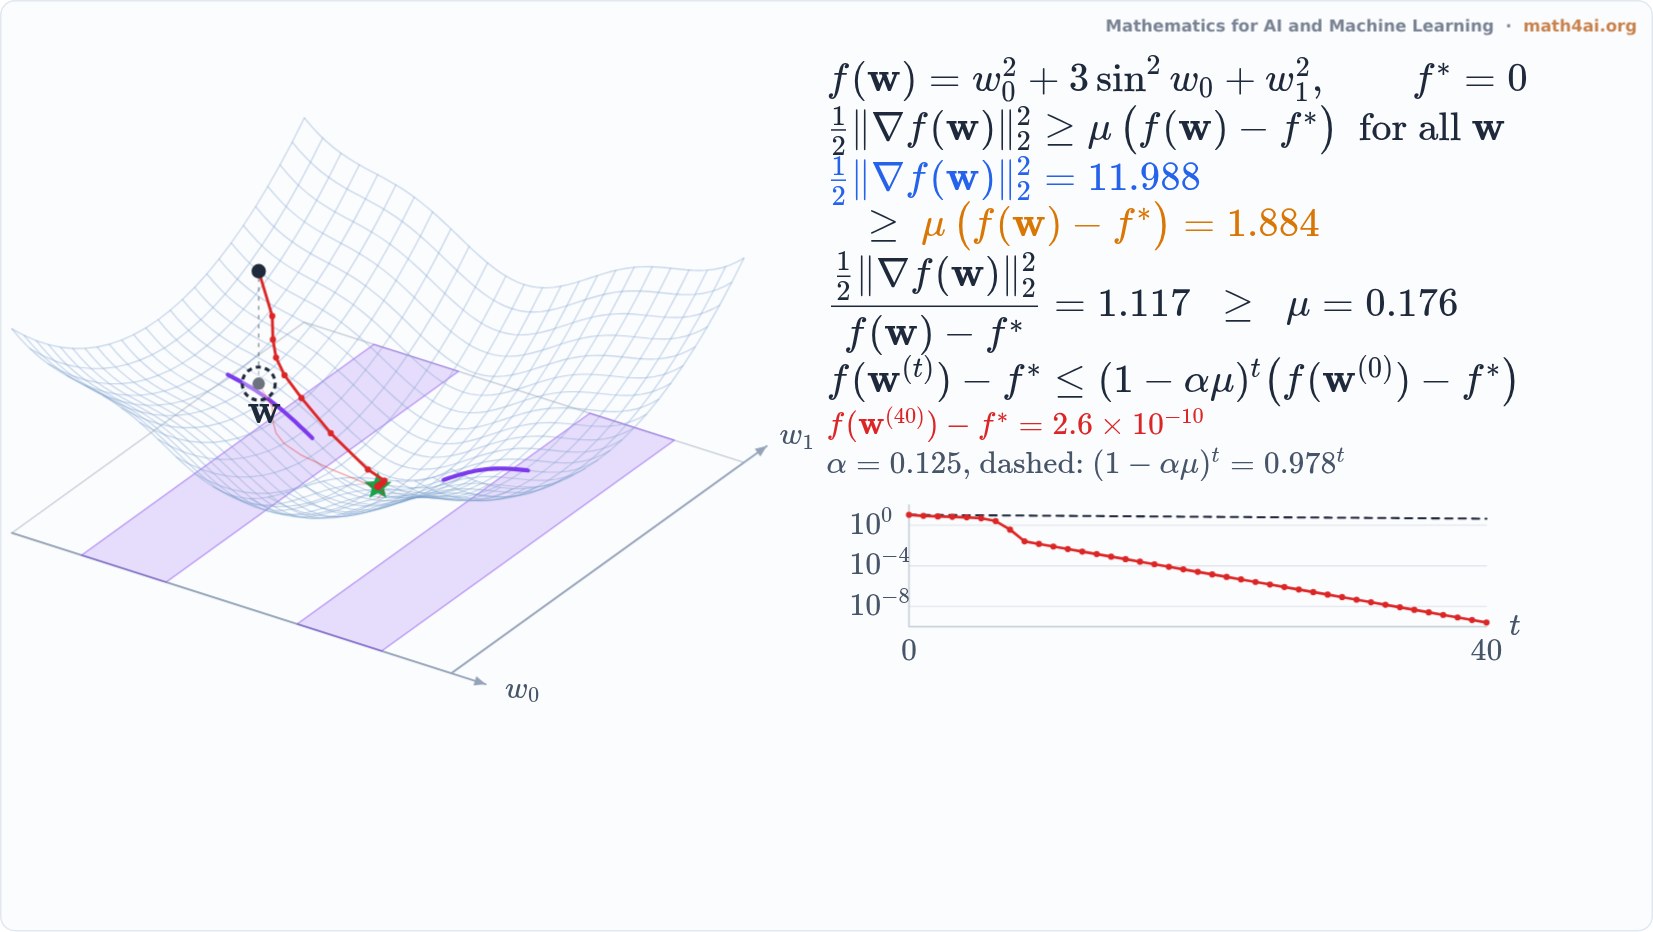 Preview1:55The Polyak-Łojasiewicz ConditionChapter 12