Eckart-Young: the Best Low-Rank Approximation
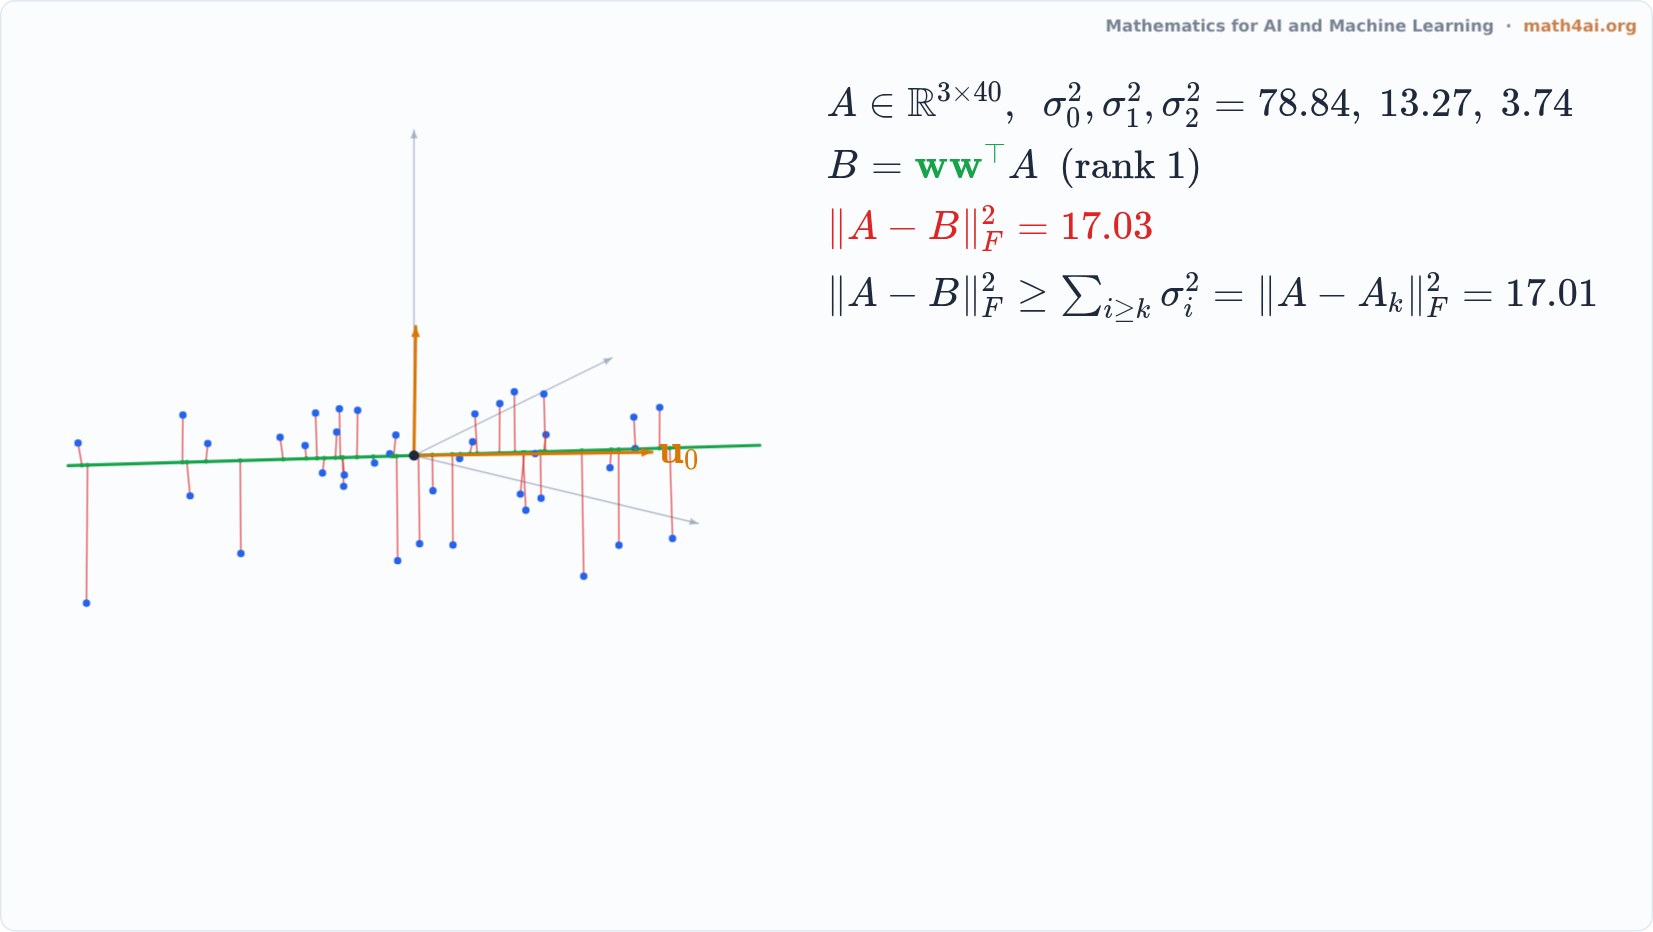
An interactive live film: the columns of a 3 x 40 matrix are a cloud; a rank-1 matrix projects them onto a line, a rank-2 onto a plane, with the residuals as red segments. Turn the line until the error is within 2% of the Eckart-Young minimum.
Narration
Here is a matrix A with three rows and forty columns. Each column is a point in space, so the matrix is this cloud.
A matrix of rank one has every column on one line through the origin. The closest such matrix to A projects every point onto the line, and its error is the sum of the squared distances: the red segments.
The rest of the narration is in the book's Companion.
More from Chapter 8
 Interactive1:49SVD: Rotate, Stretch, RotateChapter 8
 Preview1:31Energy from Singular Values: Rebuild a Picture Layer by LayerChapter 8
 Preview1:33Double Descent at the Interpolation ThresholdChapter 8
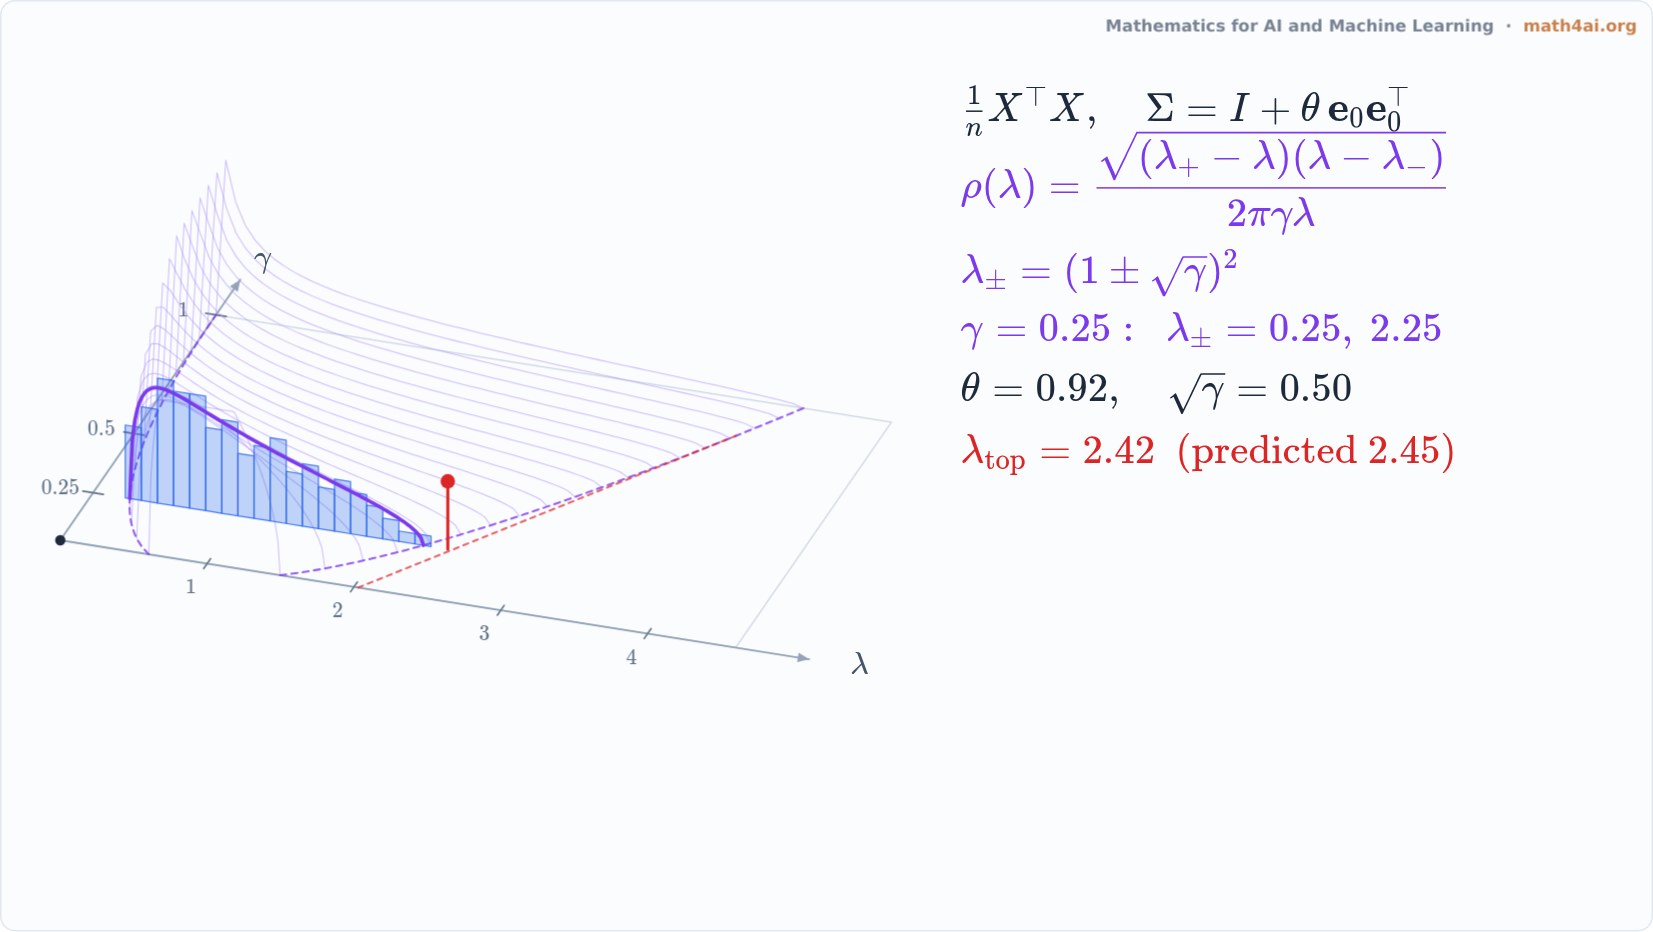 Preview1:32The Marchenko-Pastur Law and the Escaping EigenvalueChapter 8
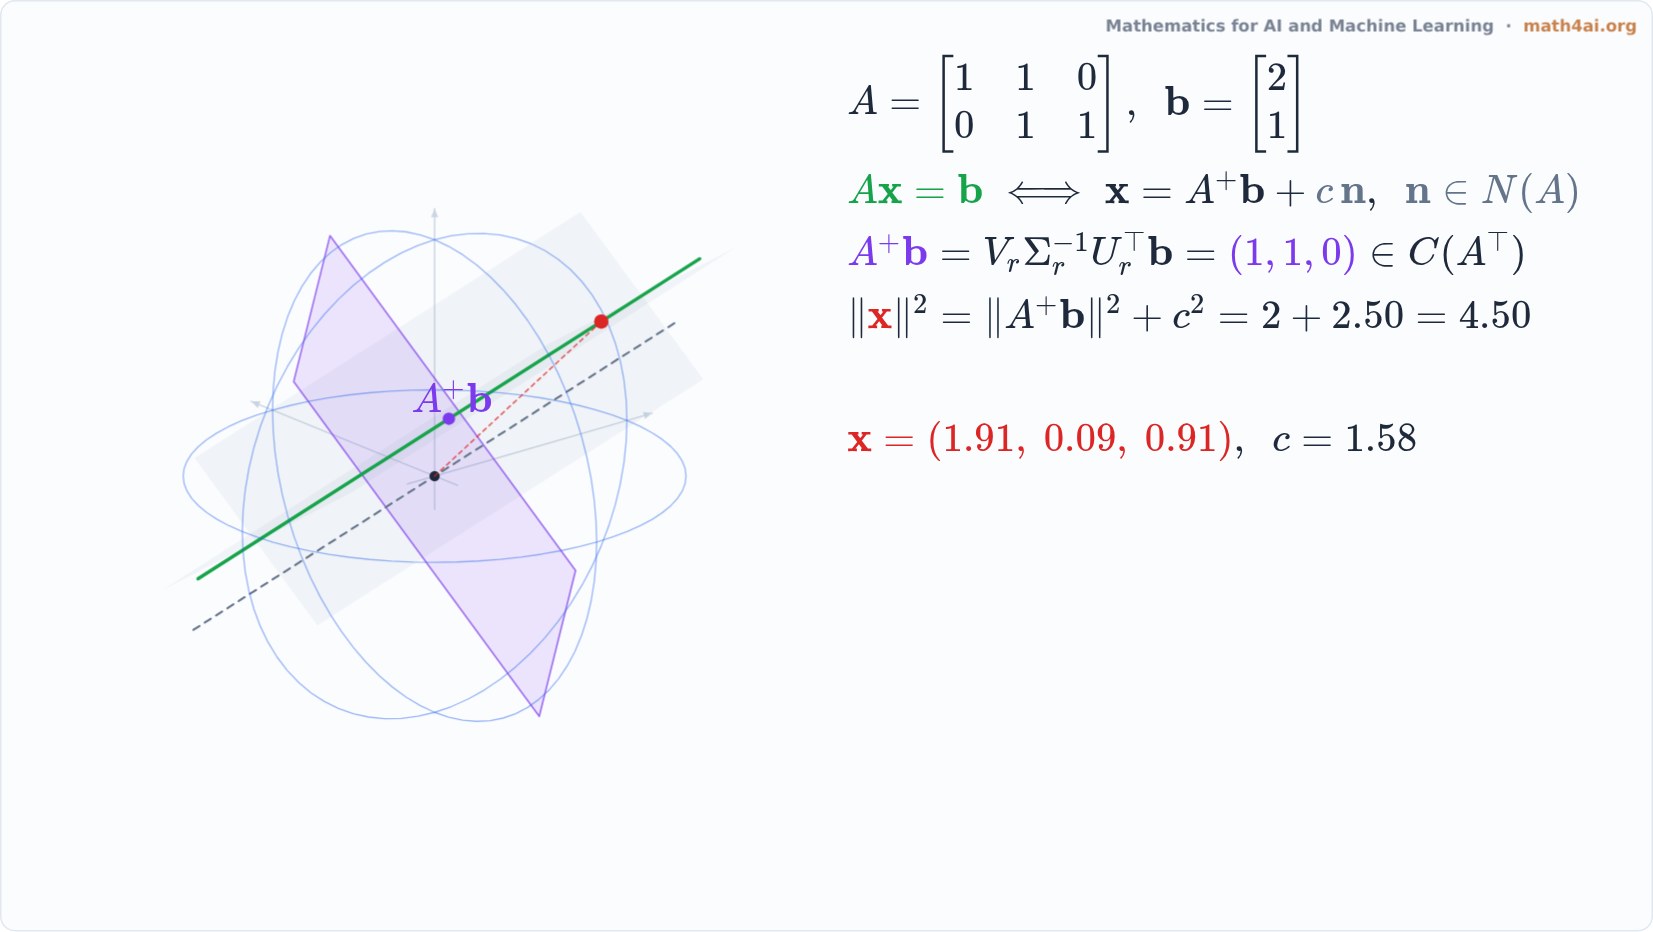 Preview1:46The Pseudoinverse: the Shortest SolutionChapter 8
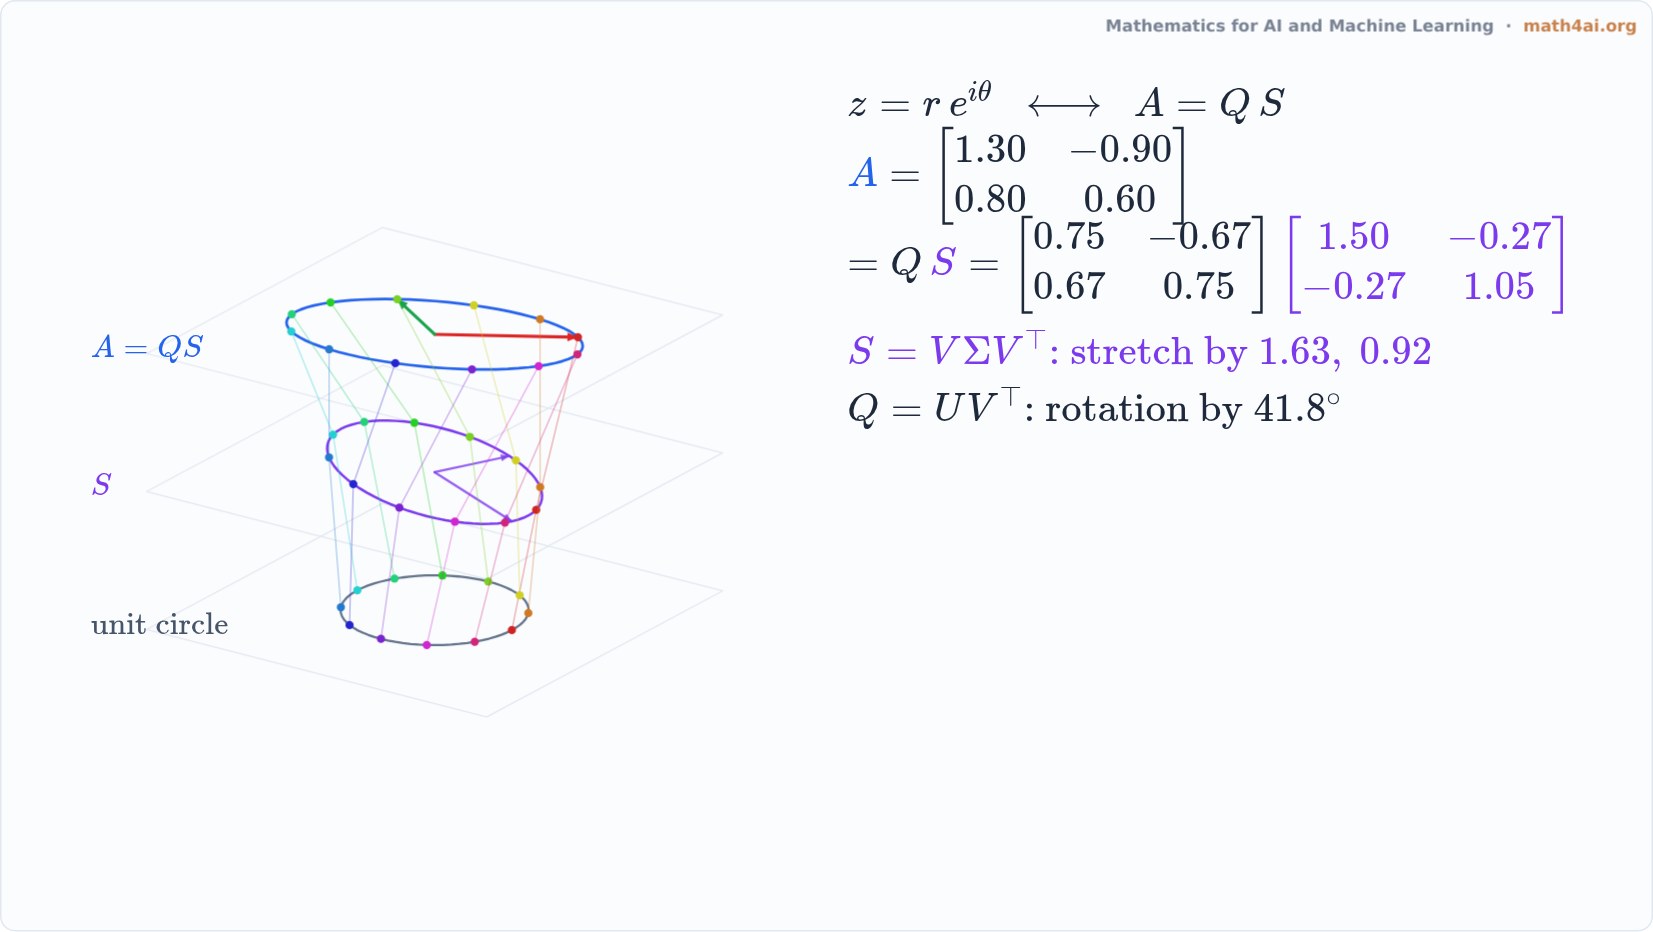 Preview1:31Polar Decomposition: Stretch, then RotateChapter 8
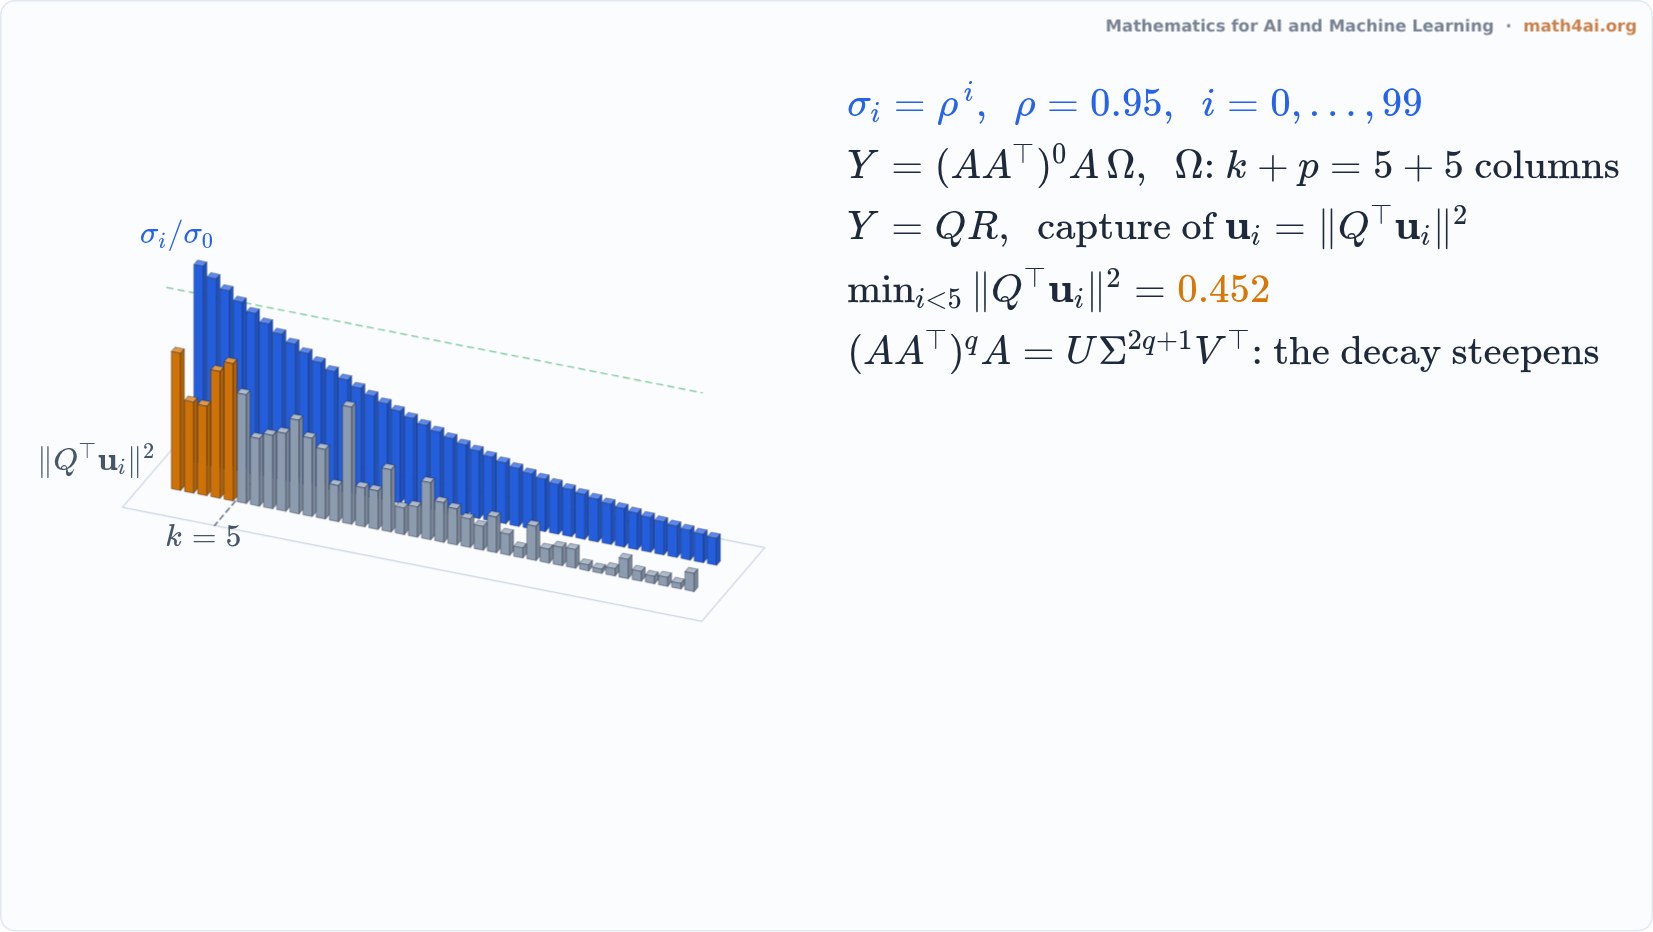 Preview1:47Randomized SVD: Catching the Top DirectionsChapter 8